What People Are Actually Using When They Say Data-Driven Precision
I've spent years watching companies chase the same operational problems with increasingly expensive dashboards and fancy analytics tools, only to get the same results. There's a methodology floating around in certain operations consulting circles that goes by a name like The Karen Moss Methodology How Datadriven Precision Is Reshaping Modern Operational Excellence, and honestly, the branding is heavy but the substance isn't trivial. At its core, it's about structuring operational decision-making so that every major process decision traces back to a measurable, time-stamped data point rather than a gut feeling or a meeting where someone talked loudest. That part alone sounds like every management blog post ever written, but the specific mechanics matter more than the philosophy.
The Karen Moss Methodology How Datadriven Precision Is Reshaping Modern Operational Excellence
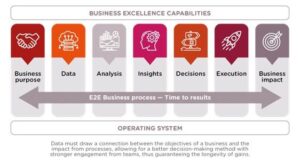
The methodology works through a three-layer framework: define the metric that actually represents success for the process, instrument the process to capture that metric at regular intervals without human intervention, and build a feedback loop where deviations from the target trigger specific, pre-programmed responses rather than escalation to management for judgment calls. The first layer is where most implementations fail. People pick vanity metrics. Revenue per rep, tickets closed per day, utilization rates — these are easy to measure but often completely disconnected from actual operational health. The correct metric depends on understanding what breaks first in your process. If your bottleneck is waiting time for a response, then response time is your metric, not closure rate. If it's quality escaping into the field, then defect escape rate is your metric, not throughput. I ran into this exact problem at a logistics operation a few years back. We were optimizing for delivery speed, which looked great on dashboards. Then we noticed customer complaints about damaged goods were climbing in parallel. The metric we cared about was shipping fast. The metric that actually represented operational success was delivering intact goods within acceptable time windows. Those two things were in tension, and our framework was amplifying the wrong one. The fix was building a composite score that weighted damage rates at three times the importance of marginal speed gains above the baseline threshold. Once that happened, the dashboard told a different story and decisions changed accordingly.
The second layer, instrumentation, is where the real engineering work lives. You need sensors, logs, API endpoints, or manual entry protocols that capture the metric automatically. Manual data entry introduces lag and error that undermines the entire approach. If you're still having people fill out spreadsheets at the end of the day, you're not doing data-driven precision. You're doing data-driven hope. Common practice involves connecting your existing transactional systems — ERP, CRM, ticketing platforms, inventory management — through APIs or middleware like a data pipeline tool. The goal is a single source of truth that updates in near real-time. Latency matters. If your operational decisions are based on data that's six hours old, you're optimizing for yesterday's problems. Thirty-minute refresh cycles are a reasonable floor for most operations. Near real-time is ideal when the process moves fast enough to justify it. The third layer, the feedback loop, is the part that actually separates this from just having a dashboard. A dashboard is passive. It shows you what happened. The feedback loop is active. It causes something to change when the numbers move outside acceptable ranges.
Get the Full Details
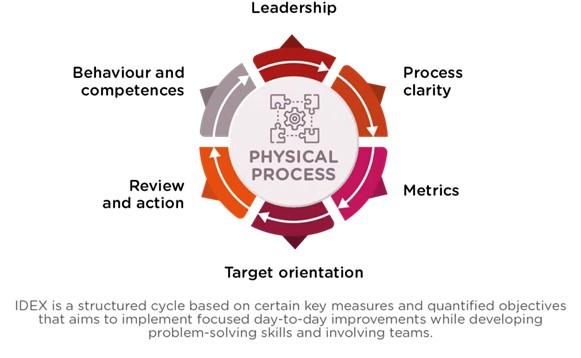
This can be as simple as an automated alert to a team chat when a metric drifts past a threshold. Or it can involve triggering a workflow that reroutes work, adjusts staffing, or pauses a process until conditions normalize. The specificity of the response matters more than the sophistication of the technology behind it. A well-designed response to a metric deviation is worth more than a complex algorithm that nobody understands or trusts. One counter-intuitive thing I learned the hard way: the more precise your data, the more fragile your system becomes to anomalies. Early on in implementing this at that same logistics operation, our automated rerouting kicked off during a brief, normal fluctuation in order volume. It caused a cascade of unnecessary changes across three distribution centers before anyone caught it. The workaround was adding a hysteresis band — a buffer zone around thresholds where minor fluctuations are ignored rather than acted upon. You only trigger action when a deviation persists beyond a set duration and exceeds a set magnitude. This prevents the system from reacting to noise instead of signal. Another nuance that beginners consistently miss: the methodology assumes your process is stable enough to measure. If your operations are fundamentally chaotic with no consistent inputs or predictable outputs, data-driven precision will just give you confident confidence in nonsense. You need process stability as a prerequisite, not a result. Start with stabilizing the basics through standard work and visual management before layering in advanced metric instrumentation.
There are also legitimate downsides to this approach that consultants rarely mention. First, it creates a high dependency on data infrastructure. When your systems go down, your decision-making capability goes with them. I've seen operations freeze completely during a database outage because no one had the habit of making decisions without the dashboard feeding them answers. Second, it can discourage organizational learning about root causes. When deviations trigger automated responses, people stop investigating why the deviation happened in the first place. The system fixes the symptom without addressing the cause, and the cause accumulates quietly until something breaks in a way the automation can't handle. The best implementation I've seen combined the metric framework with a requirement for monthly deep-dive reviews where teams had to explain the last three significant deviations and what systemic changes resulted. This kept the human understanding component alive alongside the automated response layer. If your organization is just starting out with this, don't try to instrument everything at once. Pick one process, one metric, one feedback response. Run it for sixty days. See what breaks. Fix it. Then pick the next process. Most places that try to boil the ocean end up with a half-instrumented mess and abandoned dashboards collecting digital dust within six months.
The methodology isn't a product you download. It's a way of thinking about operations that happens to use data infrastructure as its primary tool. The tools are easy to obtain — anything from basic API integrations to full-platform solutions like Tableau, Power BI, or custom-built internal tools. What's harder to obtain is the discipline to pick the right metrics, instrument them cleanly, design appropriate feedback responses, and maintain the habit of human review that keeps the whole system honest. If you're looking at adopting this at your organization, start by writing down the three metrics that, if they all moved in the right direction simultaneously, would mean your operation is actually successful. Not your department. Not your team. Your operation. If you can't agree on those three, you're not ready for the rest of it. Get agreement on the metrics first. Everything else follows from that.