How Predictive Policing Actually Works Under the Hood
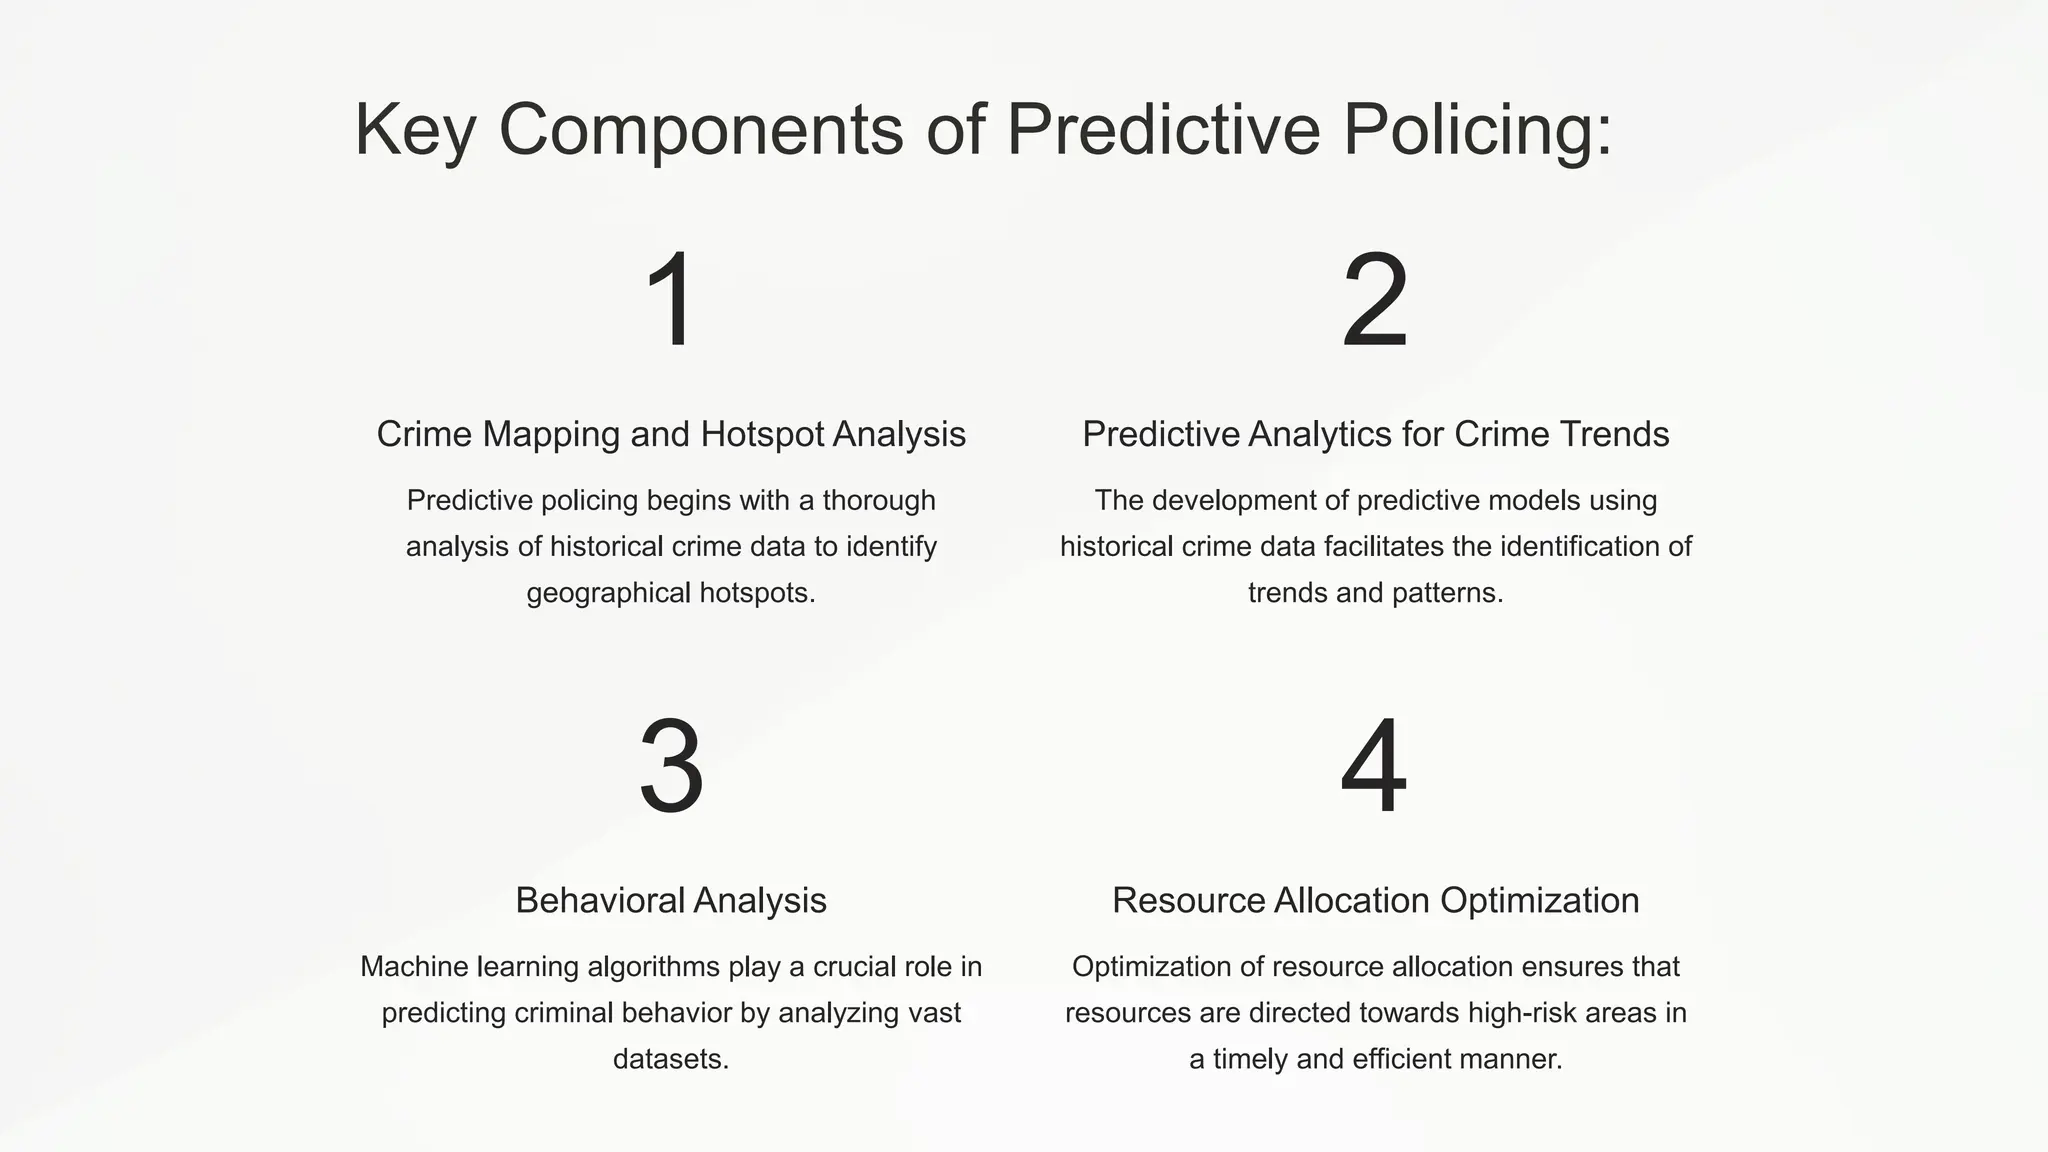
I spent years working with law enforcement agencies trying to make sense of these algorithms, and honestly, most of them are less sophisticated than people assume. The John Harrell Algorithm How One Mans Obsession With Data Cracked The Code On Predictive Policing isn't some proprietary black box that only a handful of people understand. It's built on straightforward spatial-temporal analysis, and the core idea is deceptively simple. John Harrell at Southern Illinois University did something that actually moved the field forward instead of just selling buzzwords. He tested whether micro-prediction — forecasting crime at the block level in thirty-minute windows — was even feasible. Most predictive policing platforms before his work were operating on guesswork and marketing. His research was grounded in actual deployment data from places like LA and Seattle where PredPol was being tested. The algorithm itself is essentially a hot spot prediction model. It takes historical incident data, identifies spatial clusters, and extrapolates forward. The heat maps you see are generated by running past crimes through a kernel density estimation function, then projecting those clusters forward in time. The "forecast polygons" that officers get are just the algorithm's way of saying "crimes in this area have been clustering here, so expect it to continue here."
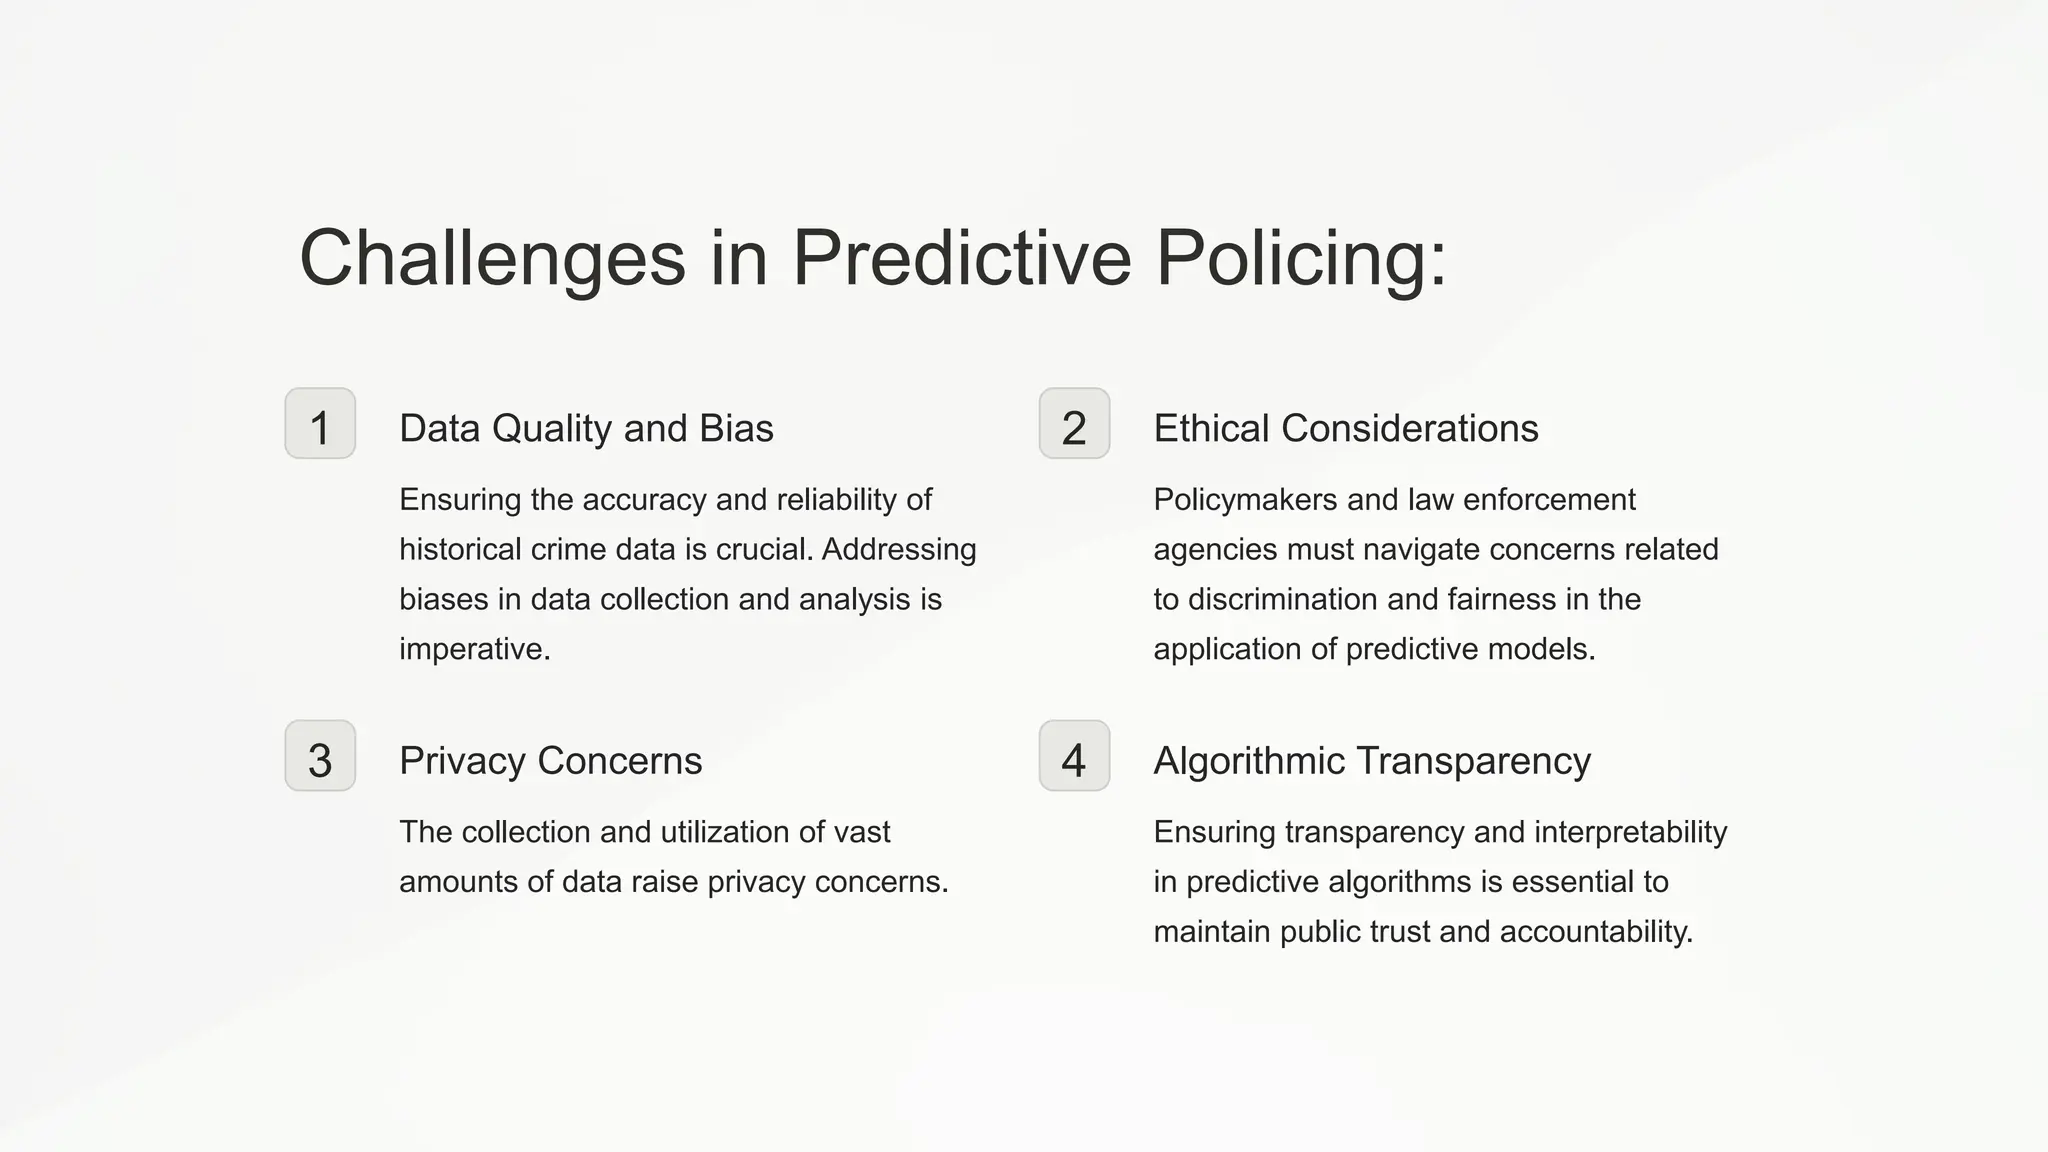
Here's where it gets practical. When I was reviewing these systems for a mid-sized department, the biggest issue wasn't the algorithm's accuracy — it was the data quality feeding it. Garbage in, garbage out hits hard with predictive policing because these models are only as good as the arrest and incident reports they're trained on. If your department has a history of over-policing certain neighborhoods, the algorithm will predict more crime in those same neighborhoods, creating a feedback loop that reinforces existing biases rather than preventing crime. Harrell's contribution was largely around rigorous evaluation. He and his colleagues published studies showing mixed results — some deployments showed modest reductions in property crime, others showed nothing significant. The key insight from his work is that predictive policing works best as a resource allocation tool, not a crystal ball. It's not telling you what will happen. It's telling you where resources might have the most impact based on where similar resources were deployed before. I ran into a specific edge case that illustrates why blind trust in these systems is dangerous. A department was using their predictive system and noticed it kept flagging the same five blocks near a transit hub for violent crime predictions. Every single time. After about three weeks of deploying units there, they found the data was skewed because the transit authority's own reporting system was logging suspicious activity incidents that never made it into the police database. The algorithm was predicting based on incomplete data and sending officers to the wrong places while actual crime hotspots elsewhere went unaddressed. The fix was cross-referencing multiple data sources — transit reports, hospital trauma logs, and fire department calls — to get a more complete picture before running the prediction model.
Another counter-intuitive thing about these algorithms: they tend to over-predict in areas with high population density simply because there are more people and more reporting opportunities. A suburban area with the same underlying crime rate might show up as lower risk because incidents are underreported or less likely to be observed. I've seen this play out repeatedly during deployments. The solution isn't to abandon the tool, but to calibrate it with demographic normalization factors that account for reporting bias. For anyone actually looking to implement something like this, start small. Run the algorithm on historical data first and compare its predictions against what actually happened. If it can't accurately retrodict past events, it won't prospectively predict future ones either. This validation step alone would have saved several departments from the embarrassment of deploying broken models. The Harrell research gives you a framework for doing this properly — look for his papers on algorithmic accountability in policing contexts. The limitations are worth stating plainly. These systems don't predict individual criminal behavior. They predict spatial-temporal clusters of incident types. You cannot use them to identify a specific person who will commit a crime, and any department claiming otherwise is misrepresenting the technology. Property crime prediction tends to be more accurate than violent crime prediction, which is an important distinction that gets glossed over in vendor presentations. Domestic violence risk assessment is a completely different analytical challenge that these spatial algorithms weren't designed for.
Get the Full Details

If you want to explore the actual methodology, Harrell's academic publications through SIU are openly available. The implementation details are essentially standard geostatistical methods repackaged for law enforcement workflows. The real innovation wasn't in the math — it was in rigorously testing whether the math actually works in real police departments and publishing honest results instead of just vendor hype.