Setting Up The Intelligent Edge Infrastructure
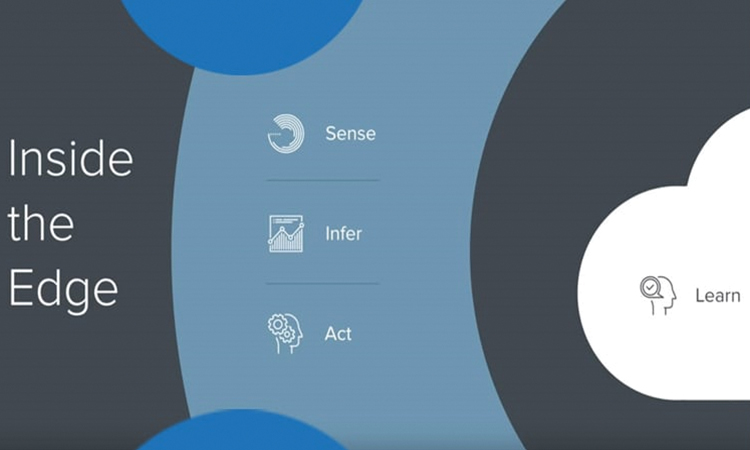
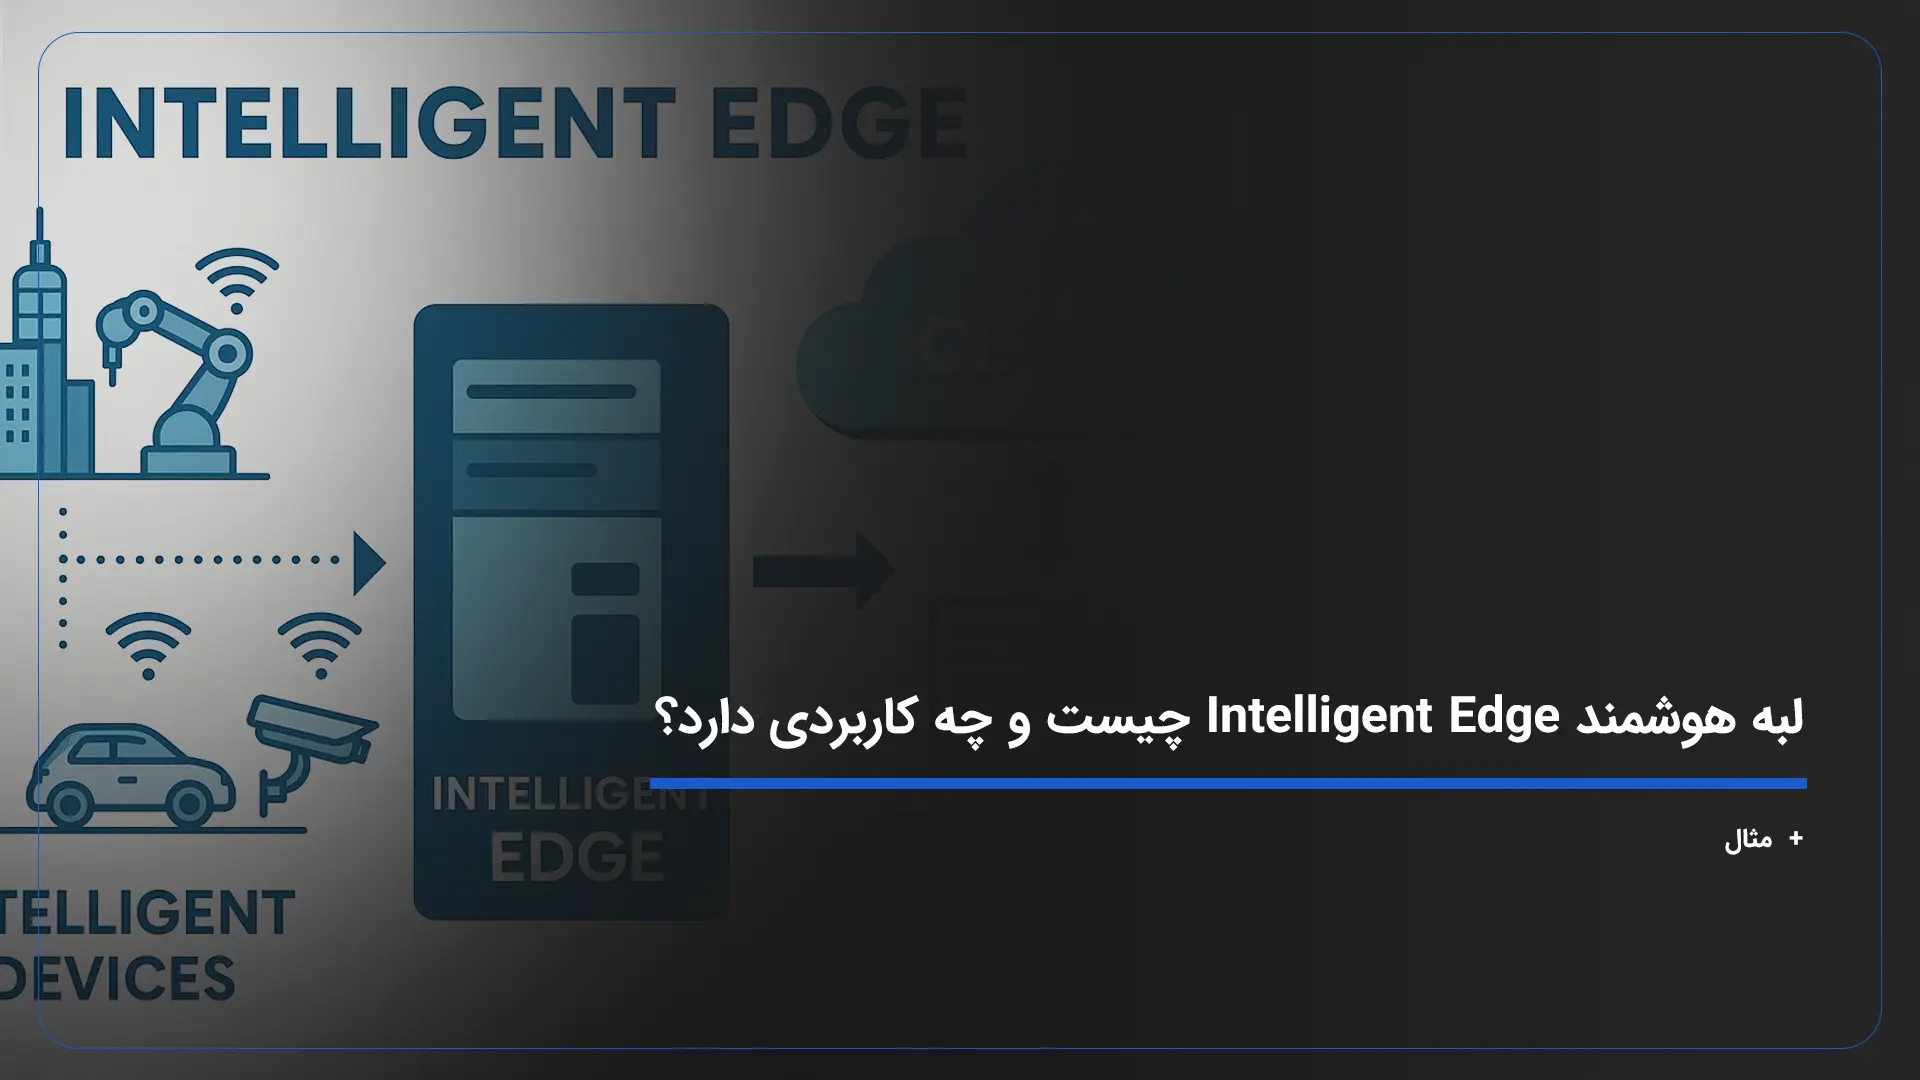
The first thing you need to understand is that edge computing is not just about putting servers closer to users. The hardware constraints alone make naive deployments fail within six months. I learned this the hard way when a client asked me to deploy a real-time analytics pipeline across twelve regional warehouses. The initial prototype looked great in the lab. It collapsed in production because nobody had accounted for thermal throttling on the edge nodes during summer months without climate control. Dimitri Portwood's approach to this problem centers on something he calls layered abstraction. The idea is simple on paper but requires discipline to implement correctly. You build three distinct layers: the perception layer handles raw sensor input, the reasoning layer processes and filters that data locally, and the orchestration layer manages communication back to the central cloud system. Most engineers try to combine the first two layers to save time. This is where things go wrong. I spent three weeks debugging a particularly nasty issue where the perception and reasoning layers were competing for the same CPU cycles on a Jetson Nano. The timestamps on incoming video frames became unreliable, and the downstream models started hallucinating objects that weren't there. The workaround was painfully simple: I added a strict time-slicing mechanism that gave the perception layer exclusive access to the GPU for twenty millisecond windows, then handed off to the reasoning layer. Everything after that ran smoothly.
The Intelligent Edge How Dimitri Portwood Shapes Performance Through Data Vision And Digital Ambition
Portwood's methodology emphasizes what he terms "data vision," which is essentially the practice of defining exactly what data matters before you build the pipeline. Most organizations collect everything and wish they had collected something else later. This reverses the usual pattern and forces you to make decisions upfront about what signals are actually worth processing at the edge versus what can wait for cloud analysis. The digital ambition piece is less technical and more about organizational structure. Portwood argues that edge deployments fail more often because of misaligned incentives than because of technology limitations. A logistics company might want edge computing to reduce latency, but their warehouse managers are evaluated on throughput, not latency metrics. The edge system gets configured to optimize for whatever the warehouse managers care about, not what the engineering team thinks matters. This mismatch has killed more projects than I can count. Here is a counter-intuitive point that most tutorials miss: the best edge architectures are intentionally asymmetrical. The edge nodes should handle slightly more computation than strictly necessary while the cloud does less than it would in a traditional setup. This seems backwards. When the edge handles more, you get faster response times and the cloud only receives refined, curated data rather than raw feeds. The bandwidth savings alone usually justify the extra hardware cost within the first year.
One specific implementation detail that people overlook is how you handle model updates at the edge. Portwood's framework recommends a staged rollout where new models first run in shadow mode on the edge nodes for forty-eight hours before going live. Shadow mode means the model runs alongside the existing one and logs its predictions without actually controlling anything. This catches a surprising number of edge cases without risking production stability. I used this approach on a project where a new object detection model was passing validation in the lab but failing in the field due to a specific lighting condition that only occurred at 6:47 AM near a particular loading dock. Another practical consideration is network resilience. Edge nodes need to operate fully autonomously when connectivity drops, which happens more often than anyone admits. The orchestration layer should queue all cloud-bound data locally and use a conflict-free replicated data type or similar structure to merge state when the connection returns. Without this, you end up with silent data loss that nobody notices until someone audits the system weeks later. The main bottleneck in this approach is human coordination, not technical complexity. Getting stakeholders across operations, IT, and data science to agree on what "success" means for an edge deployment takes longer than any engineering task. Portwood's recommendation is to establish a shared metrics dashboard that both the edge team and the business side can see in real time. When both groups are looking at the same numbers, arguments about whether the system is working decrease significantly.
Get the Full Details
If you are starting from scratch, I would suggest beginning with a single high-impact use case rather than trying to deploy across the entire organization. Pick something where the data volume is already overwhelming your central systems and where latency directly affects revenue. The metrics from that pilot will make building the case for broader adoption much easier.