Starting With the Math That Actually Moves Things
The derivative is what you get when you stop approximating and calculate exactly how fast something is changing at one specific moment. Most people encounter this in a calculus class where they spend three weeks finding slopes of tangent lines and then never use it again. That's a waste. The real utility shows up when you're actually trying to model systems that don't stay still. I remember working on a motion-capture cleanup pipeline a few years back. We were trying to reconstruct clean velocity curves from raw joint position data collected at 120 Hz. The standard approach was to take finite differences between consecutive frames, which sounds fine until your subject stops moving and the signal noise creates velocity spikes that look like jitter. I spent two days debugging what I thought was a tracking error before realizing the problem was purely numerical. The workaround was switching from first-order backward differences to a Savitzky-Golay filter for the velocity estimation, which gives you a local polynomial fit and smooths the derivative without introducing phase delay. It cut our manual correction time from about four hours per session down to roughly twenty minutes.
The Instantaneous Rate Of Change How Calculating The Momentary Speed Unlocks The Secrets Of Our Dynamic World
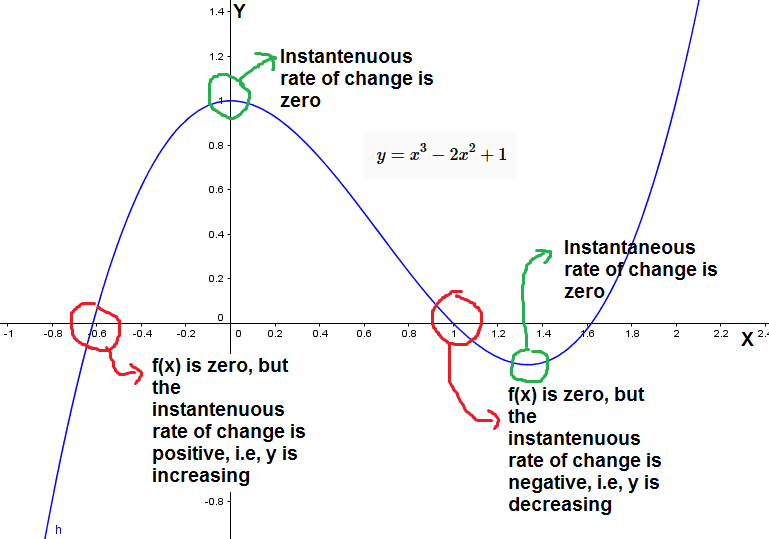
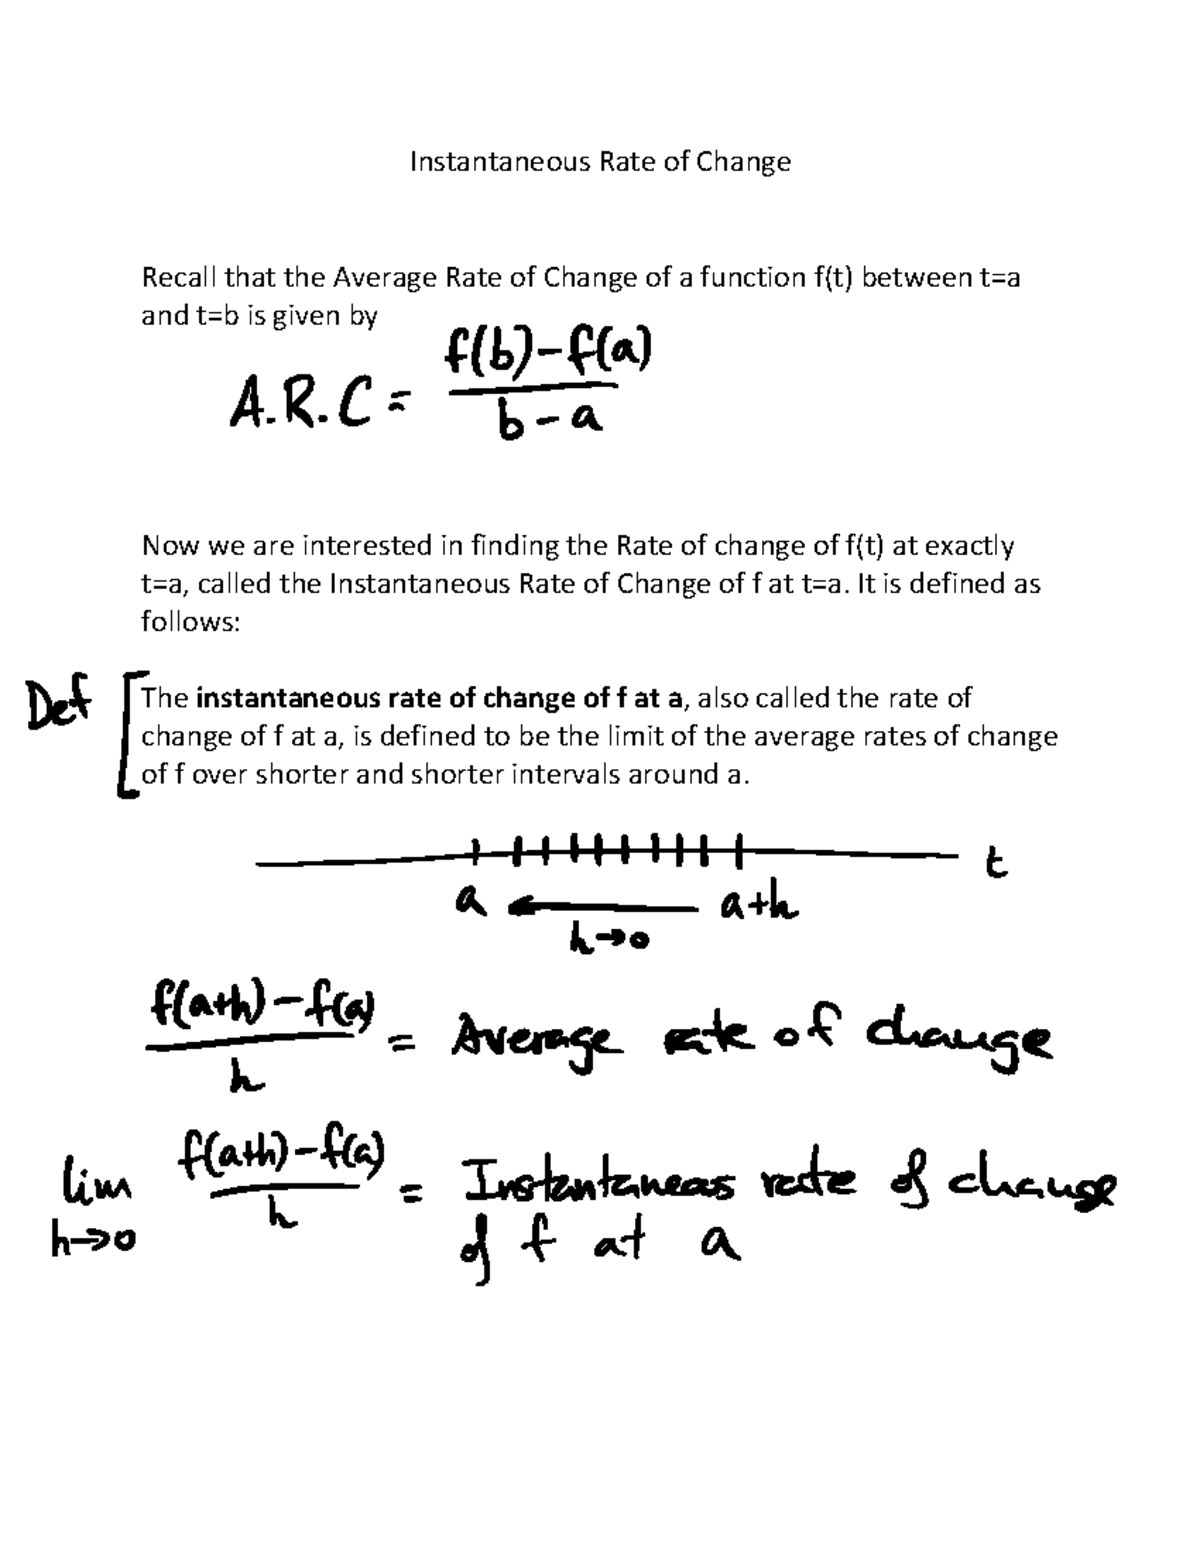
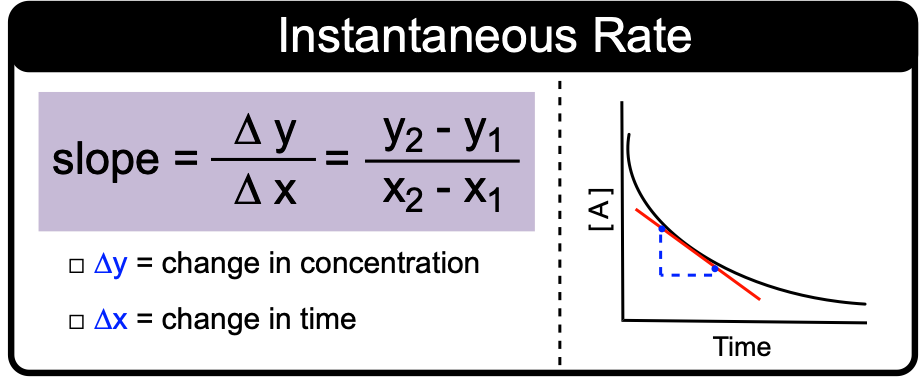
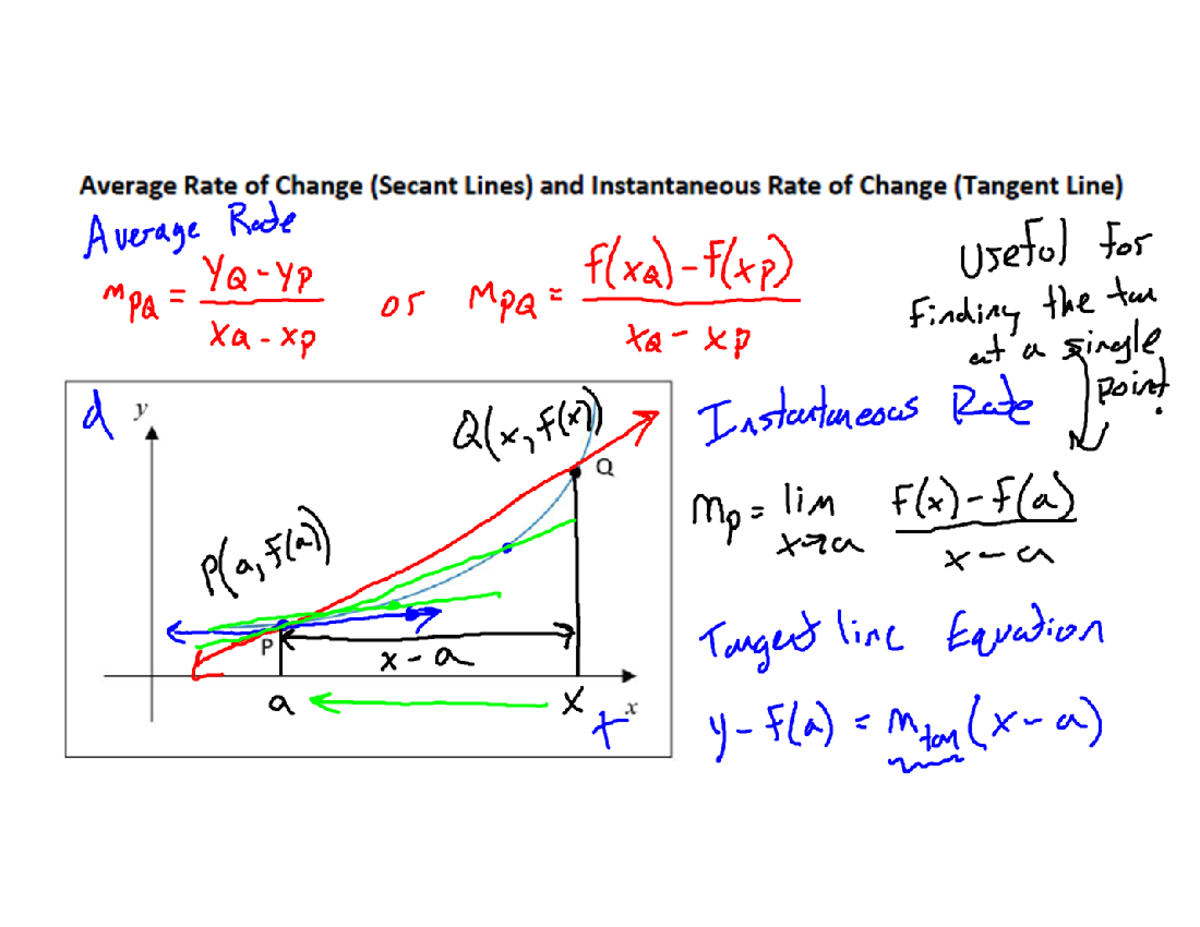
Here's the practical breakdown of how this actually works in real applications. The instantaneous rate of change is formally defined as the limit of the average rate of change as the time interval approaches zero. In symbols, that's f'(x) = lim(h0) [f(x+h) - f(x)] / h. You already know this from your textbook. What the textbook doesn't tell you is that this limit rarely works cleanly in practice because you're always dealing with discrete data or noisy measurements. When you're working with actual sensor data, you can't take a limit to zero. Your sampling rate imposes a hard floor on how small your delta-t can be. If you sample at 60 Hz, your minimum interval is 16.67 milliseconds. Any attempt to compute derivatives at smaller scales just amplifies your measurement noise. This is the single most important thing to internalize before you start building anything that uses derivatives: the derivative of noisy data is proportional to the noise amplitude divided by your timestep, which means smaller timesteps give you less accurate derivatives, not more.
There are three main approaches people use, each with tradeoffs: Central differences are more accurate than forward or backward differences for a given timestep. The formula is [f(x+h) - f(x-h)] / 2h, and the truncation error is O(h²) instead of O(h). This is the default choice for most physics simulations and game engines. But central differences introduce a half-timestep delay in phase, which matters if you're feeding the derivative back into a control loop. Savitzky-Golay filters smooth the data while computing the derivative simultaneously. They fit a polynomial to a sliding window of points and return the derivative of that polynomial. A second-order polynomial with a seven-point window is a common starting configuration. This handles noise much better than raw finite differences but adds computational overhead and a small window-width-dependent latency. For real-time systems running at 60 FPS, a seven-point window means you're using data from the last 116 milliseconds to estimate the current derivative.
Get the Full Details
Finite element or spline-based approaches are the heavy artillery. If you have the full signal available offline, you can fit a cubic spline to the data and analytically differentiate the spline. This gives you the most accurate derivative possible from discrete samples, subject only to the smoothness assumptions baked into the spline. The downside is that you need all the data upfront. You can't use this for streaming applications. I ran into a case last year where none of these worked cleanly. We were measuring the acceleration of a robotic gripper during contact with a fragile object. The position signal was fine, but the force sensor was saturating intermittently, creating flat spots in the data that made numerical differentiation produce wild oscillations. The standard filters either smoothed out the contact events entirely or left the oscillations intact. The solution was to switch to a Kalman filter formulation where position and velocity were both state variables, and the force saturation was modeled as an outlier detection problem. The Kalman filter effectively computes a weighted optimal estimate of the derivative given your process model and measurement noise characteristics. It took about three days to tune the covariance matrices properly, but once it was working, the velocity estimates were significantly better than anything the Savitzky-Golay approach could produce on this particular signal.
Where This Actually Matters
Beyond the obvious physics and engineering applications, instantaneous rate of change shows up in places people don't expect. Financial modeling uses it constantly. Option pricing models like Black-Scholes are built around the gamma and vega of a portfolio, which are second and third derivatives of the option price with respect to underlying variables. Risk managers compute these daily. The problem is that these derivatives assume continuous trading and log-normal price distributions, both of which break down during market stress. I've seen portfolios where the calculated Greeks suggested a hedge was perfectly balanced right before a flash crash, because the model couldn't account for the fact that the underlying asset jumped several percent in a single tick. No amount of derivative calculus fixes a bad model assumption. In machine learning, gradient descent is literally just stepping in the direction of the negative instantaneous rate of change of your loss function. Adam, RMSprop, and the other adaptive optimizers are all attempts to fix the fact that vanilla gradient descent uses a single learning rate for all parameters regardless of the local curvature of the loss landscape. This is a direct consequence of treating the derivative as if it were globally informative, when in high-dimensional spaces it only describes the local slope.
Control theory is probably the domain where this concept is used most rigorously. PID controllers measure the rate of change of an error signal and use it to anticipate where the system is heading. The derivative term in a PID controller is notoriously noisy, which is why most practical implementations include a low-pass filter on that term. A typical setup might filter the derivative at 5-10 Hz even if the controller runs at 1000 Hz. Without this filtering, the derivative term amplifies high-frequency noise into control signal oscillations that can damage actuators.

Common Pitfalls
People who are new to working with derivatives make the same mistakes repeatedly. The first mistake is assuming that a smooth-looking signal has a well-defined derivative everywhere. A signal can look smooth to the eye but contain high-frequency components that dominate the derivative. Always check the frequency content of your signal before differentiating. A quick FFT and you'll see if your noise floor is going to become your signal after differentiation. The second mistake is treating the derivative as a deterministic quantity when your data is stochastic. Every time you compute a derivative from measurements, you're computing an estimate with uncertainty. Propagate that uncertainty. If your position measurements have standard deviation , your central-difference velocity estimate has standard deviation approximately 2 / t. At t = 0.01 seconds with = 0.1 mm, that's about 14 mm/s of velocity uncertainty. That might seem small until you're trying to detect velocity changes on the order of 20 mm/s.
The third mistake is using derivatives for interpolation. If you have five points and compute a derivative at one of them, you're making assumptions about the function between the points. Cubic Hermite interpolation uses derivative values at endpoints to construct a smooth interpolant, but those derivatives need to be computed carefully. Finite differences are not the same as the true derivative of the underlying function, and confusing the two leads to artifacts in the interpolated result. Here's something counter-intuitive that most people miss: sometimes the best estimate of the instantaneous rate of change doesn't come from the data at all. If you have a physical model of the system, you can compute the derivative analytically from the model equations. A mass-spring-damper system's velocity is determined by its position, velocity, and applied force through a differential equation. If you know the force and the parameters, you can compute the exact derivative without numerical differentiation. The numerical derivative of your measured position is only useful when you don't have a good model or when your model has unmodeled dynamics. This is the foundation of observer design in control theory, and it applies anywhere you have governing equations.
What Derivatives Can't Do
I need to be blunt about the limitations because the literature rarely is. Derivatives assume your function is differentiable. Many real-world signals are not. Contact forces, friction transitions, and switching circuits all produce discontinuities in the derivative or the function itself. At a discontinuity, the derivative doesn't exist. Numerical methods will give you a number, but that number is meaningless. You need to detect these events separately and handle them with event-based logic rather than continuous derivative-based logic. Derivatives are local. The derivative at a point tells you nothing about the behavior of the function elsewhere. Two functions can have identical derivatives at a point but diverge immediately after. This matters in optimization, where gradient-based methods can get stuck in local minima, and in dynamical systems, where Lyapunov stability analysis requires understanding the global behavior, not just the local slope.
Derivatives amplify noise. I've said this twice now because it's worth saying again. If your signal-to-noise ratio is low, numerical differentiation will produce garbage. The only remedies are smoothing (which costs bandwidth), modeling (which requires domain knowledge), or better measurements (which costs money). There is no mathematical trick that makes a derivative of a noisy signal more accurate than the noise level permits. For systems with significant nonlinearity or discontinuities, alternative frameworks exist. Extended Kalman filters linearize the dynamics around the current estimate, which works when the nonlinearities are mild. Unscented Kalman filters use a deterministic sampling approach that captures higher-order moments without explicit Jacobian computation. Particle filters abandon the Gaussian assumption entirely and represent the state distribution with samples. These are more computationally expensive but handle cases where plain derivative-based methods break down. The bottom line is that the instantaneous rate of change is a powerful tool when your system is smooth, your measurements are clean, and you understand what the derivative is actually telling you. It fails silently in all the interesting cases, which is why you should always validate your derivative estimates against the raw data and your physical intuition before trusting them.