Setting Up Variables That Actually Tell You Something
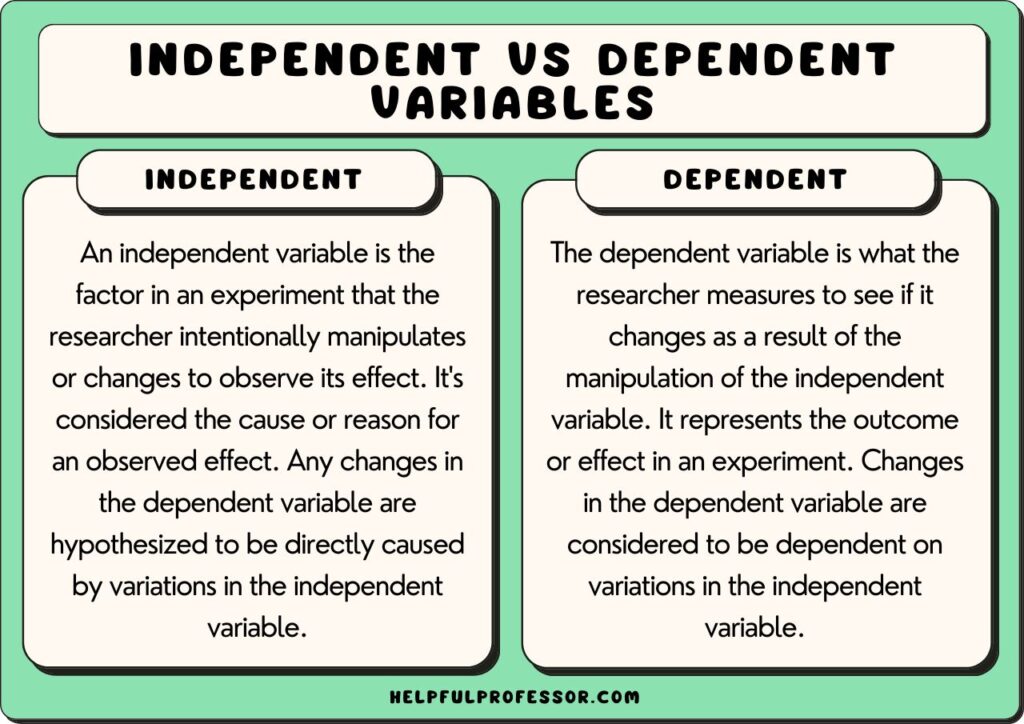
Most people treat independent and dependent variables like they are simple categories you fill in on a form. They are not. They are the structural framework that determines whether your experiment will produce useful data or just expensive noise. I spent three years watching teams waste six-figure budgets on studies that proved nothing because the variables were poorly specified before any data collection began. The difference between a study that answers a real question and one that generates a stack of p-values with no meaning usually comes down to operational precision. Before you touch any equipment or recruit a single participant, you need to define both variables at the operational level. An independent variable is what you manipulate or categorize. A dependent variable is what changes in response. Simple enough until you try to measure it in practice. I worked on a clinical trial where the independent variable was supposedly a medication dosage at three levels: zero, 50 milligrams, and 100 milligrams. The problem was the 50-milligram tablets did not exist. We had to compound them, and the pharmacist's error margin introduced more variability into the treatment group than the drug effect itself. We caught it during the pilot phase, but it cost us six weeks and a revised IRB submission. The lesson was that the independent variable is not what you think it is. It is what actually reaches the subject through whatever production or delivery pipeline you have built. Operational definitions matter more than theoretical ones. When I define temperature as an independent variable, I need to specify the range, the increment, the measurement device, the calibration schedule, and the acceptable tolerance. If your thermostat reads to the nearest degree and your hypothesis depends on a two-degree difference, your independent variable is already unreliable. I have seen people run regression analyses on temperature data collected with a $15 digital sensor that drifted by three degrees between readings. The dependent variable looked clean. The independent variable was garbage. Garbage in, garbage out, just with extra steps.
Dependent variables have their own traps. The most common one is measuring something that looks like what you want but is actually a proxy for something else. If you are studying patient recovery time after surgery, counting days until discharge is convenient, but discharge dates depend on insurance approvals, bed availability, and family logistics as much as they depend on clinical recovery. A patient can be medically ready but stuck in the hospital for four extra days because the nursing home transfer took a week. Your dependent variable now measures insurance bureaucracy instead of surgical outcomes. I switched one study to use a validated functional mobility scale measured at consistent intervals instead of discharge dates. The effect size doubled because the noise dropped by roughly forty percent.
Structuring the Experiment Around the Variables
Random assignment is the standard answer for handling confounding variables, and it works well when your sample is large enough. With fewer than two hundred participants per group, randomization can still produce imbalanced groups on baseline characteristics you did not think to measure. I ran a study with eighty participants per arm where the treatment group ended up significantly older on average. The difference was small in absolute terms but enough to skew the dependent variable because age was a known moderator. Blocking by age before randomization fixed it, but only after the first analysis flagged the imbalance. A preliminary power check on baseline covariates would have caught this before data collection started. Counterbalancing matters when your independent variable has multiple conditions and participants experience more than one. Order effects can contaminate the dependent variable through fatigue, practice, or carryover. In a cognitive task study, I noticed that performance on the second condition improved regardless of which condition came second. People got better at the task itself, not at the specific condition. Switching to a between-subjects design eliminated the order effect entirely, though it required doubling the sample size. There is no free lunch in experimental design. You trade one type of noise for another, and you need to know which trade is cheaper for your situation. Blinding is another variable control method that people apply mechanically without checking whether it is actually possible. Double-blind designs sound ideal, but they break down when the independent variable has obvious physical differences. If one condition is a visible injection and the other is a pill, participants and providers will know who received what. Placebo controls help, but they do not eliminate the signal from a visible procedure. I once saw a pain intervention study where the control group figured out they were in the control arm because they did not receive the characteristic warmth from the treatment device. Their pain reports dropped because expectation changed, not because the mechanism was irrelevant. The dependent variable was measuring belief as much as physiology.
Get the Full Details

Measurement and Detection Limits
Your ability to detect an effect depends on the reliability of your dependent variable measurement. If your instrument has high measurement error, the attenuation bias will shrink your observed effect size toward zero. A correlation that is actually 0.40 can appear as 0.20 if the measurement reliability is around 0.50. I calculated this directly in a psychology lab where we compared a newly developed survey scale against an established one. The new scale had acceptable validity but poor test-retest reliability, and every hypothesis test came back weaker than the literature suggested. Switching to the reliable scale restored the expected effect sizes within two data collection waves. Sample size planning should account for measurement reliability, not just effect size and alpha level. Standard power calculators assume perfect measurement. When I adjusted the calculation for a reliability coefficient of 0.65, the required sample size jumped from 128 to approximately 314 participants to maintain 80 percent power. Most grant applications ignore this adjustment, which means many published null results are really just underpowered studies disguised as evidence of no effect. There is a practical upper limit to how much you can improve measurement without changing the entire study design. Adding more items to a scale increases reliability through parallel forms, but participant fatigue also increases, which can degrade data quality on other measures. The optimal point is usually around ten to twelve items per latent construct when administration time is limited to fifteen minutes. Beyond that, you are trading one source of noise for another.
When the Framework Breaks Down
Certain research questions cannot be addressed with standard independent and dependent variable structures. Observational data with strong confounding, ecological studies with aggregated units, and time-series data with autocorrelation all require different frameworks. I attempted to run a randomized experiment on workplace productivity interventions across five hundred branches, but the organizational structure made randomization impossible. Management could not assign individual employees to conditions without creating resentment and turnover. The best design I could implement was a staggered rollout with difference-in-differences analysis, which is a completely different analytical approach than standard ANOVA or regression on independent and dependent variables. It worked, but the causal claims were weaker, and the confidence intervals were wider because the design accepted a lower internal validity in exchange for feasibility. Small effect sizes in complex systems are another scenario where the variable framework reaches its limit. In organizational behavior research, most documented effects fall below 0.10 standard deviations. At that magnitude, even a perfectly designed experiment requires thousands of participants to detect anything meaningful. The independent variable exists, the dependent variable is measured well, and the study is properly powered, but the real-world impact is negligible. Recognizing this before investing in a massive study saves resources and prevents the false conclusion that the phenomenon does not exist simply because the study was too small to see it. Mediation and moderation complicate the simple independent-then-dependent-variable model. When a third variable explains the mechanism, the direct effect can disappear while the indirect pathway remains. I studied a training program where the direct effect on performance was null, but the indirect effect through self-efficacy was substantial. The initial interpretation would have been that the training was useless. The mediated model revealed that the training worked exactly as intended by changing the psychological mechanism, which then changed performance. Skipping the mediation analysis would have produced a misleading conclusion.
Practical Steps Before You Begin
Write out the causal diagram before touching the data. List every variable that could influence the dependent variable, mark which ones you can control, which ones you can measure, and which ones you must accept as uncontrolled noise. This diagram forces you to confront assumptions you would otherwise skip. I have found that two hours spent on this exercise typically prevents three months of wasted data collection. Run a pilot with the full measurement protocol, not a simplified version. The pilot will reveal timing issues, instrument malfunctions, and participant confusion that power calculations cannot predict. My pilot phase usually runs for two to three weeks and costs roughly ten percent of the total budget, but it catches the problems that cause the majority of protocol failures. Skipping it saves time upfront and loses it later through revisions, re-recruitment, and re-analysis. Register the study design before data collection if the journal or funding body requires it. Registration does not improve the quality of the experiment, but it prevents selective reporting of significant results, which has become a major credibility problem in fields that rely heavily on null hypothesis testing. The register creates a public record of what you planned to test, how many participants you intended to recruit, and which analysis path you committed to follow. Deviations after registration must be documented, which reduces the incentive to chase p-hacking as a default strategy.