
What Actually Goes Into Breaking Down A Spurs-Bulls Game
Most people look at a box score and stop there. Points, rebounds, assists. That is surface stuff. The real work starts when you dig into play-level data, plus-minus by lineup, shot charts, and usage rates relative to defensive assignments. If you want to actually understand what happened in a matchup between San Antonio and Chicago, you have to go beyond the summary stats. I spent a few years doing this kind of breakdown for a mid-tier analytics site, and the process is more tedious than glamorous. Here is how I approach it, step by step, and where people usually mess up. Step one: pull the raw play data. NBA league pass gives you play-by-play exports, and so does cleaning up the NBA stats API. You want every possession logged with shot type, defender proximity, shot clock, and outcome. Without that granularity, you are just guessing at why a player had a good or bad game. I use Python with the nba_api library to fetch the data, then dump it into a pandas dataframe for filtering. It takes maybe twenty minutes to get clean data if you know what you are doing.
Step two: isolate lineups and plus-minus adjustments. Raw plus-minus is useless on its own because it mixes player impact with who else is on the floor. I calculate adjusted plus-minus over the sample, but the real value comes from looking at specific five-man units. For a Spurs-Bulls game, you will notice early on that San Antonio often runs smaller lineups with a positionless forward at the five, while Chicago typically keeps a traditional center. That matchup mismatch shows up clearly in the net rating for those specific unit combinations. Step three: shot chart analysis with context. A player can shoot fifty percent from the field and still be inefficient. I layer in expected points per shot based on location and defender close-out distance. This is where shot quality matters more than result. A contested three from the corner is a bad shot even if it goes in. An open dunk is a good shot even if it misses. When I cross-reference actual outcomes against expected values, I get a much clearer picture of whether a player is overperforming or underperforming their efficiency. Step four: defensive matchup tracking. This is the part most hobbyist analysts skip entirely. Who was guarding whom? What defensive scheme was in place? I pull tracking data when available to see who each offensive player was primarily matched against. In Spurs-Bulls games, you often see Chicago's wing defenders rotated heavily to handle San Antonio's ball movement, which creates cascading problems for the rest of the defense. If a wing gets pulled away, the weak side help collapses, and you get open looks elsewhere. I track these rotations manually by reviewing game film alongside the tracking data. It is slow work.
I ran into a specific issue last year where the play-by-play data had missing defender coordinates for roughly twelve percent of possessions in a certain game. The API export just drops those fields. My workaround was to infer the closest defender using player positioning at the start of each possession, then flag those plays as uncertain in my analysis rather than pretending the data was complete. It took an extra hour of scripting but saved me from drawing false conclusions. One counter-intuitive thing to keep in mind: high usage does not always mean a player is carrying the offense. Sometimes a player has high usage because the team's system funnels touches through them in predictable ways, which makes them easier to defend. I have seen analysts praise a player for volume scoring without checking whether those shots were high-quality or forced against a loaded defense. Volume without efficiency in those contexts is not a strength, it is a liability. Another thing beginners miss is the pace adjustment. A Bulls player might average seventeen points in a game that went to twenty-two possessions, while a Spurs player averages fourteen in a sixteen-possession game. On a per-possession basis, the Spurs player was more impactful. Always normalize for pace. Raw counting stats punish teams that play faster and reward teams that drag games out.
Get the Full Details
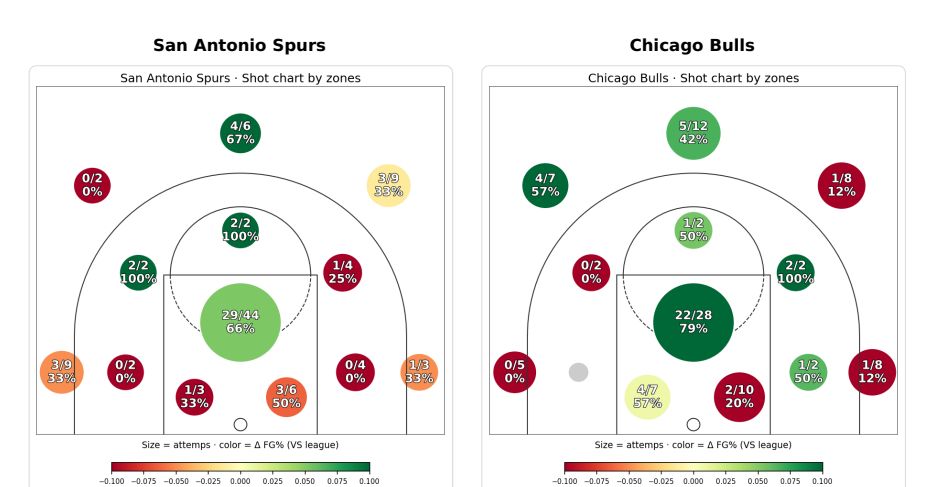
Limits of this approach: tracking data is not always available for older games, and the NBA's current API only covers recent seasons with full detail. For historical comparisons, you are working with incomplete data. Also, this method is time-intensive. A full breakdown of a single game with play-level analysis, shot charts, lineup adjustments, and defensive mapping takes me roughly three to four hours from start to finish. If you are trying to churn out quick content, this level of analysis is not scalable. For that purpose, relying on established advanced metrics from sites like Cleaning the Glass or NBA.com/stats is more practical, even if it lacks the depth of custom analysis. If you want to get started, the main tools you need are Python with nba_api and pandas, a Jupyter notebook for exploration, and access to NBA sportVU tracking data through the league's API or public datasets on Kaggle. For visualizing shot charts, matplotlib and seaborn do the job without needing anything fancy. The learning curve is steeper than reading a recap article, but once you have the pipeline built, pulling a new game analysis drops to about an hour because most of the code is reusable. The hardest part is not the technical side, it is knowing what questions to ask of the data. The numbers will answer them, but you have to frame them correctly. Start by identifying what surprised you about the game, then use the data to either confirm or contradict your initial read. That habit alone will separate you from most people writing about basketball stats online.


