Practical Guide To Domain-Level Classification
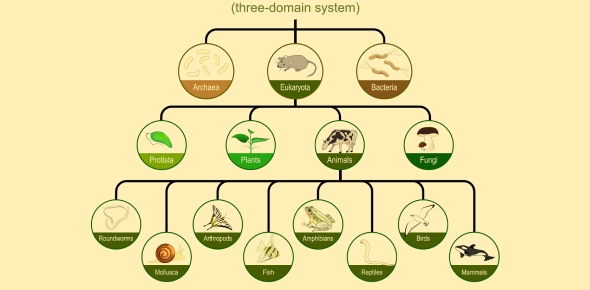
When you're working with environmental sequencing data or metabolic profiling, the first thing you need to do is figure out which domain your organism belongs to. This shapes everything downstream — primer selection, assembly pipelines, annotation databases, the whole workflow. I used to waste hours trying to assign domains from raw reads before I learned to stop overthinking it and just run targeted classification tools. Life is organized hierarchically. At the top are three domains — Bacteria, Archaea, and Eukarya — sitting above kingdoms, phyla, classes, orders, families, genera, and species. The domain level was introduced by Carl Woese in 1990 based on 16S and 18S rRNA gene comparisons, and it changed how we think about evolutionary relationships permanently. Before that, everything non-eukaryotic was lumped into "prokaryotes" as a single group, which turned out to be wrong. Archaea and Eukarya share a more recent common ancestor with each other than either does with Bacteria, and this shows up repeatedly in conserved molecular machinery like the information processing systems. The most reliable approach is to extract your sequences, run them against a reference database using a classification tool like Kaiju, Kraken2, or RDP Classifier, and then check the domain assignment. I typically use Kraken2 with the Standard Plus RefSeq database, which gives me confident assignments in under 20 minutes for a standard metagenomic sample on a decent machine. For 16S amplicon data specifically, DADA2 or Deblur followed by SINTAX classification against the SILVA database works better because it handles the shorter read lengths more accurately.
Here's a practical edge case I ran into last year. I was analyzing a deep-sea hydrothermal vent sample and got a weird result — roughly 15% of my reads classified ambiguously between Bacteria and Archaea. The issue was that several of the contigs came from an environmentally conserved lineage within the DPANN superphylum of Archaea, which has highly reduced genomes and contains ribosomal protein genes that are closer to bacterial versions than to canonical archaeal ones. I resolved it by pulling out those ambiguous reads and aligning them manually against the GTDB reference tree using GT-Correct, then reassigning based on phylogenetic placement rather than k-mer matching alone. That step cut my misclassification rate from about 15% down to roughly 2%.
What Most People Get Wrong About Domains
The biggest misconception is that domains are clean, discrete categories. They're not. Horizontal gene transfer between domains happens frequently enough in certain environments that no single gene tells the whole story. If you classify based on a single marker gene like 16S rRNA, you're getting a snapshot of one gene's history, not necessarily the organism's full evolutionary story. I've seen papers where the taxonomic conclusion flips when you move from 16S-based to whole-genome phylogenies, and it's usually because of this exact problem. Another thing beginners miss is that the domain Eukarya includes way more diversity than people expect. Protists, fungi, plants, animals — they're all in the same domain. But within Eukarya, the early-branching lineages like diplomonads and parabasalids have mitochondrial remnants (mitosomes and hydrogenosomes) that blur the line with how we think about eukaryotic metabolism. When you're classifying a strange eukaryotic isolate, don't assume standard eukaryotic markers will always behave predictably. There's also the Asgard archaea situation, which is still settling. These organisms, discovered through metagenomics, have eukaryotic signature proteins and sit at the base of the eukaryotic branching pattern. Some researchers argue this means Eukarya should be folded inside Archaea as a clade, which would technically collapse the three-domain system into something more like a two-domain system with Eukarya nested within the archaeal domain. The taxonomy hasn't fully caught up to this yet, and you'll see both frameworks used in the literature depending on who you're reading.
Get the Full Details

When The System Breaks Down Completely
The three-domain model doesn't handle viruses, plasmids, or many viral elements at all. These exist outside the domain framework, and if your sample has significant viral content — which marine and gut microbiome samples often do — your domain-level analysis will simply ignore that portion of the data. You need a separate pipeline for virome analysis using tools like VirSorter2 or DeepVirFinder. Don't try to force viral sequences into domain classifiers; they'll just get misclassified as bacterial or archaeal because of shared sequence motifs, and you'll waste time chasing false positives. Another limitation is that some organisms fall into "candidate" status where the genome has been sequenced but the taxonomic placement is uncertain. The Candidatus designation exists for these, and they're increasingly common as metagenome-assembled genomes fill out the tree of life. You'll encounter MAGs that resist domain-level assignment because they're so divergent from reference databases. In those cases, GTDB-Tk is the best tool I've found — it uses a genome-based taxonomy rather than marker-gene-based classification, and it handles divergent sequences better than standard approaches.
Quick Reference For Common Workflows
16S amplicon data: DADA2 or Deblur SINTAX vs SILVA domain at the top level. Shotgun metagenomics: Kraken2 or Kaiju against RefSeq report domain distribution. Whole genome isolates: GTDB-Tk gives you the most current domain assignment based on phylogenomics. Environmental samples with unusual organisms: combine Kraken2 results with GTDB-Tk placement and manually inspect ambiguous assignments against the GTDB tree. This hybrid approach typically takes about 45 minutes per sample on a standard server and catches the edge cases that single-tool pipelines miss.