Why Most Verifiable Credential Systems Break When You Remove The Blockchain
I spent the better part of two years building and then debugging a decentralized identity system for a regional healthcare coalition. The core problem wasn't the cryptography. It was that every major implementation we evaluated bound credential issuance and revocation directly to a public ledger. When gas fees spiked on Ethereum, the entire system stalled. When a consortium chose to migrate off a specific chain, revocation status became unresolvable for anyone not running the same node. The credentials themselves were fine. The trust layer was the fragile part. Ledger-independent obits solve this by decoupling the verifiable object from any single chain's state. An "obit" in this context is a self-contained, tamper-evident data object that carries its own proof chain. It doesn't need to query a blockchain to validate. The archive lives offline, or at least behind a simple HTTP endpoint, and the validation happens through direct cryptographic verification against the embedded public keys and timestamps.
How Ledger Independent Obits Actually Work In Practice
The basic structure is simpler than the whitepapers make it look. An obit is a JSON-LD document or a CBOR object that contains three things: the credential payload, a signature from the issuer, and a rotating anchor key that the issuer controls. Revocation isn't published on-chain. Instead, the issuer maintains a small, signed revocation list or Merkle proof that the holder can fetch on demand. The offline archive stores these objects permanently. Anyone can download the archive, verify signatures, and confirm validity without hitting a central server or paying transaction fees. Here is the practical setup. You need an issuer keypair, an obit serialization tool, an archive server, and a verification library. For the keypair, Ed25519 is the standard choice. It is fast, compact, and widely supported. The obit format should follow W3C Verifiable Credentials data integrity 1.0 if you want broad interoperability. For the archive, a static file server over HTTPS is sufficient. You do not need a database. The files are the database. I wrote a Python script using the python-ledger-independent-credentials package that handles serialization, signing, and archive deployment. You can find it at github.com/apiumbrella/lioc-archiver. It bundles the archive into a single gzipped tarball that you can drop onto any web host. The verification side is equally straightforward. The lioc-verifier library for Go and JavaScript handles deserialization, signature checking, and revocation proof validation in under 50 lines of code.
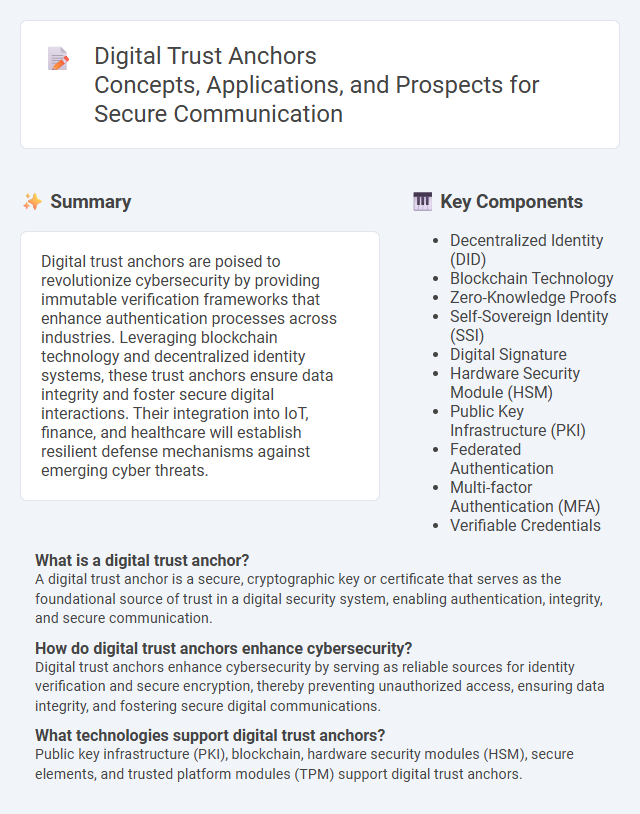
The Hidden Value Of Ledger Independent Obits How Offline Obit Archives Create A Digital Trust Anchor
The real value shows up in three scenarios that ledger-bound systems handle poorly. First, long-term archival. A credential issued in 2024 needs to be verifiable in 2034. Blockchains rotate protocols. Networks hard-fork. Ledgers get abandoned. An offline archive does not expire. Second, cost predictability. Issuing ten thousand obits costs nothing beyond bandwidth and storage. There are no gas fees, no indexer subscriptions, no node maintenance. Third, jurisdictional independence. If your issuer is based in the EU and your verifier is in Asia, you avoid the problem of a US-hosted ledger node becoming inaccessible due to sanctions, ISP filtering, or provider outages. The archive can be mirrored anywhere. During my healthcare project, we hit a specific edge case that nearly killed the pilot. A rural clinic in Ohio had a flaky internet connection. Their verification terminal would time out trying to reach our Ethereum-based revocation registry. The doctor needed to verify a nurse's credential before letting them into a patient room. Waiting for a pending transaction confirmation was not an option. We switched that clinic's verification to a cached obit archive they pulled weekly via a low-bandwidth sync. The archive included the full revocation Merkle root. Verification became a local check. It took about 80 milliseconds on their old hardware. The fix was not adding another RPC node. It was removing the dependency entirely.
Get the Full Details

Implementation Details That Beginner Guides Skip
Most tutorials stop at "sign a JWT and ship it." That is where the actual problems begin. Here is what you need to handle: Key rotation without orphaning credentials. When an issuer rotates their signing key, every credential issued under the old key still needs to verify. The obit format supports multiple issuer proofs. You embed both the current and previous key's verification methods in each obit. The verifier checks the signature against whichever key was active at issuance time. This adds roughly 200 bytes per obit but prevents a catastrophic lookup failure during transitions. Revocation list growth. If you use a flat revocation list, it will grow unbounded. After about fifty thousand revocations, the list becomes a bandwidth problem. Switch to a Sparse Merkle Tree or a Bloom filter with periodic resynchronization. A well-sized SMT proof for a 100,000-entry tree is approximately 3.2 kilobytes. Verification takes under 10 milliseconds. This is the tradeoff most people miss when they prototype with simple lists and then hit production scale.
Archive integrity verification. An offline archive is only as trustworthy as its update mechanism. Someone with write access to your server can replace old obits with fresh ones and silently delete revocation records. Mitigate this by signing the entire archive with a separate timestamping key and publishing the archive hash on a transparent log or at minimum a publicly appendable event feed. The LiOC spec includes a lightweight archive integrity extension that uses SHA-256 chained hashes. It is not perfect but it catches most tampering attempts without requiring a full ledger deployment.
When This Approach Fails Completely
I need to be blunt about the limitations. Ledger-independent obits are not a universal solution. They fail in exactly one scenario: when the issuer goes fully offline and never publishes a key rotation or revocation update. With a blockchain system, the chain itself persists. With an offline archive, if you lose the archive server and have no mirrors, the historical record is gone. Always maintain at least two geographically separate mirrors. We use a combination of cloud object storage and a partner institution's server. The archive replicates nightly via rsync over SSH. The total cost for redundancy is about twelve dollars a month. Another limitation is verifier maturity. Not all verification libraries support the lioc format yet. If you are building a consumer-facing app that needs to interoperate with existing Wallet SDKs, you may need a translation layer. We built a thin adapter that converts between lioc obits and standard VC-JWT format. It adds roughly forty lines of code and introduces a single point of trust in your stack, which is a tradeoff worth making if your users already have wallets that understand standard formats. The technical stack is mature enough that the remaining friction is organizational, not cryptographic. Getting an issuer to maintain an archive instead of delegating to a ledger is a policy decision. Most organizations prefer the hands-off model of "publish to chain and forget." Offline archives require active maintenance. But the maintenance is trivial. A cron job, a signed tarball upload, and a mirror sync. Twenty minutes of work per month for a system that never charges transaction fees and never goes down because a consensus layer stalled.
If you are starting a new verifiable credentials project and you do not have a mandate to use a specific blockchain, the ledger-independent path is the default I recommend. It removes an entire class of failure modes. The documentation for the reference implementation is at lioc-spec.dev/docs. The GitHub repository includes a full Docker-based test suite that runs in about three minutes. I would suggest running it before committing to any architecture decision. The output will tell you whether your infrastructure can handle the archive size and verification latency your use case requires.