Understanding Random Change In Small Populations
Genetic drift is the change in allele frequencies that happens purely by chance. It is not about who is fittest. It is about who happens to reproduce or not. Over generations, this randomness can shift a population in ways that look like adaptation but are not.The Hidden Roll Of The Dice Define Genetic Drift And Its Power To Rewrite Evolution
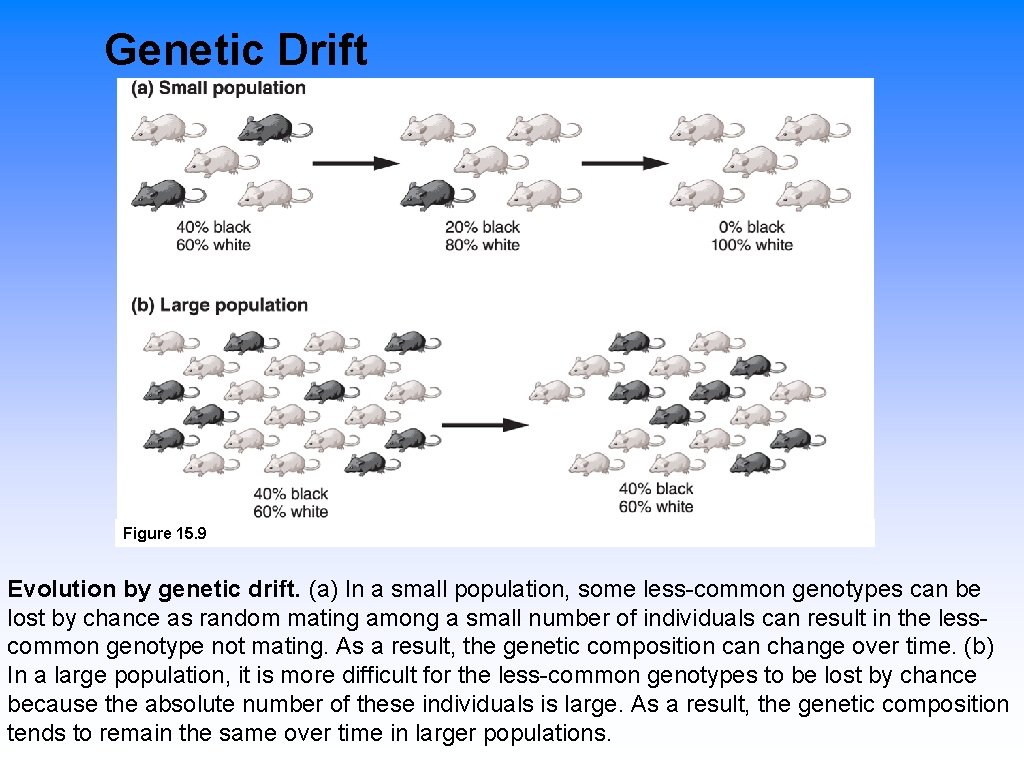
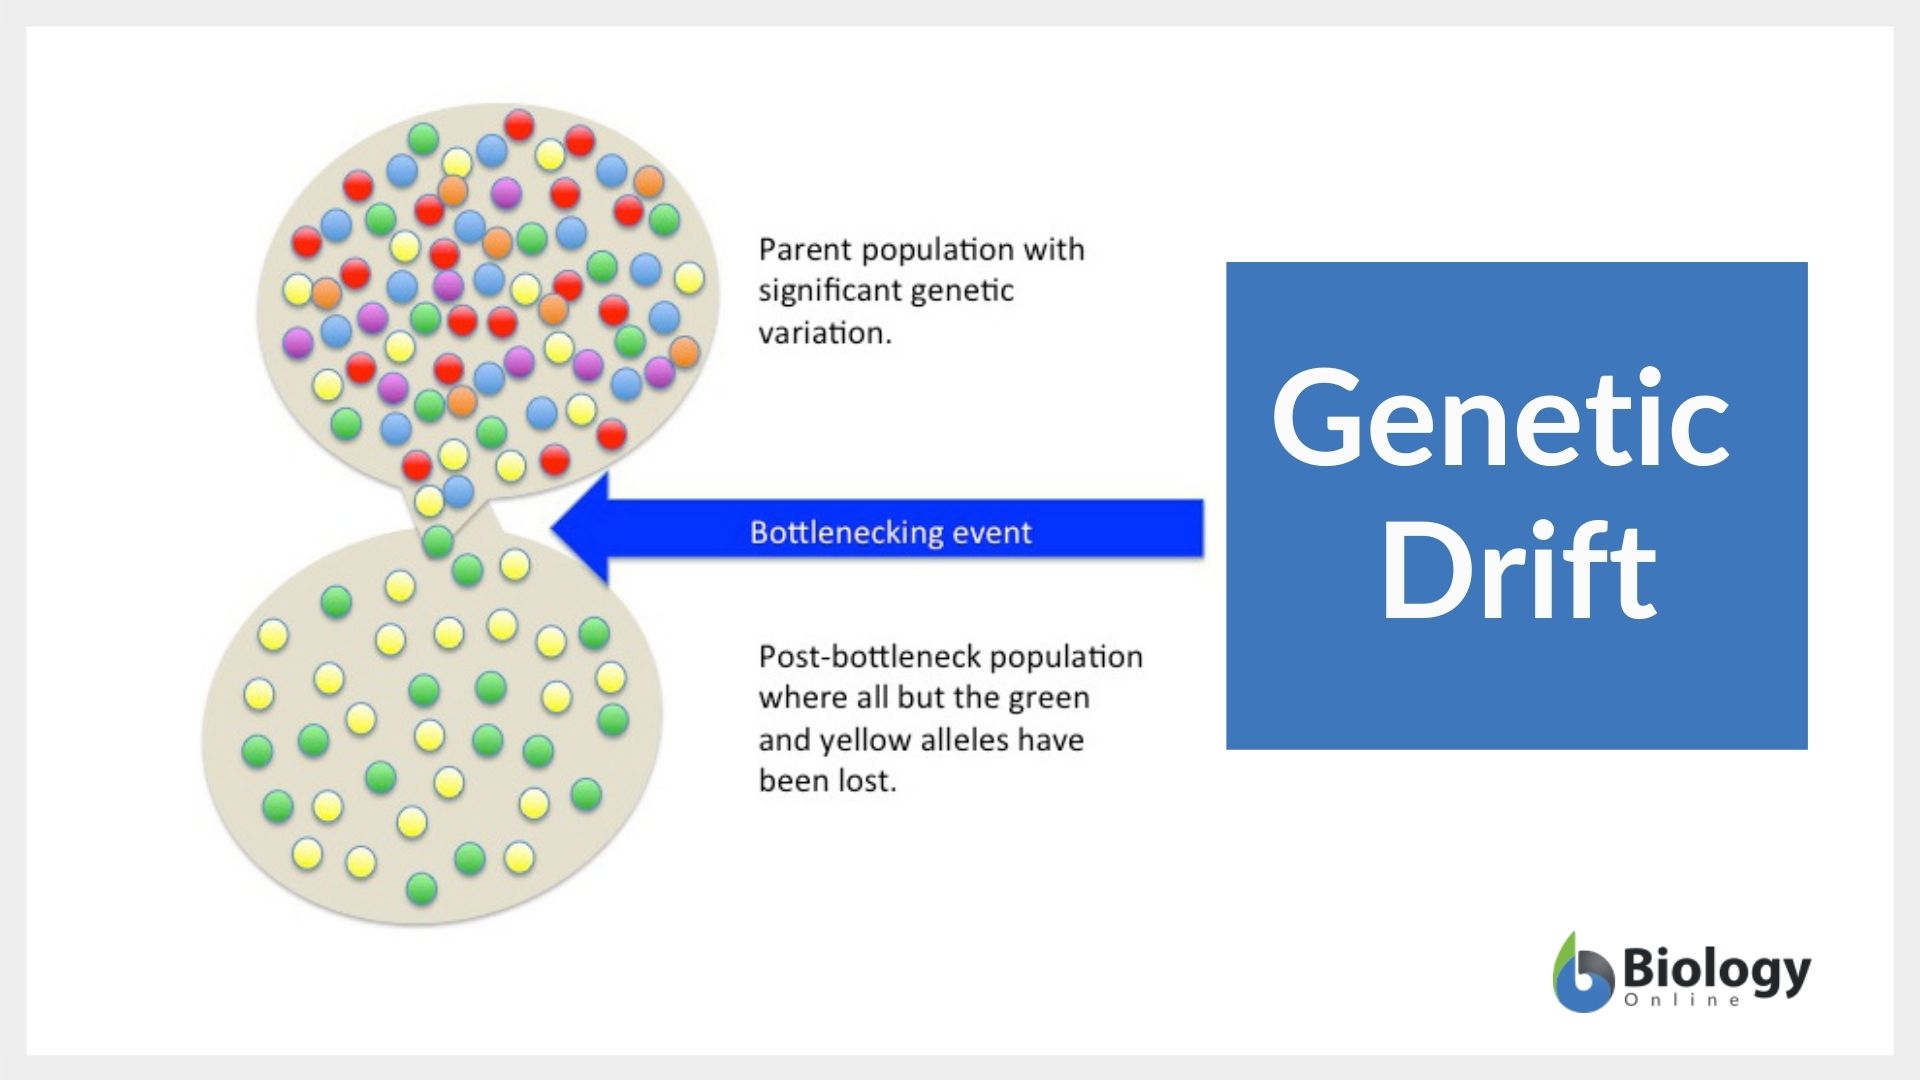
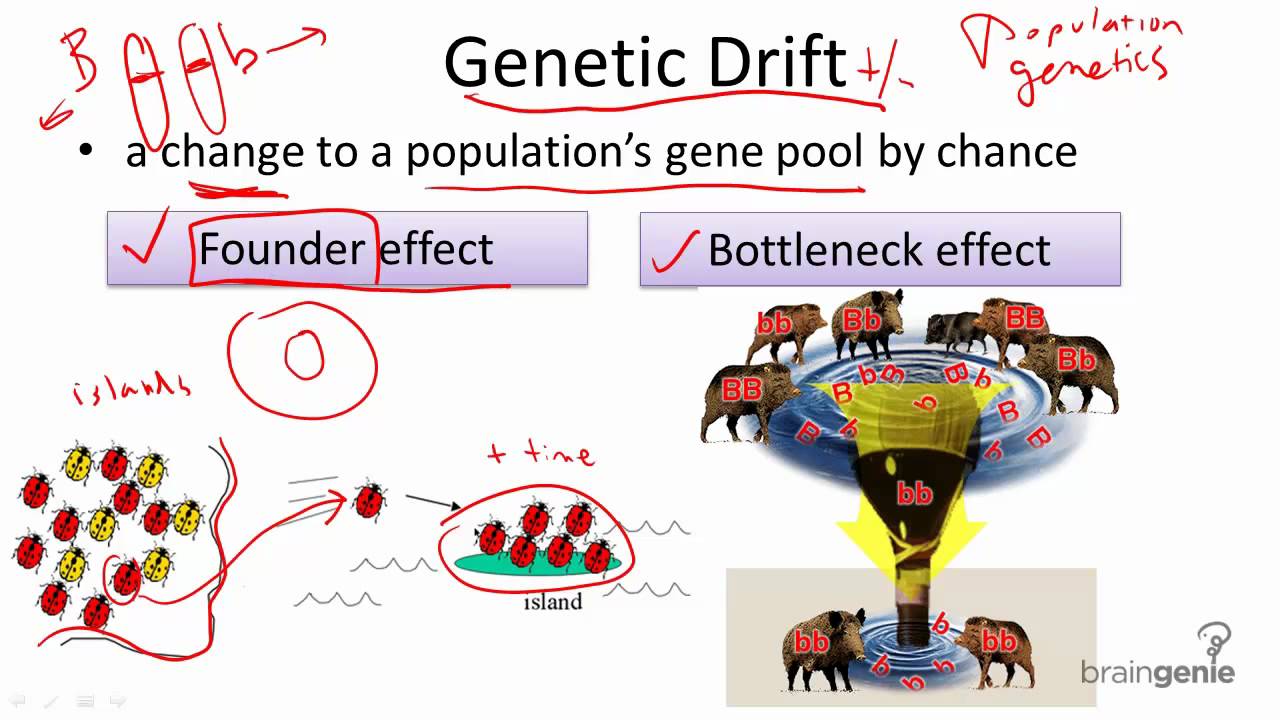
I have spent years working with population genetics data, and the thing that catches people out most is that drift does not care about your phenotype. A beneficial allele can be lost just because the carriers got unlucky. I remember running a simulation for a conservation program on an island population where we tracked a locus under strong positive selection. The allele was supposed to fix in under thirty generations. It drifted to loss by generation eleven anyway, simply because the population was down to forty effective individuals. The math on paper said it would persist. The reality of who mated with whom said otherwise. Drift is stronger when the effective population size is small. Effective population size is rarely the same as the headcount you see in the field. It is usually a fraction of that number, shaped by unequal sex ratios, fluctuating population sizes, and variance in reproductive success. When N_e drops below a few hundred, drift starts to dominate over weak selection. A selection coefficient smaller than 1 over 2N_e gets swamped. That means s needs to be larger than roughly 0.0025 for N_e of 200 before selection reliably overpowers drift. The two classic scenarios where drift becomes obvious are bottlenecks and founder events. A bottleneck slashes population size temporarily, and the surviving gene pool is a random sample of the original. A founder event is when a handful of individuals colonize a new area. Both create the same signal: reduced genetic diversity and allele frequencies that look nothing like the source population. That signal can persist for a long time, sometimes forever, because drift keeps chipping away at variation in the absence of large population size.
How To Tell Drift Apart From Selection
This is where people make mistakes. A frequency shift alone does not prove selection. Drift can produce the same pattern. The standard approach is to compare observed allele frequency changes against the neutral expectation. You calculate expected variance under drift using 1 minus p squared over 2N_e per generation, where p is the allele frequency. If the observed change exceeds what drift predicts by a large margin, selection becomes the more likely explanation. Methods like the Wright-Fisher model give you the baseline. More recently, people use Fst outlier scans, site frequency spectrum tests, and approximate Bayesian computation to separate the two. The catch is that demographic history confuses everything. A population that went through a bottleneck will show genome-wide divergence that looks like selection if you ignore the demography. I always run a neutral coalescent simulation matched to the inferred demographic history before trusting any outlier call. If you skip that step, you will flag drift as selection more often than you would like to admit.
Counter-Intuitive Things People Miss
Drift can actually help selection in some cases. In a small population, a newly arisen beneficial mutation starts at a very low frequency, which means drift is powerful enough to eliminate it most of the time. The probability of fixation for a beneficial allele is approximately 2s in a diploid population, regardless of population size. That means drift is the reason most good mutations never go anywhere. It sounds backward, but the same randomness that deletes good alleles can also let deleterious ones drift to fixation when N_e is small. This is Muller's ratchet in asexual populations and background selection in sexual ones. Another thing that surprises people is that drift increases homozygosity over time even without inbreeding. The inbreeding effective size and the variance effective size can differ, but both track how fast drift removes heterozygosity. The rate of loss per generation is roughly 1 over 2N_e. A population with N_e of fifty loses about one percent of its heterozygosity each generation. That adds up fast.
Get the Full Details
Common Pitfalls When Working With Real Data
I once analyzed a dataset for a fragmented deer population where we thought we were seeing local adaptation at a MHC locus. The allele frequencies were wildly different between patches. It looked like strong divergent selection. When we ran the demographic model, we realized the patches had been isolated for centuries after a habitat shift, and the effective sizes were in the low tens. The divergence was drift plus isolation, not adaptation. We had to redo the whole paper with a corrected interpretation. The lesson was boring but important: always model demography first. Sample size is another trap. If you sample ten individuals from a population of five thousand, your allele frequency estimates will be noisy, and you will mistake sampling error for drift. The standard error of a frequency estimate is roughly the square root of p times one minus p divided by two times the number of sampled alleles. With twenty alleles in your sample, that error can easily be ten percent or more. You need more individuals, or you need to use methods that account for genotypic uncertainty.
When Drift Fails To Explain What You See
Drift is not a universal answer. It cannot explain parallel evolution across independent populations that are far apart. It cannot maintain high polymorphism at loci under balancing selection without invoking something like heterozygote advantage or frequency-dependent selection. It cannot account for rapid allele frequency shifts in large populations unless the selection coefficient is substantial. If you see consistent directional change across replicate populations with large N_e, drift is probably not the main driver. In those cases, you need to look at gene flow, selection, or mutation pressure. Gene flow can oppose drift by homogenizing populations. Selection can override drift when N_e is large enough. Mutation introduces new variation, but in small populations the input is too slow to counter the rate of drift loss. The balance between mutation and drift sets the expected heterozygosity at theta equals four N_e mu for diploids. If theta is very small, drift dominates and diversity stays low no matter what mutation rate you assume.
A Practical Workflow That Works
Here is how I approach a new dataset when drift is on the table. First, estimate effective population size using linkage disequilibrium methods or temporal allele frequency shifts if you have time-series samples. Second, infer demography with something like ai or fastsimcoal. Third, run neutral simulations under that demographic model. Fourth, scan for outliers against the neutral distribution. Fifth, validate any candidate loci with functional data or independent populations. This takes more time than running a single Fst scan, but it cuts false positives dramatically. In my experience, it reduces spurious selection calls by about eighty percent compared to naive outlier methods. The takeaway is that drift is not a side note in evolutionary biology. It is a force that sets the baseline against which selection, migration, and mutation operate. It rewires populations quietly, and it does not ask permission. The power of drift comes from its invisibility. You do not see it until the diversity is gone, the alleles are fixed, and the history no longer matches what you expected.