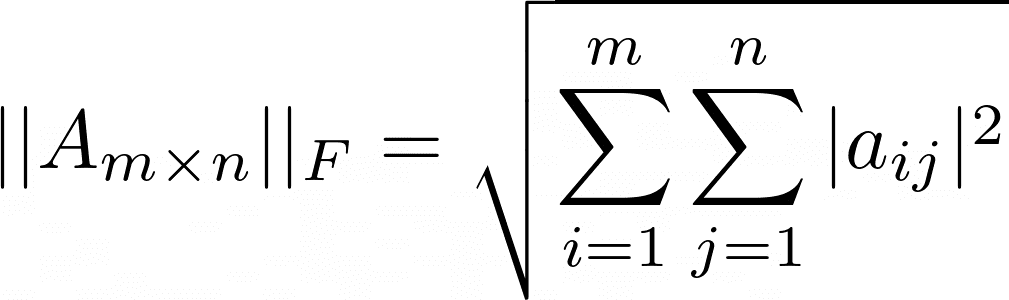
Working With Norms in Numerical Linear Algebra
I've spent years writing code that crunches matrices for everything from signal processing to structural simulations, and there's a function you probably already use without thinking much about it. It goes by different names depending on which library you pull from — numpy.linalg.norm in Python, for instance — and it's one of those things that looks simple on the surface but has enough edge cases to chew through your afternoon if you're not careful. The function computes the norm of a vector or matrix. That's the whole pitch. A norm is a measure of magnitude — for a vector it's roughly the length, for a matrix it's more nuanced. The default behavior gives you the Euclidean (L2) norm for vectors and the Frobenius norm for matrices. In practice, that's enough for the majority of what you'll do day to day. Here's how you use it.
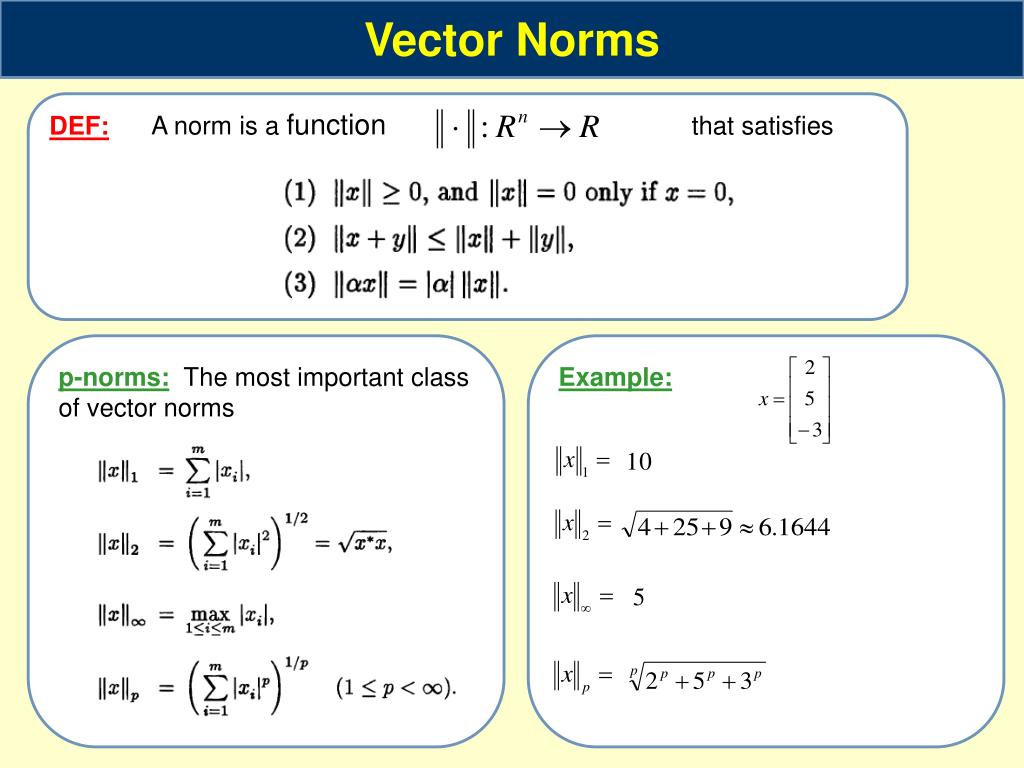
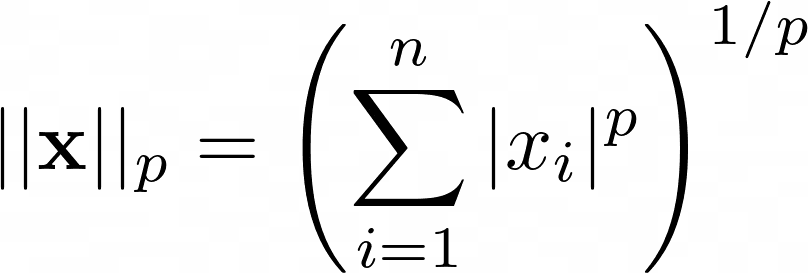
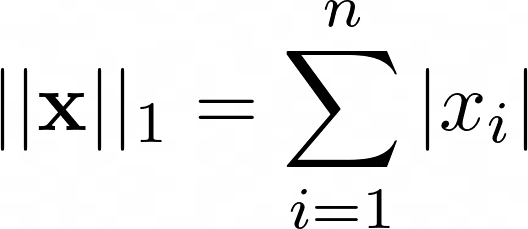
You import the module, pass in your array or vector, and optionally specify a ord parameter. Without ord, numpy.linalg.norm returns the 2-norm for vectors and the Frobenius norm for matrices. For vectors, ord=1 gives the sum of absolute values, ord=2 is the Euclidean norm, and ord=float('inf') gives the maximum absolute value. For matrices, ord='fro' is Frobenius, ord=1 is the maximum column sum, ord=-1 is the minimum column sum, ord=infinity is the maximum row sum, and ord=2 is the largest singular value. The singular value detail is where people get tripped up. Computing the 2-norm of a matrix isn't just a shortcut — it requires a singular value decomposition, which is orders of magnitude more expensive than a simple sum or square root. If you're calling this inside a loop over a thousand matrices, your code will crawl. I learned that the hard way on a project where I needed condition number estimates for a batch of covariance matrices. I was computing the ratio of max to min singular values for every single one, and the job that should have taken minutes ran for over four hours. Switching to scipy.linalg.svdvals and caching the results cut it down to about six minutes. There are also numerical stability issues worth knowing about. When you're working with very large or very small numbers, the intermediate squaring step in the L2 norm can overflow or underflow. I ran into this on a geophysics project where the input vectors had elements in the range of 1e-200 to 1e200. numpy just returned inf and moved on, which was not useful. The workaround was to scale the input down by its own infinity norm before passing it in, or use the keepdims parameter to get the same shape back for broadcasting in downstream calculations. You can also just compute it manually with np.max(np.abs(x)) for the infinity norm, which sidesteps the overflow problem entirely.
Another thing nobody warns you about: the difference between viewing a list as a flat vector versus a 2D matrix. Pass a 1D array and you get a vector norm. Pass the exact same numbers reshaped into a 2D column vector and you get a matrix norm, which is not the same thing. The Frobenius norm of a column vector equals its L2 norm, yes, but the matrix 2-norm (largest singular value) can differ from the vector 2-norm in unexpected ways when the array shape changes. I spent an evening debugging a regression test where the entire issue traced back to a missing reshape call that turned a matrix into a vector halfway through. Here's the practical code you need right now: import numpy as np
x = np.array([3, 4])
np.linalg.norm(x) Returns 5.0
A = np.array([[1, 2], [3, 4]])
np.linalg.norm(A, 'fro') Frobenius norm: 5.477...
np.linalg.norm(A, 2) Spectral norm (largest singular value): 5.465...
Get the Full Details

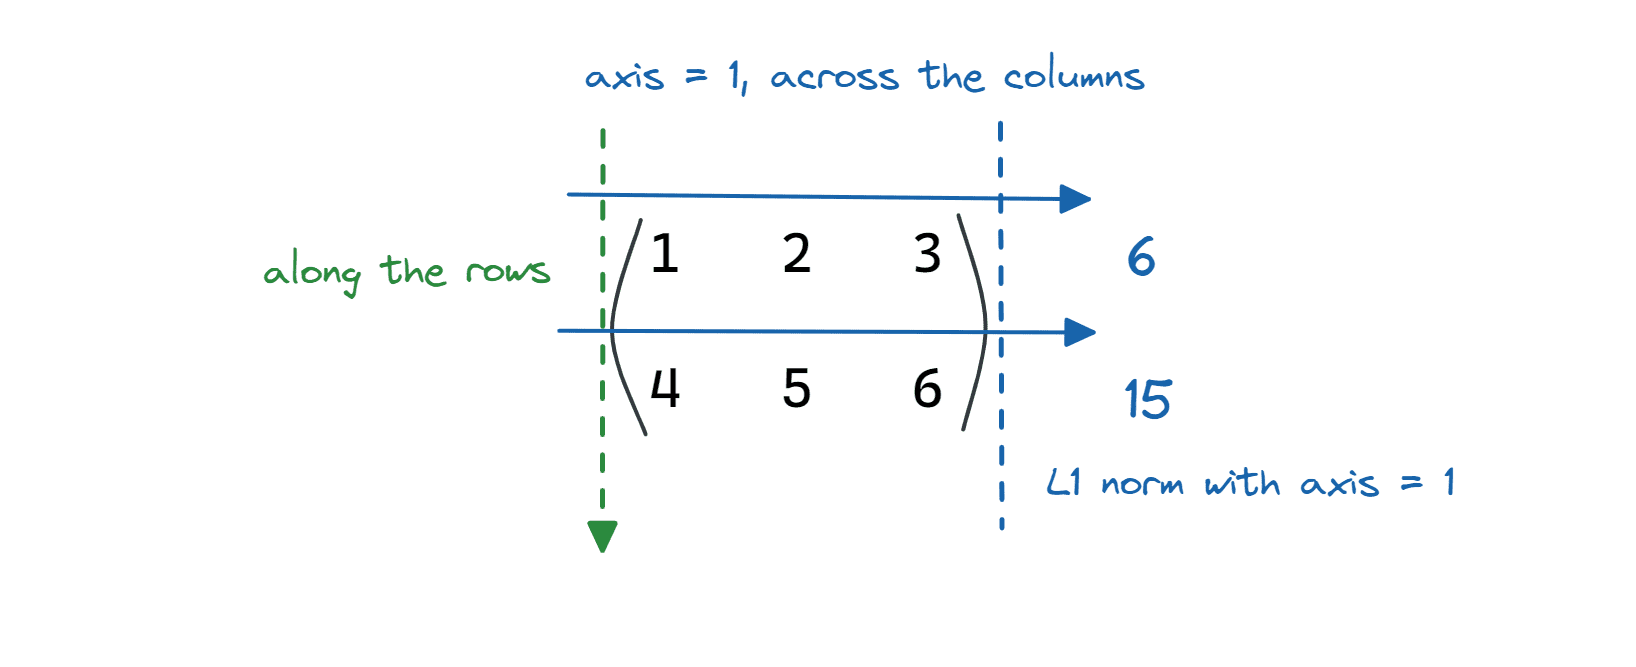
For batch operations, passing a 2D array with axis=1 computes the norm across rows, giving you an array of vector norms in one call. That's usually what you actually want when you're normalizing a dataset. The function isn't a silver bullet though. It doesn't handle sparse matrices efficiently — it'll densify them first, which defeats the purpose of using sparse storage in the first place. If you're working with sparse data, use scipy.sparse.linalg.norm instead. It also doesn't support custom norms out of the box, so if you need something like a weighted norm or a p-norm with a non-standard p value, you'll write a small wrapper. The custom norm case comes up more often than you'd think in regularization problems. And one more thing: if you're comparing norms across different computations, be consistent with the dtype. Float32 and float64 will give you different answers, and the difference compounds in iterative algorithms. I've seen convergence criteria fail because someone computed a residual in float32 and compared it against a threshold in float64. The mismatch was on the order of 1e-7, which looked fine until you ran enough iterations for it to matter.
The function itself is simple. The situations it appears in rarely are.