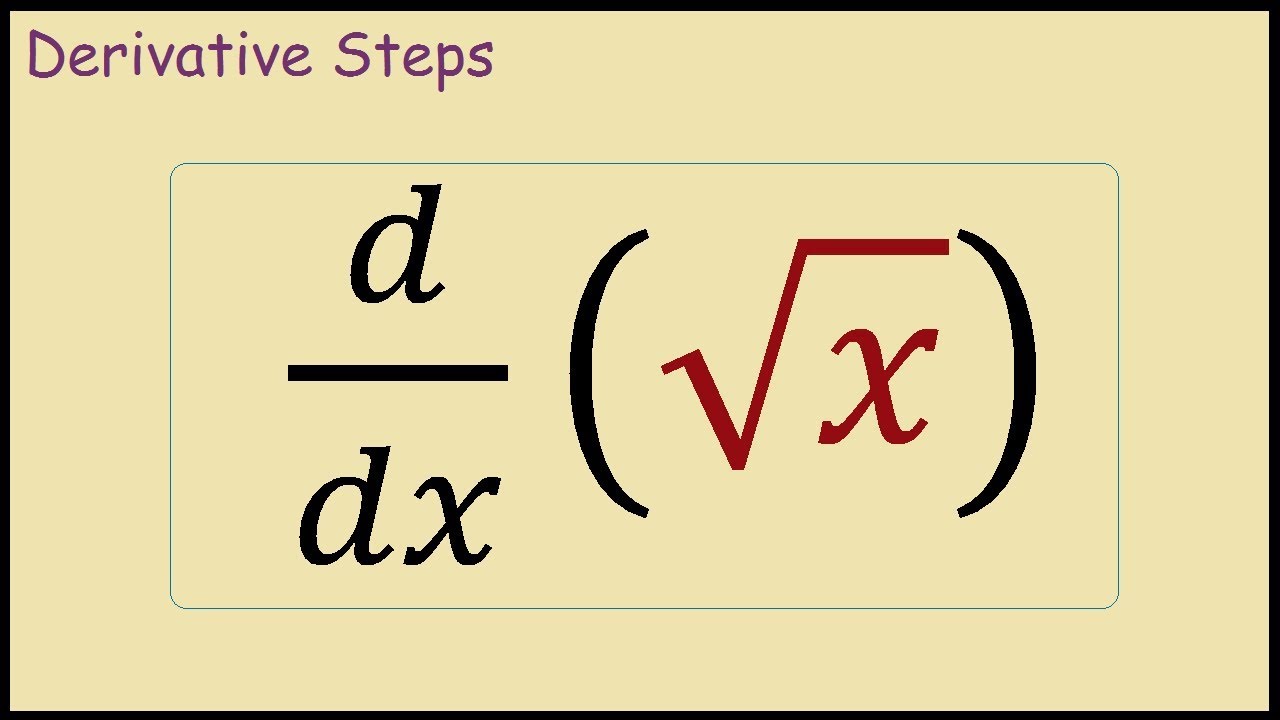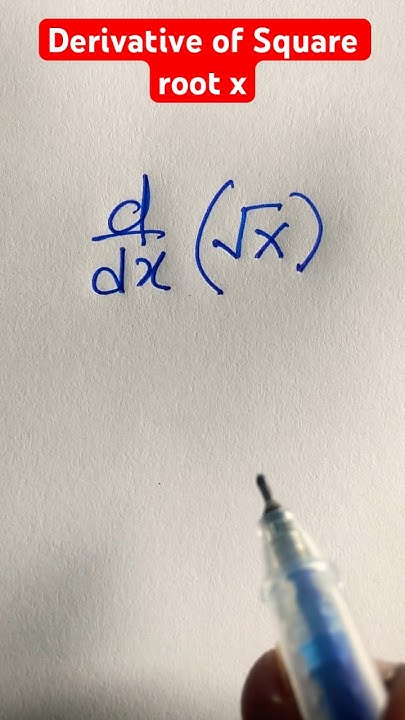Why This Derivative Shows Up Everywhere and Nobody Notices
You learn it in Calc 1, you forget it by midterms, and then you encounter it again when you are trying to optimize some cost function or model a physics problem. The derivative of the square root of x looks trivial until you need it under pressure. It is one of those foundational tools that quietly appears in engineering, economics, and data science workflows more than people realize. Here is the core formula: d/dx of sqrt(x) equals 1 over 2 times sqrt(x). Written out, that is 1/(2x). That is it. But the way you actually use this in practice involves rewriting, substitution, and occasionally catching yourself when the chain rule gets hidden inside a messy expression. I remember a project a few years back where I was fitting a decay curve to sensor data. The model had a term like sqrt(a + b*t), and I needed the gradient for the optimizer. Getting the derivative wrong by even a factor of two would have skewed the entire fit. I ended up rewriting the expression using rational exponents first, applying the power rule directly, and only then substituting back. The manual chain rule application caught an error I would have missed otherwise.
What people miss is that rewriting sqrt(x) as x^(1/2) before differentiating removes almost all ambiguity. The power rule becomes mechanical: multiply by the exponent, then subtract one from the exponent. You get (1/2) * x^(-1/2), which is exactly 1/(2x). The algebra is straightforward, but the mental shortcut of keeping everything in exponent form until the final step prevents more mistakes than anything else. The chain rule version shows up constantly. If you have sqrt(f(x)), the derivative is f'(x) / (2(f(x))). Simple in isolation, but errors accumulate fast when f(x) itself is a quotient, a product, or a composite function. I have seen people drop the inner derivative entirely and just write 1/(2(f(x))), which is wrong unless f'(x) happens to equal 1. That mistake cost me about twenty minutes debugging a numerical integration script once. Another nuance that beginners regularly overlook involves the domain. The derivative of sqrt(x) is undefined at x equals zero. The function itself is defined there, but the slope goes vertical. If you are working with any model that approaches zero, you will hit a singularity. In my experience, the workaround is usually to add a small epsilon constant or switch to a parameterization that avoids the boundary altogether. For example, instead of optimizing sqrt(x) directly near zero, I sometimes reparameterize using u equals x squared, which shifts the problematic region away from the origin entirely.
The implicit differentiation angle also deserves mention. If you start with y equals sqrt(x), square both sides to get y squared equals x, then differentiate implicitly, you recover the same result. This approach is less direct for simple cases, but it becomes essential when sqrt(x) appears inside an equation alongside other terms that make explicit isolation impractical. I use this technique regularly when working with constraint optimization problems where the objective function couples multiple variables under a radical. One counter-intuitive thing worth noting: the derivative gets smaller as x increases, not larger. The slope of sqrt(x) is steep near zero and flattens out. This matters when you are doing numerical methods because step size selection around zero requires far more care than around larger values. A fixed-step method that works fine at x equals 100 will oscillate or diverge near x equals 0.01 if you do not adjust accordingly. I typically reduce the step size by an order of magnitude whenever the domain includes values below one. There is also the matter of higher-order derivatives, which rarely get taught but show up in error analysis. The second derivative of sqrt(x) is -1/(4x^(3/2)). It is negative everywhere in the domain, confirming the concave down shape, and it grows in magnitude rapidly as x approaches zero. If you are doing Taylor approximations or error bounds involving sqrt(x), this term dominates the remainder and you cannot ignore it.
Get the Full Details

The most practical application I run into involves related rates and optimization. Suppose you are designing a container where the volume scales with the square root of the radius, or calculating the marginal cost where the cost function involves a square root term. Setting the derivative equal to zero gives you critical points, and since the derivative of sqrt(x) is never zero for any positive x, the critical points come entirely from wherever the chain rule numerator hits zero. This is a detail that trips people up in homework and in real work alike. Another area where this derivative proves useful is numerical root finding. Newton's method applied to functions involving square roots converges faster than you might expect in many cases, provided you handle the zero boundary correctly. The method relies on the derivative at each iteration, and computing 1/(2x) is cheap enough that the overhead is negligible. The bottleneck is always the boundary behavior, not the calculation itself. If you want to work through examples, start with straightforward applications like sqrt(3x plus 2) or sqrt of x squared plus one, then move to cases where the radical appears in a denominator or alongside logarithmic terms. The pattern stays the same: rewrite with fractional exponents, apply the power rule, apply the chain rule, simplify. The simplification step is where most errors hide, so do not skip it.
I also recommend keeping a cheat sheet of common forms rather than deriving from first principles every time. Things like the derivative of sqrt(ax plus b), sqrt of f of x, and sqrt of a over x all follow predictable patterns once you internalize them. Speed matters when you are doing this under time pressure, and hesitation leads to sign errors and missing factors of two. There are limitations to being overly reliant on the algebraic derivative approach. When the function inside the radical is only available numerically, you cannot apply the chain rule symbolically. In those cases, finite difference approximations become necessary, and the accuracy depends heavily on your step size choice. I have found that central differences with a step size around the square root of machine epsilon give the best balance between truncation error and roundoff for double precision work. Anything larger introduces bias, anything smaller introduces noise. Automated tools can handle the symbolic differentiation for you, but they obscure the logic that matters when debugging. I still work through the steps manually at least once per problem to verify that the tool has not made an assumption I did not expect. Symbolic engines sometimes return piecewise results or branch cut selections that are correct mathematically but wrong for your specific application domain.
The bottom line is that the derivative of the square root of x is simple to state and deceptively tricky to apply correctly across a range of contexts. Mastering the rewrite-to-exponent technique, respecting the domain boundary at zero, and knowing when to switch to numerical or implicit methods will cover the vast majority of real-world cases you encounter. Most errors stem from skipping the simplification step or forgetting the chain rule, and both are preventable with a consistent workflow.