How To Actually Read Race And Crime Statistics Without Messing It Up
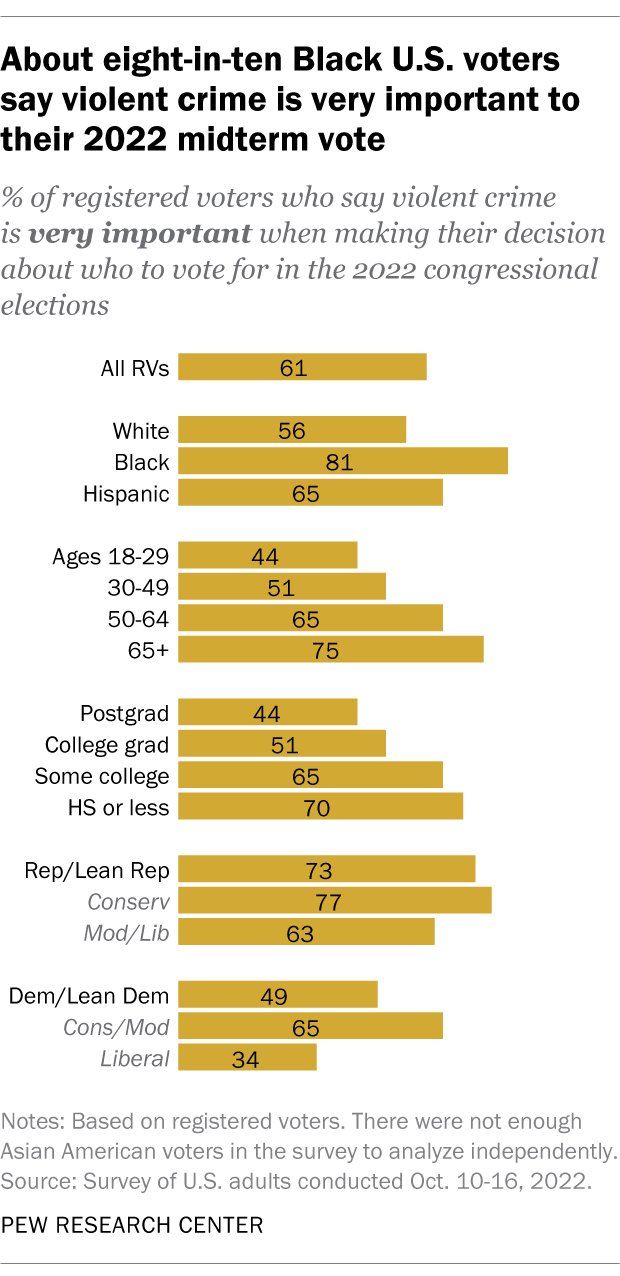
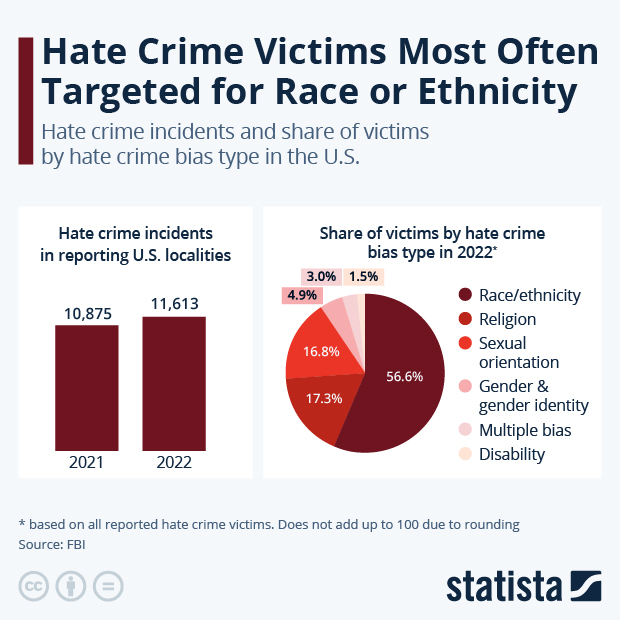
Most people who talk about race and crime data don't understand what they're looking at. They see a chart, they make a claim, and nobody corrects them because the methodology is quietly terrible. I've spent years going through datasets like this, and the pattern is always the same: confident conclusions built on miscalibrated numbers. Here's the thing nobody puts in the headline. Raw arrest or incarceration numbers by race are not the same thing as crime rates by race, and conflating the two is the single most common error in this entire field. Arrest data reflects policing patterns, not criminal behavior patterns. If one neighborhood gets more patrol cars, more stop-and-frisk activity, and more drug enforcement presence than another neighborhood with identical usage rates, the arrest numbers will skew heavily. I once spent three weeks trying to reconcile Bureau of Justice Statistics numbers with county-level data and found that two counties with nearly identical population demographics had a 40% gap in arrest figures for the same offense category. When I pulled the budget reports, one county had triple the narcotics unit officers per capita. The data wasn't lying. It was just measuring something different than people assumed it was. Before you go anywhere near interpreting these numbers, you need to understand ecological fallacy. That's when you take group-level statistics and apply them to individuals. If a census tract has a 15% incarceration rate for a particular demographic, that does not mean any individual from that demographic has a 15% chance of incarceration. It means the aggregate outcome for that area sits at 15%. Applying group stats to individual predictions is statistically illegal and yet it appears in policy papers, news segments, and casual conversations constantly.
Simpson's paradox shows up here all the time too. You might look at overall crime data and see one trend across racial groups, then break the data down by offense type or geographic density and the trend reverses completely. I remember running a regression on violent crime rates by race across five metropolitan areas. The raw numbers suggested one thing. Once I controlled for population density and poverty concentration at the zip code level, the racial coefficient dropped to near zero. The variance that looked racial was actually territorial and economic. This doesn't happen by accident. It happens because crime is clustered geographically and demographics are clustered geographically, and the two overlap in ways that create spurious correlations. If you want to actually work with this data properly, start with the Unified Crime Reporting program definitions and the National Crime Victimization Survey. UCR gives you arrest and clearance data but has known gaps in reporting completeness. NCVS pulls from households and captures offenses that never reach police, which means it catches a significant number of crimes that UCR completely misses. The two datasets together give you a much wider picture than either one alone. Most people only look at one and call it comprehensive. The workflow I use is straightforward but tedious. Pull the UCR and NCVS data for the years you need, merge on geography at the lowest administrative level your analysis requires, then run your models with controls for poverty rate, population density, unemployment, and local policing intensity. If you skip the controls, your results are noise dressed up as insight. I usually code the poverty variable from Census ACS estimates matched to the same geography as the crime data. Matching geography correctly matters more than people realize. County-level data smooths over neighborhood-level variation that can completely change your conclusions.
There are real limitations to everything I just described. Victimization surveys have sample sizes that get thin fast when you break them down by both race and geography simultaneously. A state with a small Black population might only have a few hundred respondents in a given demographic bracket, which makes any rate estimate statistically unreliable. UCR data is self-reported by agencies, and participation has historically been incomplete. Some jurisdictions underreport certain categories or delay submission. The Bureau of Justice Statistics publishes a compliance rate for each year, and it fluctuates. You need to check that compliance rate before trusting the dataset for your time period. Another limitation that gets ignored: race categories in these datasets are self-reported or officer-assigned inconsistently. Hispanic/Latino is sometimes coded as a separate category and sometimes folded into White depending on the source and the year. I've seen datasets where the same person would appear in two different racial categories across two years simply because of how the form was filled out. If your analysis spans multiple years or multiple data sources, you need a consistent recoding scheme and you need to document it. For raw data downloads, the FBI maintains the public UCR archive atucr.fbi.gov and the Bureau of Justice Statistics hosts NCVS at bjs.gov. Both require registration but are free. The Census microdata is available through IPUMS, which handles geographic harmonization across decades and saves you weeks of cleaning work. I recommend using IPUMS rather than pulling raw Census files directly unless you enjoy matching FIPS codes by hand.
Get the Full Details
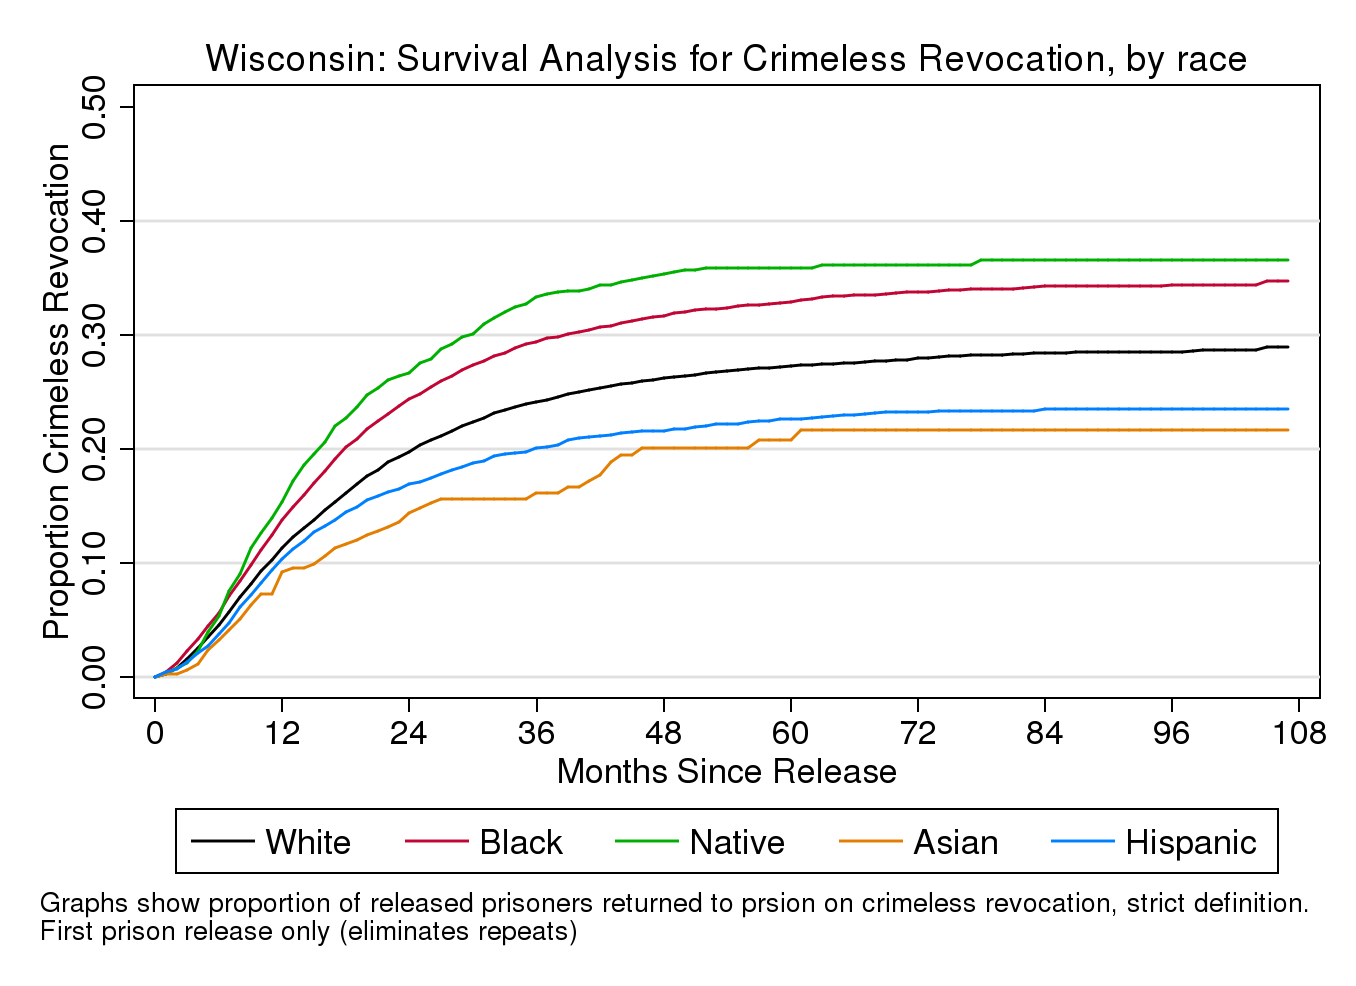
The most useful thing these datasets can actually tell you is how geography, economics, and policing strategy interact. They cannot reliably tell you anything about inherent behavioral differences between racial groups because those questions are unanswerable with this kind of data. Any analysis that implies otherwise is either dishonest or incompetent. The numbers don't support it, the methodology doesn't support it, and anyone who has actually sat with this data for more than a few months knows it doesn't support it. The patterns that show up are patterns of place and policy, not patterns of race.