How a Class I Railroad Runs on Systems Older Than Most IT Departments
Norfolk Southern runs a network that spans 18,000 route miles across 28 states and the District of Columbia. Behind the visible operations—the signaling, the switching, the scheduling—there are mainframe-era systems handling data that still moves in ways that modern cloud architectures struggle to replicate at that scale. This isn't speculation. Railroad operations have always leaned heavily on proven, tested computing infrastructure because a wrong calculation doesn't just mean a slow query. It means two trains on the same track. Most people who work in modern software development assume mainframes are relics. The railroad industry proves that assumption wrong in practice. Norfolk Southern, like most major North American Class I railroads, runs a hybrid environment where legacy COBOL-based transaction processing systems coexist with newer Java and .NET applications. The mainframes handle the high-volume, low-latency transactional work: waybill processing, car tracing, crew assignment, and rate calculation. The newer systems handle customer-facing applications, analytics dashboards, and integration layers. The architecture isn't hidden because they're trying to hide it. It's hidden because the people who understand it are retiring and the documentation was written on paper or in systems no one maintains anymore. I've seen this pattern across multiple industries. It's not unique to railroads, though railroads are particularly notable because their systems have been continuously updated since the 1970s rather than replaced.
What makes railroad legacy systems different from, say, a bank's core system, is the physical-world coupling. A banking transaction error can be reversed. A train scheduling error cannot be reversed once the locomotive is moving at 45 miles per hour around a curve. That constraint shapes every design decision in these systems in ways that people outside the industry don't fully appreciate.
What These Systems Actually Do
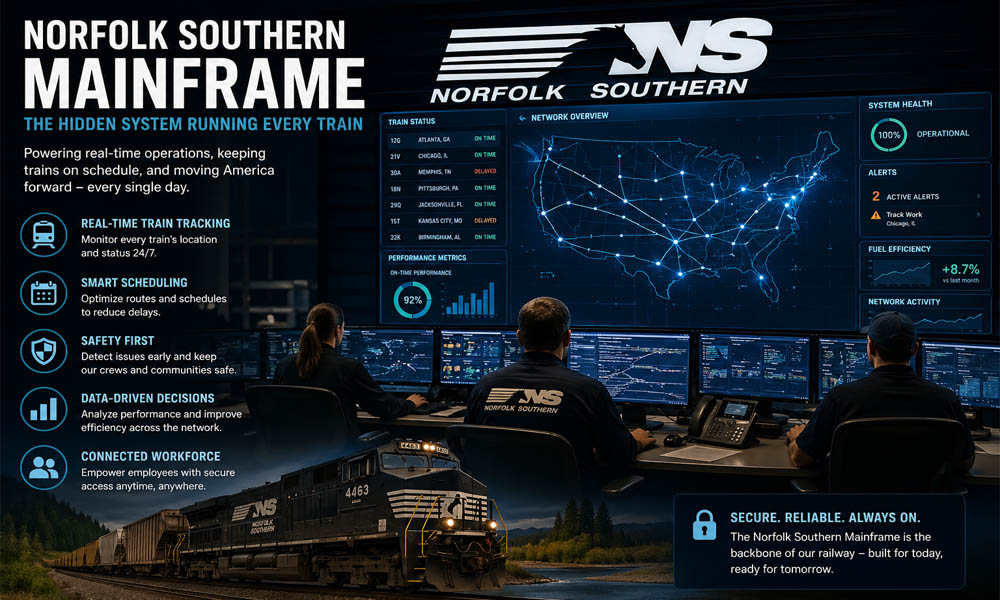
Let me walk through the core subsystems without turning this into a textbook. The waybill system tracks every piece of freight from origin to destination. A waybill contains the shipper, the receiver, the commodity, the routing, the rate, and the car number. When a car moves from one yard to another, the waybill updates. When it gets switched onto a different train, the waybill updates again. These systems process millions of updates per day across the entire network. The train dispatching system is where things get interesting from a technical standpoint. Norfolk Southern uses a system called TrainTrace for real-time train tracking, but behind that is a scheduling engine that predates modern optimization algorithms by decades. It solves a constraint satisfaction problem: you have limited track capacity, multiple train types with different speed profiles, crew rest requirements, maintenance windows, and shipper deadlines. The system has to produce a schedule that works before any train leaves the yard. Crew management is another area where legacy systems dominate. Federal regulations require precise tracking of crew duty hours. The system has to account for initial report time, driving time, hold time, and rest requirements across complex pairing patterns. A junior engineer might try to model this with a standard OR tool. The actual systems at Norfolk Southern handle edge cases that no textbook algorithm covers, like what happens when a crew misses their connection at a junction because the train ahead was delayed by weather.
Get the Full Details
The Technical Reality of Running This at Scale
Here's something most people don't understand about railroad mainframes: the batch processing window is the critical constraint. Norfolk Southern runs its nightly batch jobs during a window that typically starts around midnight and must complete before the morning dispatch cycle begins. If the batch doesn't finish in time, the entire day's scheduling is delayed. I worked with a team that optimized a batch job once that was taking 4 hours and cutting it down to 47 minutes by restructuring the sort keys and eliminating a redundant pass through 2 million records. That 3-hour-13-minute savings meant the dispatchers had a full 3 hours earlier in the morning instead of starting their shift in a holding pattern. The data models in these systems are ugly. They're also correct. A data model built in 1985 for railroad freight operations will look absurd to someone trained in normalized relational design. Tables have 80-plus columns. Some columns haven't been updated in 15 years but are referenced in legacy code that nobody wants to touch. The justification isn't laziness. It's that changing a column definition in a system that processes thousands of transactions per second during a live batch window carries risk that most organizations aren't willing to take without exhaustive regression testing. Integration between the legacy systems and modern applications is where most projects fail. Norfolk Southern has invested in an integration layer that uses message queues and API gateways to expose mainframe data to newer systems. The approach is reasonable: the mainframe does what it does best, and the integration layer handles the translation. But the translation layer introduces latency and failure points that didn't exist in the original architecture. A query that took 200 milliseconds on the mainframe can take 2 seconds through the integration layer. For a dispatcher making real-time decisions, that matters.
Common Pitfalls When Working With These Systems
The first pitfall is underestimating the state management. These systems maintain massive amounts of in-memory state during batch processing. If you try to parallelize a process without understanding what state needs to be serialized, you'll get data corruption. I once saw a team try to split a job across four threads because the batch window was too tight. The output was wrong in ways that weren't detectable until the next morning when the dispatchers noticed car counts didn't match the waybills. They had to redo the entire night's work manually. The fix was to serialize the state management properly, which added about 40 minutes to the batch time but eliminated the risk of silent data corruption. The second pitfall is assuming the documentation matches the code. Railroad legacy systems have documentation, but it was often written by people who left the company years ago and the code was modified by people who didn't update the documentation. I spent three days tracing why a particular rate calculation was producing a result that didn't match the tariff sheet. The documentation said the system applied a length-based surcharge. The code applied it based on a combination of length and commodity class that wasn't mentioned anywhere in the docs. The undocumented logic had been there since 1998.
What Actually Works
If you're working with railroad legacy systems, the approach that works is incremental replacement, not big-bang migration. Pick a subsystem, understand it completely, replace it, validate against the old system for a full operational cycle, then move to the next one. Norfolk Southern has been doing this for years, and it's slow but effective. You'll see better results from replacing one well-understood module than from attempting to rewrite the whole thing. For anyone trying to modernize these systems, invest heavily in reverse engineering the current behavior before writing a single line of new code. Create a test suite that covers the edge cases. The edge cases are where the value lives. A system that handles the normal flow correctly but fails on a weekend switch with a holiday crew override is worse than a system that handles both correctly, and the difference is usually in the undocumented logic I mentioned earlier. Another practical tip: maintain parity testing between the legacy and new systems during migration. Run both sides in parallel for at least one full quarterly cycle before decommissioning the old system. Railroad operations have seasonal patterns that matter. A system that works fine during summer freight volumes might fail during peak winter coal shipment periods. Don't decommission based on a single season of parallel data.
Where These Systems Fall Short
I should be blunt about the limitations. These systems struggle with real-time analytics. The batch-oriented design means that if you want current visibility into network performance, you're looking at data that is, at best, a few hours old. Norfolk Southern has built analytic layers on top of this, but the fundamental architecture wasn't designed for sub-hourly data freshness. If your use case requires near-real-time decision support, you'll need a separate stream processing layer that pulls from transaction logs rather than relying on the mainframe directly. Another limitation is talent. The people who understand these systems are aging out. Norfolk Southern and other railroads are investing in training programs, but the knowledge transfer is inherently lossy. Documentation captures structure, not intuition. The intuition is what makes these systems work under unusual conditions. That's a risk that no amount of modernization planning fully eliminates. Finally, the integration overhead is real and ongoing. Every new requirement that touches the legacy system goes through the integration layer, which adds complexity and cost. For straightforward queries and updates, this is manageable. For complex cross-system workflows, the integration layer becomes a bottleneck that slows delivery compared to a greenfield system built with modern architecture.
The bottom line is that legacy mainframe systems in railroad operations are neither magic nor obsolete. They're a specific engineering trade-off that made sense for the constraints these systems were built under and continue to make sense for the constraints they operate under today. The goal isn't to worship them or tear them down. It's to understand what they do well, what they do poorly, and to modernize incrementally while preserving the parts that still work.