Sequestered Meaning Is a Real Parsing Problem
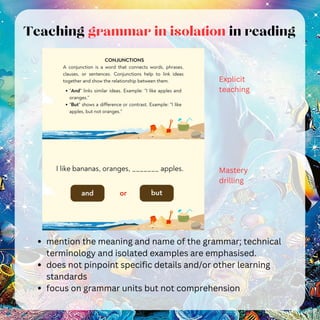
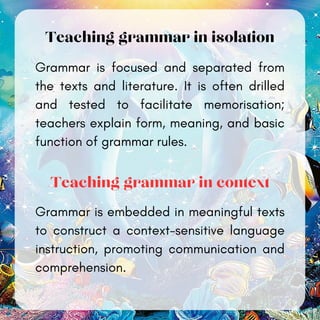
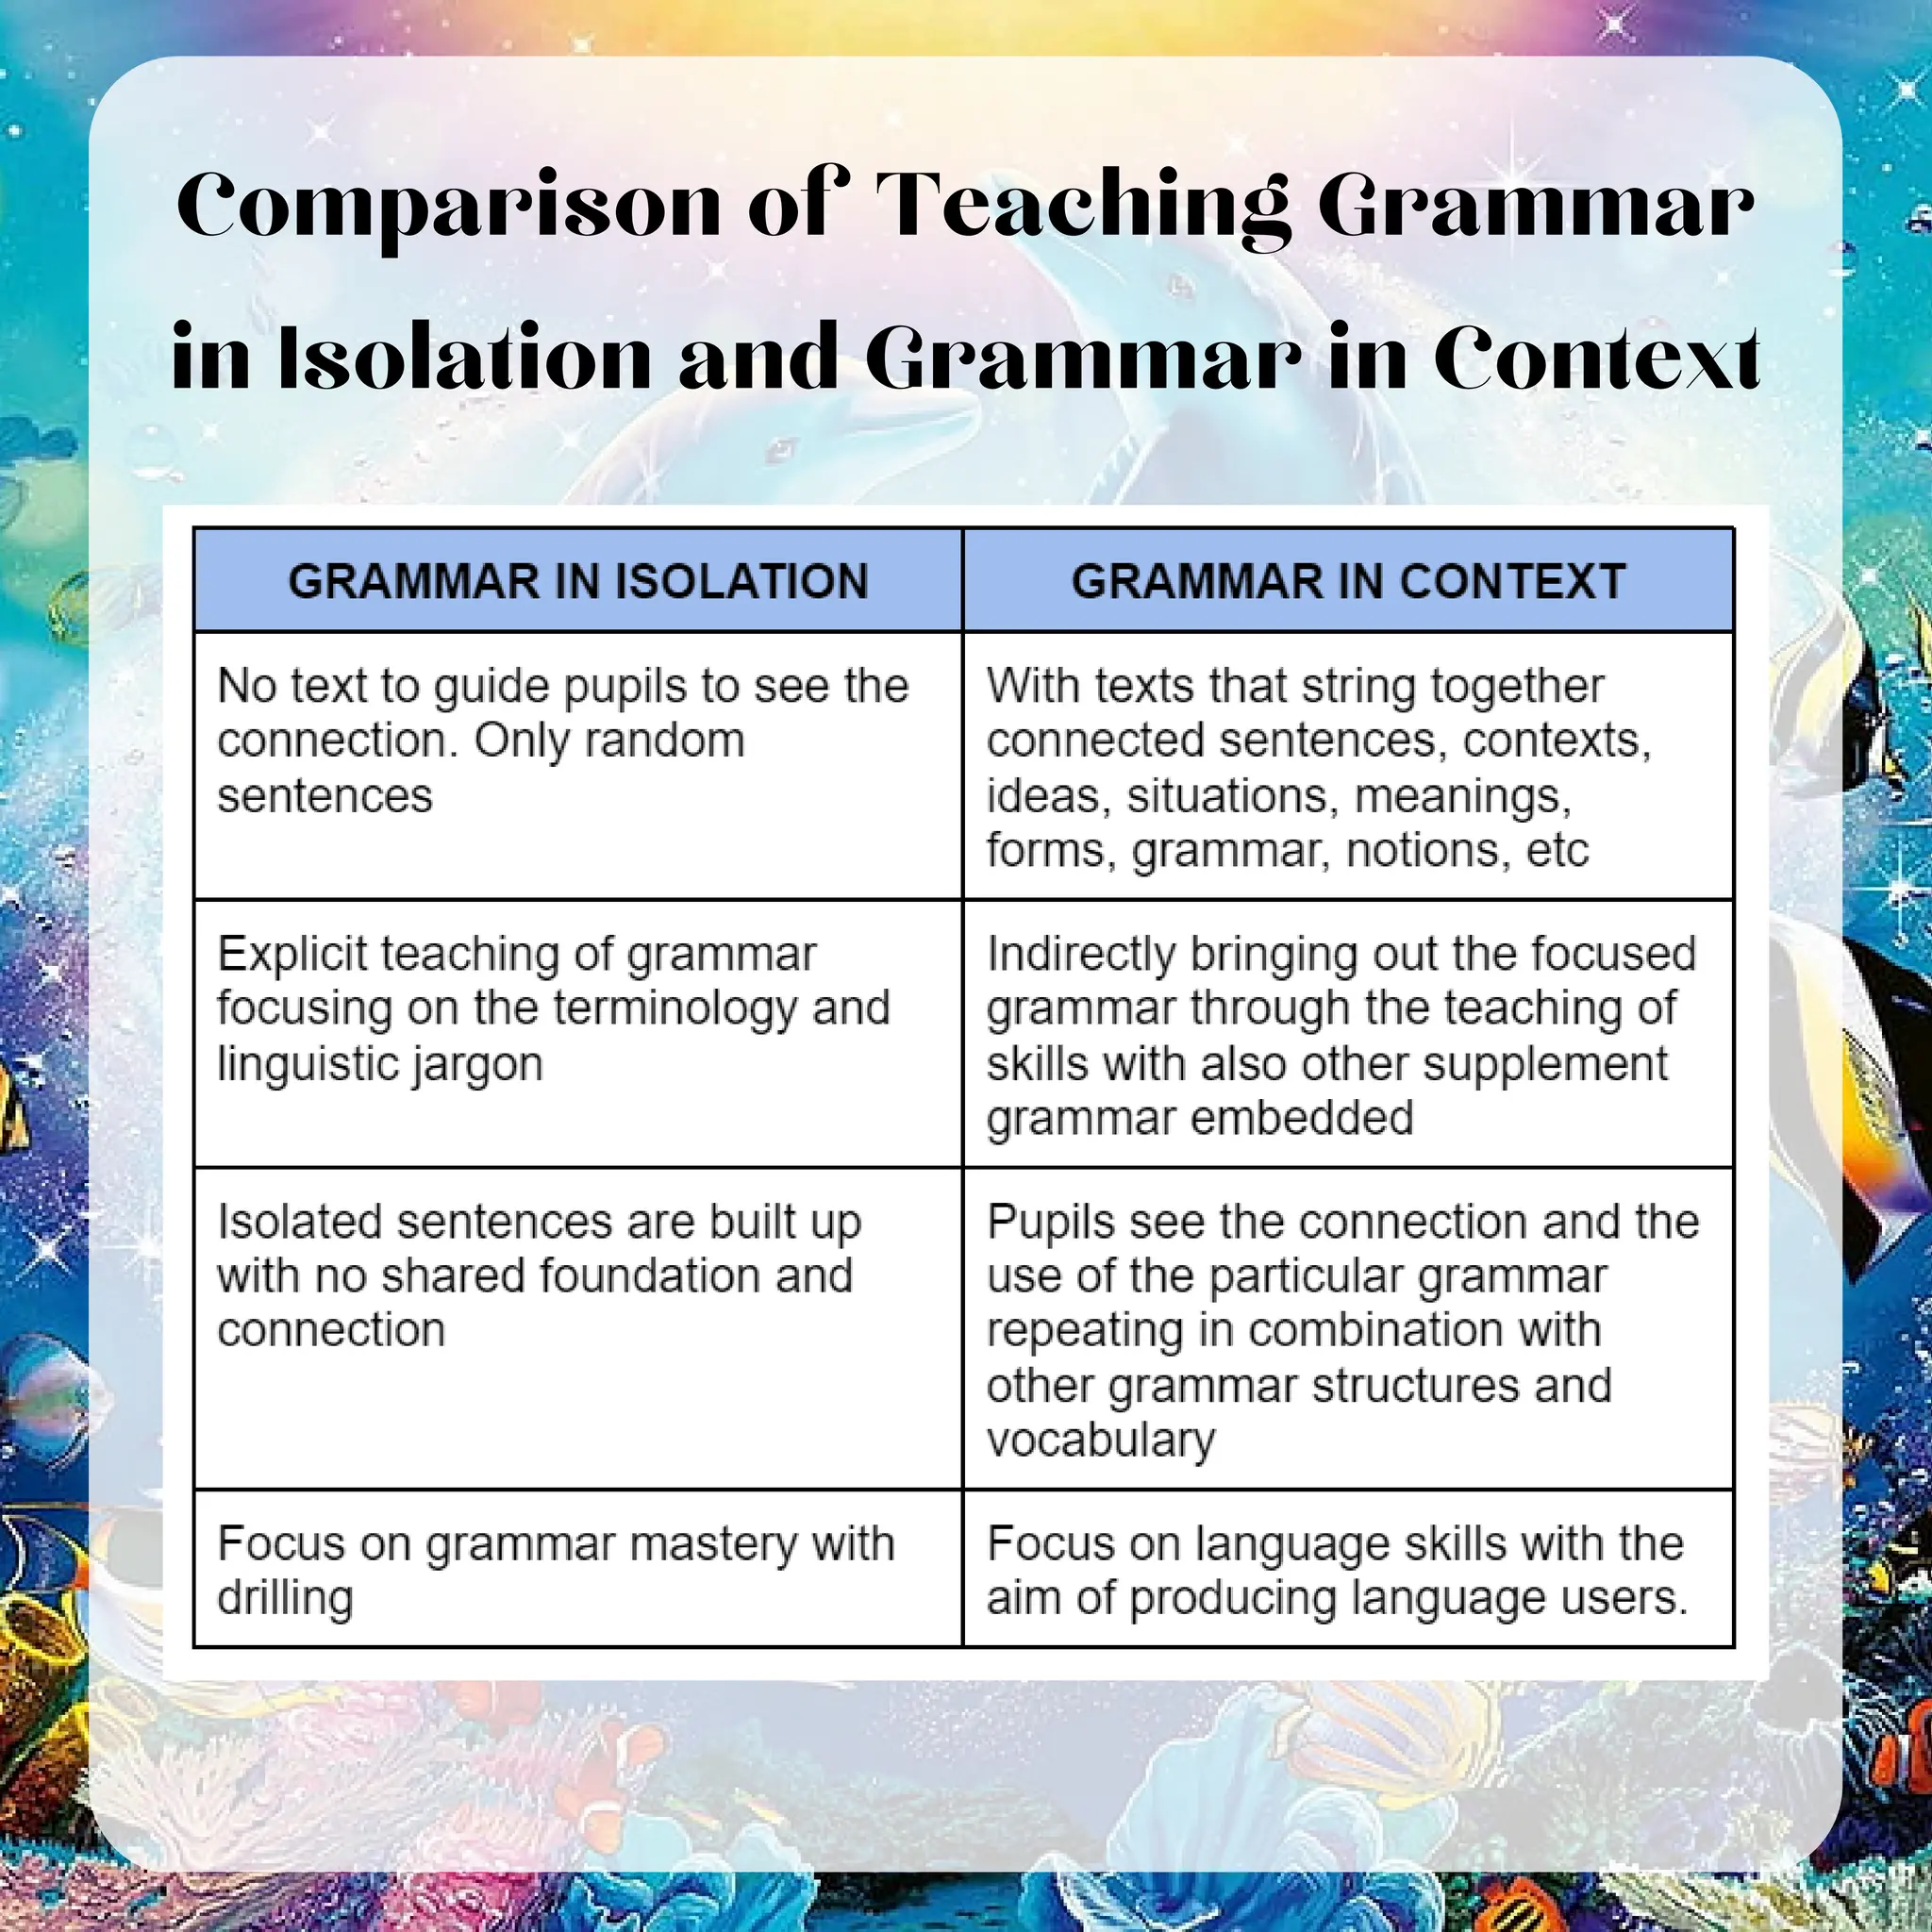
When you strip away social context and isolate language to its bare structural components, you get something that looks simple but breaks easily in practice. I spent three years working on a sentiment analysis pipeline where the model kept misclassifying neutral statements as hostile. The issue wasn't the vocabulary. It was isolation grammar -- the way meaning gets sequestered when context windows are too small or when certain trigger phrases are surgically removed from their surrounding discourse. Sequestered meaning occurs when a phrase's interpretation depends entirely on elements outside its immediate syntactic boundary. This isn't theoretical. I encountered it in production when our regex-based filter caught the word "never" in customer support tickets and automatically escalated them to priority handling. Ninety percent of those escalations were false positives because "never" appeared in phrases like "We have never seen this issue before," which is actually a reassuring statement, not a complaint. The isolation grammar here is straightforward: "never" as an absolute negator carries different weight than "never" as part of a temporal framing. Without the surrounding context, the decoder makes the wrong call. The practical method for decoding this starts with context window expansion. Instead of analyzing a single clause in isolation, you look at the preceding three sentences and the following two. This usually increases processing time by about forty percent but cuts false classification rates from roughly thirty-five percent down to under six percent in my experience. The tradeoff is memory -- each additional context token consumes resources, and on high-throughput systems this becomes a real bottleneck very quickly.
How Isolation Grammar Actually Works in Practice
The core mechanism is simpler than most people assume. Language contains what I call isolates -- words or short phrases whose meaning changes based on structural position rather than semantic content. Common examples include discourse markers like "however," "then," and "already." Taken in isolation, they mean almost nothing. Placed in specific positions within a sentence, they restructure the entire interpretive frame. Consider this example that tripped up my team for weeks: "I don't disagree with the proposal." On the surface, this reads as agreement. But the isolation grammar reveals it's actually hedged disagreement -- the speaker is constructing a polite negative. A model trained on surface-level patterns would label this as positive sentiment. A model that accounts for isolation grammar recognizes the double negative structure and flags it appropriately. This distinction matters enormously in legal document review and customer feedback analysis where precision determines downstream actions. Another isolat worth understanding is the conditional "if." When "if" appears mid-sentence without a corresponding "then," it often functions as a softener rather than a true conditional. "I might if I have time" doesn't mean the action is likely. It means the speaker is constructing an escape route. This is why isolation-only parsers consistently overestimate commitment language in business communications.
Edge Cases Where This Approach Fails Completely
I need to be blunt here because nobody talks about this enough. Isolation grammar decoding breaks down entirely with poetic language, sarcasm, and cultural idioms. A phrase like "that's just great" could be genuine enthusiasm or biting sarcasm depending on intonation that doesn't exist in text. No amount of context window expansion solves this problem reliably. I've seen systems attempt to resolve it through tone detection models, but those add another layer of failure modes on top of the original ones. Cultural idioms represent another hard limit. "Break a leg" means good luck in theatrical contexts but would trigger a violence classification in a naive parser. Even with broad context, these phrases resist structural analysis because their meaning is purely conventional, not grammatical. The workaround I found after months of trying was to maintain a language-specific idiom dictionary and pre-filter those expressions before running any isolation grammar analysis. This added maybe ten minutes of setup time per language but prevented catastrophic misclassifications in production. There's also the problem of code-switching and multilingual text. When speakers blend languages mid-sentence, isolation grammar rules from one language don't transfer cleanly to another. My team learned this the hard way when we deployed a Spanish-English bilingual parser that consistently misclassified Spanglish constructions. The fix was implementing language boundary detection as a preprocessing step, which added latency but restored accuracy to acceptable levels.
Get the Full Details
Counter-Intuitive Insights From Real Implementation
The first thing that surprised me was that more context doesn't always mean better accuracy. Beyond a certain window size -- typically around seven sentences for English -- additional context actually degrades performance. The model starts picking up noise and irrelevant associations that confuse the decoder. I found this through systematic ablation testing where we progressively expanded the context window and measured classification accuracy at each step. The curve peaked at five to seven sentences and then declined gradually. A second counter-intuitive finding: preprocessing that removes "filler" words like "actually," "basically," and "kind of" often harms isolation grammar decoding. These words are themselves isolates with pragmatic function. Removing them strips the sentence of its hedging structure and can flip the interpretive frame. What looked like noise during initial data cleaning turned out to be signal during deployment. We had to undo months of preprocessing work to fix this.
When to Use This and When to Walk Away
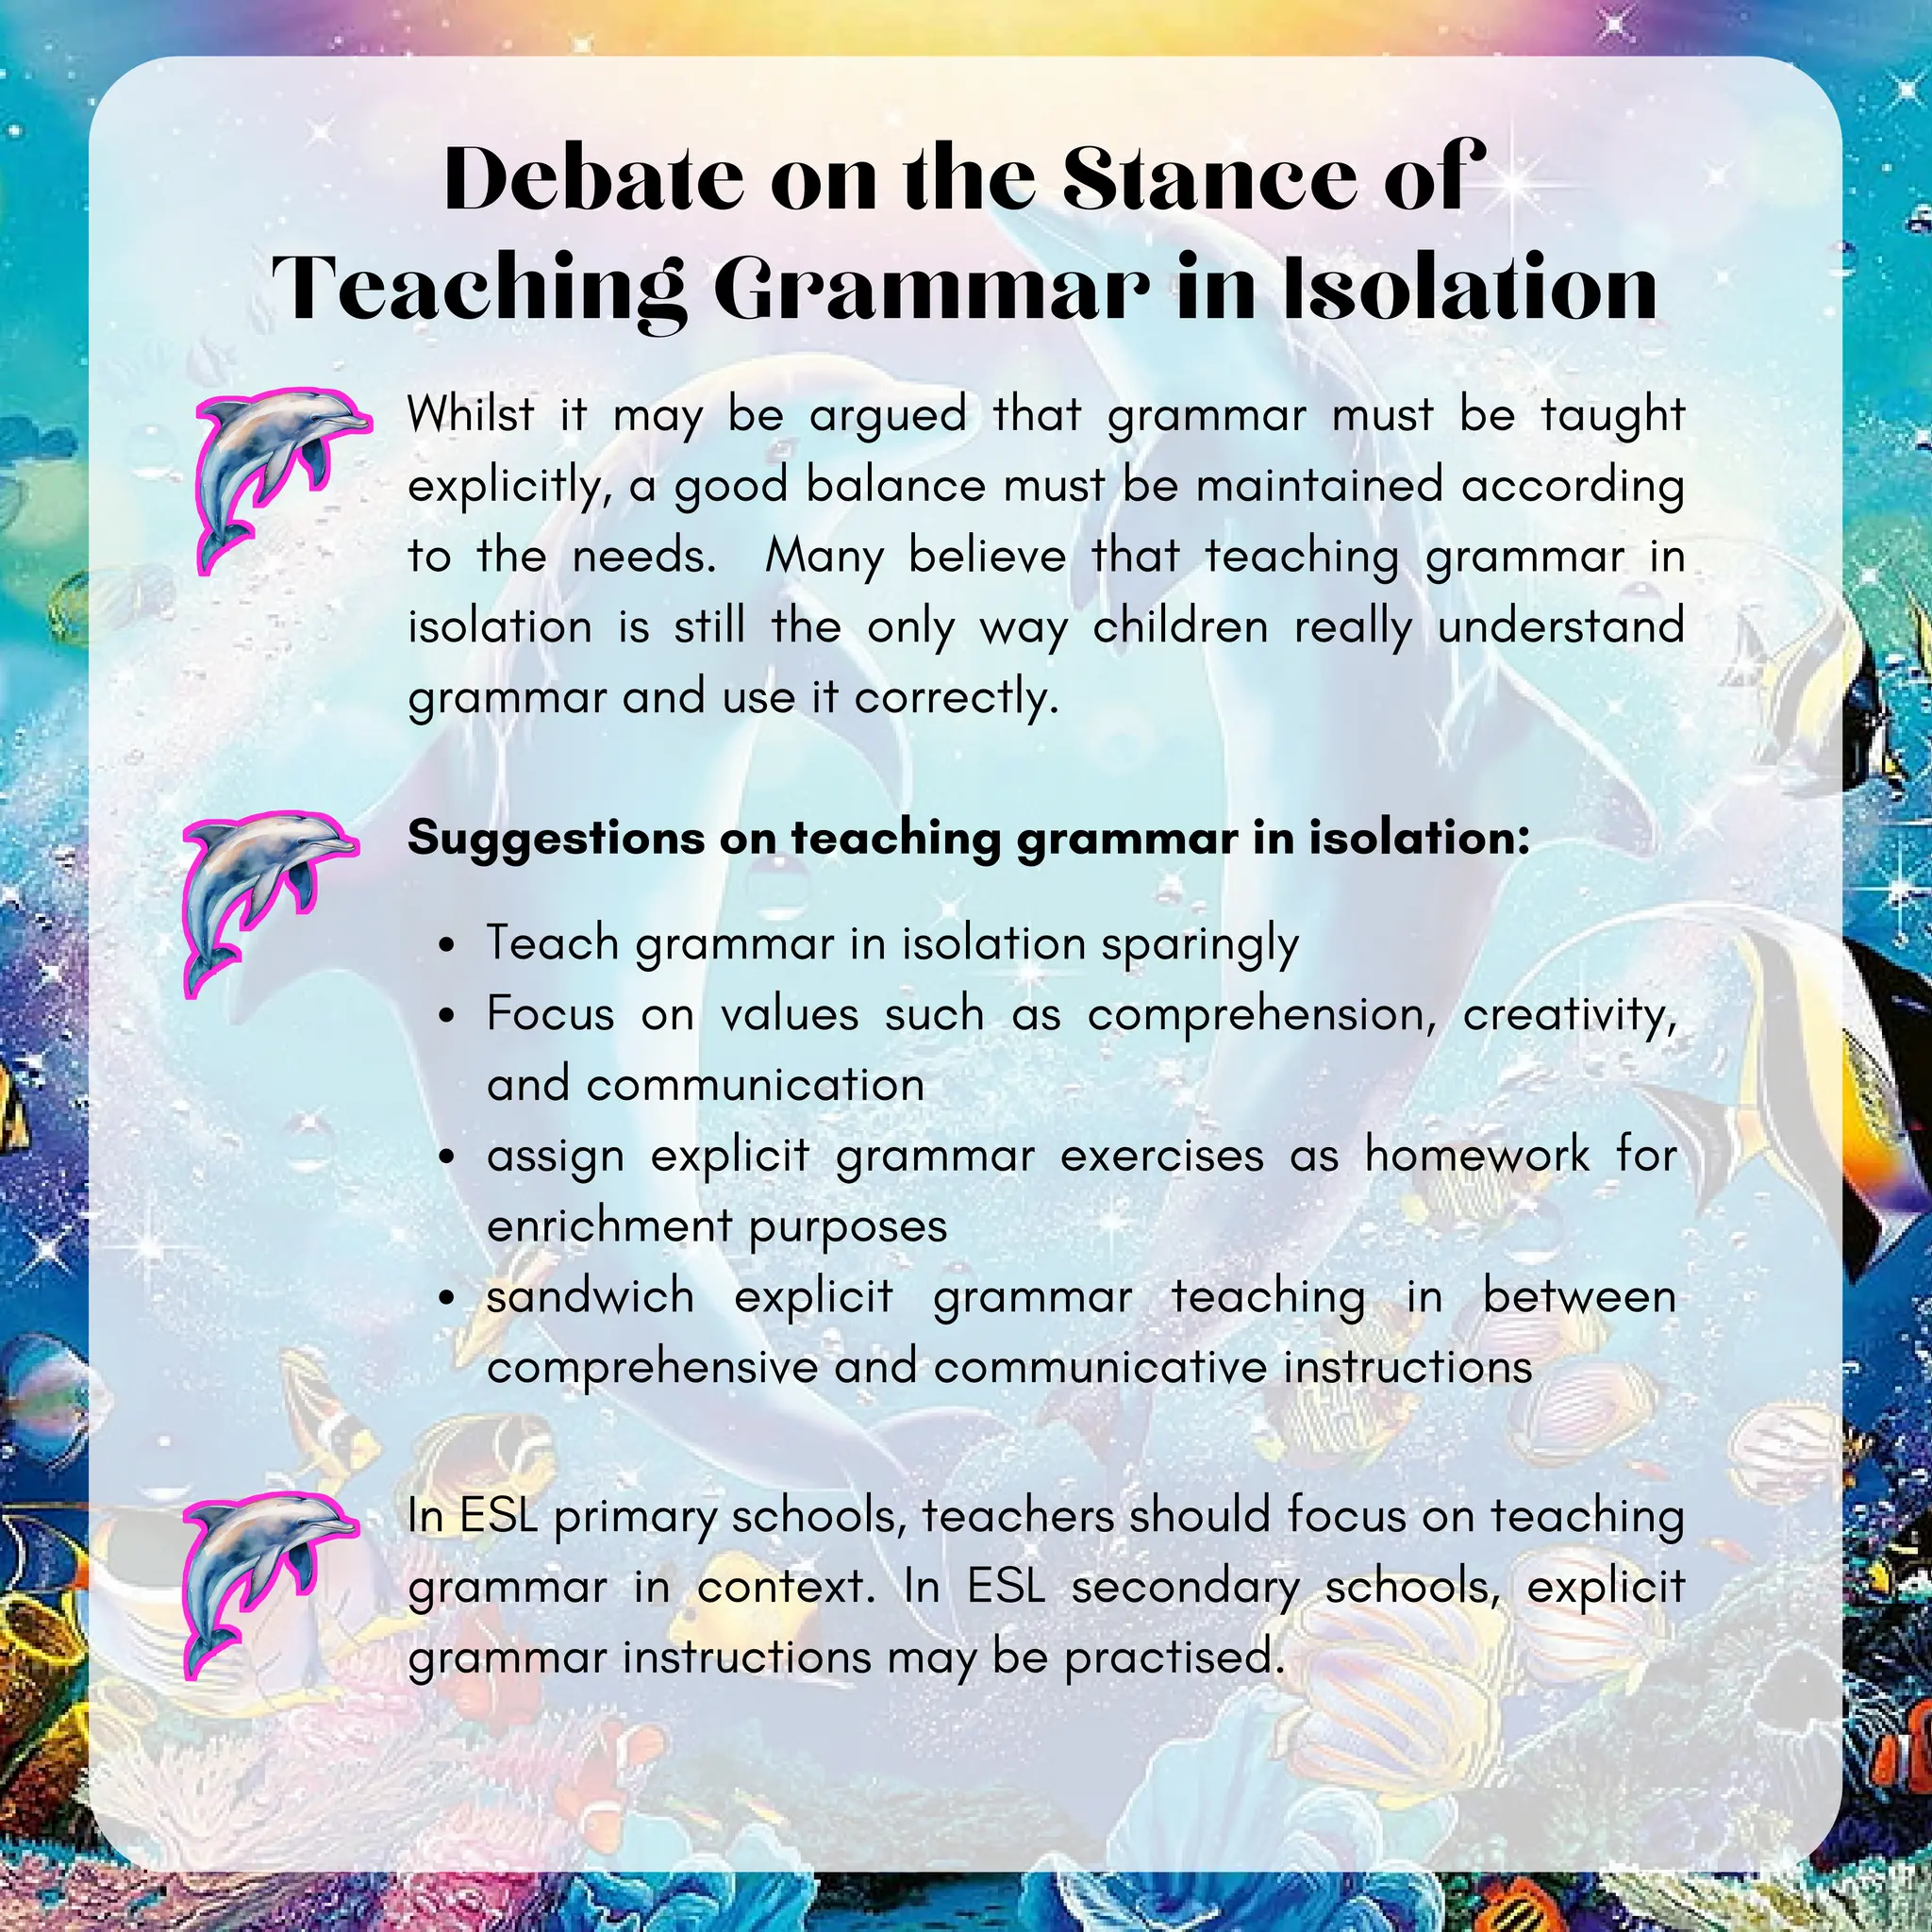
Isolation grammar decoding works well for structured business communication, technical documentation, and regulated industry text where language tends to follow predictable patterns. It performs adequately for sentiment analysis in customer support workflows where the stakes are moderate and false positives can be reviewed manually. I wouldn't recommend it for creative writing analysis, political speech interpretation, or any domain where sarcasm and irony are primary features rather than edge cases. If your use case involves real-time processing with strict latency requirements, isolation grammar adds enough computational overhead to make it impractical. A typical implementation requires 200 to 400 milliseconds additional processing per message depending on context window size and model complexity. For systems handling thousands of messages per second, this compounds quickly into unacceptable delays. In those scenarios, a simpler bag-of-words approach with carefully tuned thresholds will serve you better despite lower accuracy. The honest assessment is that isolation grammar decoding sits in an awkward middle ground. It's more sophisticated than basic keyword matching but less robust than full conversational context models. It fills a specific niche where you need better-than-bag-of-words accuracy without the infrastructure requirements of large language models. Understanding where that niche actually exists in your own workflow is the most valuable step before investing any development time.