Understanding Molecular Geometry From The Bench Up
Most people learn molecular geometry from textbooks where everything is perfectly symmetrical. The real world doesn't work that way. When you're actually working with molecules in a lab setting, you quickly realize that geometry isn't just about VSEPR shapes drawn on a whiteboard. It's about how atoms actually arrange themselves in three-dimensional space and what that means for everything the molecule can do. I spent years modeling protein-ligand interactions before I ever understood why my docking scores kept failing. The issue wasn't my software or my force field parameters. It was that I was treating geometry as a static property rather than a dynamic one. Molecules breathe. They flex. They adopt multiple conformations simultaneously, and the one your model picks matters enormously for function.
The Hidden Geometry Of Molecules How Chemistry Shapes Structure And Function
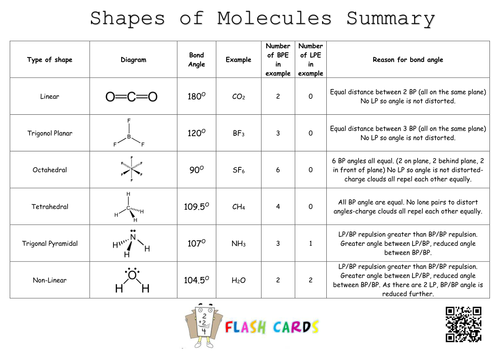
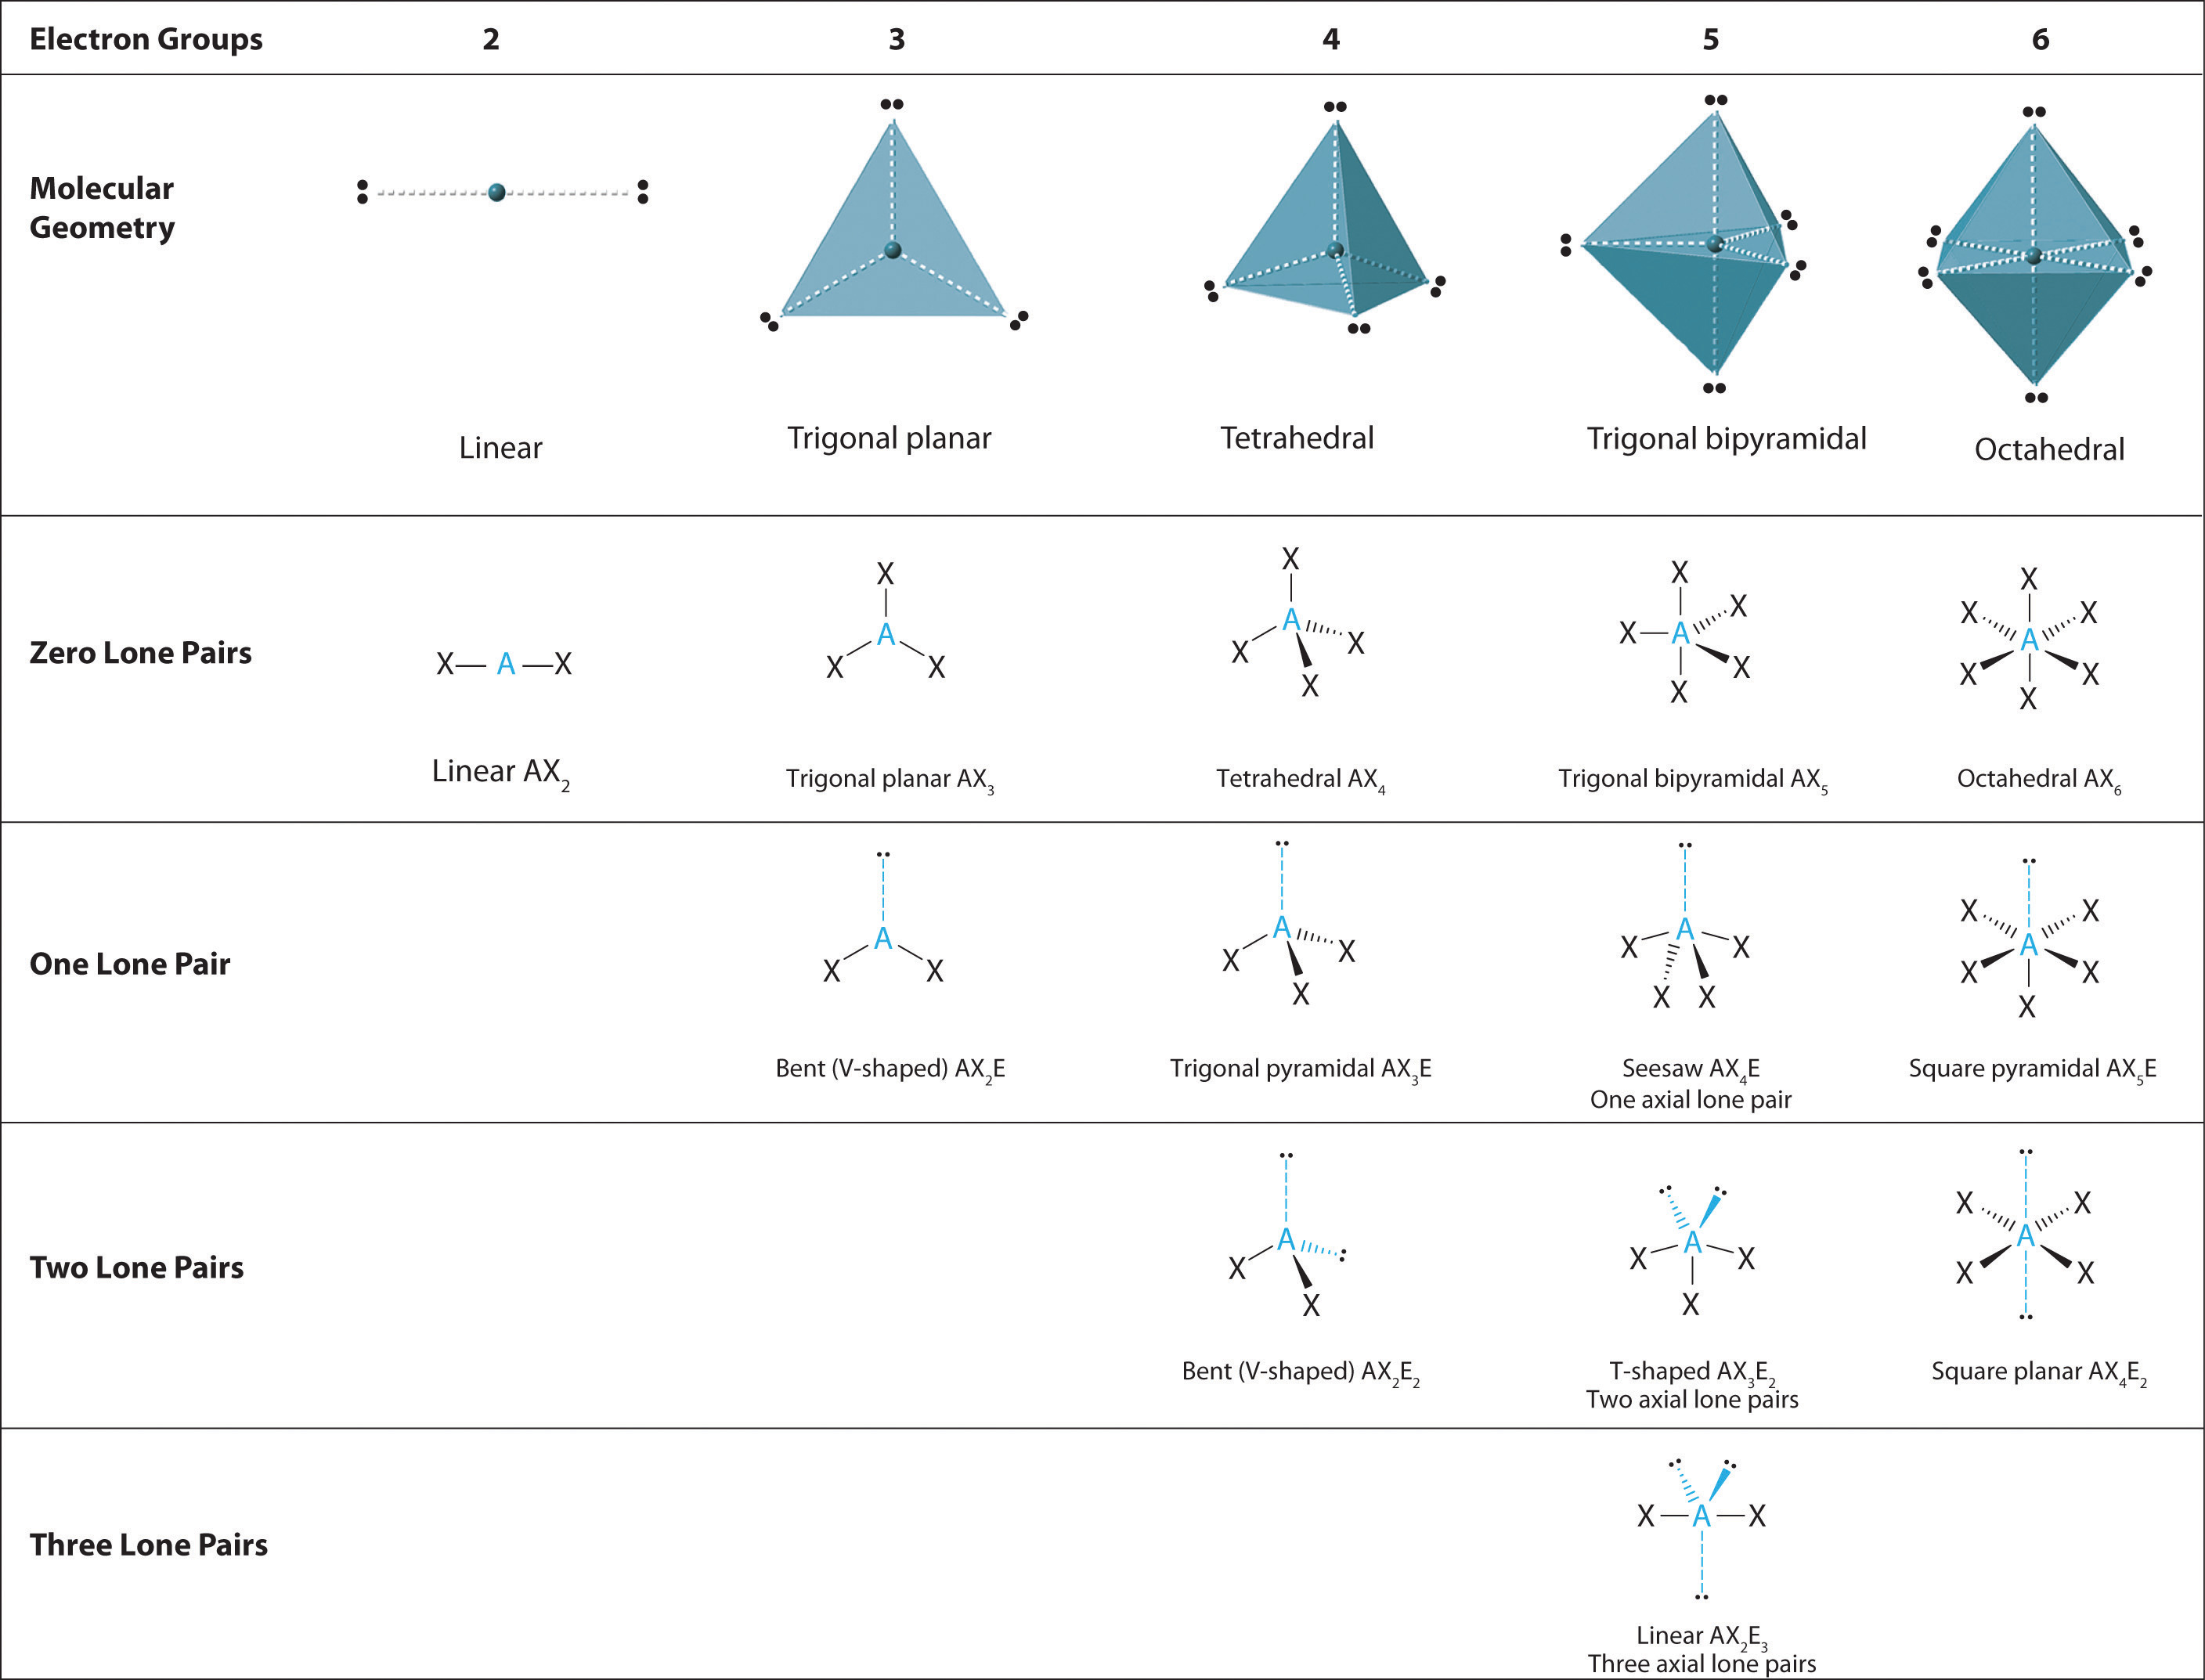
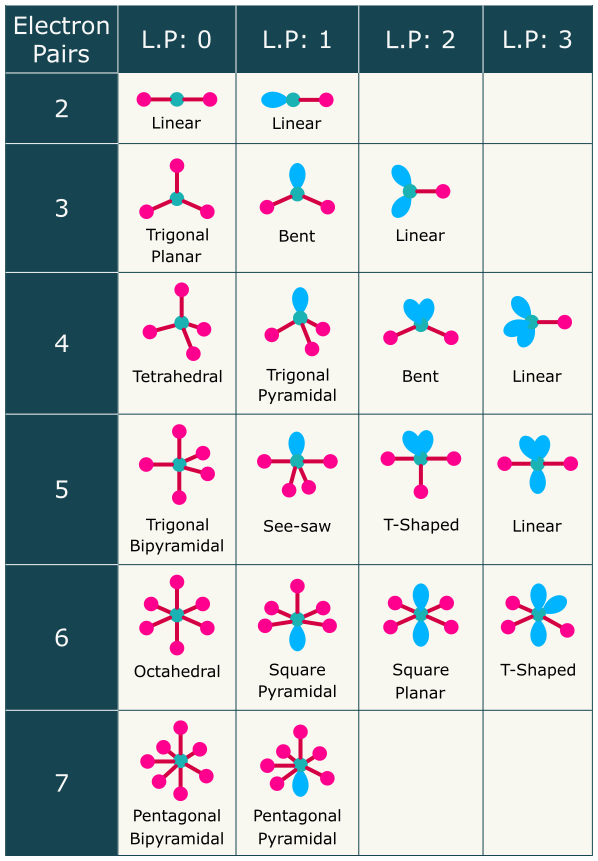
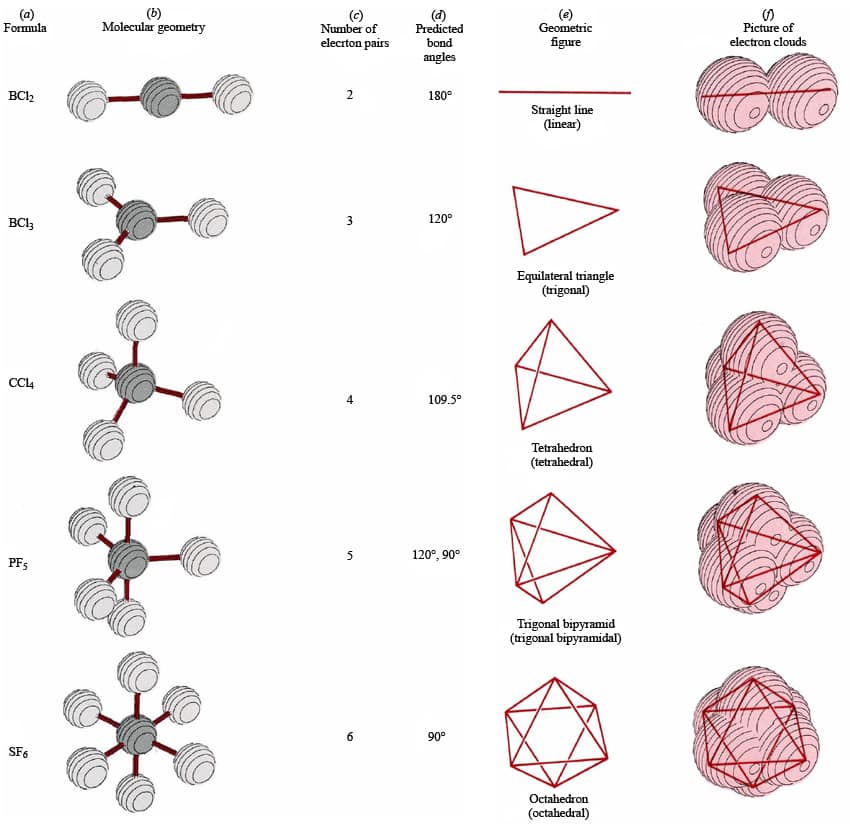
The phrase "the hidden geometry of molecules how chemistry shapes structure and function" sounds like a TED Talk title, but it describes something very concrete and practical. Geometry in chemistry isn't hidden in the sense of being mysterious. It's hidden because it's three-dimensional, and our brains are not great at visualizing 3D from 2D representations. A line drawing of benzene tells you nothing about the planar hexagonal ring, the 120-degree bond angles, or the delocalized pi system above and below the plane. You have to actually build the molecule, mentally or digitally, to see it. VSEPR theory is the entry point. Valence Shell Electron Pair Repulsion. Count your electron domains, predict the shape, move on. For water, that's four domains—two bonding, two lone pairs—giving you a bent geometry with an angle close to 109.5 degrees. For methane, four bonding domains, perfect tetrahedron at 109.5 degrees. It works. Until it doesn't. Here's where the theory gets thin: VSEPR treats electron pairs as point charges repelling each other in empty space. That's a useful approximation for introductory chemistry, but it fails for anything with d-orbital participation, significant steric strain, or delocalized bonding. Transition metal complexes are where VSEPR goes to die. A square planar platinum complex doesn't follow the same rules as a tetrahedral carbon complex, even though both have four substituents. The geometry is dictated by crystal field stabilization energy and d-orbital filling, not by simple electron pair repulsion.
The deeper insight is that geometry isn't just a consequence of bonding. It's a driver of reactivity and function. Take the classic example of cisplatin versus transplatin. Same atoms. Same bonds. Completely different geometry—chloride ligands adjacent to each other in the cis isomer, opposite in the trans isomer. Cisplatin is a potent chemotherapy drug. Transplatin is pharmacologically inert. The cis geometry allows the chlorides to be displaced sequentially by water and then by guanine N7 atoms on DNA, forming a crosslink that bends the helix and triggers apoptosis. The trans isomer can't form that crosslink because the binding sites are too far apart. Geometry is everything here. Another thing that trips people up: hybridization is not a physical observable. It's a mathematical construct we use to explain bonding patterns. Carbon in methane is sp3 hybridized. That's a useful description. But in cyclopropane, the carbon-carbon bonds are bent because the ring forces 60-degree angles. The orbitals aren't perfect sp3 hybrids anymore. They have more p-character in the ring bonds and more s-character in the C-H bonds. This is called Bent's rule, and it's one of those things that explains a lot if you know it and confuses you if you don't.
Get the Full Details
Why Geometry Determines Function
The connection between molecular geometry and function operates at multiple levels, and most people only think about the first one. At the simplest level, geometry determines whether molecules can physically interact with each other. Enzyme active sites are shaped like locks, and substrates are the keys. This is the classic Pauling model, and it's essentially correct for many systems. But it's incomplete because it treats both the lock and the key as rigid objects. In reality, both are flexible, and the binding event involves mutual adaptation. This is the induced fit model, proposed by Koshland in 1958, and it's still the dominant framework in biochemistry. At a deeper level, geometry determines electronic properties. The overlap between atomic orbitals depends on their relative orientation. In conjugated systems like retinal, the alternating single and double bonds create a pi system where the p-orbitals must be parallel for effective overlap. Rotate one bond by 90 degrees, and you break the conjugation. That's exactly what happens when light hits retinal in your eye—the 11-cis to all-trans isomerization changes the geometry of the chromophore, disrupting the conjugated system's interaction with the surrounding protein, and triggering a signal cascade that your brain interprets as vision. One bond rotation. One geometric change. Your entire visual experience depends on it.
At the most subtle level, geometry affects thermodynamics through steric strain and torsional strain. The chair conformation of cyclohexane is more stable than the boat by about 25 kJ/mol. That's not a small number. It's the difference between a molecule that exists peacefully in solution and one that's constantly flipping between conformations. Axial and equatorial substituents experience different steric environments, and this is why 1,3-diaxial interactions matter in synthesis. If you're doing an E2 elimination on a cyclohexane derivative, the leaving group and the beta-hydrogen must be anti-periplantar—meaning they need to be on opposite sides of the molecule in a specific geometric arrangement. If your substituent is axial, you're fine. If it's equatorial, the reaction either won't happen or will happen through a much higher-energy pathway.
A Practical Problem I Ran Into
Two years ago, I was modeling a series of kinase inhibitors for a project that ultimately got shelved. The target was a dual PI3K/mTOR inhibitor, and we had a lead compound that showed good potency in vitro but terrible selectivity. The selectivity issue turned out to be geometric. The hinge region of PI3K has a methionine residue where mTOR has a threonine. The threonine's hydroxyl group creates a steric constraint that our lead compound wasn't accounting for. In our initial models, we had built the ligand in a conformation that fit PI3K perfectly but would clash with the mTOR threonine. The compound was bindinging mTOR anyway because the protein could rearrange slightly to accommodate it, but the affinity was lower than we wanted. The fix wasn't to redesign the molecule from scratch. It was to run a conformational search using a force field method, identify the low-energy conformers, and then dock each one separately into both targets. This revealed that the bioactive conformation in mTOR required a different torsion angle around the central phenyl-piperazine bond than the one we had been assuming. Once we adjusted the scaffold to favor that conformation—essentially adding a subtle geometric constraint through a methyl substitution—we saw a 20-fold improvement in selectivity without losing potency. The entire workflow took about three days, including the conformational search and the redocking analysis. Before that, I was spending weeks on individual analog synthesis and testing with ambiguous results.
Common Pitfalls When Working With Molecular Geometry
The biggest mistake people make is assuming that a single static geometry represents a molecule. At room temperature, most flexible molecules exist as an ensemble of conformations. The Boltzmann distribution determines the population of each, and the relevant geometry for function is often not the global energy minimum but a higher-energy conformer that happens to be preorganized for binding. This is called conformational selection, and it's increasingly recognized as important in drug design. Another pitfall is ignoring solvent effects on geometry. Water isn't just a background medium. It forms hydrogen bonds that can stabilize certain conformations over others. A peptide that appears extended in vacuum might collapse into a compact structure in water, or vice versa. If you're doing computational geometry optimization, you need at least an implicit solvation model. Explicit solvent is better but much more expensive computationally. Stereochemistry deserves special attention because it's where geometry has the most dramatic functional consequences. Enantiomers have identical physical properties in achiral environments—same melting point, same solubility, same NMR spectra. But they interact differently with chiral biological molecules. Thalidomide is the textbook example, though the actual mechanism is more nuanced than the simple "one enantiomer is therapeutic, the other is teratogenic" story. Both enantiomers interconvert in vivo, so separating them wouldn't have helped. But the point stands: geometry matters enormously for biological function, and enantiomers are mirror-image geometries.
How To Actually Work With Molecular Geometry
If you're just getting started, you don't need expensive software or a supercomputer. Here's what actually works: Get a decent molecular visualization tool. Avogadro is free and handles basic geometry building and optimization well. For anything more serious, consider open-source options like ORCA for quantum chemistry calculations or GROMACS for molecular dynamics. If you have institutional access, Gaussian and Schrödinger's suite are industry standards. Learn to read structural data. Crystallographic databases like the Cambridge Structural Database (CSD) and the Protein Data Bank (PDB) contain millions of experimentally determined structures. Browsing the CSD for molecules similar to what you're working with can teach you more about realistic bond lengths and angles than any textbook. The average C-C single bond is 1.54 angstroms, yes, but it can vary by several hundredths depending on the chemical environment. Knowing what's normal and what's unusual takes exposure to real data.
Build things and break them. The most effective way to understand molecular geometry is to model molecules and see what happens when you change things. Rotate a bond. Change a substituent. Flip a stereocenter. Watch how the geometry responds. Computational chemistry software makes this almost too easy, which is also its danger—you can generate beautiful structures that are completely wrong because you didn't validate them against experimental data. For conformational analysis, start simple. Use a molecular mechanics force field like MMFF94 or UFF to generate conformers, then rank them by energy. If you need higher accuracy, follow up with DFT on the lowest-energy conformers. B3LYP with a 6-31G* basis set is a reasonable default for organic molecules. Don't bother with higher-level methods unless you're publishing or your system is unusually challenging.

What This Approach Cannot Do
I should be upfront about the limitations. Molecular geometry determination, whether computational or experimental, has real bottlenecks. X-ray crystallography requires crystals. Many molecules refuse to crystallize, and for membrane proteins or intrinsically disordered systems, this can be a genuine showstopper. NMR solves structures in solution but requires significant expertise to interpret, and the resulting structures are ensembles rather than single precise coordinates. Cryo-EM has revolutionized structural biology for large complexes, but it's still not routine for small molecules under 50 kDa. Computational geometry optimization has its own failures. Force fields are parameterized for specific types of molecules and can produce garbage for exotic chemistries. DFT struggles with dispersion interactions unless you add explicit correction terms like D3. Transition states are notoriously difficult to locate, and the geometry you find might be a saddle point of the wrong order. And regardless of the method, the Born-Oppenheimer approximation means you're solving for nuclear geometry on a single electronic potential energy surface, ignoring non-adiabatic effects that matter for photochemistry and some excited-state processes. If you're working with systems where geometry is uncertain and experimental validation isn't feasible, the honest answer is often "we don't know yet." That's not a failure of the approach. It's a recognition that molecular geometry, while fundamentally determined by quantum mechanics, is practically inaccessible for many systems of interest. The best practitioners know when to trust their models and when to admit the limits of their knowledge.