Supervised and Unsupervised Learning Are Fundamentally Different Problems
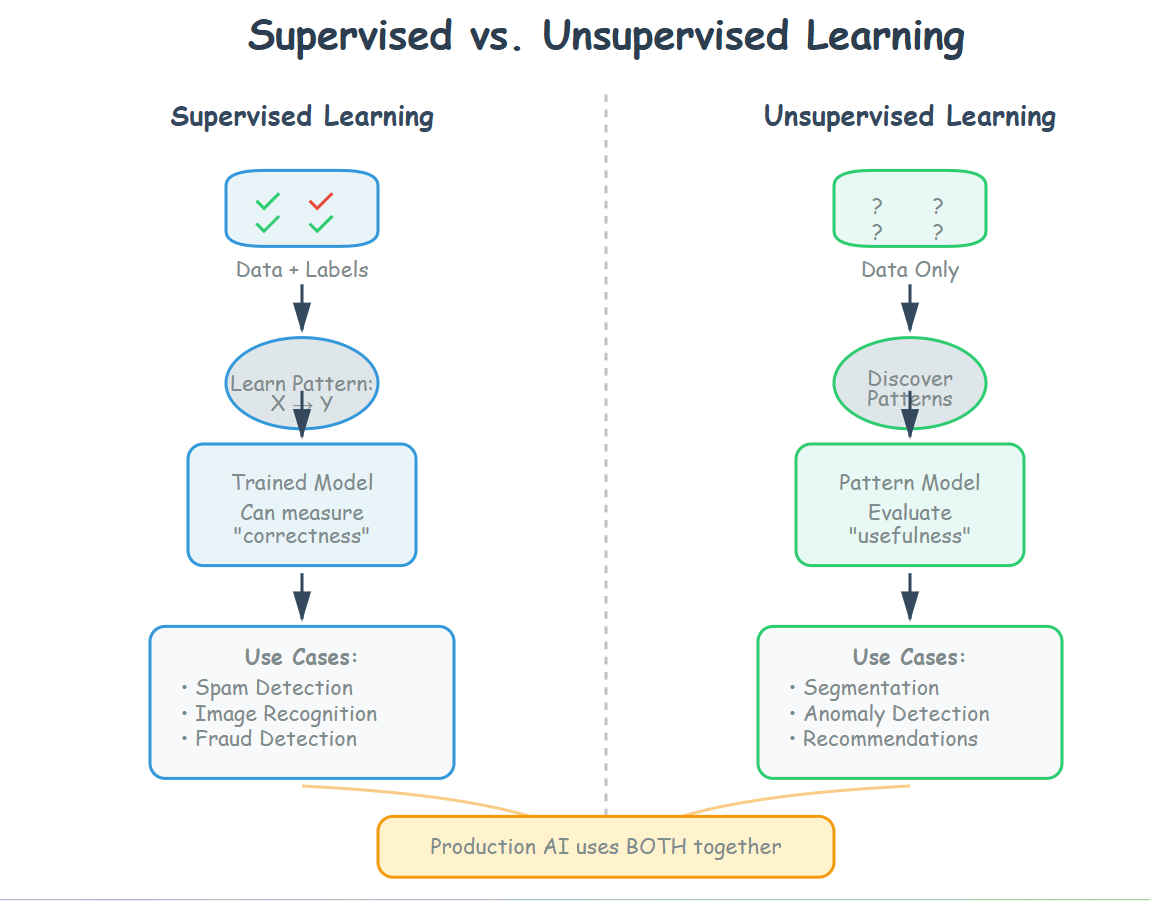
You pick between them based on whether your data has labels and what you are actually trying to predict. That is the core difference. Everything else follows from that decision. I want to be clear about the terminology here because it trips people up more than it should. When people talk about supervised versus unsupervised approaches, they are usually describing whether your training data comes with ground truth or not. Supervised learning requires labeled examples. Each input has a known correct output. You train a model to map inputs to those outputs. Unsupervised learning works with raw, unlabeled data. The model has to find structure on its own. In practice, I deal with this every day when building data pipelines for production systems. The supervised route is straightforward but expensive in terms of labeling effort. Getting quality labels for a typical image classification task runs roughly $2 to $8 per image depending on complexity and your labeling vendor. A dataset of 50,000 samples at $4 each is $200,000 before you even start training. That is not an exaggeration. I have seen projects die because the budget assumed cheap labels and hit reality after the first 5,000.
The unsupervised alternative cuts that cost to near zero but introduces a different class of problems. You get clusters or embeddings out of it. Good clusters. Meaningful ones, if your data actually has structure. Not always the case. I worked on a customer segmentation project where the unsupervised approach produced four clean clusters on the surface. When we drilled into cluster three, it turned out to be an artifact of missing data patterns, not a real customer segment. People in that cluster were not a demographic or behavioral group. They were simply the people whose tracking pixel had been disabled. The model was clustering noise. We lost three weeks chasing a ghost before we caught it. The workaround was boring and effective. Instead of jumping straight to k-means, I computed the missingness mask across every feature and ran a simple threshold analysis first. Any cluster that correlated above 0.7 with any individual missingness column got dropped. That is it. It would have taken twenty minutes instead of three weeks if I had done that upfront. I wish I had. Here is something most beginner guides skip. Supervised models can fail harder than unsupervised ones in certain edge cases, and people do not expect that. A well-tuned supervised model trained on a biased or narrow label set can achieve 94 percent accuracy on your test set and still be useless in production. The test set was not broad enough to expose the failure mode. I once deployed a fraud detection model that hit 96 percent AUC during validation. It turned out to be flagging only the most obvious fraud patterns while missing a completely different attack vector that used fresh account signatures. The model had never seen that signature type during training. Validation metrics looked fine. Production did not care about fine. We caught it after two weeks of real transactions and had to retrain with a curated set of adversarial examples that took another six weeks to collect.
On the flip side, unsupervised methods have their own failure modes that are harder to diagnose because there is no single metric telling you you are wrong. Silhouette scores go up. Inertia goes down. Everything looks good on paper. But the clusters might not map to anything actionable. I have seen teams ship unsupervised customer personas that looked great in a dashboard but were statistically indistinguishable from random when tested against holdout behavior. There is also a middle ground people should stop pretending does not exist. Semi-supervised learning sits between the two approaches and uses a small labeled set alongside a large unlabeled one. It can reduce labeling costs by 60 to 80 percent depending on the domain. The catch is that it requires the unlabeled data to share the same distribution as the labeled data. If your labeled set comes from one source and your unlabeled set comes from another, semi-supervised methods can degrade performance below what a purely supervised model would achieve. I learned this the hard way on a document classification project where the labeled documents came from internal sources and the unlabeled pool included public forums. The distribution shift killed the pseudo-labeling step and made things worse than starting supervised-only. Another practical consideration that nobody talks about enough is evaluation. Supervised learning gives you clear metrics: accuracy, precision, recall, F1, ROC AUC. You can measure progress. Unsupervised learning forces you to define evaluation criteria that may not exist naturally. You might use downstream task performance as a proxy. If the clusters you generate improve the accuracy of a downstream classifier, that is evidence they are useful. But that adds a whole extra layer of complexity to your pipeline. You are not just building a clustering model anymore. You are building a clustering model plus a classifier to validate it.
Get the Full Details
Feature scaling matters more for unsupervised methods than most people realize. Distance-based algorithms like k-means and hierarchical clustering are extremely sensitive to feature scale. A feature with a large numeric range dominates the distance calculation regardless of whether it is actually informative. I spent two days debugging why a clustering model kept putting high-value customers in the same group as low-value customers. The issue was that transaction amount features had a range of millions while engagement metrics ranged from 0 to 1. After applying log scaling to the monetary features and standard scaling across the board, the clusters became interpretable immediately. The data had not changed. The geometry had. If you are deciding which approach to use, start with your data. Count your labeled samples. Estimate labeling cost. Decide if you can afford the supervised route or if you need to explore unsupervised or semi-supervised alternatives. Then validate early and often with holdout sets that resemble your production distribution, not your training distribution. That habit alone will save you more failures than any algorithm choice.