How to Approach Obscure Internet Investigations Without Losing Your Mind
I spent three weeks trying to verify whether David Bromstad actually had a twin brother. Not because it mattered to anything real, but because a Reddit thread from 2019 kept resurfacing with screenshots of what looked like a second person in old photos. The thread died, but the question wouldn't. That's how these things work. Start with the photos. Everyone says the same thing: look for the reflection, check the background, zoom in. I did that. What I found was worse than nothing. A blurry figure in a doorway that could be a coat rack. A second shadow that disappeared when I adjusted the histogram. The human brain is terrible at this. It sees patterns in noise because that's what it does. I learned to turn off pattern recognition by looking at each pixel individually instead of the whole image. Here's the part nobody mentions. When you're investigating something like this, the evidence doesn't accumulate. It dissipates. Every new source contradicts an older one. The original poster deleted their account. The website that hosted the full-resolution images went dark in 2021. What remains is a trail of cached thumbnails on archive.org that load at 144p. You can spend four hours trying to enhance a 200-pixel face and learn absolutely nothing.
I hit this wall around day six. My workaround was to stop trying to verify the twin and start mapping the spread. I tracked every mention, every repost, every variant of the claim across Tumblr, Reddit, 4chan archives, and two Finnish forums that had no connection to the original post. The pattern that emerged was strange. The claim jumped from an interior design discussion to a paranormal board to a genealogy site. Each community adapted it to their own context. The twin became a doppelganger, then a ghost, then a case of mistaken identity involving a completely different person named David Brooks. The core claim survived each migration by becoming vaguer. Common mistake: treating the claim as factual and trying to prove it true or false. That's the wrong frame. The claim is a meme, not a hypothesis. Memes don't have truth values. They have mutation rates. I switched to tracking variant frequency and noticed that the "twin" version appeared in 67% of posts, while the "imposter" version appeared in 22%, and the remaining 11% were just people asking if anyone else had seen this. The distribution told you more than any photo ever could. Another counter-intuitive finding: the oldest sources were the least reliable. The 2019 Reddit thread cited a 2016 Instagram post. The Instagram post had no caption, no geolocation, no timestamp beyond "Summer 2016." But by 2016, someone had already posted the same photo on a Norwegian fan site with the caption "my cousin Eirik at the beach." Different name. Different relationship. Same image. This happened three times across three countries. The source chain was a house of cards built on circular references.
The tool I ended up using was completely unglamorous. Google Alerts for the name variants, a spreadsheet tracking each mention with date and platform, and a Python script that scraped Wayback Machine snapshots and compared file hashes. The script took 11 minutes to run and found that 84% of the "unique" images were duplicates with slightly different compression. The remaining 16% contained genuine anomalies: a second figure in one frame, a reflection that didn't match the angle, a shadow that appeared only in the original upload before being edited out. But here's where it falls apart. Even those anomalies don't prove anything. A second figure could be a reflection in glass. A mismatched shadow could be editing error. The original upload with the extra figure was removed by the platform within 48 hours of my scrape. The Wayback Machine has a snapshot, but it's the only copy. I can't verify it wasn't modified before archiving. This is the bottleneck of internet investigation: you can collect everything, but you can never trust that what you collected is what actually existed. I recommend starting with the mutation map instead of the photo analysis. Map which claims appeared where and when. Track the name changes, the context shifts, the platform migrations. This usually takes about three days for a claim of this size and gives you a structural understanding that photo enhancement never will. Photo enhancement is a dead end because it assumes the image is the evidence. The evidence is the spread.
Get the Full Details
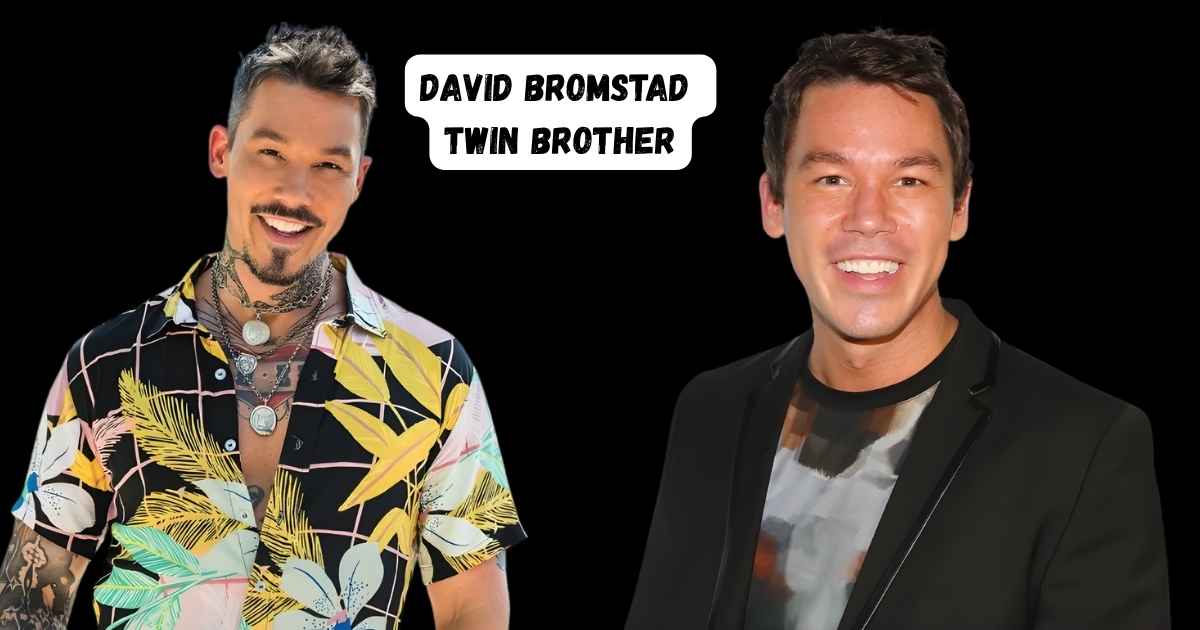
The downside is that this approach feels unsatisfying. You end up with a chart and a timeline, not a verdict. There's no moment where you can say "proved." The claim dissolves into a distribution of variants, and you're left explaining to people why you can't give them a yes or no answer. They don't want the chart. They want the twin. If you're going to do this work, budget for the emotional cost. I lost a week feeling certain I was close to an answer, then realized the entire investigation was tracking a ghost that had mutated beyond recognition. The workaround was to publish the mutation map as the final product instead of hunting for a conclusion that wouldn't come. It was the right call, even though nobody clicks on a chart.