Why Lysine's Side Chain Keeps Ruining Your Crystallization Runs
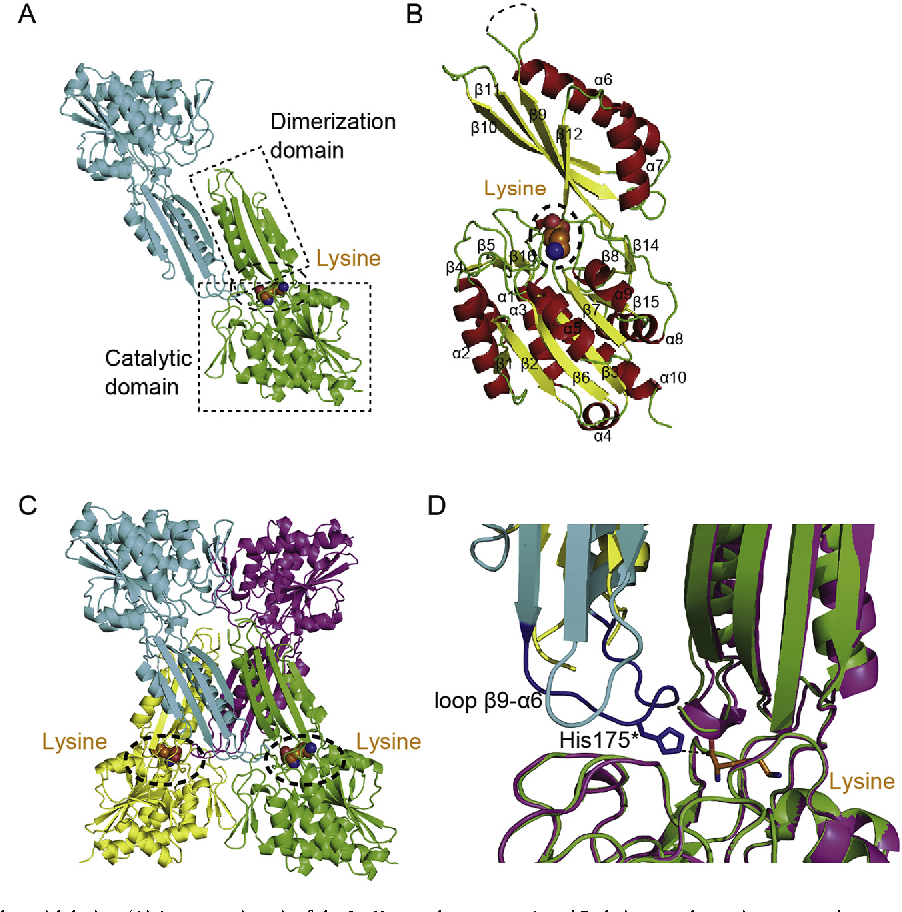
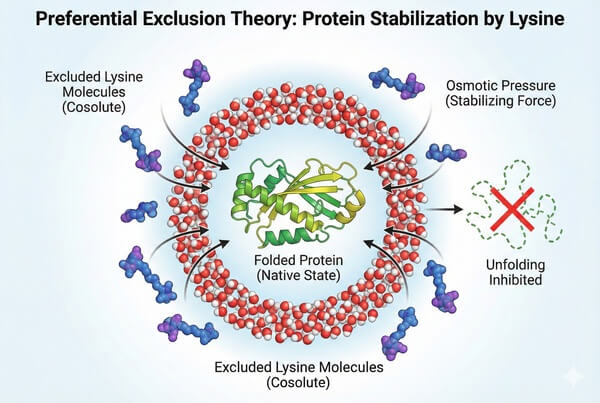
I spent about six months trying to get a decent diffraction pattern from a kinase inhibitor complex, and the problem kept coming back to a single lysine residue at the binding interface. The side chain was rotating between three conformations depending on the pH of my sitting-drop buffer, and every time I changed the condition to lock it into place, something else fell apart. That's the thing about lysine that textbooks don't really stress enough: the epsilon amino group isn't just a basic residue, it's a structural wild card that can switch between charged, hydrogen-bonded, and covalently modified states in a single experimental series. The R group of lysine is a four-carbon aliphatic chain terminating in a primary amine. At physiological pH, that amine is protonated, carrying a positive charge. That sounds simple enough, but the consequences ripple through every level of protein architecture. The charge makes lysine highly soluble in water, which drives it to the surface of globular proteins. But when it's buried, it can stabilize salt bridges with aspartate or glutamate residues, and those interactions are often the difference between a folded protein and a precipitated mess in your centrifuge tube. What most people miss is the pKa. The epsilon amino group sits around 10.5, which means in most cellular conditions it's charged, but in enzyme active sites or membrane interfaces the local electrostatic environment can shift that pKa down to 8 or even lower. I've seen it happen with a histidine-lysine pair in a protease active site where the histidine pulled electron density away from the lysine, making it neutral at pH 7.4. That neutral state allowed the lysine to flip inward and participate in hydrophobic packing, something you'd never predict from a sequence alone.
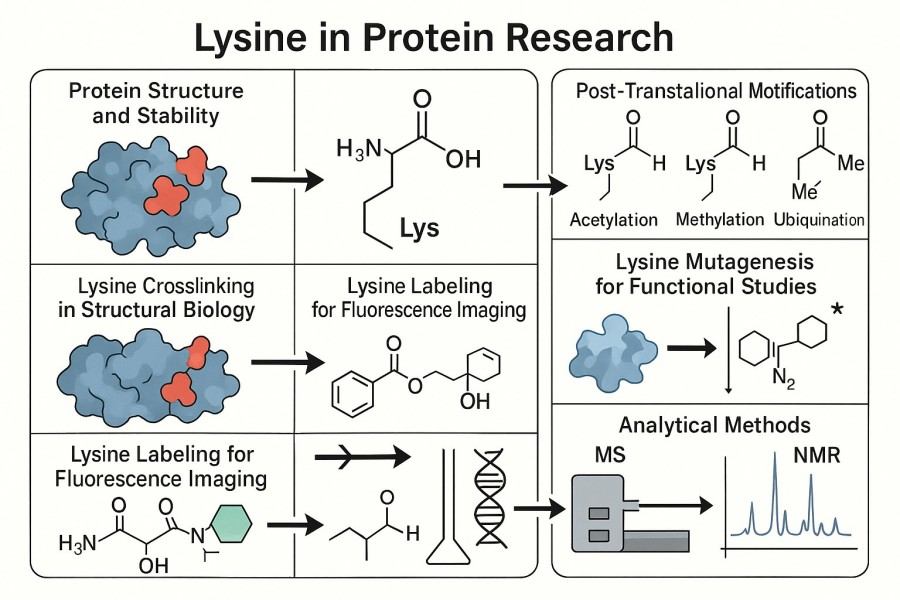
The modification landscape is where things get interesting for anyone working in pharma. Lysine is the most frequently modified residue in the proteome. Acetylation, methylation, ubiquitination, SUMOylation, palmitoylation — these aren't just regulatory curiosities. They change the volume, charge, and hydrogen-bonding capacity of the side chain in ways that directly alter protein-protein interaction surfaces. An acetyl group removes the positive charge and adds a hydrophobic methyl. A ubiquitin adds roughly 8.5 kilodaltons of steric bulk. Methylation is subtler but can tune the strength of cation-pi interactions with aromatic residues like tryptophan or tyrosine. From a structural perspective, lysine's flexibility is both an asset and a liability. The four methylene groups give it about five rotatable bonds, which means in a cryo-EM map at 3 angstroms resolution you might see electron density for the backbone but nothing for the side chain. In X-ray crystallography, it's common to model lysine as multiple conformations or to leave it unmodeled entirely if the B-factor gets too high. I learned this the hard way when building a model for a membrane protein where three surface lysines had entirely undefined density, and the reviewers asked me to justify why I wasn't modeling them. The justification was that the B-factors were off the chart and the density was noise, but it's easier to just say the side chains are disordered and move on.
How This Affects Drug Design Decisions
When you're designing a small molecule inhibitor, lysine residues at the binding site are double-edged swords. On one hand, the positively charged ammonium group can form strong ionic interactions with acidic substituents on your compound — a carboxylate or a sulfonate group can deliver meaningful binding energy. On the other hand, that same charge makes desolvation costly. Moving a lysine from water into a hydrophobic binding pocket requires stripping away its hydration shell, and if your compound doesn't compensate with a correspondingly strong interaction, you're just paying an energetic tax. I worked on a project where we were optimizing a binder for a protein-protein interaction involving a lysine that formed a salt bridge with an aspartate on the partner protein. Our first-generation inhibitor mimicked that salt bridge with a carboxylate, and the IC50 was in the low micromolar range. The problem was that the carboxylate was also interacting with water molecules in the pocket, and those interactions were entropically unfavorable. When we switched to a tetrazole bioisostere, which is a cyclic system that holds its negative charge more rigidly and sheds water more cleanly, we dropped into the low nanomolar range without changing anything else about the scaffold. That's the kind of detail that matters when you're trying to get from hit to lead. Covalent inhibitors are another area where lysine chemistry is central. The classic mechanism involves an electrophilic warhead — acrylamide, chloroacetamide, morpholine ketone — reacting with the epsilon amino group of a lysine near the binding site. The kinetics depend heavily on the local pKa of that lysine. If the lysine is in a hydrophobic environment with a lowered pKa, it's more likely to be in the neutral amine form, which is the nucleophilic species that attacks the warhead. A charged ammonium group won't react. I've seen cases where a single point mutation adjacent to the target lysine shifted the pKa by over a unit and completely abolished covalent binding, even though the mutation didn't touch the binding pocket directly.
Get the Full Details
This is also why lysine targeting is a common strategy in antibody-drug conjugates and proteolysis-targeting chimeras. The lysine residues on the surface of a therapeutic protein provide attachment points for linkers and payloads. But the heterogeneity of lysine modification — not every lysine is equally accessible, and some are already occupied by post-translational modifications — means your drug-to-antibody ratio can vary significantly between batches. I've seen ADC preparations where the distribution spanned from DAR 0 to DAR 8 when the target was supposed to be DAR 4, and half of that variance came from lysines that were already acetylated in the host cell line.
What Nobody Tells You About Lysine in Computational Work
If you're running molecular dynamics simulations, protonation state assignment for lysine is one of those things that can make or break your results. Most standard force fields assume lysine is always positively charged, but that's wrong in a significant fraction of biological contexts. Programs like PROPKA can predict pKa shifts, and they're usually within one pH unit of experimental values, but the uncertainty matters when you're trying to model a reaction or a conformational switch that depends on the protonation state. I ran a simulation once where the lysine in question was positioned near a cluster of negative charges, and the standard assumption of permanent positive charge led to unrealistic electrostatic clustering that propagated through the entire trajectory. When I manually set the residue to neutral and reran, the protein adopted a completely different conformation that actually matched the experimental data. It took three days of debugging before I realized the issue wasn't with the force field parameters but with the initial protonation state. Docking studies have a similar problem. AutoDock and Glide and the other mainstream tools typically treat lysine as a rigid positively charged residue, but the side chain can adopt many conformations, and the relevant one for binding might not be the lowest-energy solution state conformation. I've had cases where the predicted binding pose put a key lysine in a geometry that required an impossible dihedral angle, and the scoring function still gave it a good score because it couldn't penalize strain properly. Running a short minimization or MD relaxation after docking often catches these issues, but it adds time to the workflow.
Where Lysine Chemistry Falls Short
Not every lysine is a good drug target, and some of the assumptions in the literature don't hold up under scrutiny. The idea that lysine residues are uniformly reactive toward electrophilic warheads is clearly wrong. Accessibility matters enormously — a lysine buried in a hydrophobic core or stabilized by a salt bridge network is essentially inert. Even on the surface, steric hindrance from neighboring residues or glycosylation can block reaction. I've seen papers claim lysine targeting as a general strategy without reporting the actual labeling efficiency at each site, which makes it hard to compare results across laboratories. Another limitation is that lysine modification is often reversible in vivo. Deacetylases, deubiquitinases, and demethylases can reverse the very modifications that drive protein function, which means that targeting lysine-mediated interactions with small molecules may not produce sustained effects unless you're also interfering with the modifying enzymes. This is actually useful information if you're designing a drug, because it means you can predict a shorter half-life of effect for lysine-targeting compounds compared to covalent inhibitors that form irreversible bonds. But it also means that dosing regimens need to account for the turnover rate of the modification. There's also the issue of off-target reactivity. Electrophilic warheads that target lysine in a protein of interest will also react with lysine residues on albumin and other abundant plasma proteins, which reduces the effective concentration of the drug and can generate reactive metabolites. This isn't unique to lysine targeting — it's a general problem with covalent drug design — but lysine is so abundant on protein surfaces that the off-target probability is higher than you might expect from a simple sequence count.
For people moving into this space, the practical takeaway is that lysine's R group is far more versatile than introductory biochemistry suggests. The charge, the flexibility, the modification potential, and the pKa sensitivity all combine to make it a central determinant of protein structure and a recurring consideration in drug design. If you're working on anything involving protein-ligand interactions, pay attention to the lysines near your binding site. Run the pKa calculations, check the electron density, and don't assume the side chain is doing what the textbook says it should be doing.