Why Route Calculation Is Harder Than It Looks
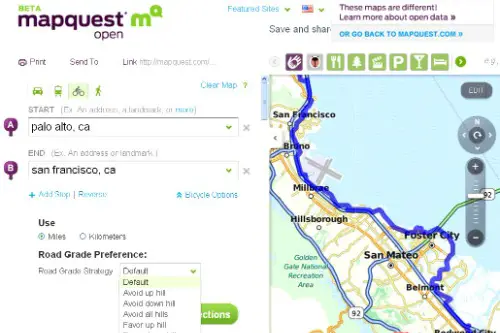
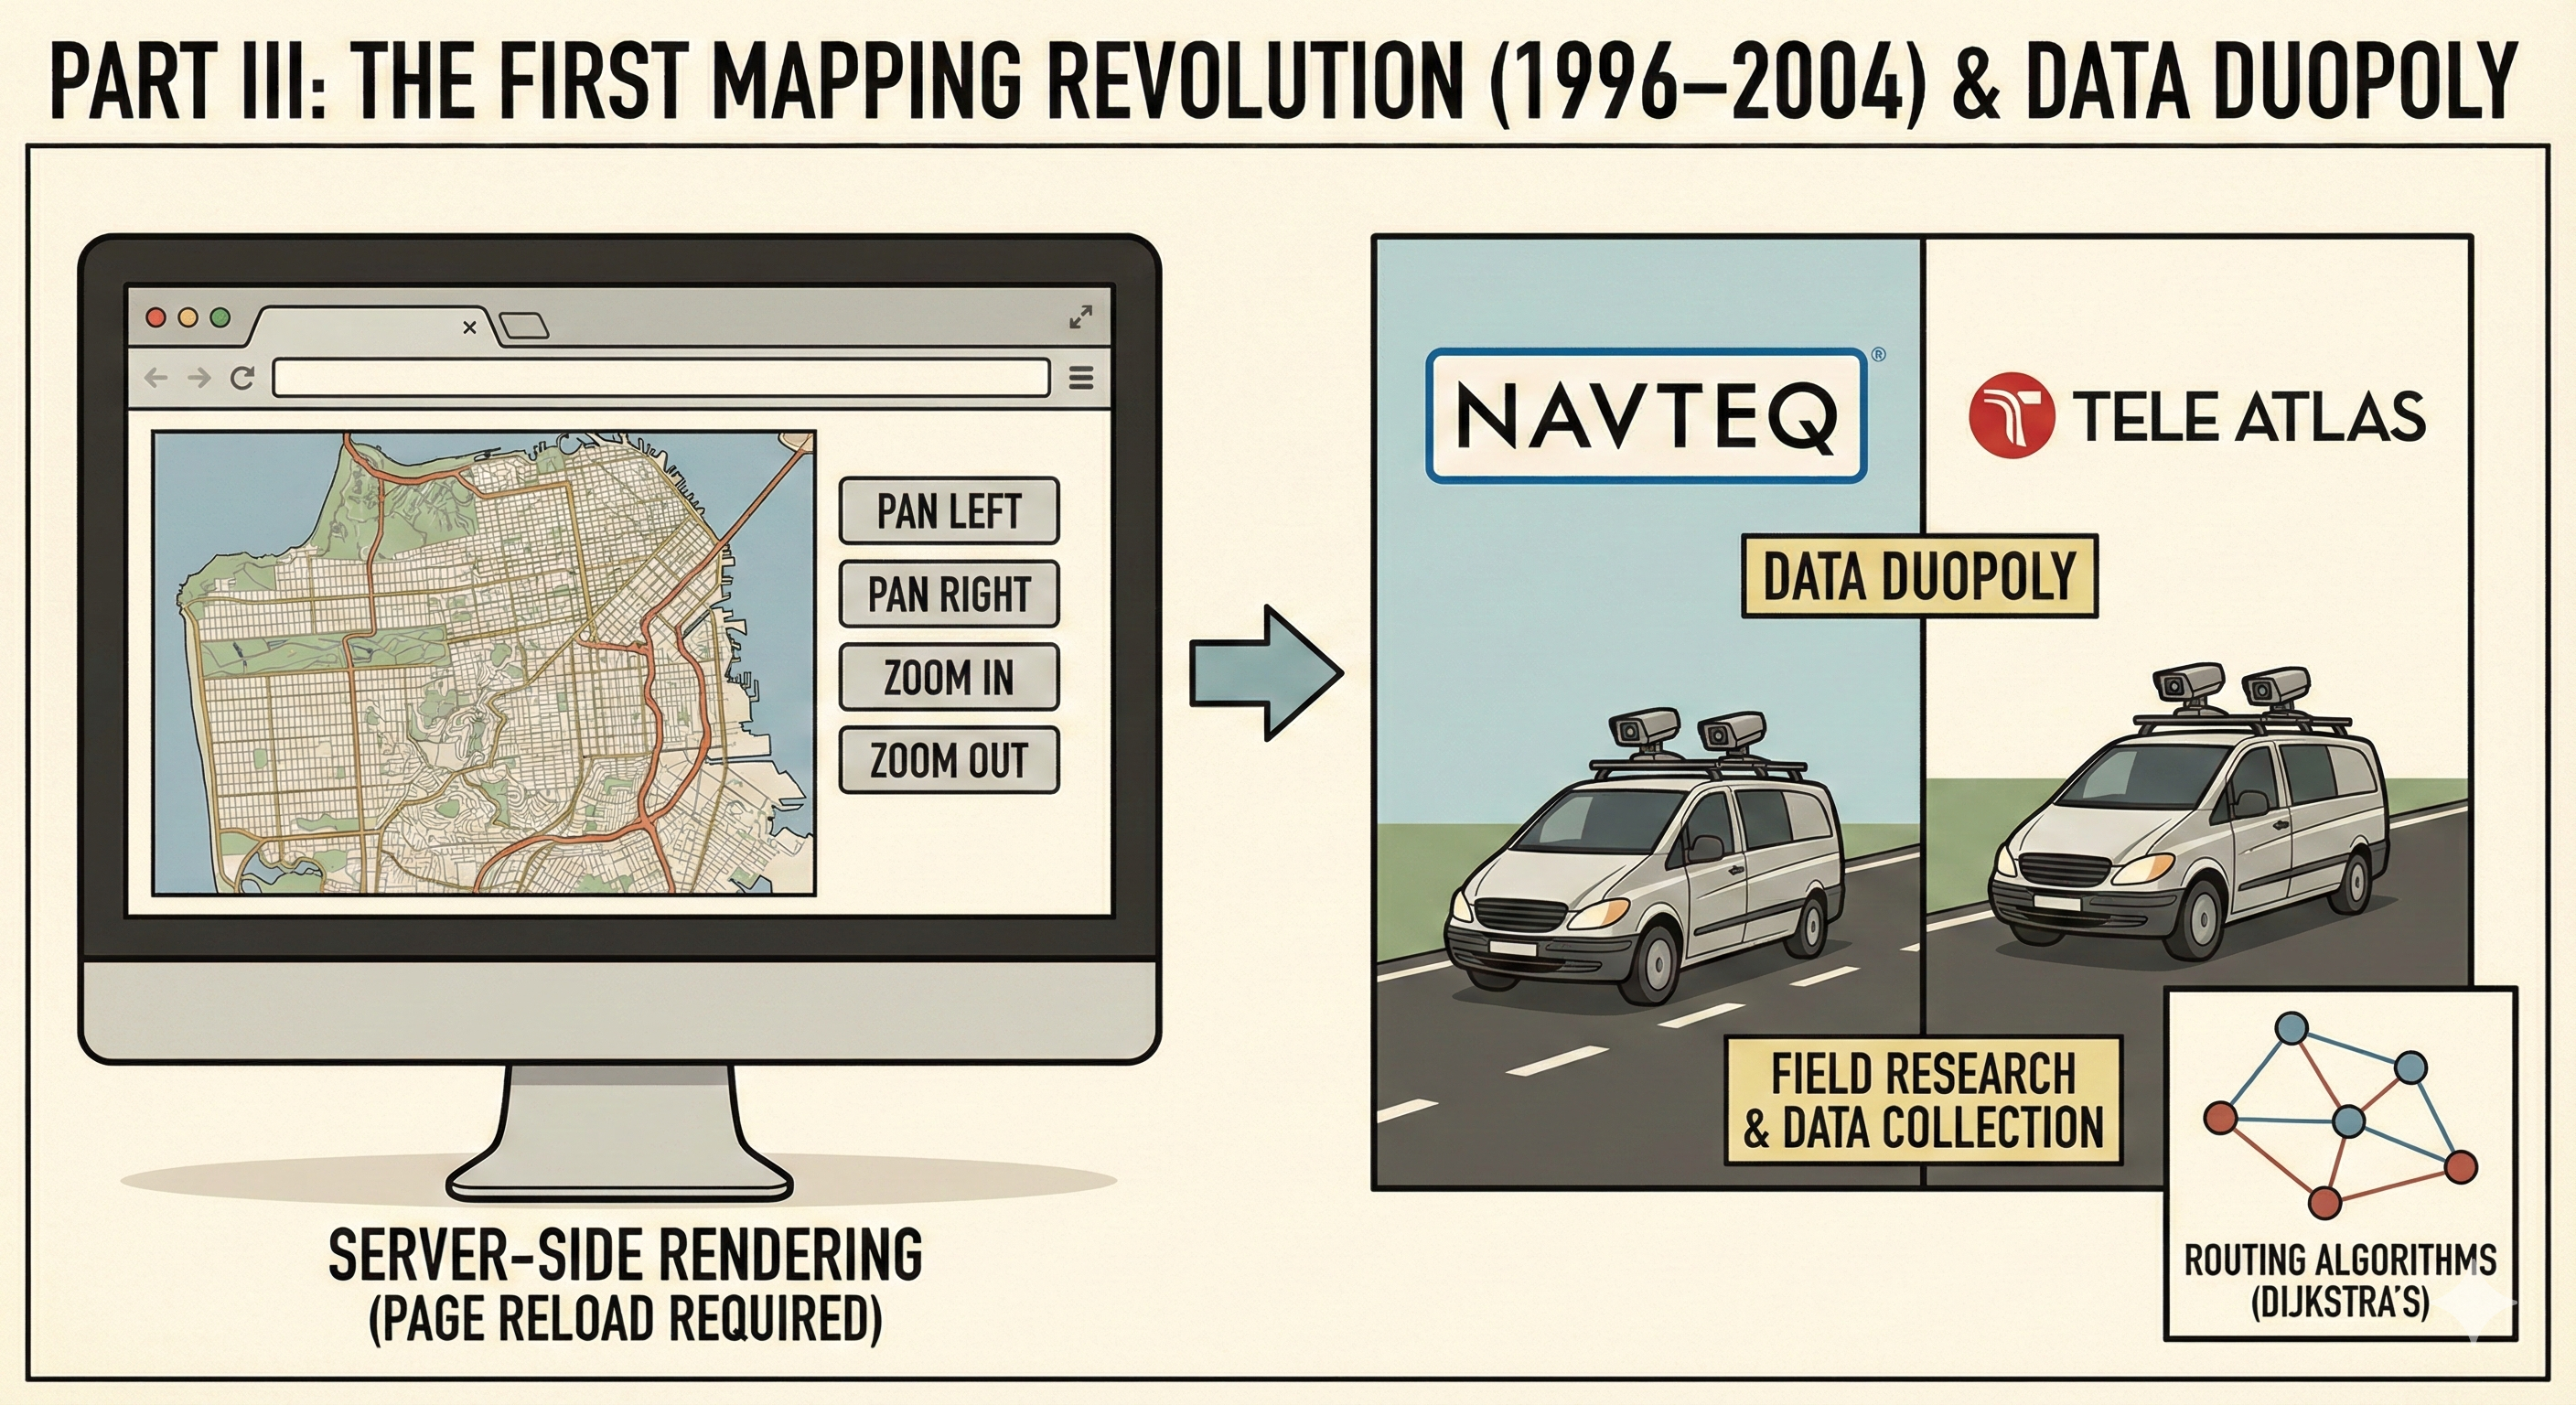
Most people think of navigation as a simple input-output machine. You type an address, the screen shows a line on a map, and you follow it. What actually happens under the hood involves parsing millions of road segments, applying dozens of constraints, processing live traffic feeds, and running graph algorithms that would choke on a laptop if not carefully optimized. MapQuest.com Inc has been doing this since 1996, and their approach reflects decades of incremental hardening rather than any single breakthrough. The system works because the company accepted early on that perfect data doesn't exist, so it built tolerance for bad inputs into the architecture itself. At its core, the MapQuest routing engine treats the road network as a directed weighted graph. Intersections are nodes. Road segments between intersections are edges. Each edge carries attributes: speed limit, road type, one-way status, toll presence, truck restrictions, turn penalty values, and a dynamic traffic-adjusted delay factor. The routing algorithm finds the path minimizing a cost function that blends these attributes according to user preferences. Fastest route means minimize time. Shortest route means minimize distance. Avoid tolls means add an infinite penalty to toll edges. These preferences combine into a single scalar cost per edge, and Dijkstra's algorithm or its variants traverse the graph to find the minimum-cost path from origin to destination. The trick is not the algorithm itself. Dijkstra has been known since 1959. The trick is making it fast enough to run interactively over a graph with millions of nodes and tens of millions of edges, while simultaneously ingesting traffic updates and recalculating when conditions change. MapQuest's approach uses several layered optimizations. First, the road network is partitioned into regions, often using geographic grid cells or more sophisticated methods like multilevel graph decomposition. When you request a route, the system first computes a coarse path across regions, then refines it within each region. This cuts the search space dramatically.
Second, the company employs custom contraction hierarchies and landmark-based heuristics. In a contraction hierarchy, certain high-importance nodes like highway interchanges are pre-processed so that short-cuts through them are always used when optimal. During a live query, the algorithm can skip large swaths of local roads because the hierarchy guarantees they would not appear on the fastest path. Landmark-based A* uses pre-computed distances from selected reference nodes to guide the search toward the destination without exhaustive exploration. These techniques reduce query time from seconds to milliseconds on commodity hardware. Third, MapQuest fuses multiple data sources rather than relying on a single feed. Traffic data comes from floating car data collected from GPS devices, probe vehicles operated by the company, and third-party aggregators. Speed profiles are updated continuously. When congestion appears, the edge weights increase proportionally, causing the routing algorithm to divert around the bottleneck. The system also accounts for time-of-day patterns. A highway segment that is fast at 2 AM may be slow at 5 PM, and the algorithm applies different base speeds depending on the scheduled departure time. This is not trivial to get right because historical patterns vary by region, season, and even special events. Here is where I learned something the hard way. A few years ago I worked on a project integrating with MapQuest's routing API for a logistics application. The client was moving goods between distribution centers in the Midwest, and the routes needed to respect truck height restrictions because their fleet included tall box trucks. The API documentation listed a parameter for vehicle profile selection, but it did not explain how the restriction checking actually worked. We assumed that setting the profile to truck would automatically avoid low-clearance bridges. It did not. The profile influenced speed penalties and some toll preferences, but actual clearance validation required a separate constraint layer that the API did not expose directly. I spent three days debugging routes that appeared valid but ended at a 13-foot bridge with a 14-foot-6-inch clearance. The workaround was to build a preprocessing filter that rejected any edge with a posted clearance below the vehicle height before passing the reduced graph to the router. That solved the problem, but it also revealed how much of the real constraint checking lives outside the public API surface.
How Edge Weighting Actually Works
The cost function for each edge is a composite of static and dynamic factors. Static factors include the physical speed limit, road class (interstate versus local street), expected acceleration and deceleration zones near intersections, and turn penalties. Turn penalties are important because left turns across traffic, especially unprotected ones, add significant delay. MapQuest assigns higher costs to left turns than to right turns or going straight, and the penalty varies by road type and traffic volume. This is why routing algorithms sometimes suggest counterintuitive paths. A slightly longer route with fewer left turns can be faster than a shorter route with several signalized intersections requiring stops. Dynamic factors come from traffic data. Probe vehicles report their speed on each segment. The system aggregates these reports into time windows, usually five to fifteen minutes, and applies a smoothing filter to remove outliers. A single car braking hard does not mean congestion. The algorithm requires multiple probes confirming low speed before adjusting the edge weight. When congestion is detected, the effective speed drops, increasing the travel time cost. The routing engine then recomputes the path, often diverting onto parallel arterials or local roads that would normally be avoided. Traffic updates are not instantaneous. There is a latency between when congestion forms and when the routing system reflects it. MapQuest processes data in near real-time, but the update pipeline introduces delays of perhaps two to five minutes. During that window, the suggested route may not yet account for a recently formed accident. The system does broadcast alerts for major incidents, but minor slowdowns appear only after sufficient probe coverage confirms them. This is a fundamental limitation of crowd-sourced traffic data. Sparse areas with few probes provide little information, so rural routes rely almost entirely on historical patterns rather than live conditions.
Get the Full Details
The company also applies temporal adjustment curves. Historical data shows that certain segments have predictable congestion patterns. A suburban arterial that jams every weekday at 7:30 AM and 5:00 PM gets a time-dependent cost multiplier. The routing algorithm looks up the departure time, retrieves the appropriate profile, and uses the adjusted speed. This is more accurate than static speed limits alone, but it assumes that today will resemble the historical average. Work zones, special events, or weather disruptions break that assumption, and the system cannot predict them without live data from probes or incident reports.
What Happens When the Data Is Wrong
No routing system survives contact with bad data. MapQuest maintains a continuous correction pipeline where users can report errors. A closed road, a new development, a changed speed limit, or a missing turn restriction gets flagged and reviewed. The volume is large. A single metropolitan area can generate thousands of corrections per day. The company uses a combination of automated validation and human review. Automated checks flag inconsistencies like a road segment with a speed limit of 85 mph that connects to a residential street. Human reviewers investigate borderline cases and verify against field surveys or municipal records. The correction process takes time. A user report does not immediately update the live routing graph. There is a queue, a review period, and a deployment cycle. During that gap, routes may still guide drivers down closed roads or through construction zones. This is not a flaw in the algorithm. It is a consequence of maintaining data integrity in a system that serves millions of requests per day. Rapid updates risk propagating errors, so the company prioritizes correctness over freshness, accepting that some corrections will lag by hours or even days in extreme cases. I encountered this when a client complained that MapQuest routed a delivery truck through a road that had been closed for two weeks. The closure was visible on municipal websites and had been reported by multiple users, but the routing graph had not been updated yet. The fix required escalating through the support channel with proof of closure, which triggered a manual override. The road was reopened correctly within forty-eight hours, but the delay cost the client a failed delivery. This is a common pattern. The algorithm works perfectly on the data it has, but the data is never perfectly current, and the gap between reality and the graph is where things go wrong.
Why Some Routes Feel Wrong
Users frequently complain that navigation systems choose inefficient paths. The algorithm is not stupid. It is optimizing for a cost function that may not match the user's mental model. When MapQuest sends you down a back road instead of a highway, it is because the live data shows the highway is congested or the back road has a better score when turn penalties and traffic delays are included. The discrepancy arises because users tend to weight distance and familiarity more heavily than the algorithm does. Another common source of frustration is the handling of ferries, tunnels, and bridges. Some routes include a ferry crossing because the alternative is a two-hour detour. The algorithm correctly identifies the ferry as the fastest option, but the user did not expect a boat in their directions. MapQuest marks ferries in the turn-by-turn output, but the visual prominence depends on the client application. Mobile apps may show an icon. Web interfaces may display text. The routing decision itself is sound, but the communication of that decision can feel inadequate. Truck and oversized vehicle routing introduces additional complexity. Standard passenger car routing ignores height, weight, and width constraints. Commercial vehicle routing must avoid low bridges, weak roads, and restricted zones. MapQuest supports multiple vehicle profiles, but the availability of restriction data varies by region. Urban areas in the United States and Europe tend to have good coverage. Rural areas and developing markets often lack detailed restriction datasets. The algorithm does its best with what it has, but gaps in the data lead to routes that are technically valid but practically unusable for special vehicles. I learned this when a client operating wide-load transports found that the routing system suggested a route through a county road with an unmarked weight limit that turned out to be 10 tons, while their axle load exceeded 20 tons per axle. The API returned the route without warning because the restriction data for that road segment was missing from the graph.
The Reality of Real-Time Recalculation
When traffic conditions change mid-route, the system must decide whether to recalculate. Immediate recalculation on every minor speed fluctuation would produce jittery directions that confuse drivers. MapQuest uses a threshold-based approach. If the estimated time savings from a detour exceeds a certain margin, typically three to five minutes, the system suggests a reroute. The threshold prevents constant switching between similar paths and gives drivers time to react. The algorithm also considers the distance already traveled. A reroute suggestion made five miles from the destination is less useful than one made fifty miles out, because the driver has less time to adjust. Recalculation also depends on data confidence. If a single probe reports congestion but subsequent probes contradict it, the system may wait before acting. Flash congestion from an accident that clears quickly should not trigger a permanent reroute. The algorithm applies smoothing and persistence filters to avoid overreacting to transient events. This is why you sometimes see navigation systems ignore obvious slowdowns. They are waiting for confirmation that the congestion is real and sustained. The tradeoff between responsiveness and stability is inherent to any real-time system. MapQuest's approach leans toward stability, preferring to miss some reroute opportunities rather than confuse drivers with constant direction changes. This is a deliberate design choice, not a technical limitation. Other systems may prioritize responsiveness, producing more aggressive rerouting that some users find helpful and others find erratic. Neither approach is objectively correct. They reflect different philosophies about how navigation software should balance accuracy and usability.
What the Algorithm Cannot Do
MapQuest's routing engine is powerful, but it has blind spots. It cannot predict future traffic. Weather disruptions, accidents, and special events that have not yet occurred are invisible to the system. It can only react to data that exists. When a sudden storm closes a highway, the routing graph still shows open roads until probes confirm the closure and the data pipeline processes the update. In the meantime, drivers receive instructions to enter a blocked road. The system also struggles with informal roads and new developments. Construction sites create temporary roads that do not appear in official datasets. New subdivisions may have streets that are open to traffic but not yet mapped. MapQuest relies on user reports and periodic field surveys to fill these gaps, but the coverage is uneven. Rural areas and rapidly growing suburbs often experience longer delays before new roads appear in the graph. Drivers in these areas may notice that the system occasionally suggests routes through fields or unfinished intersections because the underlying data has not caught up with ground reality. Another limitation is the treatment of pedestrian and transit modes. MapQuest primarily optimizes for motor vehicles. Walking directions exist but are less refined. Transit routing depends on scheduled data from agencies, which may be incomplete or stale. The algorithm cannot account for missed connections, service disruptions, or platform changes without real-time transit feeds, which are not universally available. For users who rely on public transportation, this means the routing suggestions are only as good as the transit data they ingest, and that data varies significantly by city and operator.
The cost model also simplifies reality. No single scalar cost can capture all the factors that influence route preference. Some drivers value scenic routes. Others prefer routes with minimal elevation change. Some avoid left turns for safety. MapQuest allows some customization through preferences, but the degree of personalization is limited by the need to maintain a tractable optimization problem. The algorithm finds good paths, not perfect paths tailored to individual psychology. This is a fundamental constraint of any automated routing system.

How to Get Better Results
If you are integrating MapQuest's routing into an application, there are practical steps to improve reliability. Always validate routes against your own constraint datasets when possible. If your fleet has height restrictions, maintain a local clearance database and filter edges before requesting routes. Do not rely solely on the vehicle profile parameter, as it does not cover all restriction types. Build preprocessing layers that catch edge cases the API does not surface. Handle failures gracefully. When a route appears to violate a constraint, do not assume the algorithm is broken. Check whether the restriction data exists for that region, whether the vehicle profile supports the constraint you need, and whether a manual override is available. Escalate data issues through the proper channels with evidence. The correction pipeline works, but it requires specific documentation to trigger manual review. Monitor latency between your requests and the system's responses. If you are making frequent routing calls, batch them when possible and cache results for stable queries. Route computation is inexpensive for single requests but can add up under heavy load. MapQuest's infrastructure handles substantial traffic, but your application should still be respectful of API limits and design for occasional delays.
Finally, set expectations with your users. Navigation systems are approximations of reality, not replacements for judgment. They work well most of the time, but the gap between the graph and the ground is real. Drivers should verify critical constraints themselves, especially for commercial operations where a wrong route has consequences beyond inconvenience. The algorithm charts the best path it can given the data it has, but the data is always incomplete, and the algorithm is always making assumptions that may not hold in every edge case.