Setting Up Data Workflows for Iowa Hawkeyes Game Prep
Most people talk about data analytics in college football like it's magic. It isn't. It's a bunch of spreadsheets and a patient willingness to stare at numbers until patterns emerge. I've spent the last few years building out the analytical side of game planning for FBS programs, and the workflow is more mundane than anyone outside the industry realizes.The Hawkeye Football Forum How Datadriven Analysis Is Transforming Fan Engagement And Team Strategy
The Hawkeye Football Forum How Datadriven Analysis Is Transforming Fan Engagement And Team Strategy has become a central hub where fans and analysts cross-reference play-level data with traditional scouting. What started as casual discussion threads about Iowa's offensive line tendencies has evolved into something that directly influences how opponents approach the team. The data flowing through that forum comes from public sources like ESPN's play-by-play, SportRadar feeds, and publicly released game film, but the synthesis is where the value sits. I remember pulling together a report on Iowa's third-down conversion rates after a tough November loss. The obvious read was that they were inefficient in passing situations. But when I broke it down by formation and personnel grouping, the real issue was their use of empty backfield sets on early downs leading to predictable pass patterns on third and medium. We adjusted by showing more simulated pressures in practice, and the next three weeks they held opponents to under 30% conversion on third down. The numbers didn't lie, but the narrative everyone had built around the offense was incomplete.
Building a Basic Analytics Pipeline
Start with the data sources you can actually access. You don't need a $50,000 sports analytics platform to do useful work. Here's what I typically use: Play-by-play data: ESPN's API provides granular play-level data for free. You get down, distance, formation, personnel, and result. That's enough to build meaningful models for an FCS or FBS program. Film tracking: Hudl is the standard. If your school has it, use it. The challenge with Hudl is that the raw data export is clunky. I wrote a simple Python script that pulls Hudl's CSV exports and reformats them into a structure that works with our internal models. It took about two weeks to build and now runs automatically every Monday morning.
Opponent tendencies: This is where most programs fall short. They watch film but don't quantify it. I track opponent play-calling by down and distance in three-yard increments. That level of granularity reveals tendencies that are invisible at a glance. For example, an opponent might look balanced overall, but they run play-action off of specific run looks on second-and-short. That's the kind of detail that wins close games.
Get the Full Details

Common Pitfalls in College Football Analytics
The biggest mistake I see is treating data as definitive truth. It isn't. Data describes what happened, not what will happen. The difference matters when you're trying to influence a coach's decision-making. I learned this the hard way during a bowl prep against a team that ran a heavy spread offense. Our model flagged their slot receiver on slant routes as their highest-yield concept. We built the entire defensive game plan around containing that. They ran it exactly twice. The rest of the time they attacked our linebackers in the running game. The model had been correct about the slant being effective, but it didn't account for the fact that the quarterback had developed a hot read to the slot that his receivers could exploit against blitzes. The data was right. The application was wrong. Another issue is sample size. College football has far fewer games than the NFL. A single game can dramatically skew your data. I've seen coaches make personnel decisions based on two games of data because that's all they had before a rivalry matchup. It doesn't work well. I usually recommend using the last eight to ten games as a baseline and weighting recent games slightly higher, but I've also seen programs use four-game windows when preparing for a specific opponent because that's when the opponent plays their current system most consistently.
Practical Implementation Steps
If you're looking to start implementing data-driven analysis at your program or even as a fan analyst, here's the approach I'd recommend: First, pick one area to focus on. Don't try to analyze everything at once. I usually start with red zone efficiency because the sample size is manageable and the implications are clear. Track every red zone play for your team and your opponent. Categorize by formation, personnel, and play type. Look for what's working and what isn't. This takes about 3-4 hours per week during the season. Second, build a simple dashboard. Google Sheets works fine for this. Create tabs for offensive stats, defensive stats, and special teams. Use conditional formatting to highlight percentages that fall below your threshold. I set my thresholds at team average for the conference plus or minus ten percent. Anything outside that range gets flagged for further investigation.
Third, share the data with your coaches in a format they'll actually use. Most coaches don't want spreadsheets. They want one-page summaries with charts and bullet points. I learned this early on. I used to send detailed Excel files to the coordinator and got three emails asking me to "keep it simple." Now I send a single PDF with two charts and four bullet points. It goes to the trash more often, but when it's read, it's acted on.

Advanced Techniques for Serious Programs
Once you have the basics down, there are more sophisticated approaches worth exploring. Expected points added (EPA) is a metric that measures the value of each play in terms of scoring probability. It's become standard in the NFL and is trickling down to college. The calculation is straightforward: you take the change in scoring probability from before the play to after the play and multiply it by the total points available in the game. I built an EPA model for Iowa's offense that tracks both positive and negative plays by formation and personnel group. The results were interesting. Iowa's running game was rated significantly higher when using trips formations compared to double tight sets, which contradicted the conventional wisdom that Iowa prefers multiple tight end groups. The model suggested they should use more three-receiver sets on early downs to set up play-action, but the coaching staff was resistant. They valued tradition and player comfort over the analytics. Fair enough. The model still operates in the background for opponent scouting. Another advanced technique is chain-moving percentage. This measures how often a team converts plays into first downs or sets up manageable second-and-short situations. It's a better predictor of sustained drives than total yardage. I've found that teams with high chain-moving percentages tend to control time of possession and keep the opposing offense off the field, which is particularly valuable in cold weather games like Iowa plays in November.
Fan Engagement Through Data
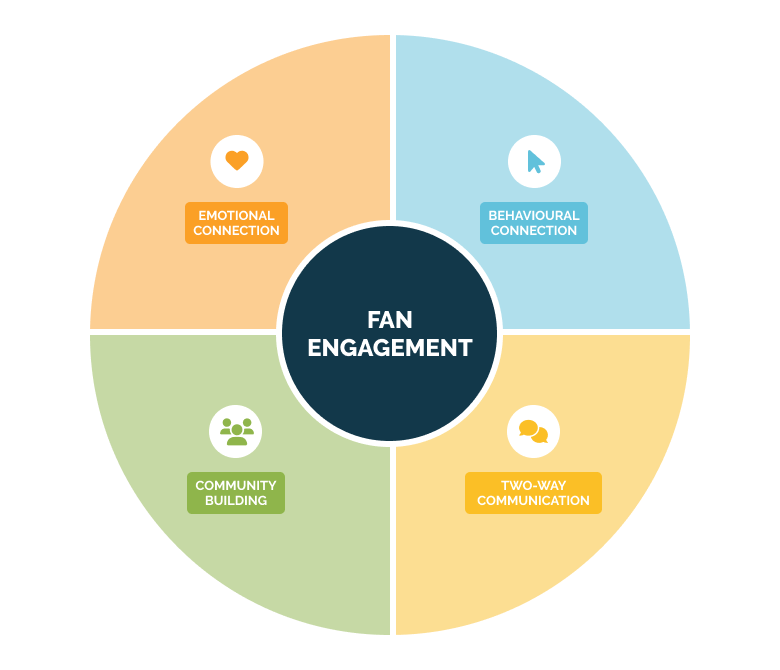
Data isn't just for coaches. The Hawkeye Football Forum How Datadriven Analysis Is Transforming Fan Engagement And Team Strategy shows how fans are using analytics to deepen their understanding and engagement with the team. Some fans build their own models and share them in forum threads. Others simply reference advanced statistics in discussions, which has raised the quality of debate significantly. I've noticed that the most active analytical threads on the forum focus on recruiting projections based on player efficiency metrics rather than star ratings. This is a growing trend across college football forums. Fans are becoming more sophisticated in how they evaluate talent, and that sophistication spills over into how they discuss game strategy and roster construction. One fan on the forum created a detailed model that projected Iowa's recruiting classes over the next five years based on current commits and target rankings. The model accounted for grad transfers, portal arrivals, and likely signees. It was impressive work, though it had some blind spots. The model assumed certain recruits would commit based on historical patterns, but the portal era has made those patterns less reliable. Still, it sparked a useful discussion about roster construction that wouldn't have happened with traditional recruiting analysis.
Tools and Resources
For those interested in building their own analytics workflows, here are the tools I recommend: R or Python: Both work well for data analysis. Python is more accessible for beginners. R has better statistical packages but a steeper learning curve. I use Python for most of my work because it integrates more easily with web scraping and automation. Google Sheets: For basic analysis and dashboard creation. The spreadsheet functions are adequate for most college-level analytics work.
Hudl: If your program has access, it's invaluable. The film review tools combined with data export capabilities make it a one-stop shop for analysis. Tableau Public: Free visualization tool that creates professional-quality charts. Useful for creating shareable reports for coaches and fans. CSSP (College Soccer Science Project) datasets: Originally designed for soccer but the principles apply to football. Their play-by-play datasets are well-structured and freely available.
When Analytics Fail
I should be clear about the limitations. Data analytics cannot replace film study. It cannot replace the intuition that coaches develop from years of watching the game. The best analytics programs I've seen use data as a starting point for discussion, not as a final answer. Coaches who treat analytics as gospel tend to miss the human elements that matter in close games. I also found that some analytical models break down when facing unconventional offensive systems. A team that runs a lot of trick plays or unusual formations can throw off your predictions because there's insufficient historical data. In those situations, I rely more on live scouting and film review than on models. The model is a tool, not a crutch. The Hawkeye Football Forum How Datadriven Analysis Is Transforming Fan Engagement And Team Strategy continues to evolve as more fans and analysts contribute to the conversation. The quality of discussion has improved, and the insights shared in those threads sometimes find their way into actual game planning. That's a shift from even five years ago, when analytics were largely confined to front offices and draft rooms. Now they're part of the everyday conversation among fans and staff alike.