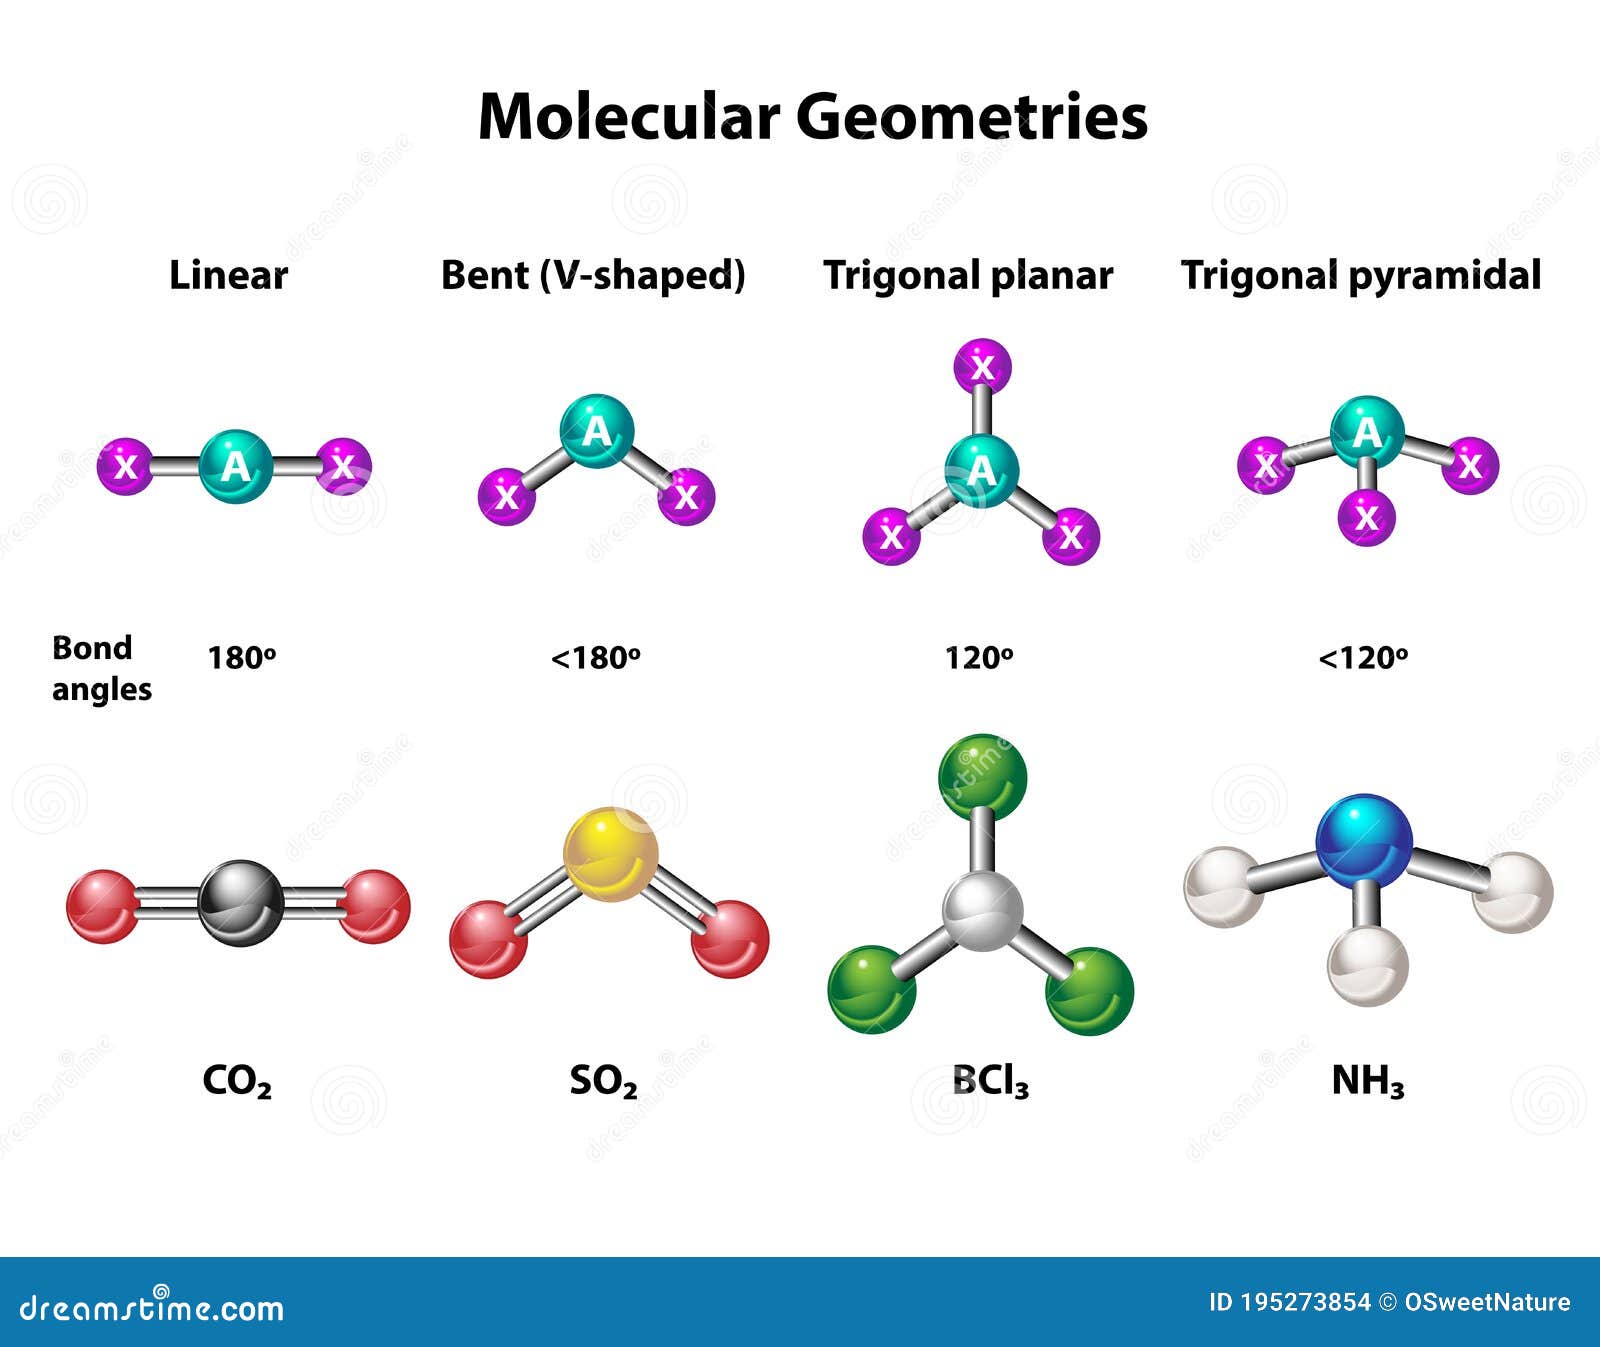
Understanding How Molecules Arrange Themselves In Space
I spent three weeks trying to get a crystal structure to refine properly last year. The molecule kept giving me impossible bond angles, and I eventually realized the problem wasn't the sample or the instrument. It was my initial model. I had placed the atoms using standard bond lengths without accounting for the actual steric clashes in the bulky side chains. Once I rebuilt the model manually with the correct geometry, the R-factor dropped from 0.28 to 0.11 in two cycles. That experience taught me that molecular geometry isn't just about memorizing VSEPR theory from your undergraduate textbook. The real world has complications that simple models don't capture. You need to understand what governs these shapes and when the standard rules break down.
The Geometry Of Molecules Unlocking The Secrets Of The Molecular World
Molecular geometry describes the three-dimensional arrangement of atoms within a molecule. This isn't abstract theory. The shape determines how molecules interact with each other, how drugs bind to receptors, and why certain materials conduct electricity while others don't. When you're working with computational chemistry or structural biology, getting the geometry wrong means your entire simulation is garbage. The basic framework comes from several sources. Valence Bond Theory explains hybridization and orbital overlap. Molecular Orbital Theory deals with delocalized electrons and bonding across entire molecules. VSEPR theory predicts shapes based on electron pair repulsion. Each approach has specific use cases and limitations. I should tell you about something most people miss. Hybridization is a mathematical construct, not a physical reality. When you see sp3 mentioned in textbooks, it's a useful shorthand for describing tetrahedral geometry, but the electrons don't actually "hybridize" in any measurable way. The real physics comes from solving the Schrödinger equation for the system. Modern computational methods like DFT approximate this directly without invoking hybridization at all.
Here's a practical workflow I use when determining molecular geometry from experimental data. First, you need quality diffraction data. X-ray crystallography gives you electron density maps, but the resolution matters enormously. At 2.0 angstroms, you can reliably place carbon and nitrogen atoms. At 3.5 angstroms, you're mostly guessing where the hydrogens go. I've seen people publish structures at poor resolution where the "geometry" turned out to be completely wrong because the model was over-interpreted. If you're working with smaller molecules in solution, NMR spectroscopy provides distance constraints through NOE experiments. These give you interatomic distances rather than precise coordinates. You then use constraint-based modeling to generate structures that fit the data. The resulting ensemble shows you the flexibility of the molecule, which is actually more useful than a single static picture. Electron diffraction works for gas-phase molecules. This method avoids crystal packing effects entirely, giving you geometry in isolation. The tradeoff is that you can only study volatile compounds, and the data analysis requires sophisticated scattering calculations.
Get the Full Details

When building computational models, I start with semi-empirical methods like PM6 or AM1 for quick geometry optimization. These are fast but have known systematic errors. Bond lengths might be off by 0.05 angstroms. For publication-quality results, I move to DFT with a functional like B3LYP or wB97X-D and a triple-zeta basis set. This typically takes 2-4 hours for a moderate-sized organic molecule on a standard workstation. Something counter-intuitive about DFT: more expensive functionals don't always give better geometries. B3LYP, despite its age, often produces better bond lengths than newer meta-GGA functionals for organic molecules. The error cancellation between exchange and correlation components plays a bigger role than people realize. I learned this the hard way when I spent a week optimizing with a fancy functional only to find the bond angles were systematically wrong compared to the crystal structure. For transition metal complexes, the geometry problem gets significantly harder. Ligand field effects, Jahn-Teller distortions, and multireference character mean you often need CASSCF or CASPT2 calculations. These are computationally expensive and require expertise to set up correctly. A single calculation can take days on a cluster. I've had postdocs spend weeks trying to get reasonable geometries for certain lanthanide complexes before switching to simpler methods and accepting the limitations.
Here's another practical issue. Hydrogen atoms are notoriously difficult to position accurately. In X-ray structures, hydrogen scatters X-rays weakly because it has only one electron. Neutron diffraction solves this problem but requires a neutron source and large crystals. Most researchers simply ride the hydrogens along, placing them in calculated positions based on idealized geometry. This works well for heavy atom positioning but introduces uncertainty when you're studying hydrogen bonding networks. Biochemical systems present their own challenges. Proteins have backbone constraints from the peptide bond, which is planar due to partial double bond character. The omega angle is fixed at 180 degrees for trans peptide bonds. Phi and psi angles define the conformation, and Ramachandran plots show which combinations are sterically allowed. I've seen people generate protein models with phi angles in disallowed regions because the force field didn't penalize those geometries sufficiently. Nucleic acid geometry follows different rules. The sugar pucker affects the overall helical parameters. C2'-endo sugars favor B-form DNA, while C3'-endo favors A-form. RNA is almost exclusively A-form because the 2'-hydroxyl group sterically blocks the C2'-endo conformation. When modeling DNA-protein interactions, getting the sugar pucker wrong can make or break your binding energy calculations.
A common mistake I see is assuming that optimized gas-phase geometry matches solution or solid-state geometry. Crystal packing forces can distort bond angles by several degrees. Solvent effects shift conformer populations. I once spent a day troubleshooting why my computed NMR shifts didn't match experiment before realizing the gas-phase optimized structure was the wrong conformer for the solution conditions. Software choices matter too. Gaussian is reliable but expensive. ORCA is free and excellent for transition metals. GAMESS has good functionality but a steeper learning curve. For biomolecules, AMBER and CHARMM are standard but require careful parameterization. I recommend validating your software choice against a known reference system before committing to it for production work. The field moves fast. Machine learning potentials are starting to challenge traditional quantum chemistry methods. Some approaches can predict geometries in seconds that would take DFT hours, though they lack the theoretical rigor for novel systems. I'm cautious about relying on them for anything where I can't verify against first-principles calculations.

When teaching this material, I emphasize that geometry determination is iterative. You collect data, build a model, refine it, check the residuals, and repeat. The final structure is always an approximation constrained by the available information. Acknowledging uncertainty in your geometry estimates is more credible than claiming unrealistic precision. For the record, if you're studying supramolecular assemblies or disordered systems, single-molecule geometry concepts break down. You need ensemble descriptions or time-averaged structures. This limitation applies to cryo-EM data interpretation particularly badly. The "resolution" number hides enormous local variation.