Genetic engineering tools in the lab are nothing like the textbooks make them look
I spent about seven years working with recombinant DNA systems before I ever felt comfortable telling someone else how to do it. The gap between reading a protocol and actually getting clean results is usually measured in failed experiments, not wasted time. Most people skip past the boring parts because they want the answer quickly. That approach works until your plasmid prep comes back contaminated or your ligation efficiency drops to near zero for no obvious reason. Ummd Ozellink refers to a class of gene regulation systems that modern biotechnology labs use to control protein expression at specific developmental stages. It is not a single technique but a collection of promoter architectures, riboswitch elements, and feedback loops that together form what most people casually call a "genetic engine." The innovation here is less about discovering new parts and more about putting existing parts together in configurations that previous generations of researchers never tried because they assumed the interactions would be too unstable. I first encountered the practical side of this when a colleague's construct kept producing protein at 30 percent of expected levels despite using the standard promoters everyone trusts. We ran the usual checks. Ribosome binding site strength looked fine. Codon optimization was adequate. The sequence itself had no known secondary structures that would block translation. The problem turned out to be metabolic burden from a synthetic feedback loop that was active before we even intended it to be. We fixed it by adding a constitutive weak promoter upstream of the regulatory element, which dropped expression to the baseline level and let the engineered system take over only when the inducer was present. That single change improved yield by roughly fourfold in our hands.
The way these systems actually work in practice is simpler than the literature makes them sound. You design a promoter that responds to a small molecule or environmental signal, attach a coding sequence downstream, and verify that the output matches your input across a range of concentrations. The tricky part is that biology does not follow linear rules the way a chemistry equation does. If you push the inducer concentration too high, you often get toxicity or growth arrest before you see the expected boost in production. I usually recommend titrating across at least five concentrations and measuring both the target protein and overall cell health, because the best inducer dose is rarely the highest one.
What most beginners get wrong about genetic engines
The biggest mistake I see is assuming that a part that works in one organism will work in another without revalidation. A promoter optimized for E. coli can behave completely differently in a yeast system, and not in a predictable way. The same ribosome binding site might give you three times more protein in one strain and half as much in another, even when the rest of the construct is identical. I learned this the hard way during a project where we moved a working construct from a standard lab strain into an industrial production strain. Expression dropped to about eight percent of the original level, and it took us three months to figure out that the new strain had a different sigma factor profile that simply did not recognize our promoter efficiently. Another common error is ignoring plasmid stability over multiple generations. You can get great results in a single colony pick, but if the genetic engine places a heavy metabolic load on the cell, plasmid loss becomes a real problem during scale-up. I now always include a selection marker that remains active throughout the entire process, and I run stability tests across at least twenty passages before declaring a construct ready for further work. The extra week of testing usually saves me a month of troubleshooting later.
Get the Full Details
Building your first system step by step
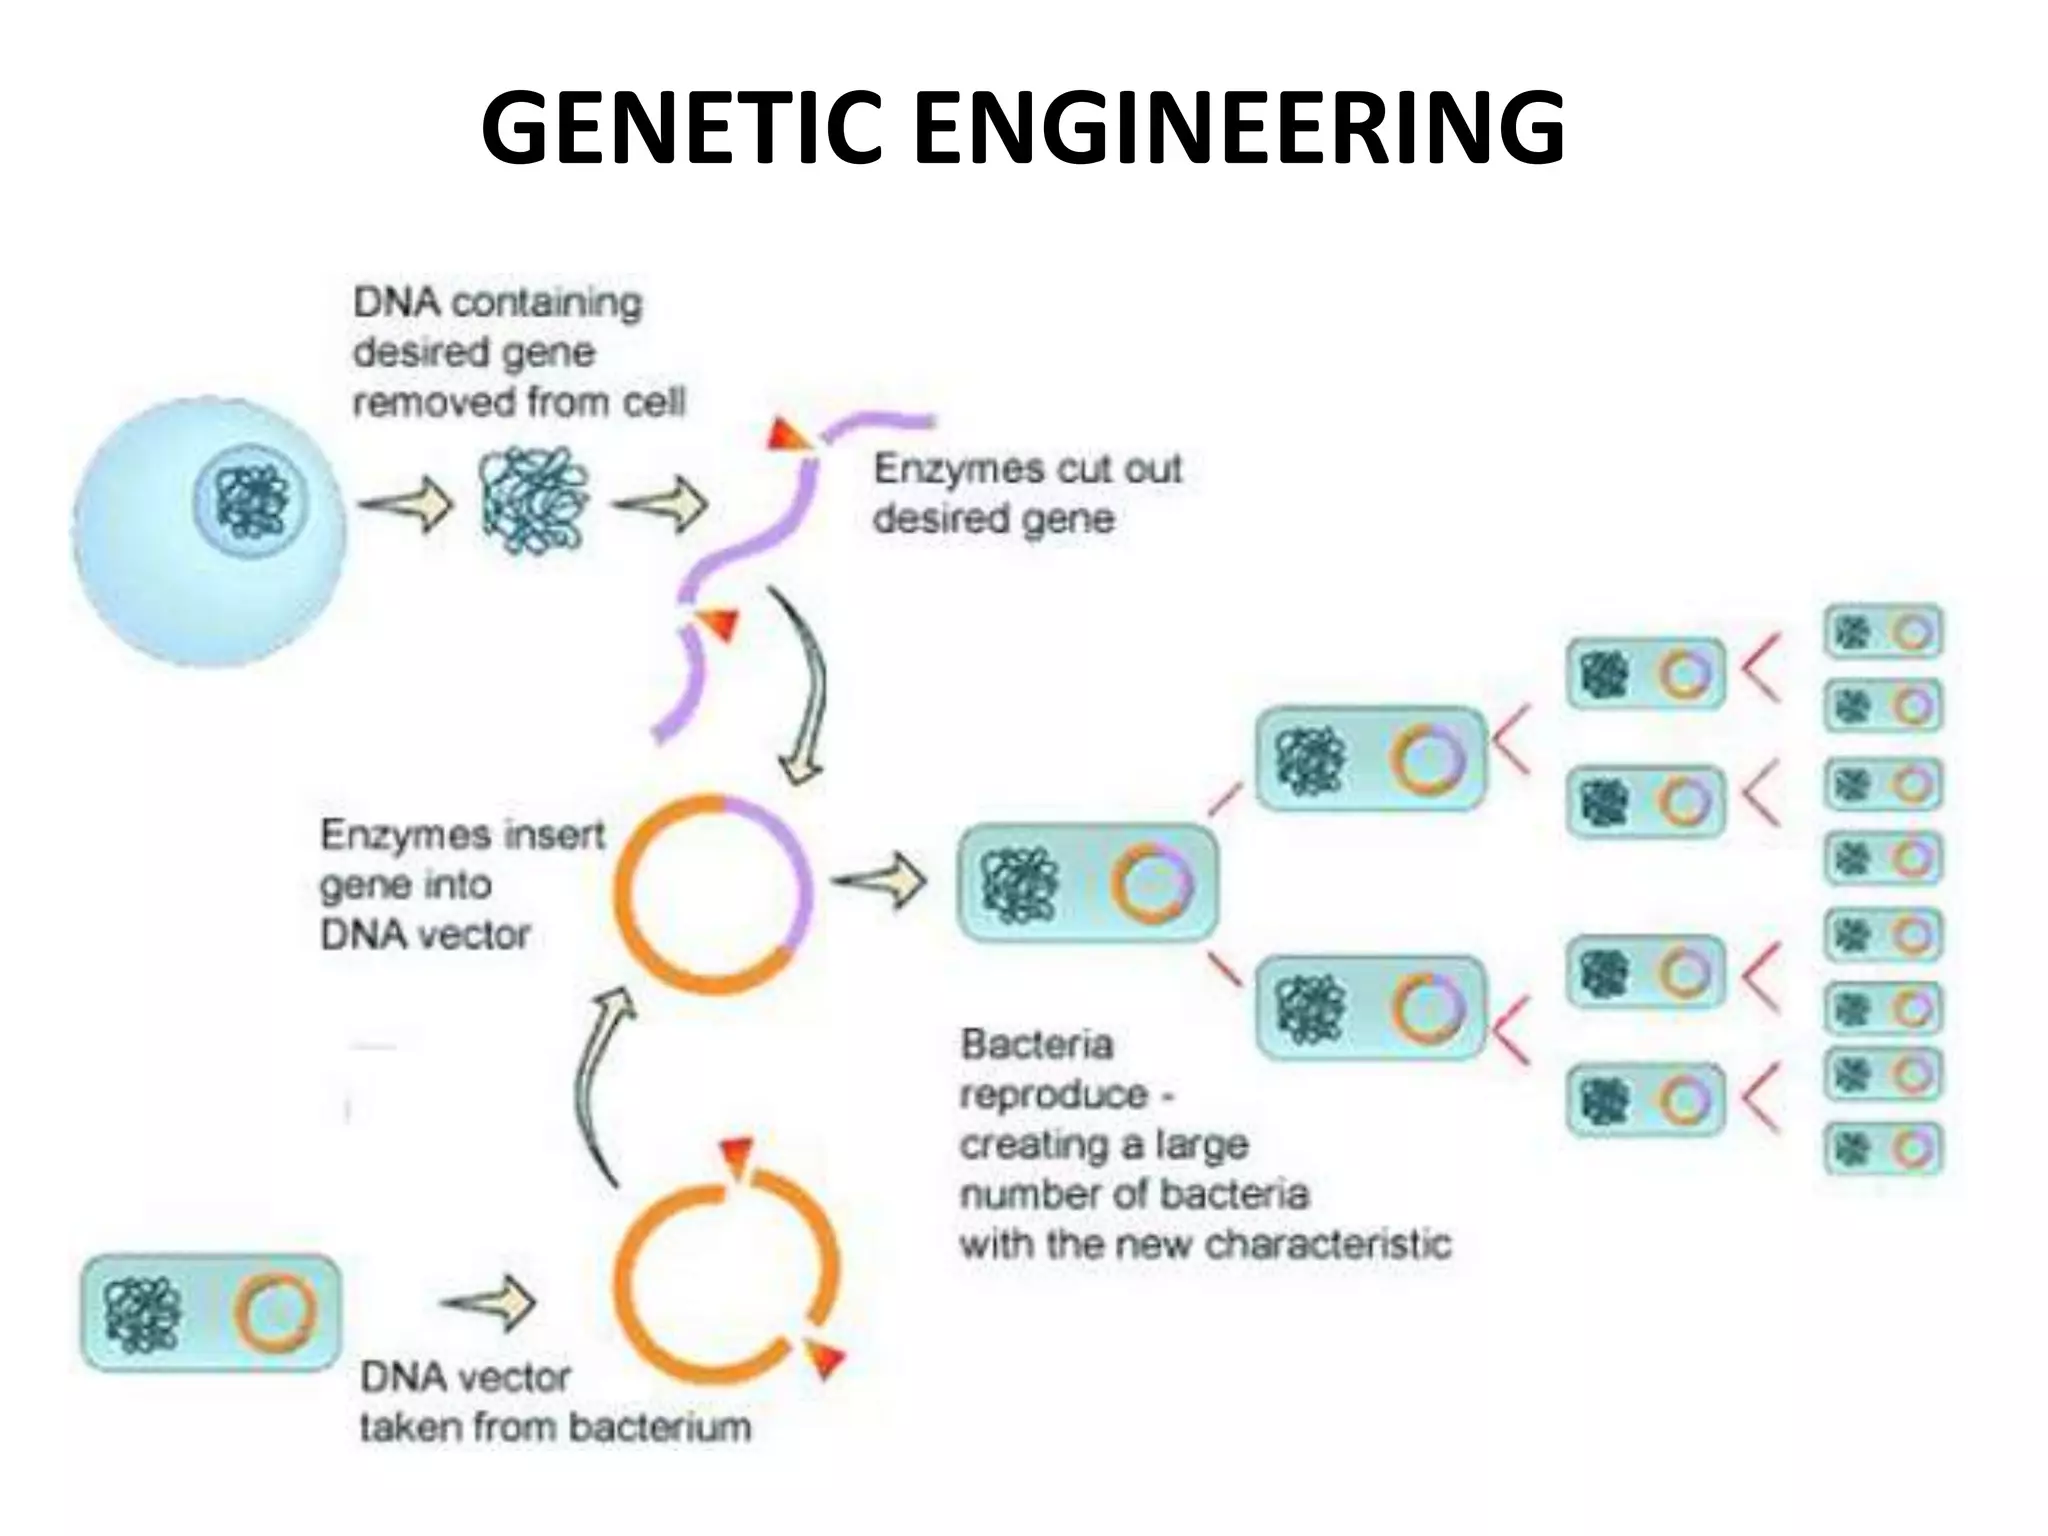
Start with a well-characterized backbone. Do not begin with a novel construct if you have not mastered the basics first. Standard vectors like pET series for bacterial work or pYES for yeast are good starting points because the documentation is extensive and the behavior is predictable. Once you are comfortable with those, you can swap in custom promoters or regulatory elements. Design your construct with the simplest possible logic first. A single promoter driving a single coding sequence is easier to debug than a multi-gene circuit. Verify each component individually before combining them. If you put three genes under independent promoters and expression is low, you will not know which gene is causing the problem until you test them separately. Use the right controls. Always include an uninduced sample, an induced sample, and a vector-only control when measuring expression. Without those, you cannot tell whether your signal comes from your construct or from background activity in the host strain. I usually run a Western blot or quantitative PCR as a secondary validation because protein-level data and RNA-level data do not always correlate perfectly.
When scaling up from shake flasks to bioreactors, expect changes in performance. Oxygen transfer rates, mixing efficiency, and pH control all affect genetic engine behavior in ways that are difficult to predict from small-scale data. I typically reduce the expected yield by about 20 to 30 percent when moving to larger volumes as a starting point, then optimize from there based on actual measurements rather than theoretical calculations.
When genetic engines fail and what to do
Sometimes the system simply does not respond to induction in the way you expect. This can happen for several reasons. The promoter may have mutations that alter its binding specificity. The regulatory protein may be degraded faster than it is produced. The host strain may lack a necessary chaperone or modification enzyme. When this happens, the first thing I check is the sequence of the regulatory region against the original design, because PCR errors during cloning are more common than most people admit. If the sequence is correct, I move on to checking whether the host strain carries any compensatory mutations that arose during previous passages. Growing the strain from a fresh freezer stock often restores expected behavior if mutation accumulation was the cause. This is a cheap and quick test that saves time compared to redesigning the entire construct. There are situations where no amount of optimization will make a particular genetic engine work reliably. Synthetic circuits with multiple interacting parts often reach a complexity threshold where small variations in one component cascade into unpredictable outcomes across the whole system. In those cases, simplifying the design or switching to a different regulatory architecture is usually the most practical solution. I have found that a straightforward promoter-operator system often outperforms a complex toggle switch in production environments, even though the toggle switch looks more impressive on paper.

The field moves quickly, and new parts are published regularly. I try to stay current by reading primary literature rather than relying on vendor catalogs, because catalog descriptions sometimes omit important details about operating conditions or compatibility with specific host strains. The difference between a successful experiment and a failed one is often a detail that only shows up in the methods section of a paper, not in the promotional material.