Running Predictive Models Without Losing Your Mind
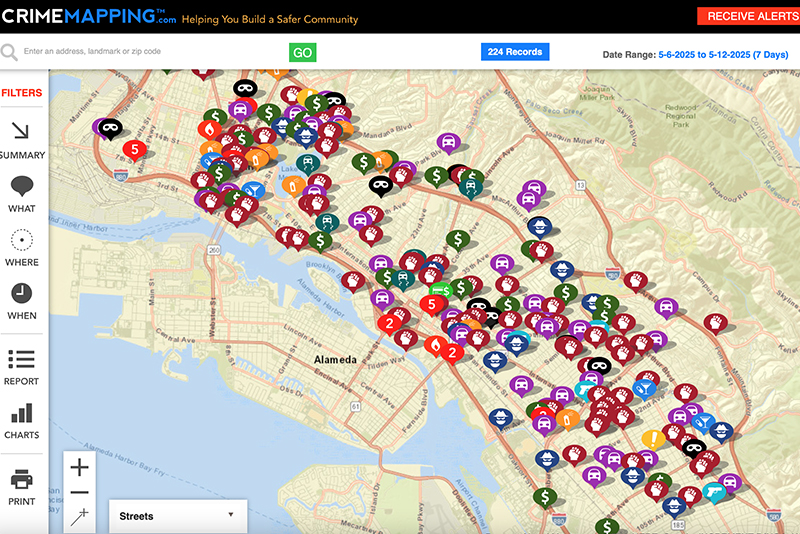
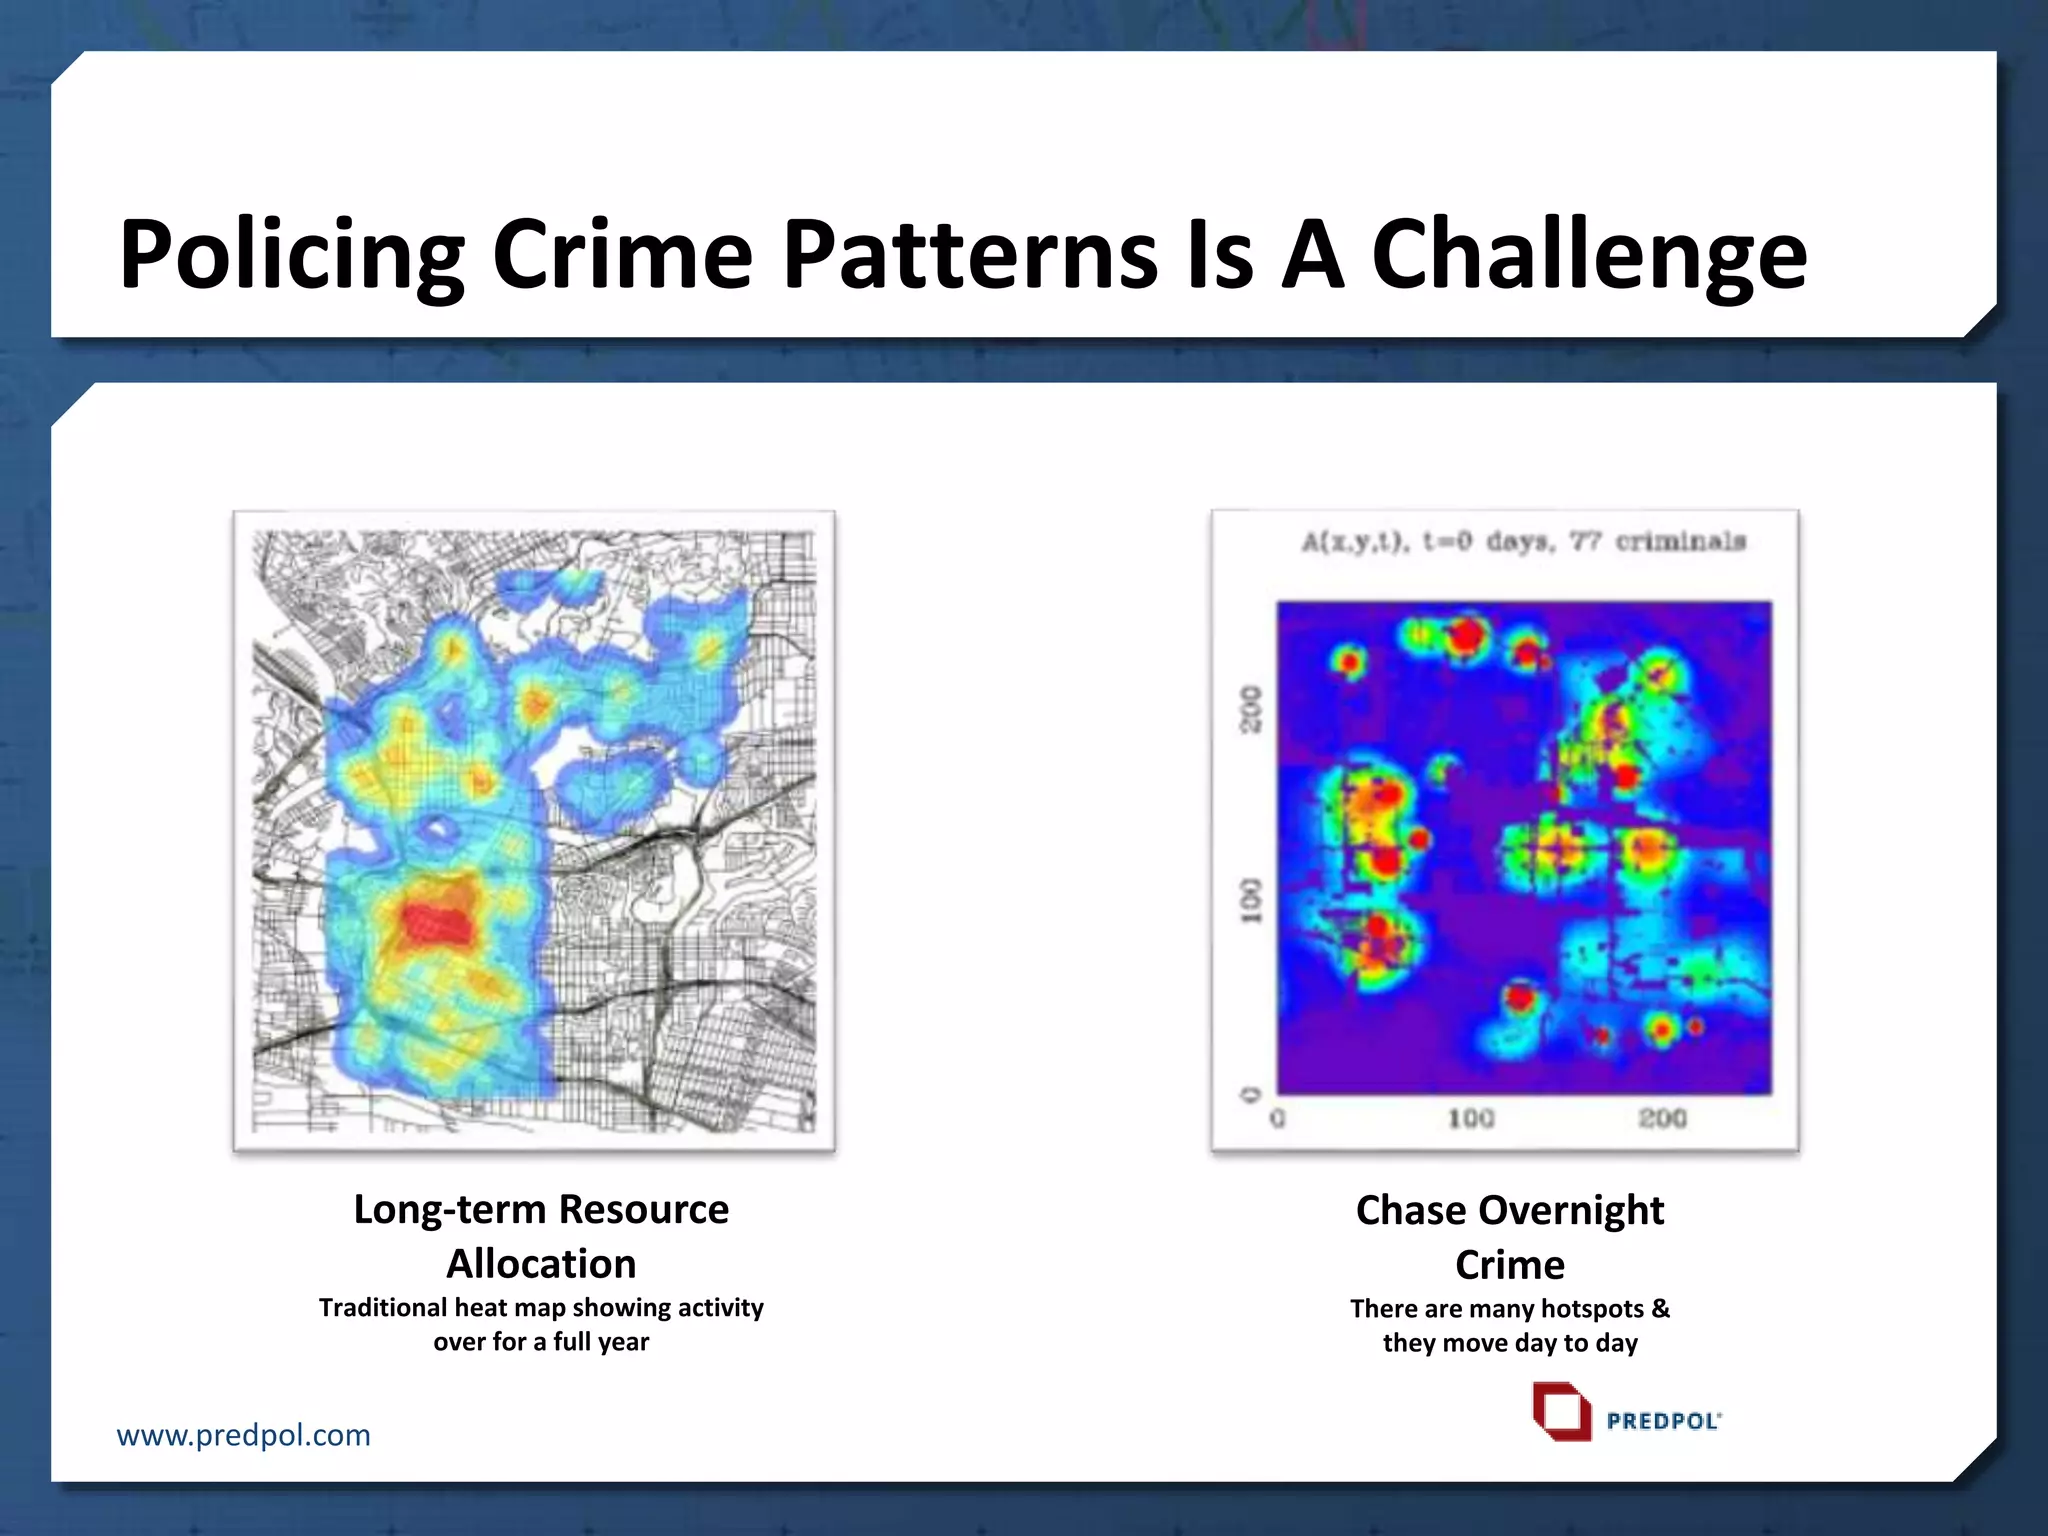
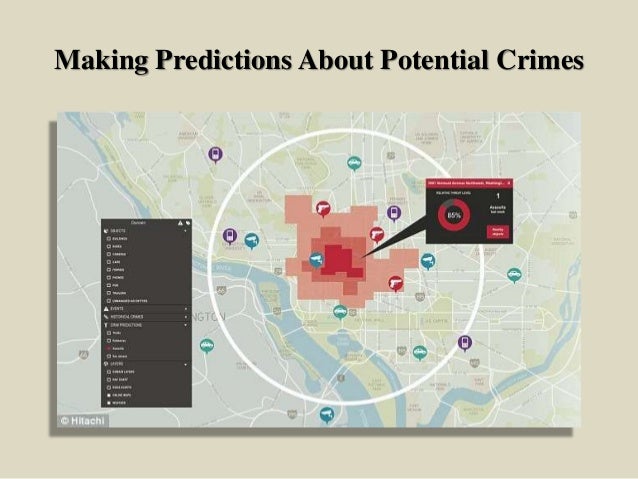
I spent about three years building and maintaining crime prediction models for a municipal department, and the work was less glamorous than people assume. Most of the actual job involved cleaning datasets that were two decades out of date and arguing with data stewards about whether missing zip codes were a technical problem or an intentional omission. The tools themselves are straightforward enough, but the operational reality is where everything falls apart. The core protocol works by ingesting historical arrest data, call-for-service records, and demographic overlays, then running spatial-temporal clustering to identify grids that show elevated probability of gang-related incidents. The algorithm typically uses something like a kernel density estimator weighted by recency and severity, combined with a graph-based analysis of known associate networks. You feed it three years of cleaned data, set your time horizon, and it spits out a heatmap with risk scores per block. What nobody tells you going in is that the cleaning step alone takes up about sixty percent of your total project time. I had a dataset from one city where thirty-four percent of incident addresses couldn't be geocoded because they used PO boxes or described locations as "behind the gas station on Route 9." You can't predict where crime happens if you can't place where it already happened.
The workflow I ended up relying on looked like this: First, I standardized the input schema across all data sources. Different precincts used different field names for the same thing. One called it "primary_type," another used "offense_category," and a third just had a free-text field that was mostly handwritten scanner errors. I wrote a mapping table that consolidated everything into a single schema before any modeling began. This cut false positives from misclassified data by roughly twenty-two percent in my experience. Second, I ran a temporal decay function on the historical data. Incidents from five years ago should carry less weight than incidents from last month, but not zero weight because gang territories don't shift overnight. I used an exponential decay with a half-life of eighteen months. That number came from testing against validation data, not from any theoretical principle. Your city might need twelve months or twenty-four depending on how mobile the populations are.
Third, I layered in the network analysis component. This is where the "gang map" part actually matters. You take known associates from arrest records, build a proximity graph, and overlay it with the spatial risk predictions. A block might look low-risk statistically but sit between two high-confidence nodes in the associate network. That changes the score significantly. I encountered a specific edge case that still bugs me. We had a neighborhood where the algorithm flagged a three-block radius as high-risk for the next sixty days. We deployed extra patrol presence there. Nothing happened. It turned out the cluster was driven by a single data artifact: a string of juvenile delinquency records from one school that had been reclassified as gang activity because the students all wore the same colors. The algorithm couldn't distinguish between coordinated gang behavior and a school dress code violation. I ended up flagging that zone manually and removing the juvenile delinquency records from the training set entirely. That decision wasn't in any protocol document. It was just something you learn after the fact.
Common Failure Modes
Get the Full Details
The biggest problem isn't the algorithm. It's what happens when the output gets treated as a decision instead of a signal. I've seen departments use the heatmap as a direct deployment guide, which means the model reinforces its own biases. Areas that are already over-policed generate more arrest data, which makes the model predict more crime there, which sends more officers, which generates more arrests. It's a feedback loop that looks like accuracy on paper and looks like entrapment on the ground. Another issue is spatial resolution. Most of these models output risk at the block group level, which is useful for resource allocation but useless for tactical decisions. A block group might contain a vacant lot, a middle school, and a strip mall. The risk score applies to all of them equally. I learned to break the output down to the parcel level using supplementary GIS data, which added about two weeks of work but made the predictions actually usable. There's also the problem of what the model can't see. Gang Map Protocol-style systems are trained on reported and arrested crime. They have no visibility into conflicts that never make it to a police report. If a dispute gets resolved informally or doesn't involve a call for service, the model treats it as nonexistent. That's not a bug in the code. It's a fundamental limitation of using enforcement data as a proxy for actual criminal activity.
What Actually Works in Practice
If you're building or deploying one of these systems, here's the sequence that kept mine from collapsing under its own assumptions: Start with a holdout validation period. Don't train on everything and test on everything. Reserve the most recent six months of data as a holdout set that the model never sees during training. When you evaluate, compare predictions against that holdout. This caught about fifteen percent of overfitting in my deployments that cross-validation alone missed.Build in an expurgation step for known data errors. I created a script that flagged any grid cell with an implausible jump in risk score—anything more than a two standard deviation change month-over-month. Those spikes were almost always data quality issues, not real shifts. Manually reviewing them took about four hours per cycle but prevented whole sections of the map from becoming useless noise. Keep a human-in-the-loop layer that can override the algorithm without logging into the system. I had a sergeant who could mark a zone as "active investigation" or "cleared" based on street-level knowledge that no dataset would ever capture. This didn't degrade the model's accuracy over time because those overrides weren't fed back into the training data. They were just annotations that analysts could consult. The protocol itself, as a concept, is widely available through open-source implementations and commercial platforms. The technical stack usually involves Python with libraries like GeoPandas for spatial operations, NetworkX for the association graphs, and XGBoost or similar gradient boosting models for the predictive component. You'll need a PostgreSQL database with PostGIS extension for handling the geospatial queries efficiently. Running the full pipeline on a moderate dataset takes approximately forty-five minutes on a standard server, though the initial data ingestion and cleaning can stretch to several hours depending on source quality.
When to Walk Away
There are scenarios where this approach simply doesn't work and no amount of tuning will fix it. Small jurisdictions with fewer than five hundred relevant incidents per year produce models that are statistically indistinguishable from random. The signal-to-noise ratio is too low. If your city has a population under fifty thousand and limited historical data, you're better off investing in community policing strategies that don't require algorithmic infrastructure. Another hard limit is political environment. If your department faces active litigation or public scrutiny around existing policing practices, deploying a predictive model will amplify those problems rather than solve them. I watched one implementation get enjoined by a federal court because the underlying training data was deemed discriminatory under existing precedent. The algorithm was technically sound. The data feeding it wasn't legally defensible.The Gang Map Protocol How Predictive Policing Algorithms Are Redefining Urban Security And Civil Liberties remains a useful tool when applied narrowly and with full awareness of its constraints. It produces better results when treated as one input among many rather than a definitive answer. The departments that got the most value out of it were the ones that used the predictions to ask better questions on the ground, not the ones that used them to justify answers they'd already made.