YouTube API Quota System — How It Actually Works
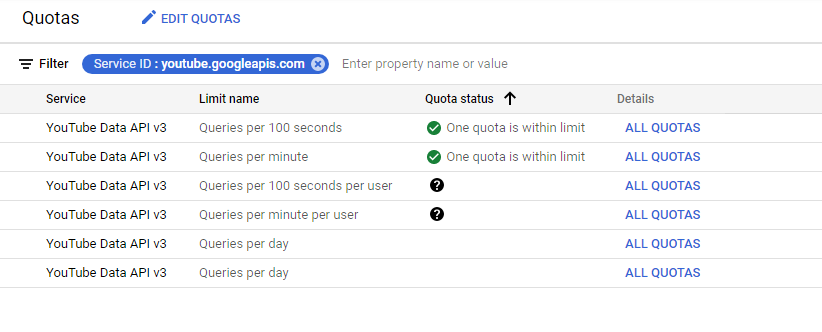
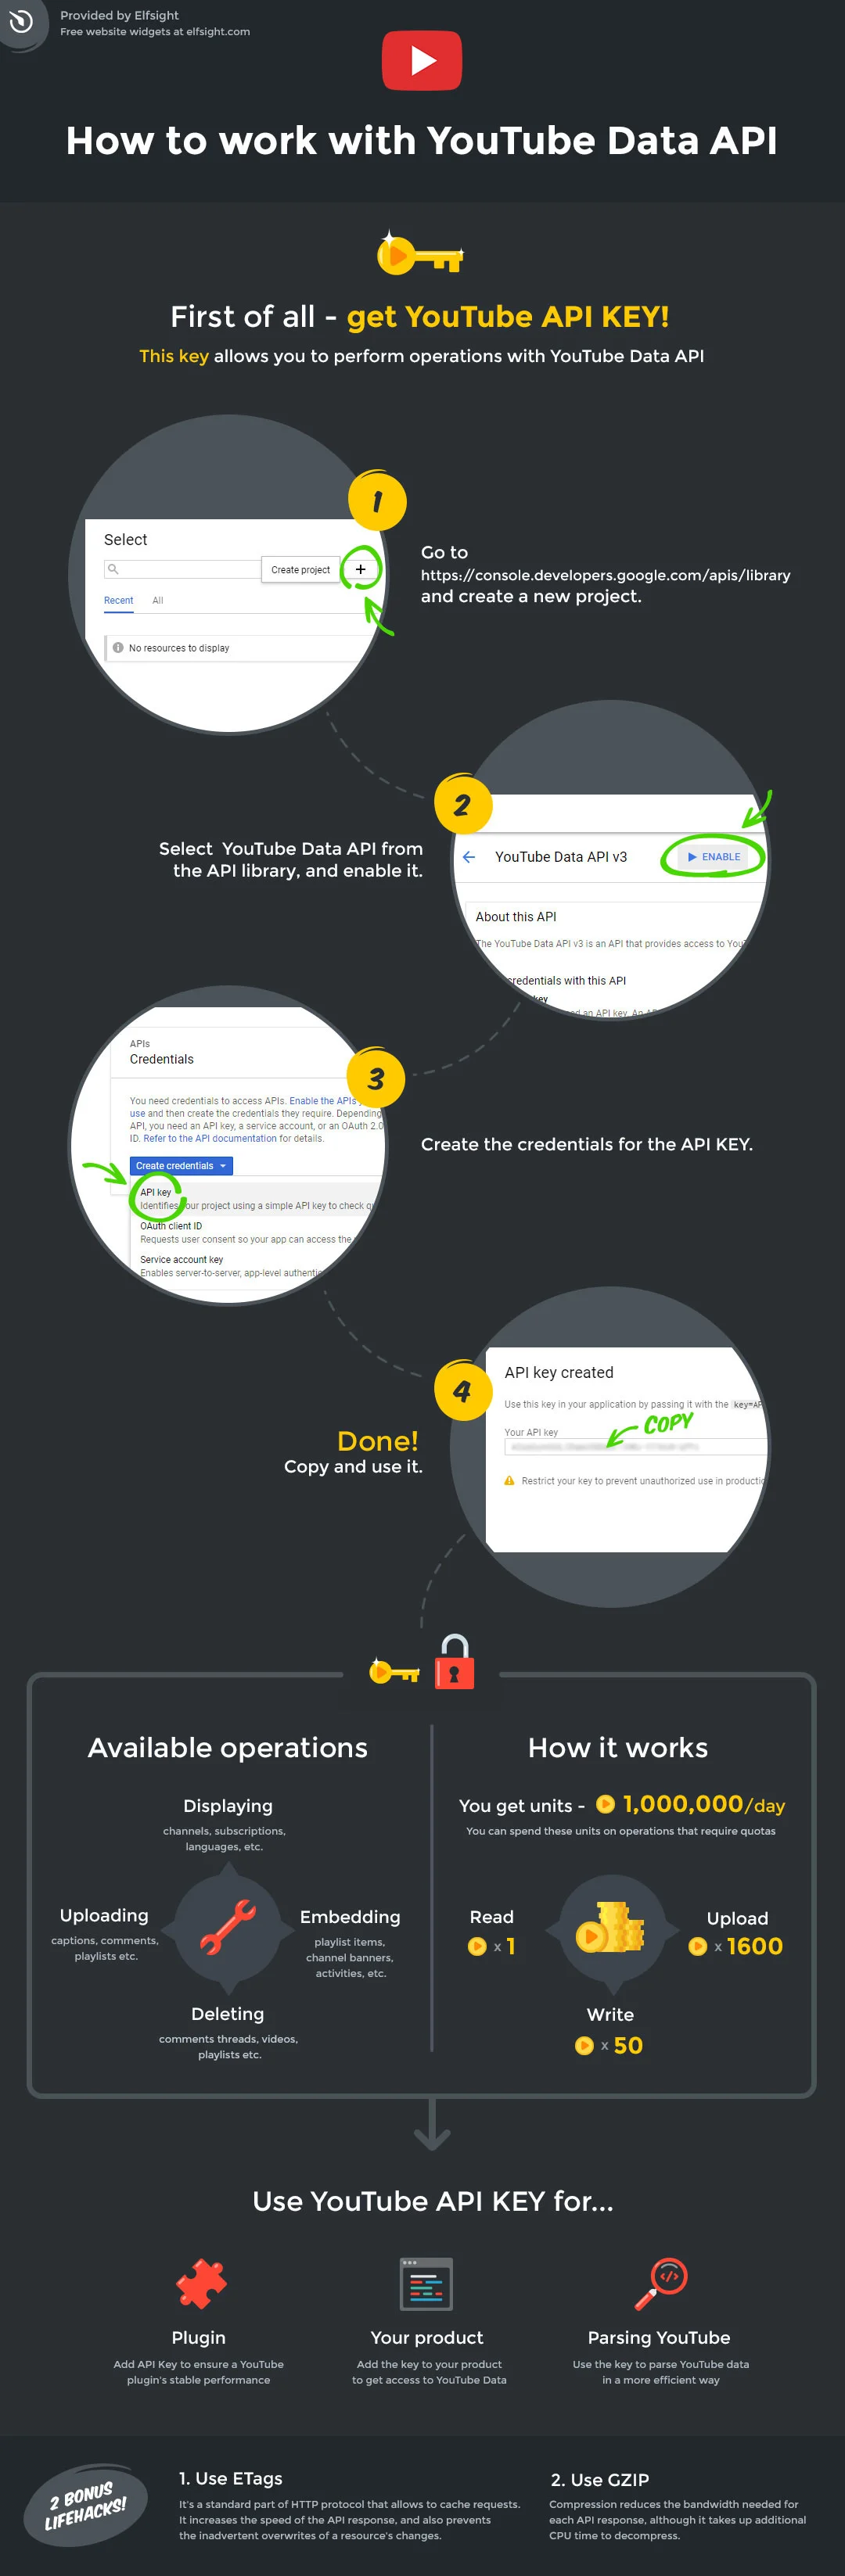
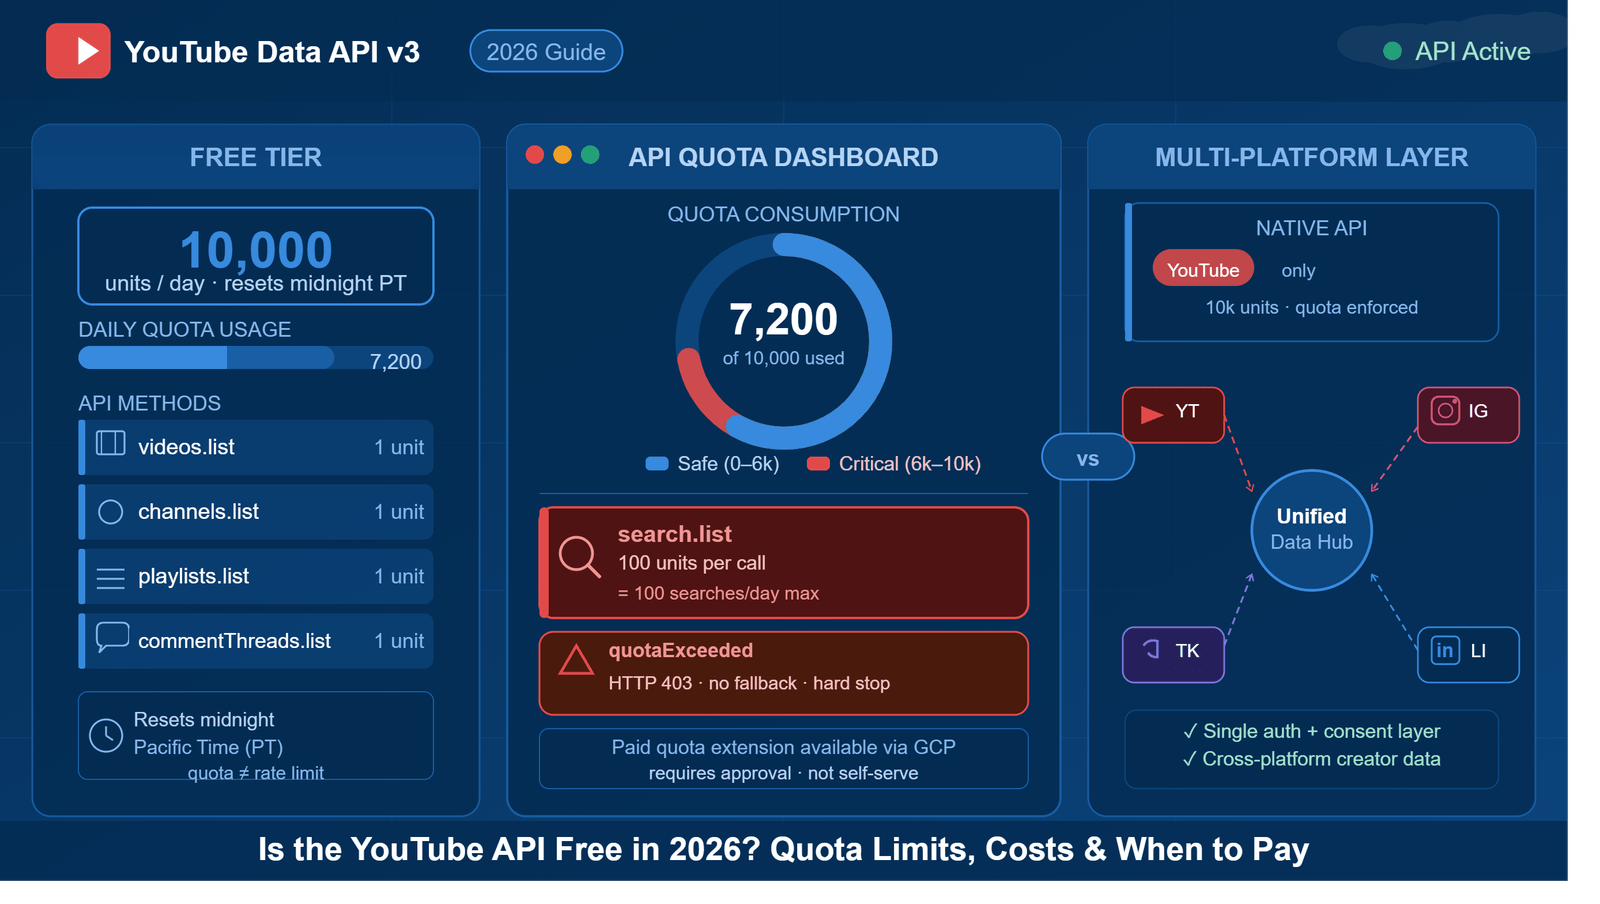
The YouTube Data API v3 charges quota based on operations, not bandwidth or requests. A single search query costs 100 quota units. Listing your own channel uploads costs just 1. Reading comments on your own videos costs 1. The asymmetry is brutal if you are not tracking which endpoint you call and for what purpose. I learned that the hard way when a simple polling script burned through 50,000 quota in two hours because I was using search instead of playlistItems. Quota resets at midnight UTC, not your local timezone. You get a daily budget that you can set in the Google Cloud Console, but there is no hourly cap by default. Once you hit your limit, every subsequent API call returns a 403 with a quota error until the next UTC day. There is no throttling delay. It is a hard wall.The Future Of YouTube API Key Quota Maximize Your Usage
Maximizing your YouTube API quota usage comes down to two things: choosing the right endpoints and batching requests whenever the API supports it. Most developers underestimate how much quota a single page of results consumes. A search.list call with a page size of 50 still costs 100 quota regardless. Pulling the next page with search.list.pageToken costs another 100. That is where people lose control of their budget. The most underrated optimization is using the part parameter effectively. When you call videos.list, you can request only the parts you need. If you only want view counts and titles, passing part=snippet,statistics is identical in quota cost to requesting every available part. But some endpoints charge differently based on part combinations, and the documentation rarely spells that out clearly. The stats part on videos.list adds a small overhead compared to snippet alone, but on channels.list, the statusPrivacy part is free to include alongside snippet. Batching is another area where developers get tripped up. The YouTube API supports batching up to 100 requests in a single HTTP call, and the quota charge applies to each individual request inside the batch, not the wrapper. So if you need to fetch details for 50 videos, sending 50 separate requests costs 50 × the per-video quota. Sending them as one batch with 50 inner requests costs exactly the same total quota but saves you from making 50 round trips. The time savings are significant, but the quota impact is neutral. Batch for speed, not for quota savings.
Endpoints Ranked by Quota Cost
Here is the practical ranking I use when designing a data pipeline. Search operations are the most expensive by far. Each search.list call is 100 quota. A single keyword search returns a page of results, and you pay 100 per page. If your application needs to monitor trending videos across multiple regions, that adds up fast. I once built a trending tracker for three regions and burned 3,000 quota per hour during peak hours just on the search calls. Playlist operations are relatively cheap. playlistItems.list costs 1 quota per call regardless of page size. You can fetch an entire playlist's worth of video IDs for a single quota point. This is the backbone of any efficient video monitoring system. Instead of searching for videos by keyword repeatedly, load a playlist once and track changes to its items. The quota delta between a search-based approach and a playlist-based approach can be 100x or more over a day. Channel and video metadata calls sit in the middle tier. channels.list and videos.list each cost 1 quota per call with a default page size of 5. Requesting 50 items on a single call still costs 1 quota. The page size parameter does not affect quota, which surprises most people. You only pay more when you make additional calls, not when you request larger pages.
My Specific Edge Case — Comment Monitoring
I encountered a particularly nasty problem when building a comment moderation system. The comments.list endpoint costs 1 quota per call, which sounds reasonable until you realize that top-level comments and replies are returned in the same response body. To get reply threads, you have to make a separate API call for each comment's reply tree. A single video with 200 comments and an average of 5 replies per comment generates roughly 200 + 200 = 400 API calls if you fetch everything separately. At 1 quota each, that is 400 quota just to read one video's comments. The workaround I landed on was to only fetch comments for videos that I already knew had new activity, rather than scanning all videos in a playlist. I used a combination of the subscriptions.list endpoint to get uploaded video IDs and then checked only those for comment changes. This reduced my comment monitoring quota from an estimated 5,000 per day down to about 800, depending on how many videos my users actually uploaded. The tradeoff is that I missed comments on videos I was not actively tracking, but for a moderation system that priority did not matter as much as budget.
Get the Full Details
Counter-Intuitive Insights Beginners Miss
Most people think that reusing the same API key across multiple projects saves quota. It does not. Quota is charged per project, not per key. If you have three Google Cloud projects using the same YouTube API key, each project sees the full quota consumption independently. I discovered this when my staging environment suddenly hit quota limits while my production environment had plenty of budget remaining. Moving the API key to a dedicated project per environment fixed the confusion but required updating credentials everywhere. Another common mistake is using the mine=true parameter liberally. The mine parameter filters results to the authenticated user's own data, but it requires the OAuth scope https://www.googleapis.com/auth/youtube.readonly. If your application already has that scope for other reasons, mine is free and efficient. But adding the scope solely to use mine is unnecessary bloat. The quota cost difference between search.list(q="keyword") and search.list(mine=true) is identical, but the latter requires a scope the developer may not have thought about. The third insight is about the publishedAfter and publishedBefore filters. Many developers paginate through results chronologically using pageToken, which costs 100 quota per page on search endpoints. Using publishedAfter to narrow the date range to the last 24 hours can reduce a search from potentially hundreds of pages to just one or two. The quota impact on a search that would have cost 5,000 drops to 100 or 200. This is not obvious from the endpoint documentation, but it is one of the highest-impact optimizations available.
When This Approach Fails Completely
Quota optimization has hard limits. If your use case genuinely requires bulk searches across millions of keywords, no amount of endpoint tweaking will keep you under a reasonable budget. I worked with a team that needed to track hashtag performance across 10,000 tags daily. Their search-based approach would have consumed approximately 1,000,000 quota per day. Even with publishedAfter filters and playlist substitution, they could not reduce it below 50,000. They eventually moved to a third-party analytics provider that had different pricing and accepted the cost as a line item. Another scenario where quota maximization breaks down is real-time streaming data. The YouTube Live Streaming API has its own quota structure that does not follow the standard Data API rules. Broadcast lifecycle operations, liveStream.bind, and streamingMetrics.list each have their own cost models. If your application manages live streams, you need to read the separate liveStreamingQuota documentation, which is entirely independent from the Data API quota reference.
Practical Daily Budget Management
Setting a daily quota budget in the Google Cloud Console is straightforward but often insufficient on its own. The console limit stops new requests at midnight UTC, but it does not alert you before you hit the wall. I recommend setting the budget at 80% of your actual expected daily usage and using the API's quota headers to build internal monitoring. Every YouTube API response includes a X-Server-Response-Time header and a quota usage indicator in the JSON body when you request prettyPrint=true. The prettyPrint parameter adds no quota cost and returns the full response with metadata. Parsing the response body for quota information lets you track consumption in real time without additional API calls. I built a simple logger that records the quota field from each response and raises an alert when daily consumption reaches 70% of the project budget. This gave us about 48 hours of warning before any potential cutoff, which was enough time to adjust polling frequencies or switch to cached data. If you are building for production, consider splitting your workloads across multiple projects. Project A handles search-heavy operations with a generous daily budget. Project B handles lightweight metadata fetching with a smaller budget. Project C handles live stream management with its own quota pool. This approach prevents a single spike in one area from taking down the entire system. I have seen teams lose access to their comment monitoring because a trending video search exhausted the only project's quota. Two projects would have prevented that entirely.
Alternative: Cached Data with Periodic Refresh
For applications that do not need real-time accuracy, caching API responses locally eliminates the majority of quota costs. Store the response body for each endpoint call and invalidate based on a TTL. A playlistItems.list response for a static playlist can be cached for hours with no quality loss. A search.list response for a popular keyword changes frequently and should have a shorter TTL, maybe 15 minutes during peak hours. The exact TTL depends on your use case. I found that a 10-minute cache for comment data was acceptable for a community management tool, reducing my daily quota from roughly 12,000 to about 2,000. For a news aggregation site, even 10 minutes was too slow, and I had to accept the higher quota cost as the price of freshness. There is no universal answer, but the cache-first approach almost always wins on budget unless real-time data is a hard requirement.