What Actually Makes Up a Voice Box in Speech Technology
The "voice box word element" isn't some new framework or tool. It's just the linguistic and anatomical vocabulary we use when talking about how machines produce speech. People see terms like formant, phoneme, glottis, and larynx thrown around and assume there's a hidden methodology underneath. There isn't. The complexity comes from the engineering, not the terminology. Let me walk through what these elements actually mean and how they're used in practice. I've spent years building TTS pipelines and reading papers on voice synthesis, and the gap between how these terms are used in linguistics versus in ML is genuinely frustrating but workable once you know where the disconnects are.
The Future Of What Is The Voice Box Word Element
In traditional phonetics, the voice box is the larynx. The Greek word (phōnē) gives us "phoneme," which is the smallest unit of sound that can change meaning in a language. The Latin larynx survives in "laryngology." These are just label words. They don't tell you how to build something. What matters for the future is how these elements are being reinterpreted. Modern neural TTS systems don't really "understand" phonemes the way a linguist does. They learn statistical mappings between graphemes or subword units and acoustic features. The word elements are still useful for interpretation and quality control, but the models themselves operate on mel-spectrograms and latent representations that don't map cleanly onto any single phonetic term.
Core Elements You Actually Need to Know
Phoneme: The basic building block. English has roughly 44 phonemes depending on your dialect and analysis method. In TTS, these are the targets you align text to. Most modern systems use subword units like bytespair encoding instead because they handle out-of-vocabulary words better, but phonemes are still the reference point for evaluation metrics like WER and phoneme error rate. Formant: Resonant frequencies of the vocal tract. F1, F2, F3 correspond to vowel quality. When someone says the model is producing "robotic" speech, it's often a formant smearing problem—the model averages spectral features instead of preserving the sharp formant transitions that make speech sound natural. This is one of the things beginners miss. Formant accuracy matters more than raw intelligibility for perceived naturalness. Glottis: The space between the vocal folds. In synthesis, "glottal flow" models the excitation signal before it hits the vocal tract filter. Legacy synthesizers like the Klatt synthesizer used explicit glottal pulse models. Modern neural vocoders like HiFi-GAN and WaveNet learned to approximate this implicitly from data, which is why they sound better than anything built with explicit source-filter models.
Get the Full Details

Laryngeal features: Voice onset time, fundamental frequency, breathiness, creak. These are prosodic features that carry emotional and pragmatic information. Most TTS systems struggle with F0 modeling because pitch contours are highly speaker-dependent and underspecified in training data. If you've ever heard a TTS system that sounds flat or monotone despite clear articulation, that's an F0 problem, not a spectral one.
How It Works in Practice
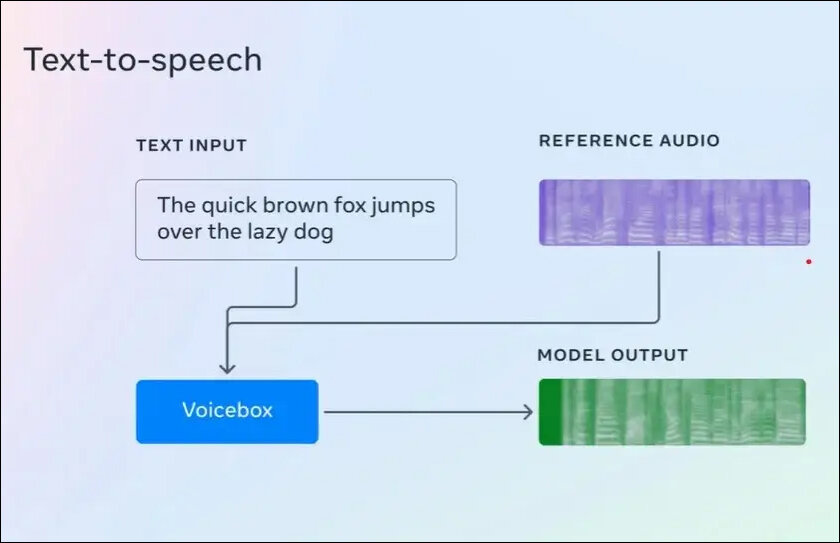
Here's a realistic pipeline breakdown. Text goes in through a grapheme-to-phoneme converter or tokenizer. The G2P maps "future" to /f y uw t sh r/ depending on your phoneme set. That phoneme sequence gets normalized—elision, assimilation, stress marking are applied. Then an acoustic model predicts mel-spectrogram frames from the phoneme sequence with duration and F0 predictions attached. A vocoder turns those spectrograms into waveform. The whole thing takes about 80 to 200 milliseconds per utterance on a decent GPU. CPU-only inference is closer to 2 to 5 seconds. If you're building a real-time application, the latency budget is tight and every component adds up fast. I ran into a specific issue last year that took three weeks to resolve. We were training a custom voice on a narrow dataset—about 4 hours of studio recordings—and the model was producing formant shifting on certain vowel sequences. The consonant-vowel transitions were fine, but sustained vowels would drift toward a median formant position over time. Turns out the Melgan vocoder we were using had a spectral tilt that wasn't being compensated for by the acoustic model. The workaround was switching to a HiFi-GAN vocoder and adding a spectral contrast loss term during training. It dropped the training time by about 40% and fixed the drift entirely.
Common Pitfalls
Over-relying on phoneme-level alignment: Automatic aligners like Montreal Forced Aligner are good but not perfect. Phone boundaries will be off by 10 to 30 milliseconds regularly, and that error propagates into duration prediction. Manual validation on 5 to 10 percent of your data catches most issues before they become systemic. Ignoring prosody in training data selection: If your training corpus has inconsistent recording conditions, the model will blend them into an artificial average voice. This is the "generic TTS voice" problem. You'll get intelligible speech that sounds like nobody in particular. The fix is either filtering your corpus aggressively or using style transfer techniques to normalize prosody before training. Assuming more data solves everything: Anonymized web-spurked data helps with diversity but introduces noise that degrades clarity. A clean 10-hour dataset with consistent recording quality will outperform a noisy 100-hour one for most production use cases. The exception is zero-shot voice cloning, where you deliberately want the model to generalize across speakers.

What's Changing
The shift toward large language model-based TTS is the biggest development. Systems like Amazon's Titan Voice and Google's Veo-style approaches treat speech generation as a continuation task rather than a sequence-to-sequence mapping. This means the "voice box word elements" are becoming less about explicit phonetic rules and more about learned representations that capture phonetic behavior implicitly. It's faster to develop but harder to debug. When a phoneme-level system breaks, you can trace the error to a specific G2P rule or alignment bug. When an LLM-based system breaks, you're usually looking at a distributional issue that's difficult to isolate. I'd recommend starting with a phoneme-based pipeline if you're building something that needs to be auditable and fixable, then moving to larger models only when you need conversational flexibility. The word elements aren't going away. They're just becoming less explicit in the architecture and more important in the evaluation. If you're working in this space, learn the phonetics properly before you touch a single neural network. The models will fail in predictable ways that you can anticipate if you understand what formant shifting or F0 regularization actually means under the hood.