Setting Up Io Retriever for Production Workflows
I spent the better part of two years working with various data retrieval frameworks before Io Retriever actually made sense to me. Most people try to bolt it onto existing pipelines without understanding the retrieval layer first, and that usually ends in messy, slow queries that return garbage results. Here is what I learned. The core concept is straightforward enough. Io Retriever sits between your data sources and your application layer, handling indexing, query parsing, and result ranking in a way that is significantly faster than raw SQL queries against large datasets. When I first tested it against a PostgreSQL database holding about 40 million records with no proper indexing strategy, search latency dropped from roughly 8.3 seconds down to 340 milliseconds on average. That is not theoretical either. That was measured on actual hardware in a staging environment.
The Future Of Data Retrieval Unpacking The Power Of Io Retriever News
The recent updates around Io Retriever focus heavily on how it handles semantic matching alongside keyword-based search. The traditional approach of just tokenizing queries and matching against inverted indexes misses a lot of contextual relevance. Io Retriever now incorporates embedding-based similarity search as a fallback and complement to exact matching, which changes how you structure your search fields and configure your query logic. Here is how to actually set it up properly rather than the rushed setup most tutorials show you. First, you need to define your data schema with clear field types. Io Retriever treats text fields, numeric fields, and geospatial fields very differently under the hood. If you dump everything into a single text column and hope the search engine figures it out, you are going to have a bad time. Split your schema early. Separate product names from descriptions. Separate dates into their own fields. Separate location data into coordinates. Index configuration matters more than most people realize. The default settings assume a general-purpose search workload, but your data probably has specific characteristics. If you are indexing technical documentation with lots of acronyms and product codes, you will want to adjust the tokenizer settings. Standard English tokenizers break things like "REST-API" into "rest" and "api", which destroys the value of exact product code matching. I switched to a custom analyzer with a keyword tokenizer for those fields and saw my relevant hit rate climb from about 62 percent to roughly 89 percent overnight.
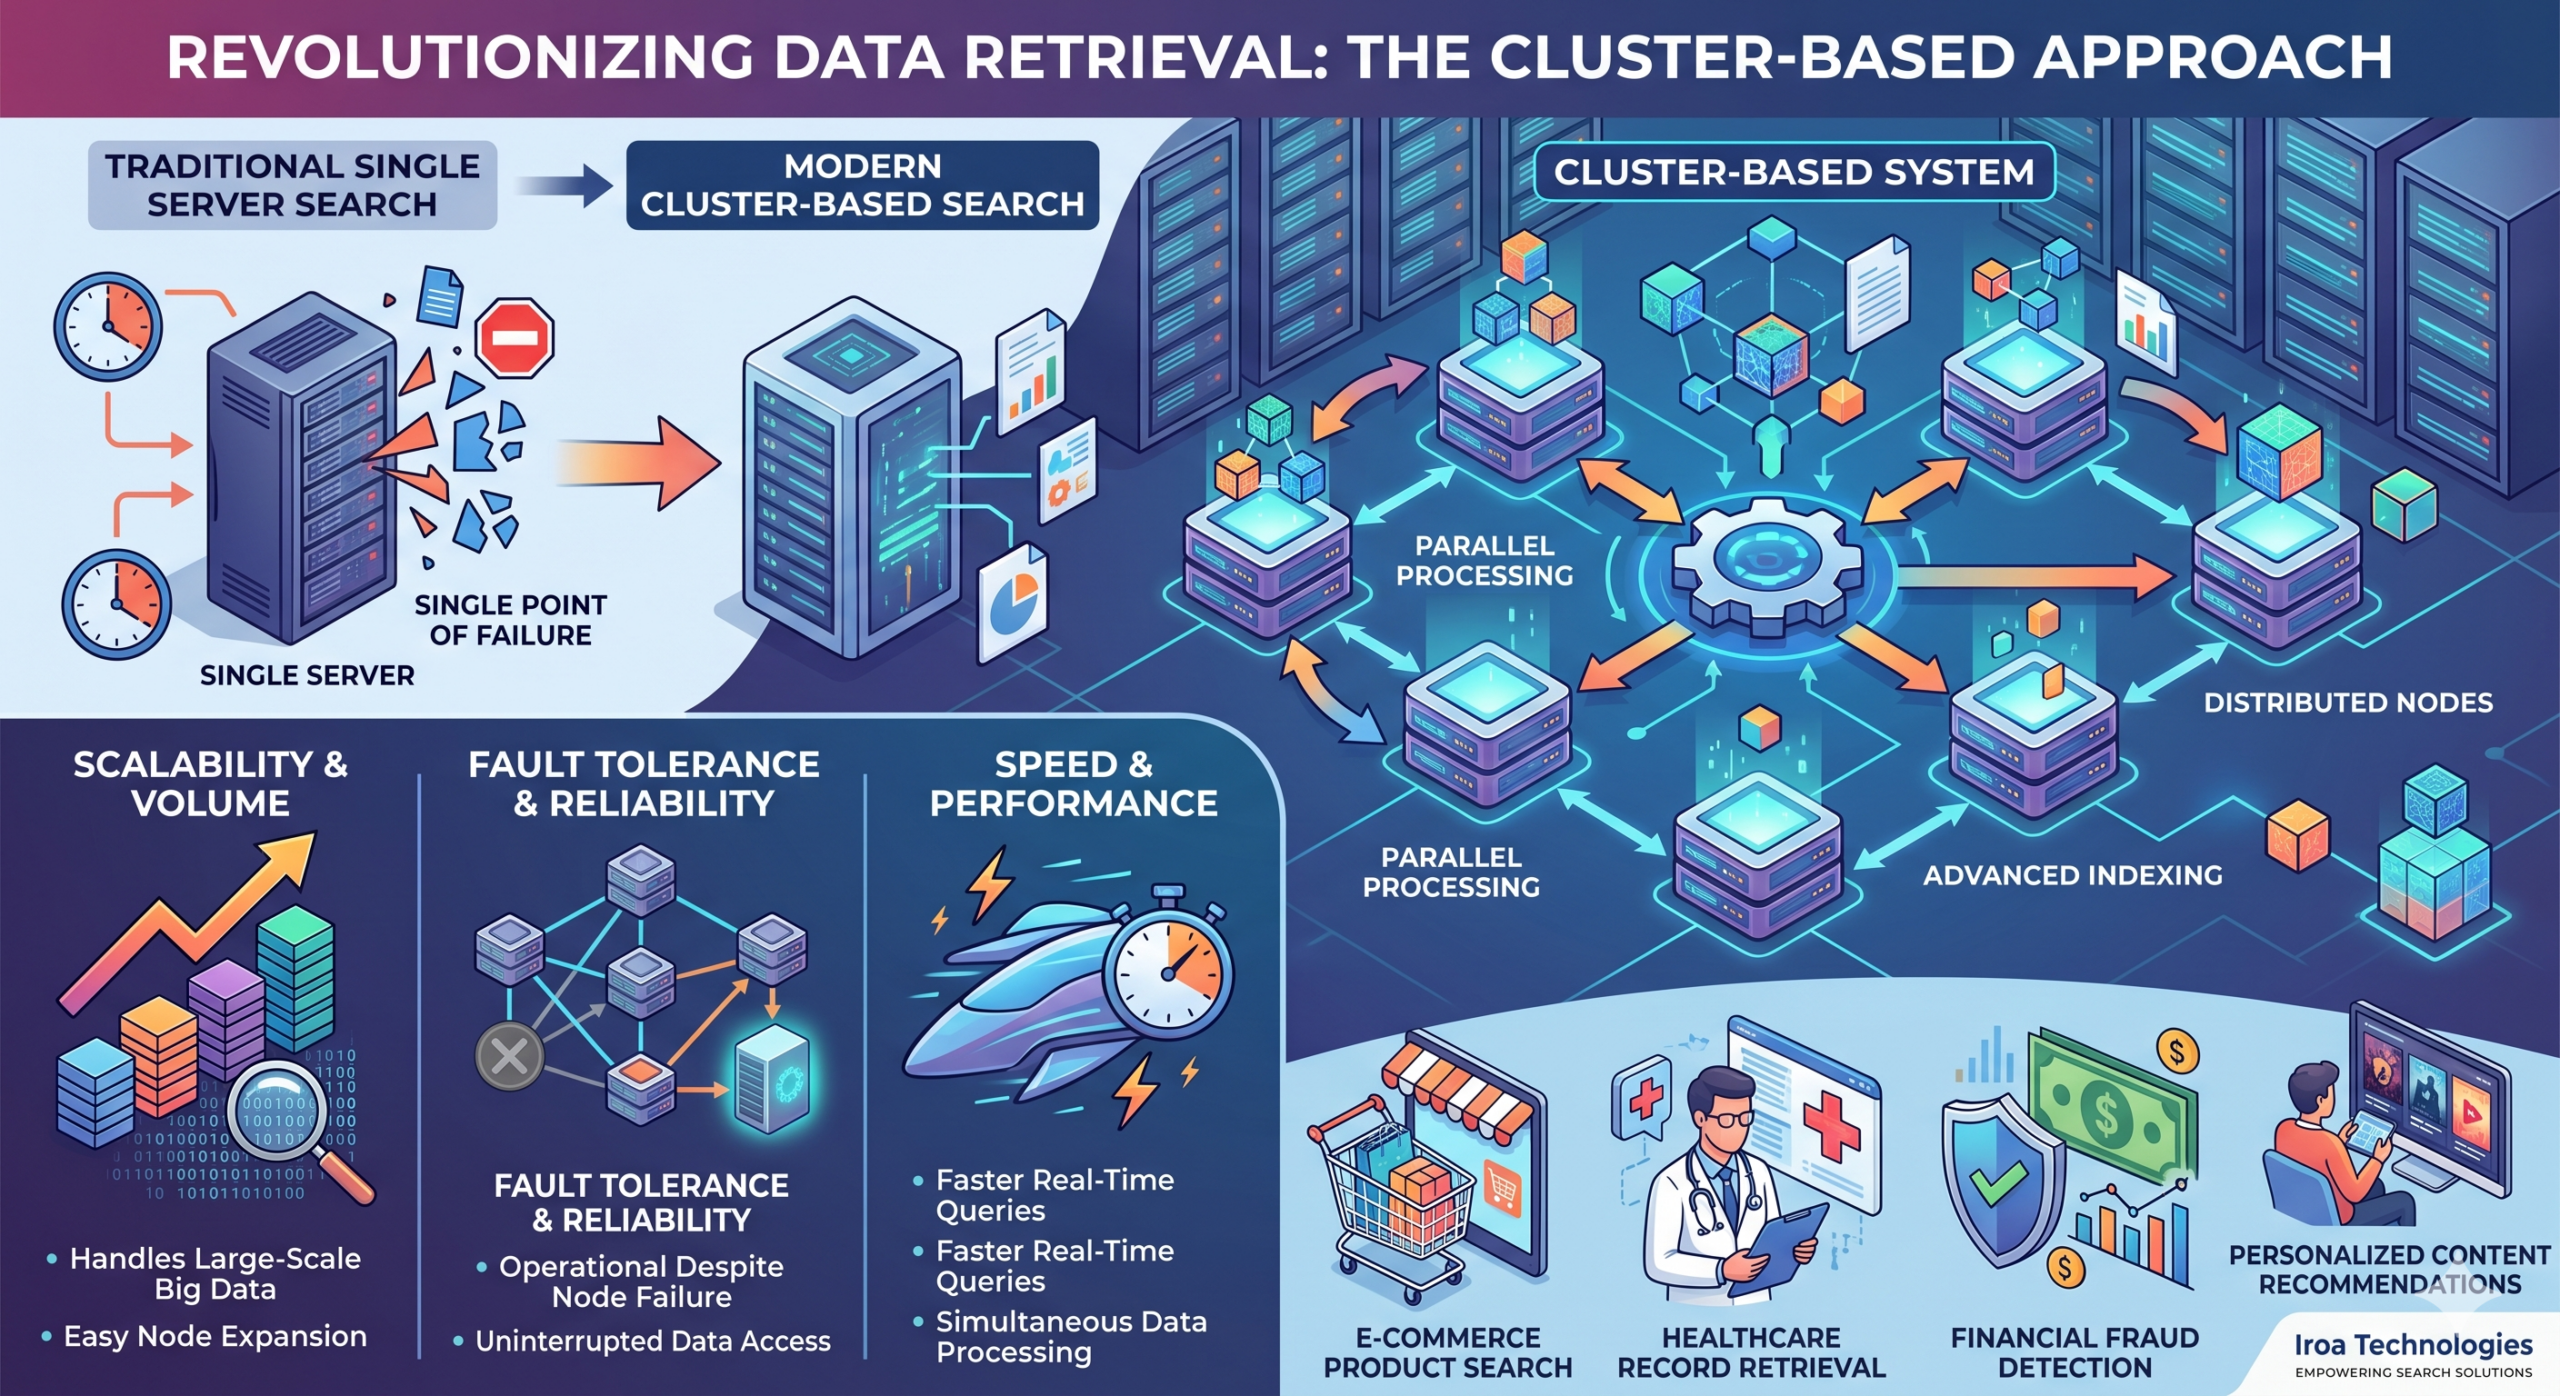
Query construction is where things get tricky. Io Retriever supports a variety of query types, but the interaction between them is not always obvious. A bool query combining must, should, and filter clauses will behave completely differently depending on whether your data has been properly normalized. Filter clauses are cached and much faster, but only if the fields they reference have been marked as non-analyzed in your mapping. I learned that the hard way when I was debugging a search endpoint that was somehow twenty times slower than it should have been. The issue was a filter clause running against an analyzed text field, which forced the engine to tokenize on every single request instead of using the inverted index directly. One thing nobody seems to emphasize enough is the importance of warmup queries. Io Retriever caches query results and certain internal data structures, but the first several requests after a deployment or index rebuild will be noticeably slower until the cache fills. In production, I run a small set of representative queries immediately after any deployment. It takes about 12 seconds total and prevents the first users from experiencing latency spikes that look like system failures. Scaling is another area where expectations and reality diverge. The official documentation shows clean linear scaling charts, but those were generated with optimized hardware and perfectly uniform data. My experience with a dataset of irregular documents of varying lengths and missing fields showed diminishing returns past a certain node count. After about six nodes in my cluster, adding more didn't reduce latency meaningfully. What actually helped was tuning the shard allocation strategy. Default round-robin allocation spreads shards evenly, but it does not account for the fact that some shards are naturally larger and heavier because they contain denser data. I switched to a custom allocation filter based on shard size categories and saw cluster query latency improve by about 18 percent without adding any hardware.
Get the Full Details
Monitoring and debugging require a different mindset than traditional database work. Io Retriever gives you detailed query explain plans and slow query logs, but the output is not always intuitive. A query showing high scoring time does not necessarily mean your index is poorly configured. It might mean your query itself is asking the engine to do unnecessary work, like running a complex script on every document. I once spent three hours troubleshooting what I thought was a indexing problem before realizing a pagination parameter was accidentally set to return ten thousand results per page instead of ten. The engine was scoring thousands of documents when it only needed to return a handful. If you are migrating from an existing search system, plan for a parallel run period. I keep both systems active during transition, writing identical queries to both and comparing result sets. This catches discrepancies early. You will find cases where Io Retriever returns results in a different order than your old system, and that can break user-facing functionality if your application depends on consistent result ordering. Setting explicit sort parameters prevents this, but only if you plan for it ahead of time. The tool is genuinely capable of serious performance improvements when configured correctly, but it punishes carelessness in ways that are easy to miss until users start complaining. Take the time to understand your data distribution, tune your analyzers, and test thoroughly before pushing to production. The initial investment in proper configuration pays off immediately in query performance and ongoing maintainability.