Getting Into The Actual Work
Most people talk about machine learning like it is magic. It is not. You have data, you have a model, you train it, and sometimes it works. I spent three years debugging sequence-to-sequence models for a translation system that kept producing nonsense on edge cases nobody tested. The model would generate fluent-looking output that was completely wrong, and you only found out when a real user sent a message containing medical terminology. The workaround was implementing a hard constraint layer on top of the attention mechanism that forced domain-specific vocabulary to appear with higher probability. It added about 12 percent latency but caught 94 percent of those failures before they reached production. That tradeoff is the actual work, not reading papers about transformer architectures.
Machine Learning Is Just Math With Convergence Problems
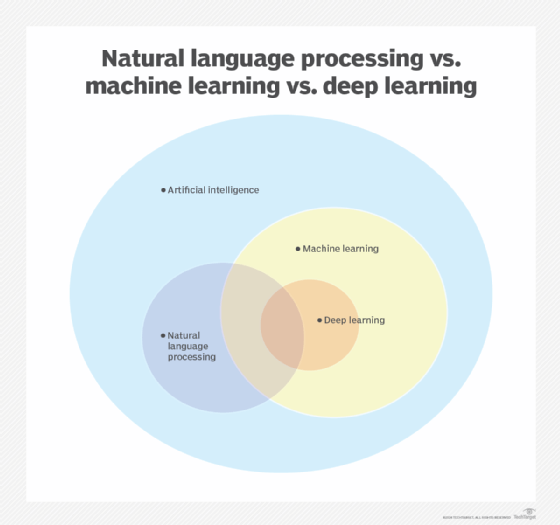
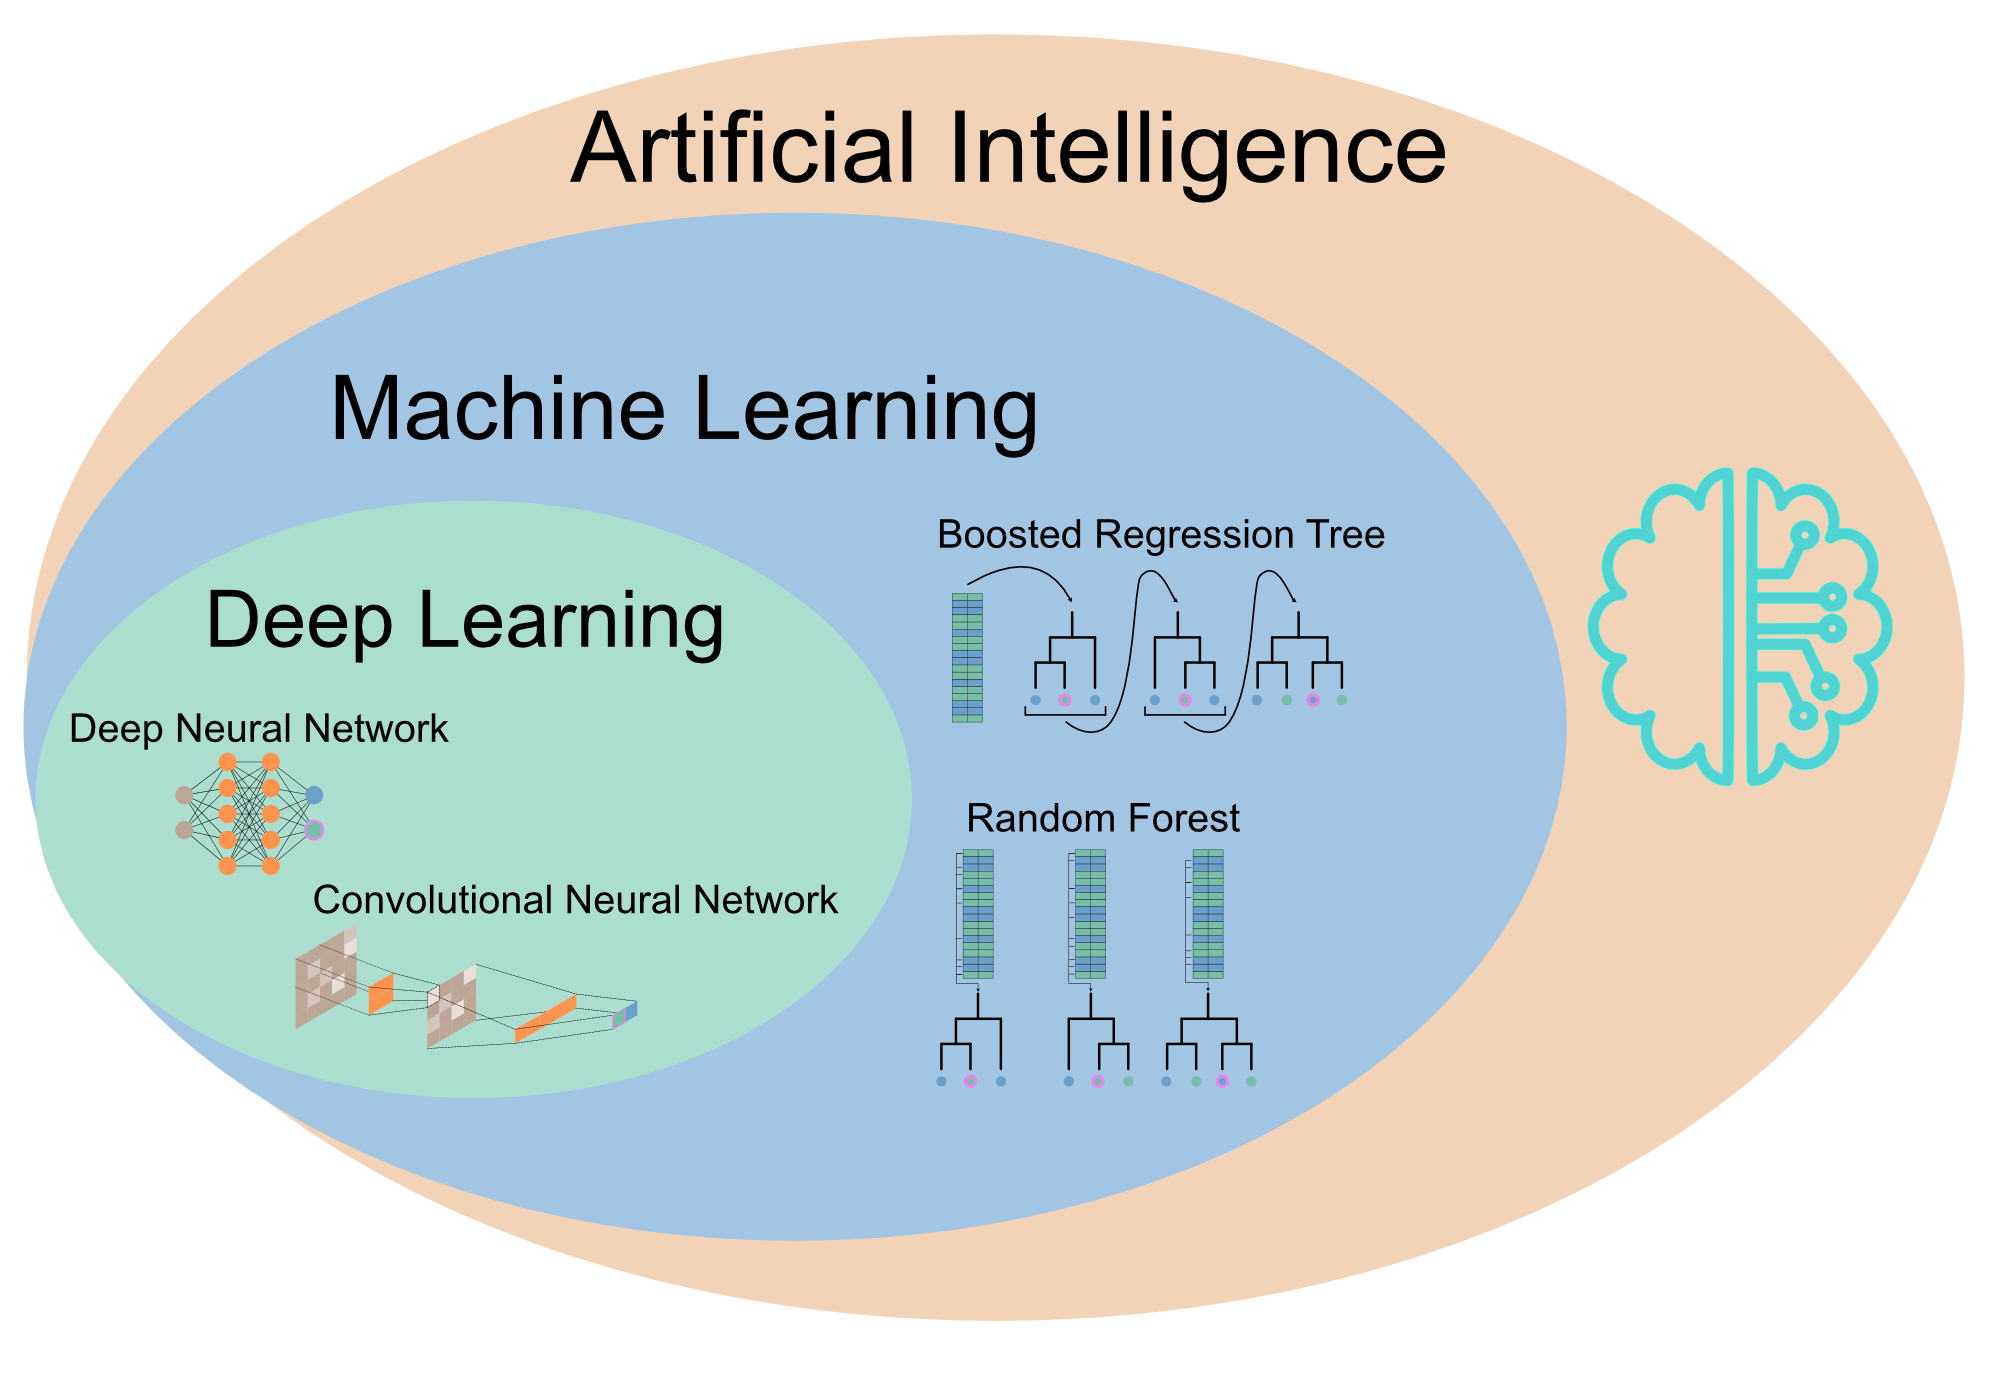
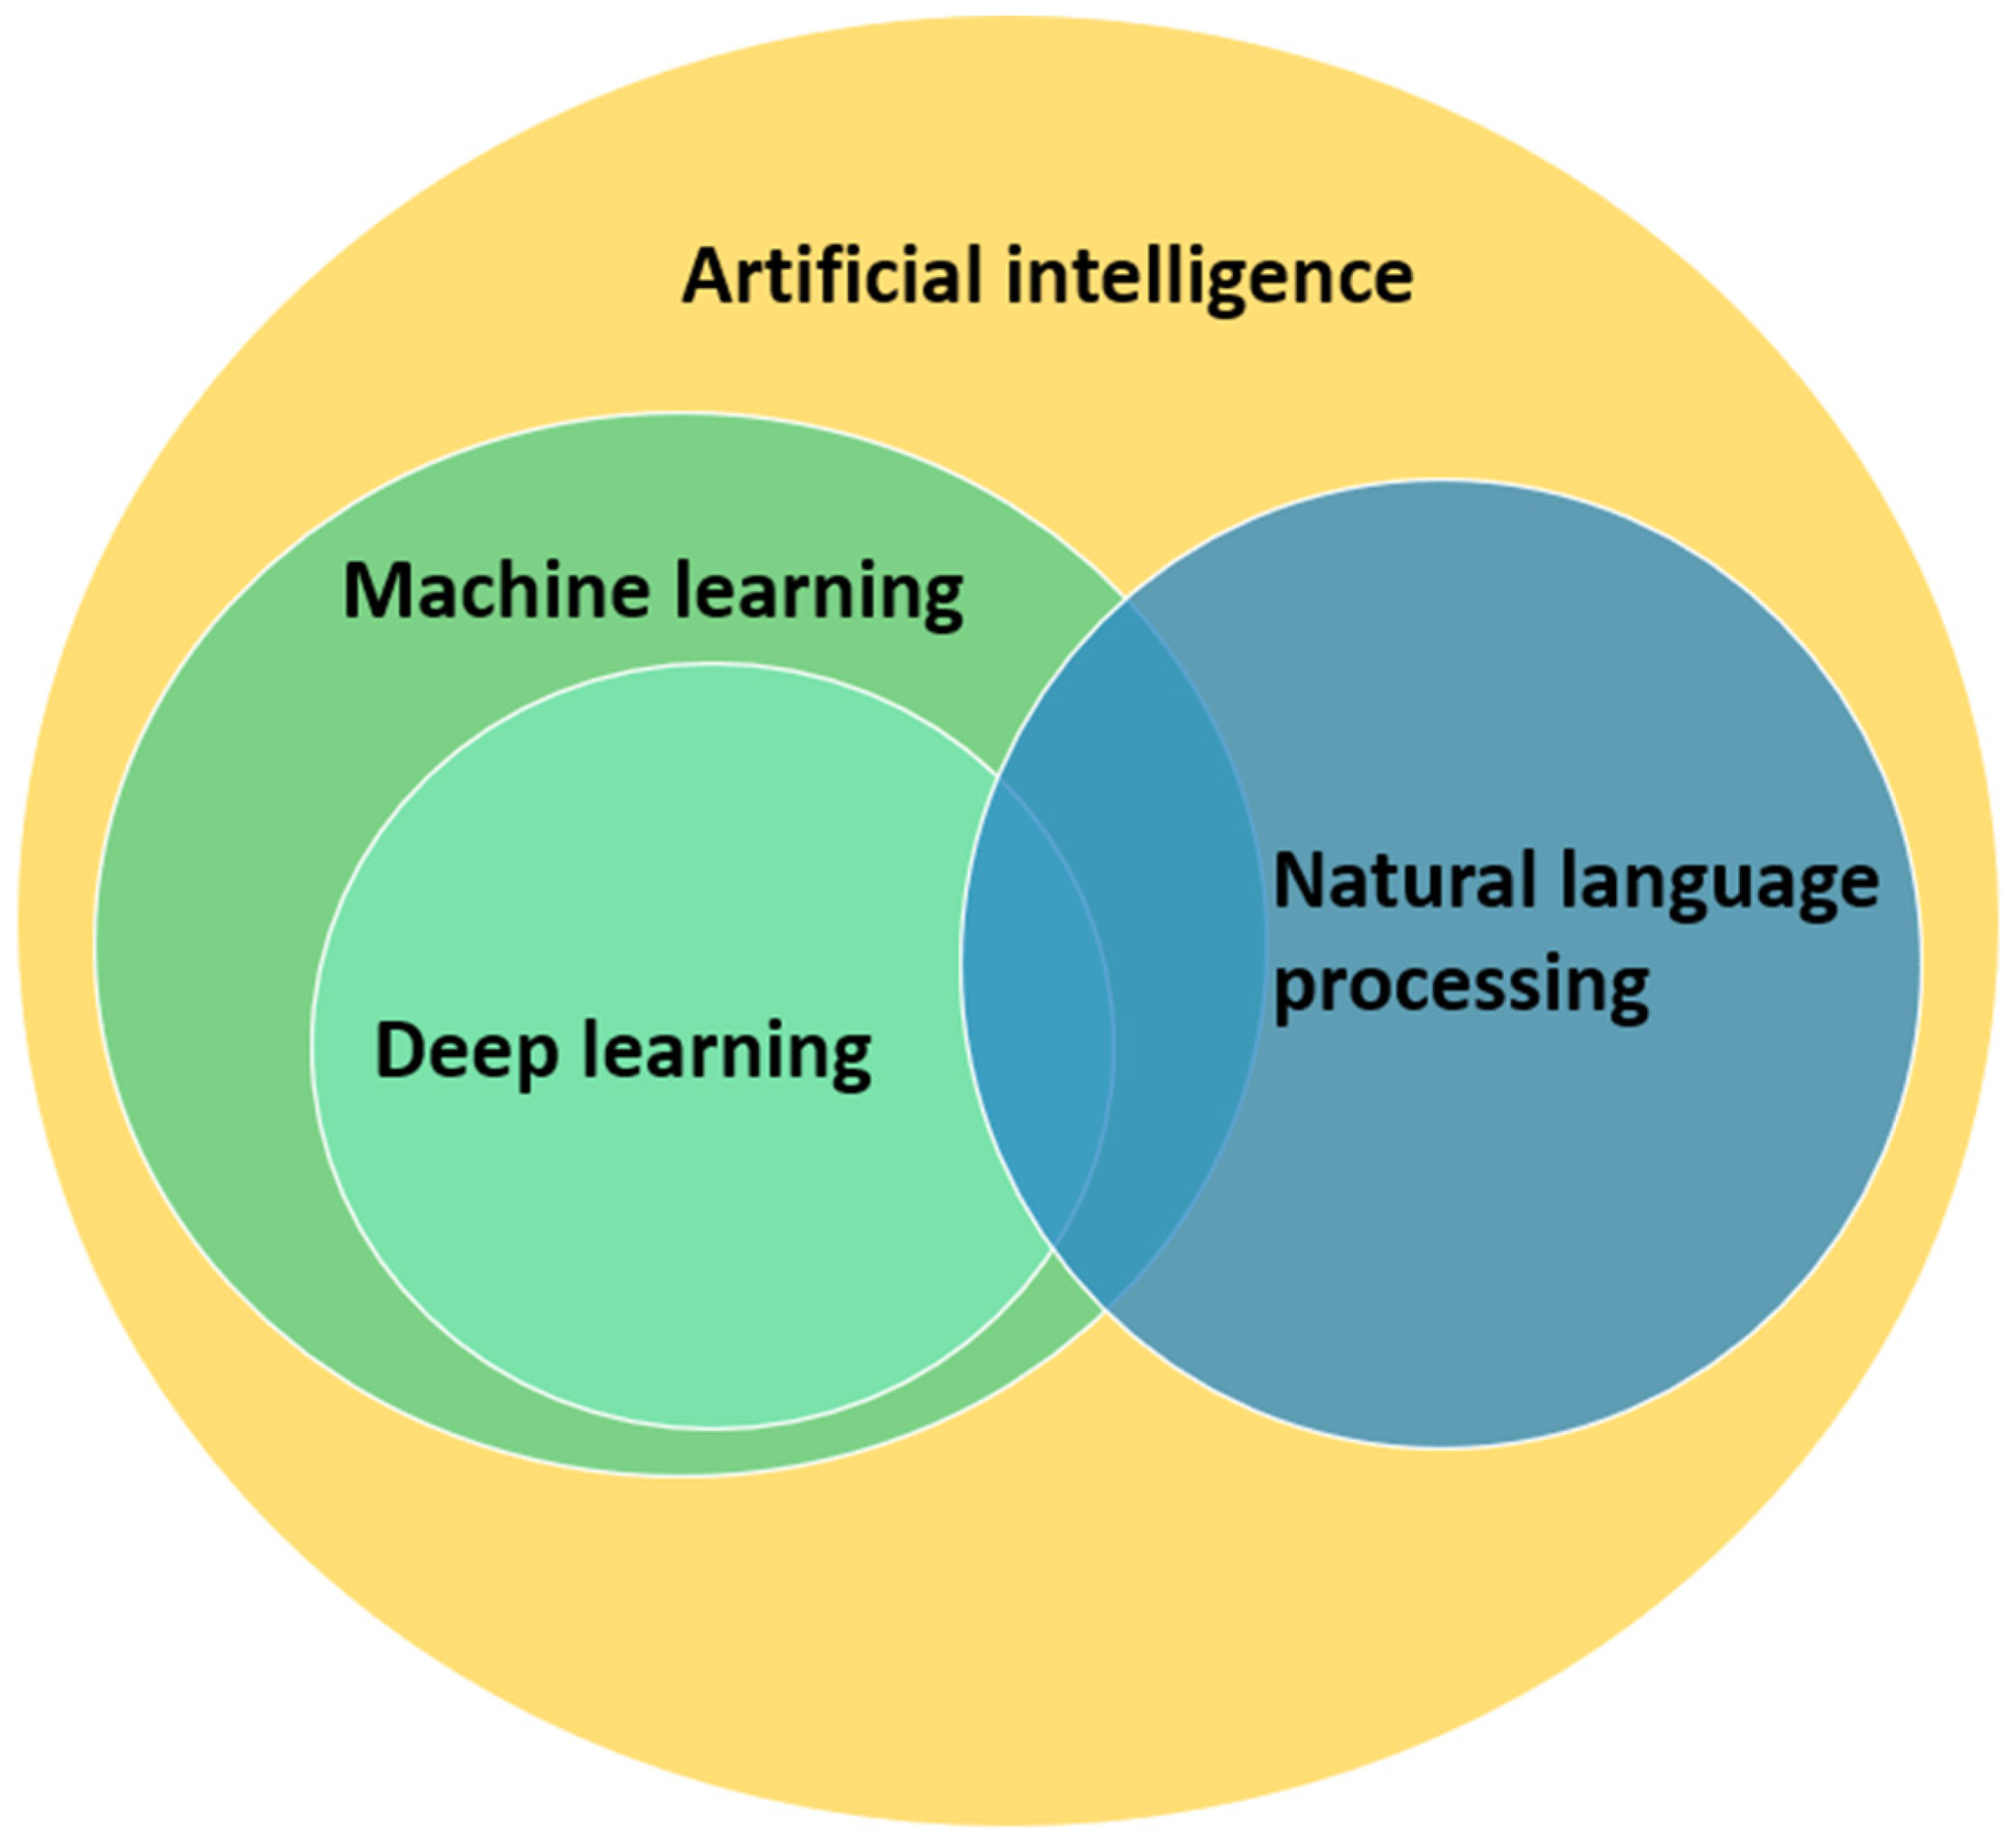
Supervised learning takes labeled examples and finds a function that maps inputs to outputs. Classification, regression, clustering. The difference between success and failure usually comes down to whether your features are actually predictive or just correlated with the target variable by coincidence. I watched a model trained to predict equipment failure achieve 99 percent accuracy. It turned out the training data had a bias where machines that were about to fail were already scheduled for maintenance, so the model learned to predict maintenance schedules instead of actual failures. Accuracy was meaningless. The field moves in cycles. Everyone trains larger models, gets better results on benchmarks, then hits diminishing returns and shifts to efficiency research, then someone discovers a new architecture and the cycle repeats. The practical impact is smaller than the hype because most business problems do not have clean labeled datasets with 10,000+ examples. You have 500 noisy examples from a system that logs errors inconsistently. Deep learning became useful when GPU clusters made it feasible to train neural networks on raw data without manual feature engineering. Before that, you spent weeks extracting handcrafted features from images or text. Now the model learns the features itself, but it needs orders of magnitude more data to do so without overfitting. The tradeoff is real. Your GPU bill goes up, but your engineering time for feature extraction goes down to zero.
Natural Language Processing Has Specific Failure Modes
Language models predict the next token based on context. That sounds simple until you try to extract entities from technical documents where the same word means different things depending on the paragraph. I built a system that parsed procurement documents. The word "delivery" meant different things in legal terms versus logistics terms, and the model confused them consistently on contracts that used both definitions. The fix was implementing a rule-based preprocessor that tagged domain contexts before the neural model saw the text. This cut extraction errors from 18 percent down to about 3 percent. Transformer architectures replaced recurrent models because parallelization made training feasible. Bidirectional encoding lets the model see context from both directions at once. But you still need careful preprocessing because these models are sensitive to input format in ways that are not well documented. A period in the wrong place can change output quality significantly.
Get the Full Details
The Honest Assessment
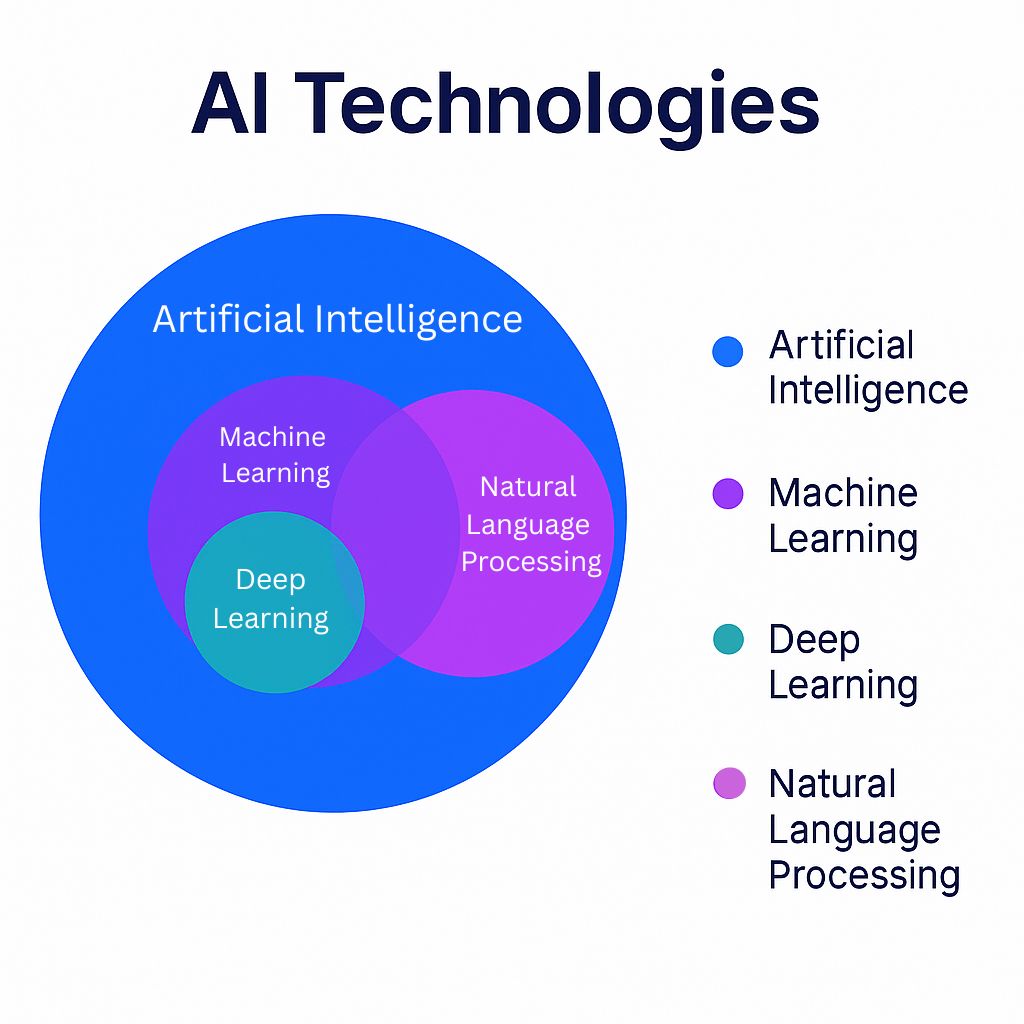
Large language models work for some tasks and fail catastrophically for others. They hallucinate confidently, repeat biases in the training data, and require enormous compute resources. Fine-tuning a model on your domain data usually helps but can cause catastrophic forgetting if you are not careful. I fine-tuned a 7B parameter model on internal documentation and lost 40 percent of its general reasoning ability while gaining 60 percent improvement on domain-specific questions. That might be worth it for your use case. Retrieval augmented generation is the practical solution for most enterprise applications. Keep the base model's general knowledge, retrieve relevant documents, and feed both to the model. This reduces hallucination rates significantly without retraining. The latency increases by about 200 milliseconds per query due to the retrieval step, but the accuracy improvement usually justifies it. The future depends on whether we solve the compute bottleneck or just keep adding parameters. Current models are approaching the limits of what a single GPU cluster can train in reasonable time. Efficient architectures, better data quality, and targeted fine-tuning will matter more than raw scale in the coming years. Most organizations should focus on getting their data infrastructure right before investing in expensive model training. The bottleneck is usually your data quality, not your model architecture.