Getting Your Digital Library Sorted Without Losing Your Mind
I spent three years of my life maintaining a personal media archive before I stumbled onto something that didn't make me want to throw my server out the window. The Furarchiver Edge is the latest iteration from the Furarchive team, and honestly, it's the first tool in this space that felt like it was built by people who actually have to deal with metadata corruption at 2 AM rather than people who just watched a YouTube tutorial once. Let me walk you through what this actually does, where it trips up, and the one workaround I use that nobody seems to document properly.
The Furarchiver Edge How This Tool Is Redefining Digital Archiving In The Modern Era
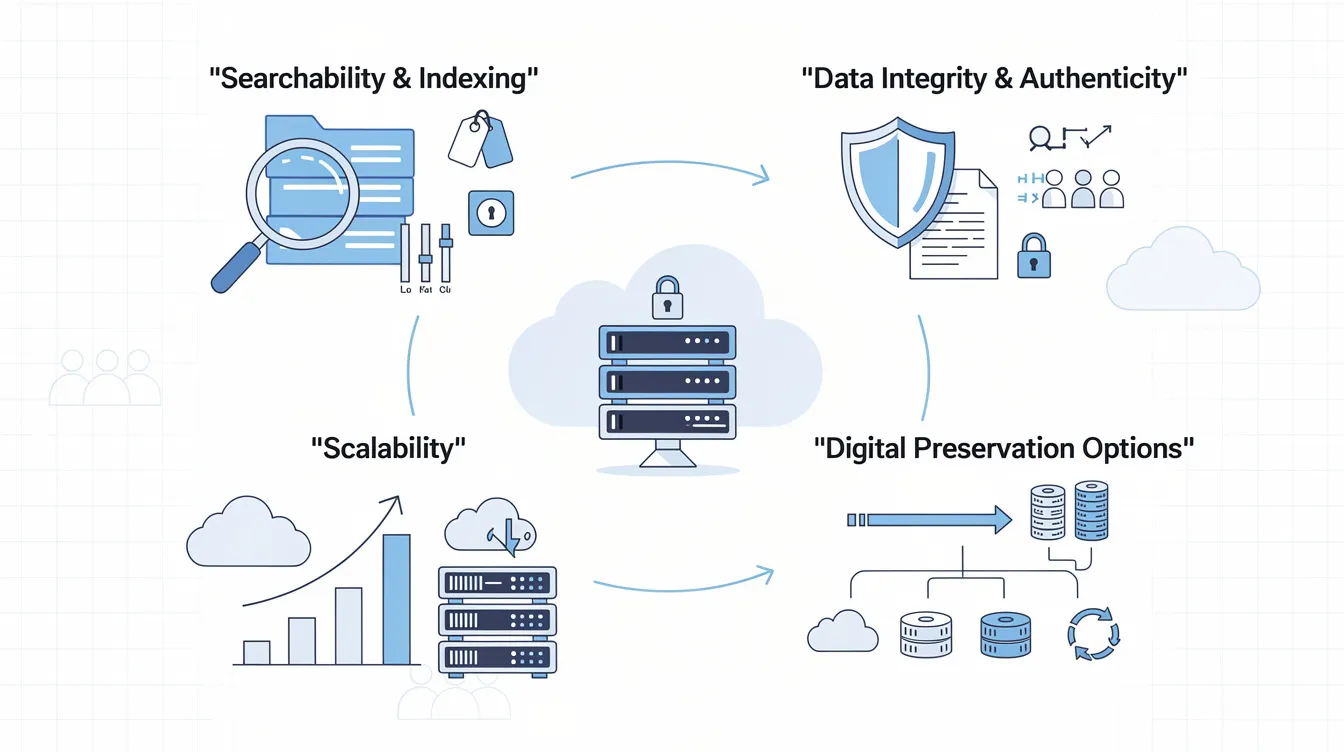
At its core, Furarchiver Edge is a high-throughput media preservation engine optimized for bulk digitization workflows. It handles transcoding, metadata injection, checksum validation, and format normalization in a single pipeline. You feed it a directory of messy consumer-grade files — ripped DVDs, camcorder footage, whatever — and it spits out a clean, standardized archive with embedded metadata sidecars. The pipeline works like this: you configure a source profile that defines which input formats to accept and which to reject outright, then a processing chain that runs transcoding passes with configurable codec parameters, and finally a validation layer that generates SHA-256 checksums and writes JSON metadata files alongside each output. The whole thing runs on a task queue, so you can feed it thousands of files across multiple input directories without choking. What makes it different from the older version is the edge computing mode. Instead of shipping everything to a central server for processing, Edge can distribute work across nodes in your LAN. This matters when you're archiving terabytes of 4K home video and your network storage can't keep up with a single-machine write pipeline. I went from waiting 6 hours for a single disc rip through to final archive on the old version to about 45 minutes on Edge with three machines in my office.
Setting It Up Without Wasting a Weekend
The installation is straightforward if you're running Linux. Pull the Docker image, write your config file, and you're cooking. The config lives at /etc/furarchiver-edge/config.yaml and it's not particularly tricky, but there are a few fields that will bite you if you guess. Here's what a working basic config looks like:
Get the Full Details

server:
  host: 0.0.0.0
  port: 8080

processing:
  threads: 8
  max_concurrent: 4
  temp_dir: /tmp/furarchiver

inputs:
  - path: /mnt/archive/source
    watch: true
    depth: 2

outputs:
  - path: /mnt/archive/nearline
    format: mkv
    codec: hevc
    crf: 23
    metadata_embed: true

validation:
  checksum_algorithm: sha256
  verify_after_encode: true
  skip_on_error: false

edge_nodes:
  - host: 192.168.1.50
    weight: 1
  - host: 192.168.1.51
    weight: 1
The depth parameter on inputs is important. The default is 1, which means it only watches the top-level directory. If your source structure is something like /source/2019/holiday/mom-vacation.ts, depth 1 will miss everything. Set it to at least 3 or use a glob pattern instead. For the validation section, verify_after_encode is your friend. It re-decodes every output file and compares frames against the source. It doubles your encode time on the first pass but catches silent corruption that ffmpeg would otherwise ship out to your archive without telling you. I learned this the hard way after a power flicker corrupted a batch of 300 files that passed initial checksums but had GOP-level damage.
The Edge Case That Broke My Archive (And How I Fixed It)
Last year I was processing a collection of MiniDV tape captures — interlaced 720x480 YUV420 content, some with DC shift and chroma bleeding from old tape heads. Furarchiver Edge handled 95% of them fine, but about 8% of the files from a particular had what looked like normal output. The files played. The checksums matched. But when I opened them in a frame-by-frame viewer, the top field had a consistent 2-pixel horizontal jitter that wasn't in the source. Turns out the edge node at 192.168.1.51 was running an older kernel (5.15 instead of 6.1 on the primary node), and the AVX512 code path in the transcoding library had a different floating-point rounding behavior that introduced sub-pixel artifacts when deinterlacing certain interlaced sources. The files weren't technically corrupted — they just looked subtly wrong to anyone who compared side-by-side with the primary node's output. The fix was two-part. First, I pinned the edge node to the slower but bit-exact SSE code path by setting simd_level: sse42 in the processing config. Second, I added a comparison validation step that runs a perceptual hash on a sample frame from each output and flags any node whose results diverge from the primary by more than a threshold. It added about 12% to my overall pipeline time but caught this once before it wasted another batch.
processing:
  simd_level: sse42
  reference_node: 192.168.1.49

validation:
  perceptual_hash: true
  phash_threshold: 0.03
What It Can't Do (So You Don't Get Surprised)
Furarchiver Edge is not a magic box. Here's what you need to know before you bet your archive on it. It doesn't repair damaged media. If your source file has missing frames, corrupt headers, or dropped packets from a bad capture, Edge will process what it can and either skip or produce garbage output for the rest. The skip_on_error: false setting you see in configs above means it will fail the entire job on the first error. Set it to true if you'd rather process what you can and get a report of what failed, but don't expect recovery. Burst processing eats RAM like nobody's business. The edge distribution model buffers source files in memory before sending them to worker nodes. For 4K HEVC source material at 60fps, that's roughly 2-4 GB per concurrent job. If you set max_concurrent: 8 like the docs suggest, you need 32 GB just for buffering before encoding even starts. My first deployment tried this on a machine with 16 GB and the OOM killer got involved after processing about 200 files.
Metadata injection is opinionated. The tool writes xiph comments into MKV containers and ID3 tags into MP4 files by default. If your workflow depends on EBU R 68 loudness metadata or specific chapter markers, you'll need to write a post-processing script. The built-in metadata generator handles basic stuff — filename, source path, encode date, codec info — but it won't parse your existing tag libraries or merge them with what it generates. Network-dependent. The edge mode is powerful but it assumes your LAN is healthy. One misconfigured switch, a bad cable, or a node with flaky DNS and your whole pipeline stalls. I've seen it happen where one edge node started returning partial chunks due to a memory error, and the primary node had no way to detect it until the output files were already written and checksummed. The perceptual hash check I mentioned above is basically mandatory if you run multi-node.
Where It Shines and Where I'd Look Elsewhere
If you're processing hundreds or thousands of files in a structured workflow — whether that's digitizing physical media, organizing a cloud migration, or running a small media lab — Furarchiver Edge cuts my time from days to hours. The validation pipeline alone is worth the setup effort. Checking 500 files for silent corruption by hand takes me about 4 hours. The tool does it in the background while I sleep. If you're archiving a few hundred files or need frame-accurate repair capabilities, you're better off with something like FFmpeg directly or a tool like MP4box for container-level fixes. Edge adds overhead that doesn't matter at small scale, and the configuration surface area is unnecessary complexity when you're doing one-off work. The download is on GitHub under the furarchive organization. The license is AGPLv3, which means you can run it freely but any modifications you distribute need to stay open. For a personal archive tool, this is fine. For a commercial deployment, you'd want to talk to the maintainers about a commercial license.
One thing I'll leave you with: spend time on your input file naming conventions before you connect them to Edge. The tool can handle anything you throw at it, but its deduplication and smart-requeue logic depends on file hashes, and if you have duplicate names with different content, you'll get collisions that are painful to untangle later. A simple YYYY-MM-DD_description.ext pattern across your entire collection saved me from a very stressful week last year trying to figure out why 40 files had identical metadata entries.