How People Actually Run This Without Losing Their Minds
I still remember mid-Q2 when our production calendar collapsed because three departments were interpreting "front runner" differently. Engineering treated it as first-to-start, operations treated it as first-to-finish, and finance just wanted something to bill against. We spent two weeks untangling it. The fix was uglier than you would think. Most organizations approach this from the wrong angle. They build the schedule around the work, not around the people doing the work. It sounds like semantics but it is the difference between a calendar that holds and one that falls apart the moment someone goes on vacation.
The Front Runner Schedule Blueprint How Elite Organizations Optimize Time Talent And Execution
The core idea is simpler than the name suggests. You identify the single most constrained resource in any given stretch of work, then you build outward from that constraint instead of trying to flatten every timeline simultaneously. Everyone else adjusts. The constraint does not. This is basically Critical Chain Project Management dressed up for executives who do not want to read the original books. The constraint gets protected by buffers, non-critical paths get flopped into resource-level lanes, and parallel work is throttled so nothing arrives all at once and blocks the bottleneck from moving.
What the Schedule Blueprint Actually Requires
You need three inputs before this works at all: 1. A clear bottleneck map. Not a Gantt chart. A list of the top three people or systems that limit throughput across the organization in a typical quarter. Usually it is two senior engineers, one approvals owner, and whichever external vendor controls your delivery timeline. 2. Raw estimates minus student syndrome. People do not give optimistic estimates by accident. They pad because they were burned by unrealistic deadlines. Strip that padding using historical velocity data, keep a conservative floor, and feed the stripped number into the front-runner lane. Do not let the team inflate again. Enforce it.
Get the Full Details

3. A buffer management system that does not require a dashboard. This is where most attempts fail. If your buffer tracking requires a consultant to update a slide deck every Monday, you are not running this. You need a color code, a threshold, and one person empowered to reroute work without committee approval.
The Method, Walked Through
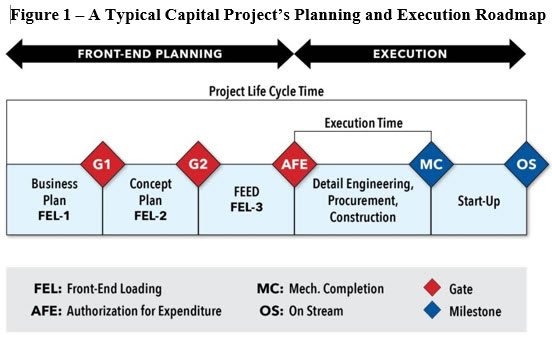
Here is how the actual sequence runs in practice, not the sanitized version from the handbook: Start by identifying the front runner. The front runner is the task sequence that passes through your bottleneck. Anything that does not touch the bottleneck is deferred or parallelized behind it. You are not scheduling everything. You are scheduling the thing that controls everything else. Next, estimate that sequence. Use team averages from the last four completed cycles, not best case numbers. If your bottleneck takes 8 hours per unit on average, do not plan for 5. Plan for 8, add a project buffer at the end equal to 50 percent of that sequence, and you are closer to reality than most portfolios.
Then layer in the non-front-runner work. Put it in parallel lanes but feed it into the schedule at staggered entry points. The goal is to arrive at the bottleneck in small batches, not as a wave. Batch size matters more than people realize. A batch of two units creates more context switching overhead than a batch of six units delivered over the same window. Maintain the buffer. Check it twice a week, not daily. Daily check-ins create noise that looks like urgency. Twice weekly checks catch real erosion. If the buffer drops below 25 percent, escalate the reroute decision to the single owner I mentioned earlier. That person has the authority to pull work from other lanes temporarily. Without that authority, the buffer is decorative.
One Edge Case That Broke Us and How We Fixed It
About eighteen months ago we hit a situation where the front runner for a major product launch kept getting hijacked by a minor regulatory filing. The filing was low visibility, high urgency, and owned by someone who reported into a different division. Every time it appeared, it ate three days off the main schedule and the buffer ate the rest. We tried escalation protocols. Those failed because the other division had its own metrics and did not care about our buffer status. The workaround was to treat the regulatory filing as a hidden front runner and schedule it explicitly in its own lane with its own buffer. Once we gave it a calendar position instead of letting it ambush us, the main launch sequence stabilized within two sprints. Buffer consumption dropped by roughly sixty percent and the launch hit its date. The lesson here is not about better communication. It is about schedule visibility. If a task can derail the front runner and it is not on the front runner's schedule, you are not managing the schedule. You are managing hope.
Things That This Approach Does Not Fix
Be honest about where this breaks: It does not work when the bottleneck shifts weekly. If your constraint moves depending on whoever is on PTO or which vendor is late that month, you are not doing resource leveling. You are doing fire fighting with a prettier title. In that scenario, invest in cross-training and redundant capacity first, then revisit this framework. It fails under heavy scope uncertainty. If the product requirements change mid-quarter at a rate above twenty percent of committed work, buffer management cannot absorb the churn. The schedule will look clean while the work dissolves behind it. Use stage-gate checkpoints with go/no-go decisions instead of trying to buffer through ambiguity.
It requires executive patience. The first quarter of implementation usually feels slower because you are stripping padding that felt like safety. Stakeholders will complain. Your data needs to show the trade-off clearly, and you need to survive the complaints. If leadership cannot tolerate a temporary dip in perceived throughput, this will be abandoned and you will be left with a half-implemented system and worse outcomes than if you had done nothing.
A Realistic Implementation Sequence
Pick one portfolio stream. Not the whole company. One stream with a stable bottleneck and a team that has worked together for at least two quarters. Run the blueprint there for eight weeks. Track three numbers only: buffer consumption rate, front runner completion accuracy, and non-bottleneck idle time. If buffer consumption stays under forty percent by week six and front runner dates land within ten percent of plan, expand to the next stream. If not, debug the bottleneck identification before scaling. Most teams skip that step and blame the method. After the second expansion, introduce staggered batching across streams. That is where the compounding gain shows up. You should see a fifteen to thirty percent reduction in average cycle time across the portfolio within twelve weeks, assuming you do not add headcount during that window. Headcount changes mess with velocity baselines.
Software Reality Check
Most project tools claim to support this. None do it natively without customization. You will spend more time configuring Jira, Asana, or MS Project than you will saving time, unless your organization already has a dedicated portfolioOps person. For smaller teams, a well-maintained spreadsheet with three tabs plus a shared buffer tracker often outperforms a poorly configured enterprise tool. Do not romanticize the software. If your work is under sixty hours per unit, the overhead of buffer management and bottleneck scheduling outweighs the benefit. Short-cycle work benefits more from kanban flow and WIP limits than from this blueprint. If your delivery depends heavily on external vendors whose timelines you cannot control, invest in contractual SLAs and penalty structures first. This framework assumes you have enough scheduling sovereignty to make the math work. The organizations that make this look elegant usually spent eighteen months building the data discipline underneath it. The schedule is not the strategy. The strategy is knowing what your constraint actually is and having the courage to protect it.