Antonyms Are Not What Your Dictionary Says They Are
The Fascinating World Of Antonyms Unveiling The Power Of Opposites
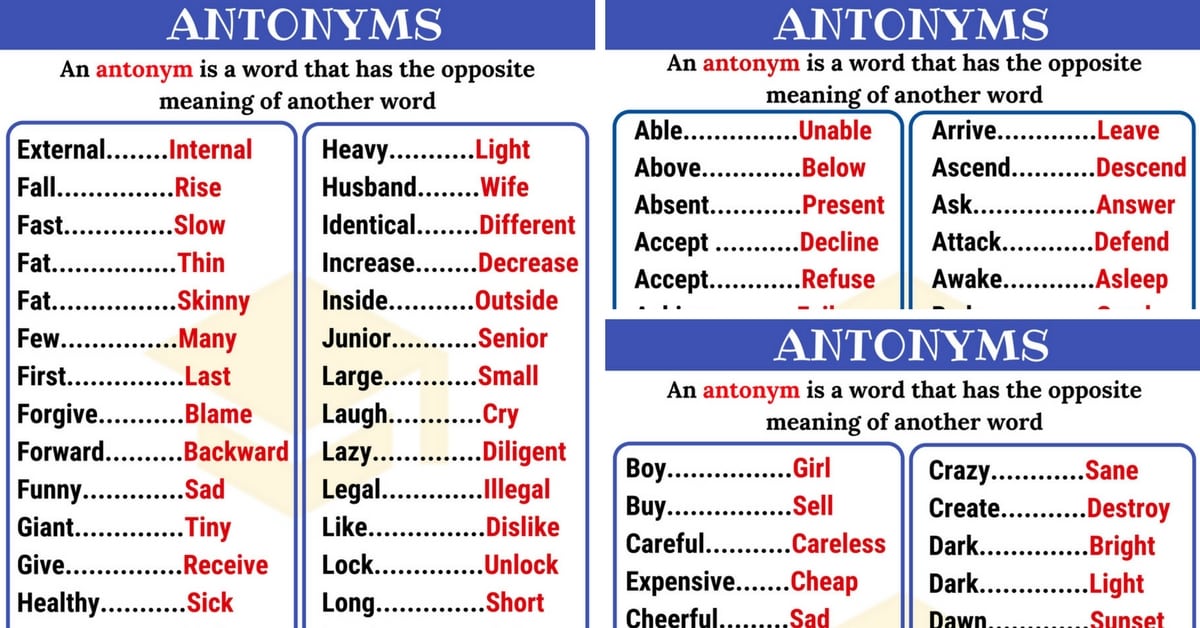
Antonyms are words that have opposite meanings. That sounds straightforward until you actually sit down to sort them out. I spent three weeks once trying to build a semantic tag system for a product catalog and learned that "cheap" and "expensive" are not clean opposites in any meaningful taxonomic sense. Cheap implies low quality to most people. The opposite of expensive is affordable, not cheap. If you map those wrong, your search filters break in ugly ways. Most people building these systems don't think about it. They just grab the first opposite from a thesaurus and call it a day. Antonyms in natural language don't come in tidy pairs. There are different classes and mixing them up causes real problems downstream. The main types you will actually encounter aregradable antonyms, complementaries, and converses. Gradales exist on a spectrum. Hot and cold sit between warm, tepid, lukewarm, and freezing depending on context. You cannot say something is either hot or cold with no middle ground. That distinction matters because gradable antonyms are where most of your ambiguity lives. Complementary antonyms are binary. Alive and dead. Valid and invalid. Pregnant and not pregnant. Something cannot be both. These are safe to use in logic. They are also the rarest type in natural language. Converses are relational opposites. Husband and wife. Buyer and seller. Teacher and student. One side of the pair cannot exist without the other. Mapping these into a data model as simple boolean flags is a mistake I saw on a live project. Someone coded "admin" and "user" as antonyms in the schema. Then they wondered why half the permission errors were unexplainable.
I ran into a specific edge case with converses that took me two days to debug. We had a database of service interactions where each record linked a provider to a customer. A product manager wanted a dashboard that showed "customer history" by listing all records where that person appeared. The naive approach was to store an inverse field. That doubled our write latency and introduced consistency bugs every time an update failed halfway through. The fix was to stop treating converse pairs as data at all and build a single junction table with directional foreign keys, then resolve the converse relationship at query time using an index on both column permutations. Simple. But only once you know the problem exists. The power of antonyms is not theoretical. It shows up in search, sentiment analysis, knowledge graphs, and any system that tries to understand what a word means by contrasting it with another. Search engines rely heavily on antonym relationships to broaden queries. When someone searches for "cheap flights," the engine knows that cheap here maps to a value intent, not a quality judgment, and surfaces discounted options rather than low-rated airlines. That mapping is not automatic. It has to be engineered. In sentiment analysis, antonyms are the thing that breaks naive models the most. Take the sentence "The movie was not good." A basic word-list approach sees "good" and calls it positive. It misses the negation. A better model handles negation scope, but then runs into the problem of scalar negation. "Not cheap" does not mean "expensive." It means somewhere above the threshold for cheap, which could be mid-range. I have seen teams throw out their first-pass sentiment pipeline after realizing that antonym-based heuristics were inflating positive scores on customer reviews by almost twenty percent. The fix was layering a negation scope detector and then validating against held-out labeled data before re-enabling the antonym boost.
Knowledge graphs use antonym relations as explicit edges. The usual format is a predicate like antonymOf connecting two nodes. This looks clean until you try to reason over it. If A is the antonym of B, and B is the antonym of C, can you infer anything about A and C? In complementary pairs, yes. In gradable pairs, no. The reasoning engine needs to know which class each edge belongs to or it generates garbage inference. We hit this when a client tried to automatically populate comparison pages by chaining antonym edges. The pages included things like "Is hot the opposite of dry?" because the graph had no type discipline on the antonym relationship. Adding a type tag to each antonym edge fixed it immediately. If you are building something that uses antonyms, the practical part starts with deciding whether you need a static list or a dynamic extraction. Static lists come from resources like WordNet, which is free and covers English well. It is also outdated on newer vocabulary. Words like "ghost" used as a verb or "touch grass" do not appear there in useful forms. If your domain is ecommerce, medical, or legal, WordNet will miss a lot. The workaround is to supplement it with domain-specific synonym/antonym corpora. I pull from ConceptNet for general coverage, then merge in custom lists built from labeled training data in the target domain. The merge step is not trivial because the same pair can be antonyms in one domain and not in another. "Open" and "closed" are antonyms for stores, but not really for software permissions where "open" pairs with "restricted." For dynamic extraction, the standard approach today is to use embeddings and find neighbors with opposite polarity. You can do this by training a contrastive model or by using existing vector representations and computing cosine similarity on negated contexts. I use a simple pipeline: collect sentences with target words in negated and affirmed contexts, encode them, cluster the negated and affirmed vectors separately, and measure the distance between clusters. Words with high inter-cluster separation and high intra-cluster cohesion are likely robust antonyms. It takes about an hour to run on a modest GPU cluster for a few thousand target words. The output is noisy. You still need manual validation on the top pairs. But it catches usage-based antonyms that static resources miss.
Get the Full Details

There are pitfalls that slow people down more than the technical parts. First is directionality. Antonym relationships are not always symmetric in how people use them. "Happy" and "sad" feel symmetric. "Begin" and "end" are directional in narrative contexts. If you assume symmetry everywhere, your reverse lookups will misfire. Second is context dependence. "Long" and "short" are antonyms for distance, but not always for time. "High" and "low" flip again for temperature versus status. The third pitfall is false antonyms from thesauruses. They list contrasts without confirming actual opposition. "Big" and "small" are genuine. "Big" and "insignificant" are more literary than functional and cause noise in automated pipelines. The downside of relying on antonym mapping is that it inflates precision on narrow tasks and collapses on ambiguous ones. Sentiment models that lean too hard on antonym substitution overcorrect on litotes and sarcasm. Search expansion using antonyms pulls in irrelevant results when the antonym pair is gradable and context-sensitive. Knowledge graph inference fails when converse and complementary edges are treated identically. The recommendation I give teams is to treat antonyms as a supplementary signal, not a primary one. Use them to fill gaps. Do not let them drive the main logic. Validate against held-out examples before shipping anything that depends on them. And document which type each antonym pair is so downstream components can handle them correctly. I keep a small personal reference for antonym types. It is just a spreadsheet with columns for the pair, the type, the domain, and a confidence score from manual review. I update it whenever a new pipeline breaks in production. That has happened twice in the last year, once because someone changed a negation handling rule and once because a new product category introduced relational opposites that looked like gradable pairs. Both fixes were quick once the category was identified. The spreadsheet saved me from repeating the same mistake.
If you want a starting resource, WordNet is the baseline. It is open, well-maintained for older vocabulary, and easy to query via Python libraries. For newer language, ConceptNet covers more ground but requires filtering for quality. If you need domain-specific pairs, building them from labeled data using the embedding contrast method described above is the most reliable path I have found. It takes effort. It also produces results that actually match how people use words today instead of how dictionaries decided they should be used fifty years ago.