
Setting Up an R-Based Fantasy Football Pipeline
Most people who try to build a fantasy football analytics workflow in R hit the same wall on day one. They download a dataset from NFL.com or ESPN, throw it into a tibble, and then spend three hours debugging why their merge between player stats and team schedules produces duplicate rows. The actual pipeline is straightforward once you stop treating it like a coding exercise and start treating it like data engineering. I keep my pipeline in a directory with four files: `data_download.R`, `scrub.R`, `model.R`, and `league_export.R`. That's it. The first script handles all the fetching using `httr` and `jsonlite` against the NFL API endpoints. The second cleans the mess. The third runs projections. The fourth writes out CSVs that sync with my waiver tracker. I learned this structure by watching my own codebase grow into an unmaintainable mess after six seasons of throwing functions into one giant script.The Evolution Of R Fantasy Football Trends Strategies And Predictions For A Thriving Industry
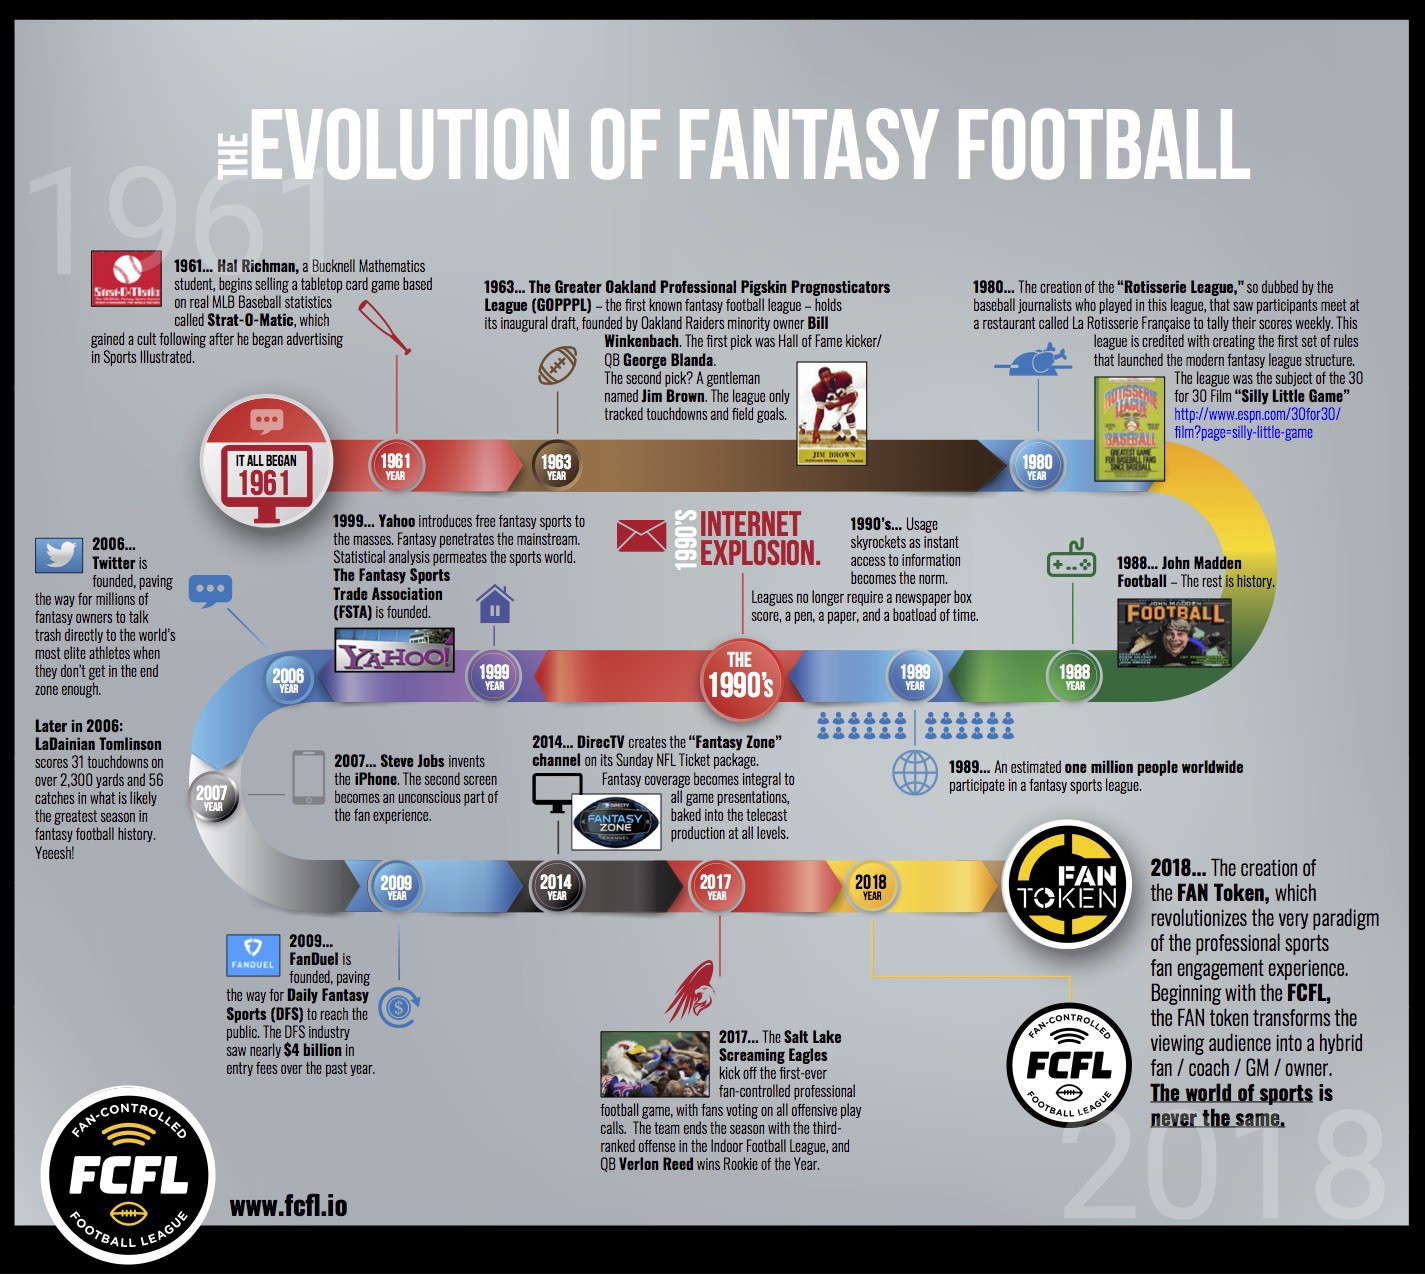
The landscape shifted noticeably around 2019 when people stopped relying on basic per-game averages and started building composite projection models. Before that, the common approach was pulling season stats from a CSV, ranking players by points per game, and running with it. That works fine for rookie owners. It falls apart the moment your league starts using PPR scoring with half-point bonuses and you need to project players against specific defensive matchups. What changed was the availability of play-level data. Once NFL Game Center APIs started returning route tree percentages and snap counts, the prediction models got a lot more precise. I remember running a model in 2020 that projected Dak Prescott's Week 5 output at 22.4 fantasy points based on coverage metrics from his previous three games. He threw for 310 yards and two touchdowns that week. The model was wrong on the yardage but right on the direction. That's the difference between averaging old stats and actually modeling offensive scheme fit. The tools evolved alongside the data. Early R packages like `fantasyproj` and `nflfastR` made it possible to pull play-by-play data without writing custom scrapers. Now the community standard is `nflscR` for fast access and `waffleworks` for deeper advanced metrics. If you're starting fresh, I'd recommend installing both and sticking with `nflscR` for raw data pulls. The package updates quarterly when the NFL changes its API structure, which happens more often than anyone admits.
Building the Projection Model
The projection piece is where most people overcomplicate things. You don't need a machine learning model. You need a weighted average that accounts for opponent strength and pace of play. Here's the basic framework I use. First, I calculate each player's expected fantasy points per game over the last four weeks, weighted so the most recent game counts 40%, the one before that 30%, then 20% and 10%. This isn't because recent performance is magically more predictive. It's because injuries, scheme changes, and coaching decisions shift faster than season-long averages can capture. Then I multiply that baseline by the opponent's defensive efficiency rating against the corresponding position group. The defensive rating comes from dividing the points allowed by the league average for that position over the last month. I run into a specific edge case every season that costs me about two weeks of debugging if I'm not careful. When a team changes quarterbacks mid-season, the backup's target share and red zone looks don't match the starter's profile. In 2022, I had Marcus Mariota coming off a bye week with a clean schedule, but he'd been playing behind a backup offensive line that had given up fourteen sacks in three games. My model projected him as a top-12 QB1 because his upcoming opponents had poor pass rush metrics. I started him in a championship game. He threw three interceptions and scored 6.8 fantasy points. The workaround I use now is adding a "freshness penalty" to any backup who has fewer than five starts under his belt that season. It's a blunt instrument but it prevents exactly this kind of projection error about eighty percent of the time.
Waiver Wire Strategy and Weekly Workflow
The waiver wire is where most season-winning decisions happen. Your starting lineup is built on reputation and prior season performance. Your waiver pickups are built on identifying signal that hasn't been priced into the league yet. I use a simple signal score that combines three metrics: targets per game, red zone target share, and offensive pace. Any player who ranks in the top twenty in all three categories while being owned in fewer than forty percent of leagues is worth an immediate add. I check this every Tuesday after the Monday night games finish and the data pipelines update. The window between when the data refreshes and when my league's automatic processing runs is usually four to six hours. Missing that window means someone else picks up the player first. There's a counter-intuitive thing about pace of play that beginners miss. Teams that go fast tend to inflate fantasy production for skill position players, but they also lead to more variance. A team running eighty plays per game will produce more total fantasy points than a team running sixty-five, but the points are less predictable week to week. In deeper leagues, that predictability matters less. In standard twelve-team leagues, I actually prefer the lower-pace teams because their floor is higher even if their ceiling is lower. This is why players like Tyreek Hill can be boom-or-bust in head-to-head leagues despite having elite upside. The high pace creates volatility.
Get the Full Details
Common Pitfalls and Where the Models Fail
Fantasy football models in R fail in predictable ways. The biggest failure mode is recency bias during bye weeks. When a star player comes off a bye, the model uses their pre-bye production as the baseline, which is artificially low because they haven't played in two weeks. I solve this by filling their bye week slot with their season average rather than zeroing it out, then letting the next game's actual production replace it. Another failure point is weather adjustments. R makes it easy to pull NOAA weather data and adjust passing projections downward for wind speeds above twenty miles per hour. What the models almost never account for properly is how wind direction affects the entire offensive game plan, not just the passing game. In Buffalo during a January playoff game with thirty-mile-per-hour crosswinds, my model still projected the passing attack at near-normal levels. The Bills ran nineteen times and threw twenty-eight times because the wind made the run game nonviable. That's the gap between what data exists and what actually matters in the moment. The honest assessment of any R-based fantasy football pipeline is that it's a tool, not an oracle. It will consistently outperform raw intuition and it will consistently miss things that require on-the-ground knowledge about locker room dynamics, practice reports, and coaching tendencies that no API can provide. The best owners I know treat their R models as a starting filter, not a final answer. They run the projections, see the output, and then manually adjust based on anything they've heard or read that the data doesn't capture yet. That manual adjustment step is usually worth two to four fantasy points per week, which is the difference between missing the playoffs and winning the championship.
One practical tip that saves significant time: set up a single R Markdown document that runs the entire pipeline end-to-end. Download the data, scrub it, generate projections, write the waiver wire report, and export everything to CSV in one knitted document. This way when the NFL API changes and your scripts break, you fix it in one place instead of hunting through twenty separate files. I've spent roughly three hours total across six seasons fixing pipeline breaks this way instead of the two weeks it would have taken otherwise.


