What People Mean When They Talk About Immigration in Biology
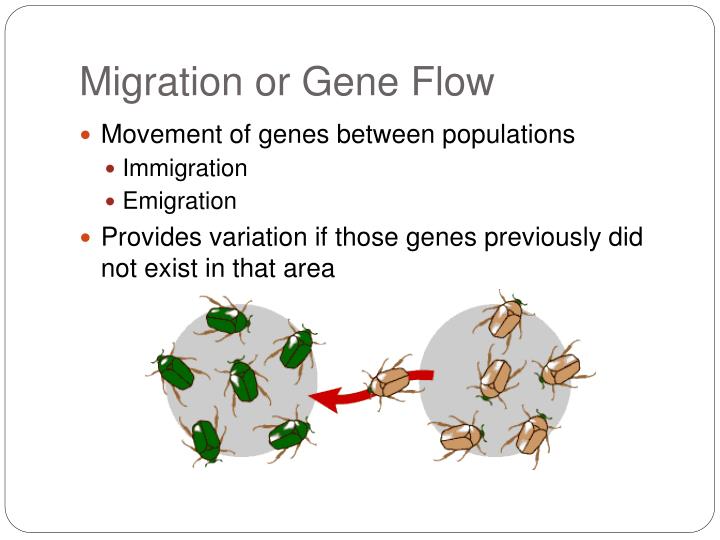
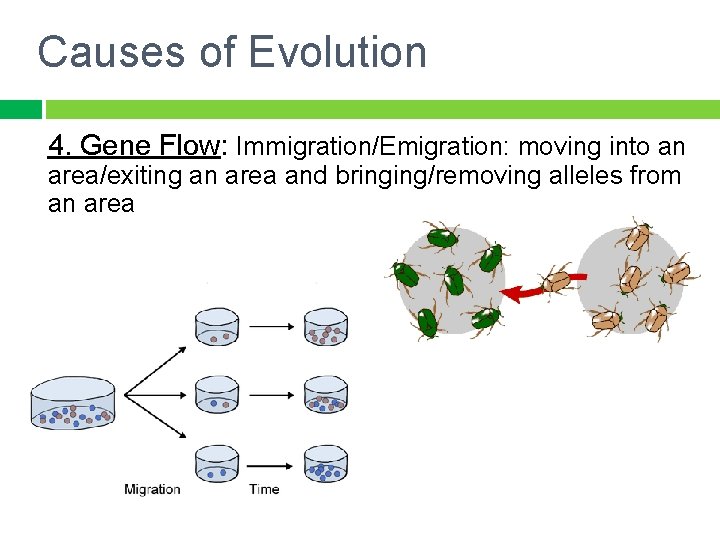
The concept of immigration in biology isn't as simple as someone moving from one place to another. In population genetics and ecology, immigration refers to the movement of individuals or their genetic material into a new population, where they breed and contribute alleles to the local gene pool. This is formally called gene flow. The terminology gets messy fast because ecologists and geneticists use the word differently, and the two subfields don't always line up when you're actually running models or writing papers. When I first started working with migration data in population genetics, I assumed the math would be straightforward. It wasn't. The standard models treat immigration as a simple proportional influx of genes per generation, but real systems are rarely that clean. You have asymmetric migration, temporal variation, and the awkward problem that most of what we measure is indirect—estimates of migration rates derived from F-statistics or coalescent methods rather than direct observation.
The Evolution Of Immigration In Biology A Complex And Rapidly Changing Field
The historical arc of this field runs roughly like this. Wright and Fisher built the foundational mathematics of gene flow in the 1930s and 1940s. They treated populations as abstract islands exchanging migrants at constant rates. The island model was elegant and nearly useless for anything beyond teaching. Then Nagylaki, Slatkin, and a whole wave of people refined the stepping-stone and isolation-by-distance frameworks through the 1970s and 1980s. Those models at least acknowledged that geography matters. The real shift came with the molecular era. Suddenly we had sequence data instead of just phenotypic observations, and researchers could directly infer demographic history. Hudson's MIGRATE software in the late 1990s was a genuine turning point. It used Markov chain Monte Carlo methods on gene genealogies to estimate migration rates and effective population sizes simultaneously. Before that paper, migration estimation was mostly hand-waving with Fst values converted into rough Nm estimates using the formula Nm (1/Fs - 1)/4. That formula assumes equilibrium, which almost no real population satisfies. More recent work has pushed into Bayesian frameworks, ABC (approximate Bayesian computation), and machine learning approaches. Beaumont's work on ABC around 2002 opened the door to model choice without needing explicit likelihoods, which was a big deal because the exact likelihoods for most realistic migration scenarios are computationally intractable. Now we see methods like dadi and fastsimcoal2 doing full demographic inference from site frequency spectra, and newer tools like MSMC and SMC++ leveraging sequential Markovian coalescent theory to reconstruct population size changes and divergence times from single genomes or a handful of diploid sequences.
The field is moving fast. What was state of the art five years ago is often considered baseline today. That's both a blessing and a headache if you're trying to stay current.
Get the Full Details

How Migration Rates Are Actually Estimated
There are several distinct approaches, and they answer different questions. You need to pick the right one for your system, or you will produce garbage results that look convincing on the surface. Fixation index methods. The old Fs-based approach converts pairwise differentiation into an estimate of migrants per generation under the infinite island model. The conversion is Nm = (1/Fs - 1)/4 for diploids. This is useful as a rough first glance. It breaks down whenever populations are not at migration-drift equilibrium, which includes almost every system humans have touched. It also collapses to nonsense when Fs is negative or near zero because the formula simply doesn't apply. Use it as a sanity check, not an analysis. Coalescent-based methods. Programs like MIGRATE-N and IMa2 estimate migration rates and divergence times jointly from multilocus sequence data. They model the genealogy of sampled alleles backward in time and integrate over possible tree topologies. The computational cost scales poorly with sample size. MIGRATE-N can handle maybe a few dozen sequences across a handful of loci before MCMC mixing becomes problematic. If you have hundreds of individuals, you need something else.
Site frequency spectrum methods. dadi and fastsimcoal2 work from the unfolded or folded allele frequency spectrum. You specify a demographic model—number of populations, timing of splits, migration rates—and the program simulates the expected SFS under that model, then finds the parameter values that maximize the likelihood of observing your actual data. These methods are orders of magnitude faster than full coalescent approaches for large datasets. The tradeoff is that you have to guess the right model structure beforehand, and misspecification is easy. If you fit a two-population symmetric migration model to a system that actually has three populations with asymmetric gene flow, the output will be internally consistent and completely wrong. Assignment and Bayesian clustering. STRUCTURE, fineSTRUCTURE, and ADMIXTURE approach the problem differently. Instead of estimating continuous migration rates, they cluster individuals into genetic groups and infer admixture proportions. These methods are good for detecting recent admixture and identifying which populations contribute ancestry to a given individual. They are terrible for estimating historical migration rates or divergence times. People frequently misuse them for exactly those purposes because the output looks nicer on a bar plot than a table of migration rate confidence intervals. Linkage disequilibrium methods. LD-based estimators like the one implemented in NEILS or the approach by Wang (2009) use the decay of linkage disequilibrium with time since admixture to estimate recent migration or admixture dates. These are useful for very recent events—on the order of a few generations to a couple dozen. They tell you almost nothing about deeper demographic history.
A Specific Problem I Ran Into
Last year I was working on a project involving a species complex with suspected recent secondary contact. We had RADseq data from roughly 200 individuals across eleven populations. I ran fastsimcoal2 with a range of demographic models. Everything looked reasonable until I cross-referenced the migration estimates with known landscape features. Two of the population pairs showed symmetric migration rates of about 5 per generation, but the landscape between them included a major mountain range that I knew from field work would be a significant barrier. The model was fitting the data, but it was fitting the wrong thing. The symmetric migration parameters were absorbing signal from incomplete lineage sorting and ancient shared polymorphism, not contemporary gene flow. The workaround was to add an additional parameter for ancestral population size and to test a model with no post-divergence migration alongside the migrating model. The no-migration model actually had higher likelihood under certain configurations once ancestral structure was accounted for. We also ran a separate analysis using fineSTRUCTURE to confirm that the genetic signal in those two populations was consistent with shared ancestry rather than ongoing exchange. The combined evidence suggested the high apparent migration was an artifact of model misspecification, not a biological reality. This kind of convergence between methods matters more than any single estimate.
Common Pitfalls
Equilibrium assumptions. Most classical methods assume migration-drift equilibrium. Real populations rarely sit at equilibrium. Habitat fragmentation, range shifts, and introduction events all violate this assumption. If your system has experienced recent disturbance—which includes basically everything in the Anthropocene—you need methods designed for nonequilibrium demography. fastsimcoal2 and dadi can accommodate some nonequilibrium scenarios, but the parameter space explodes quickly and identifiability becomes questionable. Confounding migration with population size. Migration and effective population size leave similar signatures in genetic data. Both affect the amount of genetic diversity and the shape of the site frequency spectrum. When you estimate them jointly, the confidence intervals overlap substantially. This is not a software bug. It is a fundamental identifiability problem. No amount of data will fully resolve it unless you have strong external information, such as temporal sampling or independent ecological data on dispersal. Marker choice matters more than people admit. RADseq, SNP arrays, and whole-genome sequencing each have different biases. RADseq tends to undersample regions of low complexity and can have missing data patterns that correlate with population structure, creating spurious signals of differentiation. SNP arrays are even worse because the ascertainment bias is baked into the design—most arrays are optimized for common variants in a subset of populations. Whole genomes are ideal but expensive at scale. If you are working with nonmodel organisms, you probably don't have genomes, and you need to be honest about what your marker system can and cannot tell you.
Ignoring sex-biased dispersal. Many organisms have asymmetric dispersal between males and females. mtDNA and nuclear markers will give you different migration estimates in those cases. I have seen people publish single migration rate estimates from mitochondrial data alone and present them as species-wide parameters. That is incorrect. You need to at minimum compare uniparental and biparental markers, and ideally use sex-linked markers if your study organism has them.
What This Field Is Heading Toward
The direction seems clear even if the specifics change quickly. Single genomes are becoming usable for demographic inference rather than requiring dense multilocus sampling. SMC-based methods are improving, and as more reference genomes become available, pairwise sequentially Markovian coalescent approaches will likely replace many SFS-based methods for within-species inference. Machine learning is entering the picture in a restrained way—not as a replacement for likelihood-based methods but as a tool for model validation and for handling parameter regimes where traditional optimization struggles. Another shift is toward integrative frameworks that combine genetic data with ecological niche models, paleoclimate records, and spatial information. Purely genetic inference has limits, and the field is slowly acknowledging that. Programs like phyloNet and methods for testing reticulate evolution are becoming more accessible. Hybridization and introgression, once treated as noise or edge cases, are now recognized as fundamental drivers of evolutionary change in many groups. The practical implication is that the toolbox is larger and more fragmented than at any point in the last thirty years. Pick your methods carefully. Validate with simulations. Report uncertainty. And don't trust a migration estimate that doesn't make sense given what you already know about the species' biology.