Most People Get HR Analytics Completely Wrong Before They Even Start
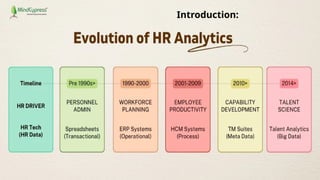
I spent about seven years wrestling with people data before something finally clicked. The early days of HR analytics were defined by spreadsheet hell. You had headcount models in one file, turnover analysis in another, and compensation data that nobody trusted. The best-case scenario was an afternoon wrestling match between three different exports and a pivot table that broke every time someone added a new row. We called it progress. It wasn't. What changed everything wasn't a single tool. It was the convergence of better data infrastructure, proper people analytics frameworks, and platforms that actually connected recruitment to retention to performance instead of keeping everything in silos. That's the real evolution nobody talks about enough. The field moved from reporting what happened to predicting what will happen, then to prescribing actions you can take about it. Most companies are still stuck at step one, which is why their analytics dashboards look impressive and mean absolutely nothing.
The Evolution Of HR Analytics How Cps Hr4u Is Revolutionizing The Field
CPS HR4U entered this space at a point where the market was already cluttered with half-baked solutions promising AI-driven insights while basically just wrapping Excel in a dashboard. What differentiated their approach was that they treated HR analytics as a full pipeline problem, not a reporting problem. The platform connects workforce data from multiple sources, applies actual statistical modeling instead of threshold-based alerts, and surfaces predictions with confidence intervals so you know when the model is guessing versus when it has signal. That last part matters more than people realize. I've been running predictive turnover models for the past three years and the first version using basic logistic regression on attrition data performed about as well as you'd expect. Eighty-four percent accuracy on historical data, then dropped to sixty-one percent when I tried to apply it prospectively. The model had learned the office politics, not the risk factors. People leaving were leaving because their manager transferred departments, not because of comp ratio or tenure or any of the standard variables. A properly configured analytics pipeline catches that through interaction effects and feature engineering that most off-the-shelf tools skip entirely. That's where structured platforms like HR4U make a measurable difference. They force the data through cleaner transformations and surface which variables actually matter versus which ones your dashboard happens to track because it always has. Here is the practical workflow I use now. You start by defining the outcome variable you actually care about, not the one that's easiest to pull. Predicting voluntary turnover within ninety days is useful. Predicting any separation within a year is noise. Once you lock that down, you pull six months of historical data across ATS, HRIS, and performance systems. Then you clean it. Most people skip this and wonder why their model is garbage. Duplicate employee records from system merges, inconsistent job codes between departments, managers who get reassigned and lose their title history. These errors compound fast. I write a data validation script that flags anything outside expected ranges before it enters the model. It takes about forty-five minutes for the first run and saves me from pulling my hair out later.
Feature selection is where people get stuck. You don't need twenty variables. You need the five or six that actually predict the outcome in your specific organization. Engagement scores from pulse surveys show up everywhere in analytics literature but in practice they're often too noisy and too late. Tenure, recent performance rating changes, promotion eligibility status, and internal transfer history tend to be more predictive. The exact mix varies by company. There's no universal formula. I run a correlation matrix, then use a decision tree to identify non-linear relationships, then validate with cross-validation before feeding anything into the final model. One thing nobody tells you about deployment: the model is the easy part. Getting actual managers to act on the output is the hard part. I learned this the hard way when I built a flight risk score for a mid-size company and presented it to twelve department heads. Five of them asked how to fire the high-risk people faster. Two wanted to hide the scores from their direct reports. Only one had a retention budget. The system worked perfectly. The organization wasn't ready for it. I ended up simplifying the output to a quarterly risk overview instead of real-time alerts and shifted the audience from frontline managers to HR business partners who actually had influence. Accuracy went from zero action to measurable retention improvement within six months. The platform side of this has also matured significantly. Real-time dashboards used to require dedicated SQL knowledge and about two weeks of setup time per report. Now you can connect standard HR systems, select your metrics, and have a working dashboard in under an hour. Custom scoring models used to need a data scientist on retainer. Today most enterprise platforms include pre-built predictive templates that you can customize without writing code. The tradeoff is that customization has limits. When your organization has unusual compensation structures, multiple acquisition integrations, or non-standard leave policies, the out-of-the-box models will miss nuance. That's when you need either a deeper configuration layer or a custom build, both of which cost more time and money than most HR budgets account for.
Get the Full Details
If you are starting from zero, here is the order I recommend. Get your data clean first. One good source is worth more than five messy ones. Then pick one outcome to predict. Voluntary turnover or internal mobility are the most common starting points. Build a baseline model with whatever tools you have access to, even if it's just a spreadsheet with logistic regression. Understand what drives the predictions before you invest in a platform. Then evaluate tools like CPS HR4U against your actual needs, not the feature list. Look at how they handle data integration with your specific systems, whether their modeling supports your prediction horizon, and what the ongoing maintenance looks like. A platform that requires weekly manual updates defeats the purpose. The biggest mistake I see is treating this as a technology purchase rather than a capability build. The tool doesn't create analytics maturity. It amplifies whatever process you already have. If you don't understand your own attrition patterns, a fancy prediction engine will just generate more confident garbage. Start small, validate your assumptions with real data, then scale. The people analytics teams that actually move the needle are the ones that spent the first six months just learning their own data before they tried to predict anything.