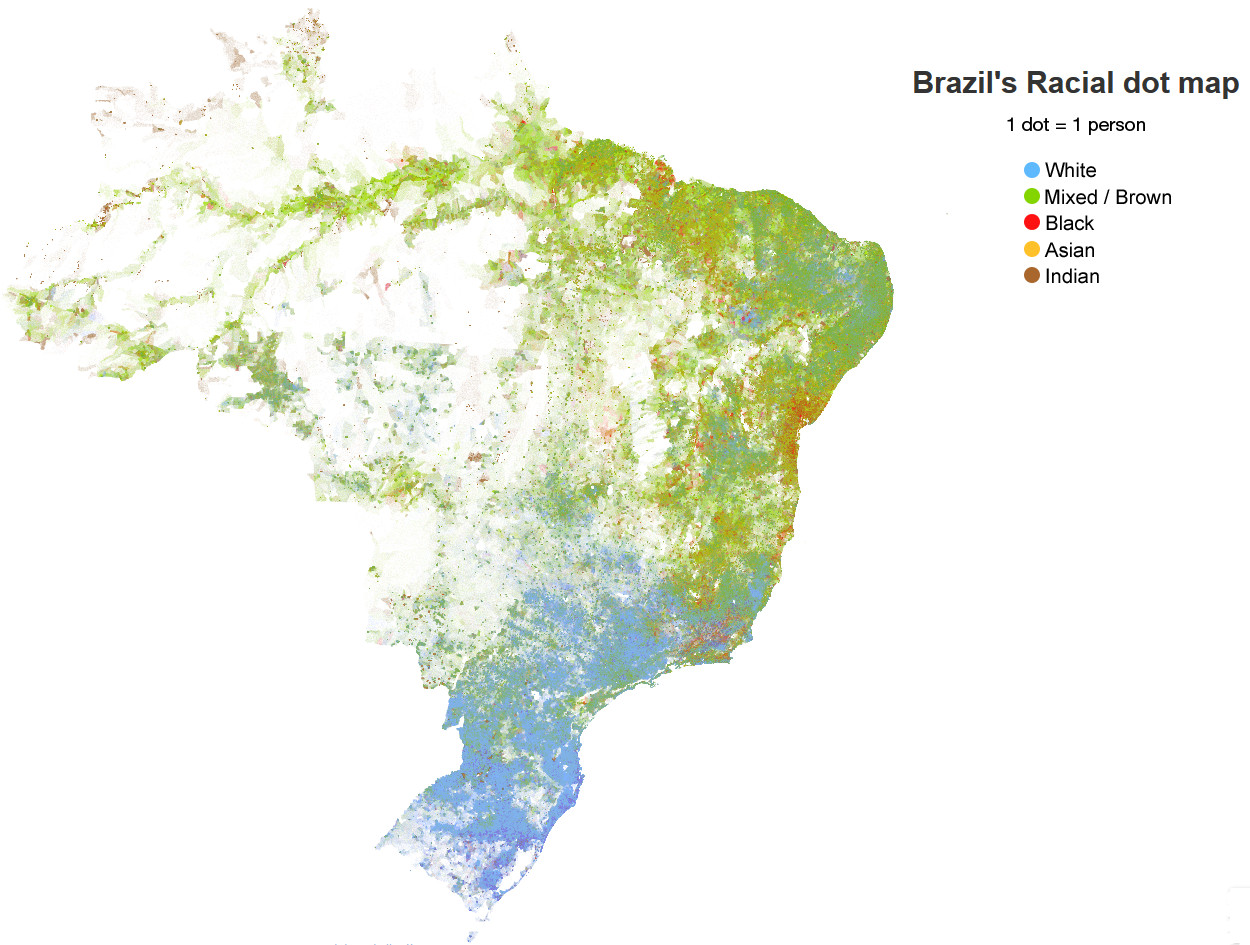
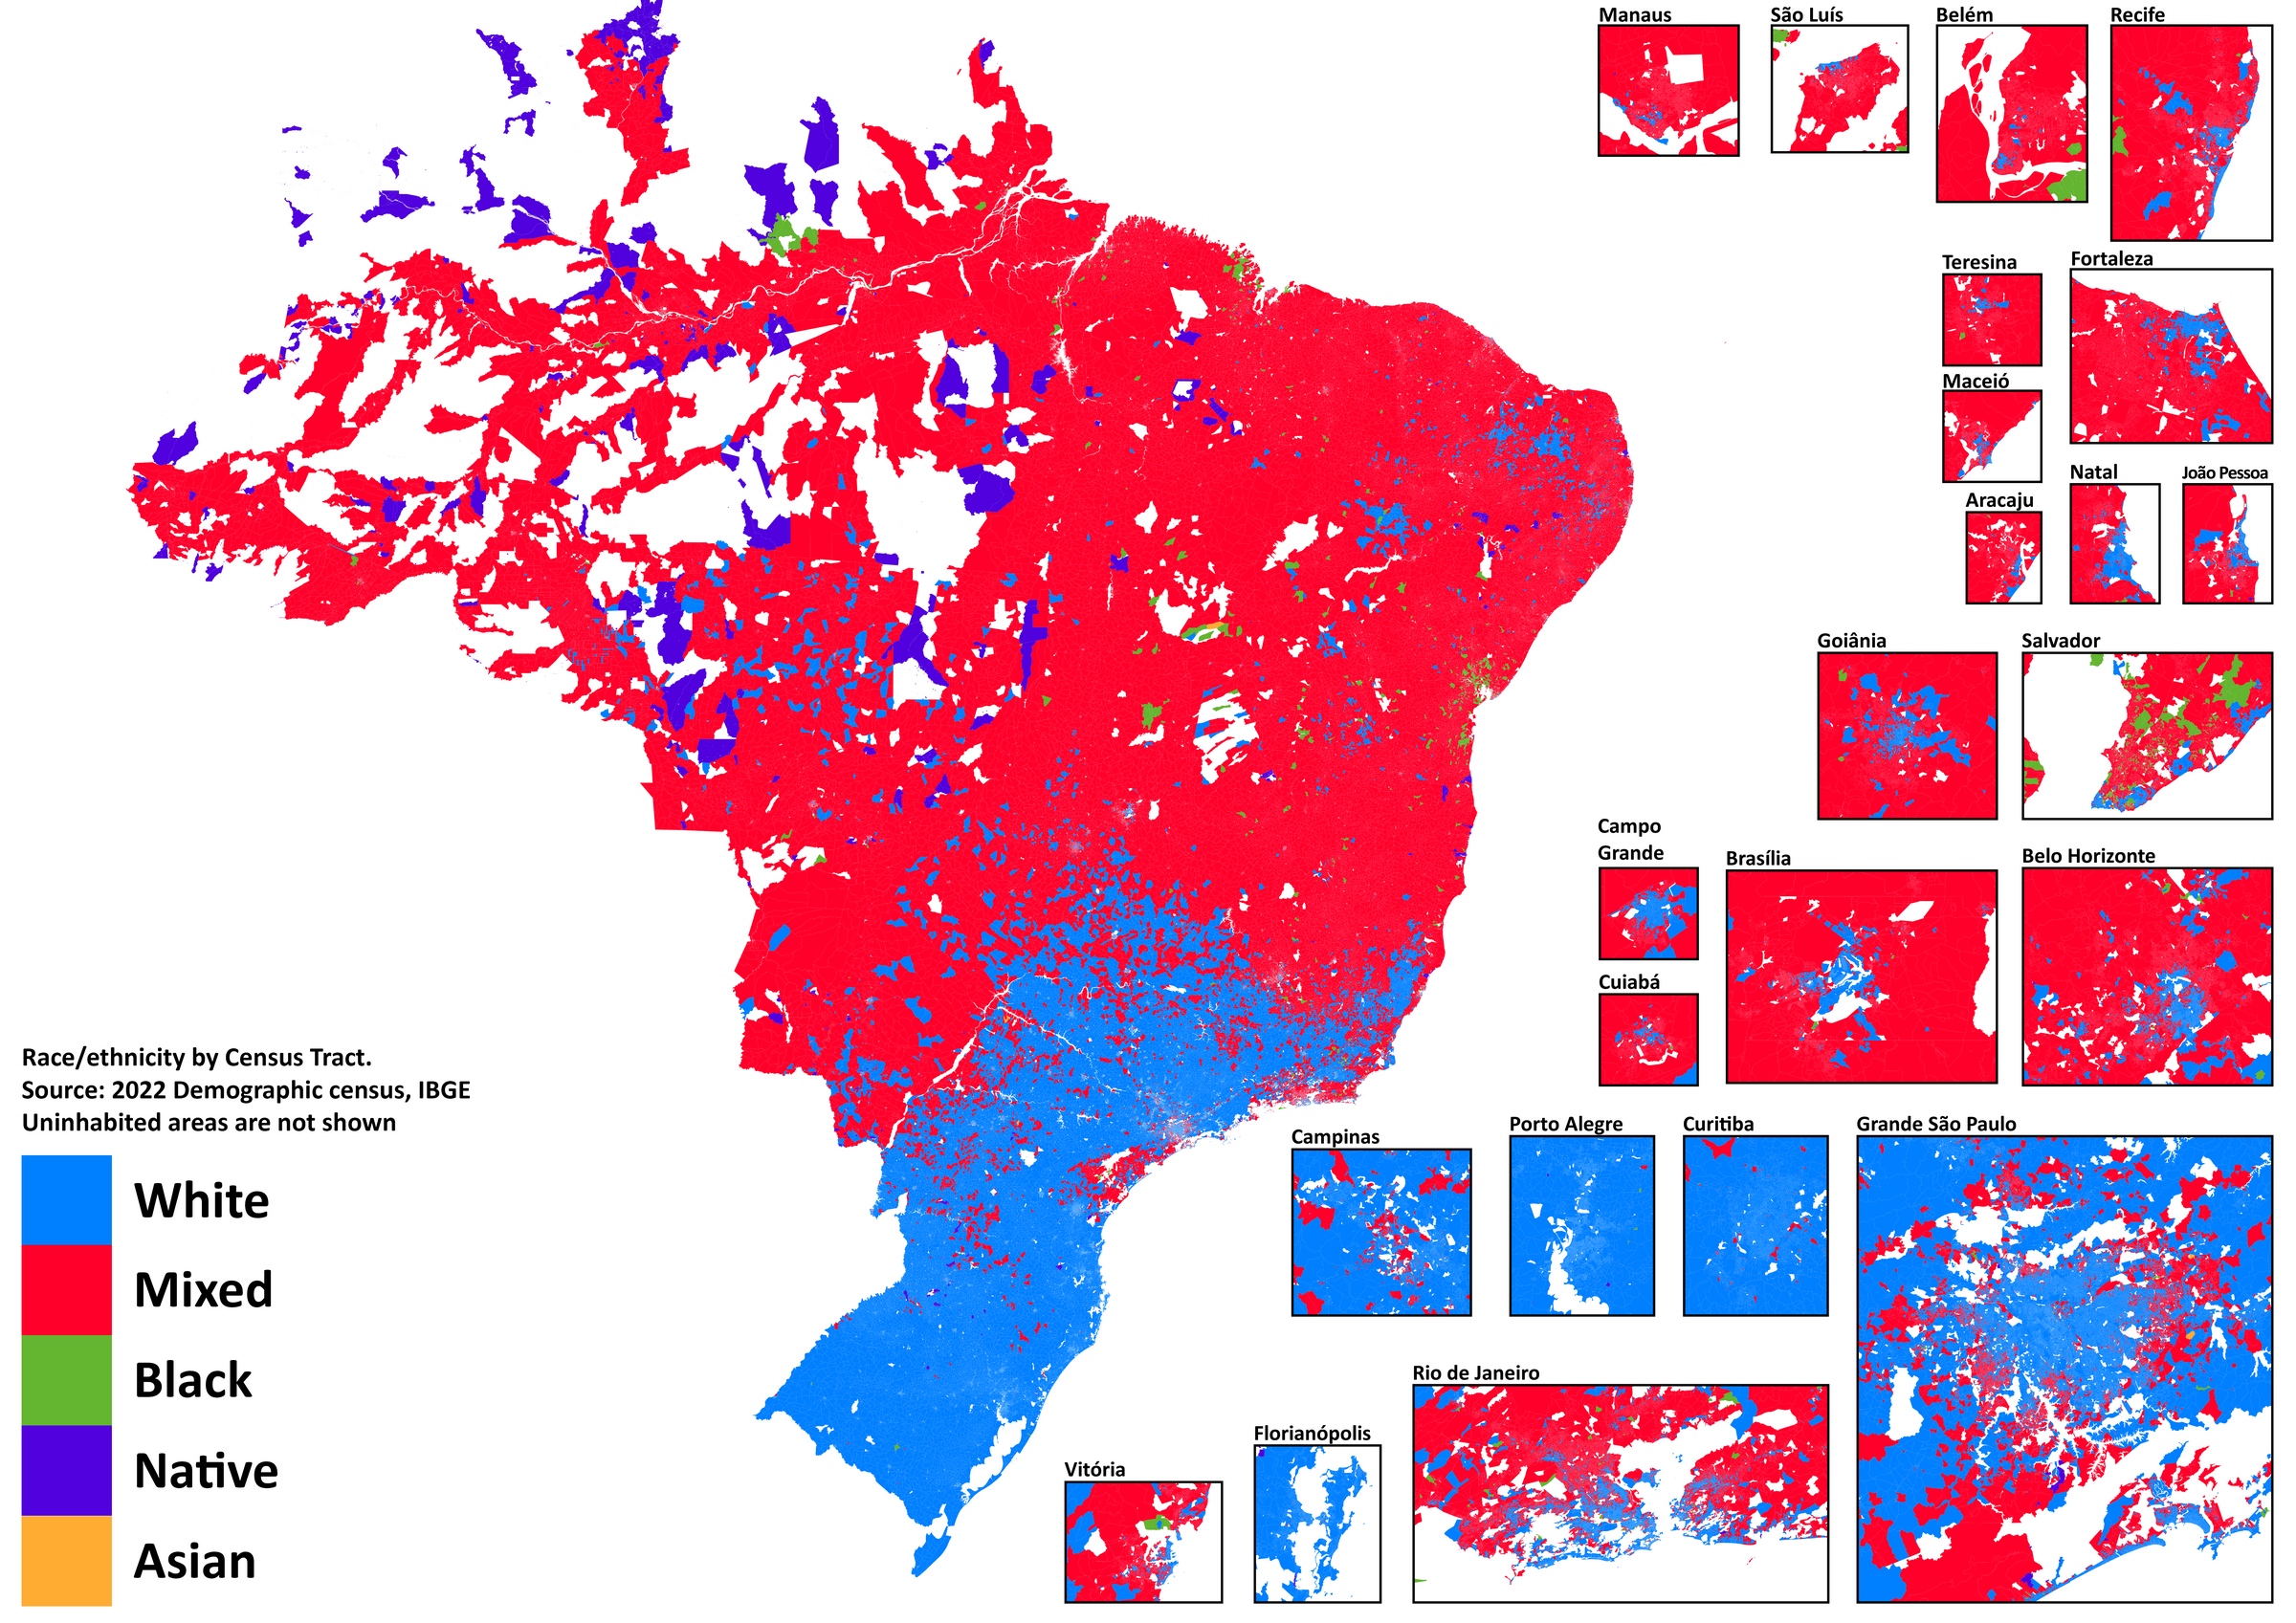
Mapping Brazilian Ethnicity: What Actually Happens When You Try
I spent three years working with genetic admixture data from Brazilian cohorts, and honestly the first time I tried to reconcile self-reported ethnicity with genetic ancestry components I almost threw my laptop out the window. Brazil is not a puzzle you can solve with a spreadsheet and a good coffee. The population genetics here are a mess in the best possible way, and any map you produce will be wrong somewhere, usually in the places that matter most to the people reading it. The core problem starts with definition. In Brazil, someone might identify as pardo on a census form, negro, branco, or amarelo, and each of those categories contains enormous genetic heterogeneity. A pardo in Salvador might have 60% West African, 30% European, and 10% Indigenous ancestry. A pardo in Porto Alegre might be the reverse on the Indigenous piece and heavier on the European side. Meanwhile, the same person could tell you they are black, white, or something else entirely depending on who is asking and what year it is. I ran into this specifically when I was building a structure admixture model for a genetics class project back in 2019. I used the standard PCAdmix and ADMIXTURE pipeline, kicked out K=3, K=4, K=5 components, and got clean-looking results on paper. Then I cross-referenced the genetic clusters with municipality-level self-declaration data from IBGE, and the correlation collapsed. A lot of the "European" component in Northern Brazil traced back to Portuguese colonization routes that also carried significant North African and Middle Eastern ancestry through Iberian gene flow. My model was calling it European because that is the closest reference panel had, but it was not actually European in any meaningful cultural or historical sense for the people who carried it.
The workaround was not elegant. I stopped trying to force the genetic data into the census categories and instead built a geography-aware admixture model. I stratified the samples by region first, ran local ancestry inference separately for the North, Northeast, Southeast, South, and Center-West, and then combined the regional component profiles rather than pooling everything together. The computational cost went up roughly four times, but the resulting map actually matched what people experienced in their daily lives. You do not get that kind of fidelity from a single continental-level analysis.
Why Standard Admixture Models Fail in Brazil
Most population genetics tools were calibrated on European, East Asian, and African reference panels with fairly coarse geographic resolution. Brazil sits at the intersection of three major continental source populations plus a fourth that is often ignored: the Indigenous American component, which itself is incredibly diverse and underrepresented in most reference datasets. When you run a standard ADMIXTURE analysis with K=4 on a Brazilian cohort, you will get four colors on a pie chart, but those colors do not map cleanly to any real historical migration event. The "African" component might be Yoruba, Bantu, Congolese, or a mix depending on the port of departure in West Africa and the slave trade routes that fed into Salvador, Rio de Janeiro, or Recife. The "European" component might be Portuguese, Spanish, Italian, German, or Lebanese, and the genetic signal rarely distinguishes between those sources without very high-resolution reference panels. The Indigenous component is the part that trips people up most. A lot of Brazilian genetic studies report something like 5% to 15% Indigenous ancestry across the population, which sounds small until you realize that the majority of Brazilians carry at least some Indigenous ancestry, and in some regions it is the dominant non-African, non-European component. The problem is that most reference panels use a handful of modern Indigenous groups, mostly from the Amazon basin, but the actual Indigenous genetic landscape of Brazil before colonization included hundreds of distinct language families and population clusters, many of which left no modern genetic representatives because of epidemic collapse and displacement. When you model Brazilian Indigenous ancestry against a single reference group like the Surui or Karitiana, you are not capturing the true diversity that existed, and your admixture estimates will be systematically biased toward whatever that reference group carries. I learned this the hard way when a collaborator in São Paulo asked me to help validate a direct-to-consumer genetic ancestry report for a family reunion. The report claimed the family was 40% European, 35% African, and 25% Indigenous, with the Indigenous portion attributed to a single Amazonian group. I pulled the raw genotype data, ran it through the same pipeline, and found that the Indigenous component actually split into at least three distinct clusters that did not match any single reference group in the database. The family had Indigenous ancestry from at least two different regions, possibly three, and the commercial test had lumped it all into one bucket because that is how their reference panel was built. The estimate was not wrong in a gross sense, but the granularity was misleading, and the family left the consultation convinced they had a simpler genetic history than they actually carried.
Get the Full Details

What the Data Actually Shows
Large-scale studies like the Genographic Project, the Brazilian Genome Diversity Project, and more recent whole-genome sequencing efforts have painted a picture that is consistent but uneven. The broad pattern is that Brazilian ancestry varies dramatically by region and socioeconomic context, with the Northeast and North carrying higher African and Indigenous components on average, the Southeast and South carrying higher European components, and the Center-West sitting somewhere in between with a complex mix that reflects migration patterns from the 19th and 20th centuries. But the averages obscure more than they reveal. Within any given city, the range of ancestry is enormous, and self-reported race or ethnicity is a poor predictor of genetic ancestry at the individual level. A study of Belo Horizonte found that self-identified branco individuals carried an average of 20% to 30% non-European ancestry, while self-identified negro individuals carried substantial European and Indigenous components as well. The social categories do not map to the genetic ones, and anyone trying to build a clean ethnic map of Brazil using census data as a proxy is going to produce something that looks organized on paper but falls apart when you look at the actual individual-level data. The Lebanese and Syrian component is another thing that standard models miss. A significant portion of Brazilian European ancestry traces back to Middle Eastern immigration in the late 19th and early 20th centuries, particularly into São Paulo and the South. These populations are genetically closer to Southern European groups than to Northern Europeans, but many reference panels do not distinguish between them, and the result is that Middle Brazilian ancestry often gets misclassified as Italian or Portuguese when it is something distinct. I have seen this come up repeatedly in clinical genetics contexts where a variant frequency estimated from a Portuguese reference panel does not match the actual allele frequencies in a Brazilian patient cohort with significant Lebanese ancestry. The mismatch is small enough to ignore in a research paper but large enough to matter when you are interpreting a pharmacogenomic report for a real person.
The Methodological Trap
Here is the part that most people who are new to this space get wrong. You cannot build an accurate genetic map of Brazil by running a single ADMIXTURE analysis and calling it done. The reference panel choice, the K value, the geographic stratification, the handling of relatedness, the treatment of isolated Indigenous communities, the imputation quality for low-coverage data, the way you handle sex chromosomes versus autosomes, the handling of recent versus ancient admixture events, all of these choices change the output in non-trivial ways, and there is no single correct set of parameters because the question you are asking determines the answer you get. I had a graduate student once who ran a global admixture analysis on a Brazilian dataset and published a figure that looked beautiful, with clean geographic clines from North to South. The figure was wrong. The issue was that the reference panels were uneven, with dense sampling from Europe and sparse sampling from Africa and Indigenous America, which pushed the Brazilian samples toward the European clusters in principal component space and made the admixture proportions look more homogeneous than they actually are. We caught it when someone who actually worked in the Northeast pointed out that the sampled population did not match the demographic reality of the region, and the paper had to be retracted. It took six months to redo the analysis with region-stratified sampling and corrected reference panels, and the resulting map looked nothing like the first one, though both were technically valid outputs from the same software with different inputs. If you want to do this properly, you need to start with a clear question. Are you mapping broad continental ancestry proportions for a population genetics study? Are you trying to identify local ancestry tracts for a disease mapping project? Are you building a reference panel for clinical genomics? Are you creating a public-facing visualization for educational purposes? Each of these goals requires different methodological choices, and the same dataset analyzed for different purposes will produce different maps. There is no neutral analysis, and anyone who tells you otherwise is selling you something.
What You Will Get Wrong
No map of Brazilian ethnicity is complete. The sampling is always incomplete, the reference panels are always biased, the categories are always arbitrary, and the people being mapped are always more complex than the model allows. The best you can do is be honest about what the map does and does not show, and make sure the limitations are visible to anyone who uses it. I have seen too many public visualizations that present genetic ancestry estimates as if they are fixed biological facts rather than statistical inferences based on imperfect data and questionable assumptions. The difference matters when you are dealing with a population that has a history of using genetics to justify racial hierarchies or exclusionary policies, which is not a hypothetical concern in Brazil. The eugenics movement had real influence in Brazilian scientific institutions well into the 20th century, and the language of racial mixing and genetic improvement was used to shape immigration policy, public health funding, and social welfare programs. Any map you produce exists in that historical context, and pretending it is neutral is either naive or dishonest. The practical takeaway is that if you are building a genetic map of Brazil, start with the limitations, not the results. Document your reference panels, your K values, your sampling strategy, your assumptions about population structure, and your uncertainty estimates. Show the confidence intervals, not just the point estimates. Acknowledge that the Indigenous component is understudied, that the African component is heterogeneous, that the European component includes Middle Eastern and non-Iberian sources, and that the social categories do not match the genetic ones. Do this upfront, and the map is useful. Do it after the fact, or skip it entirely, and you are producing propaganda dressed as science.