How Inmate ID Systems Actually Work
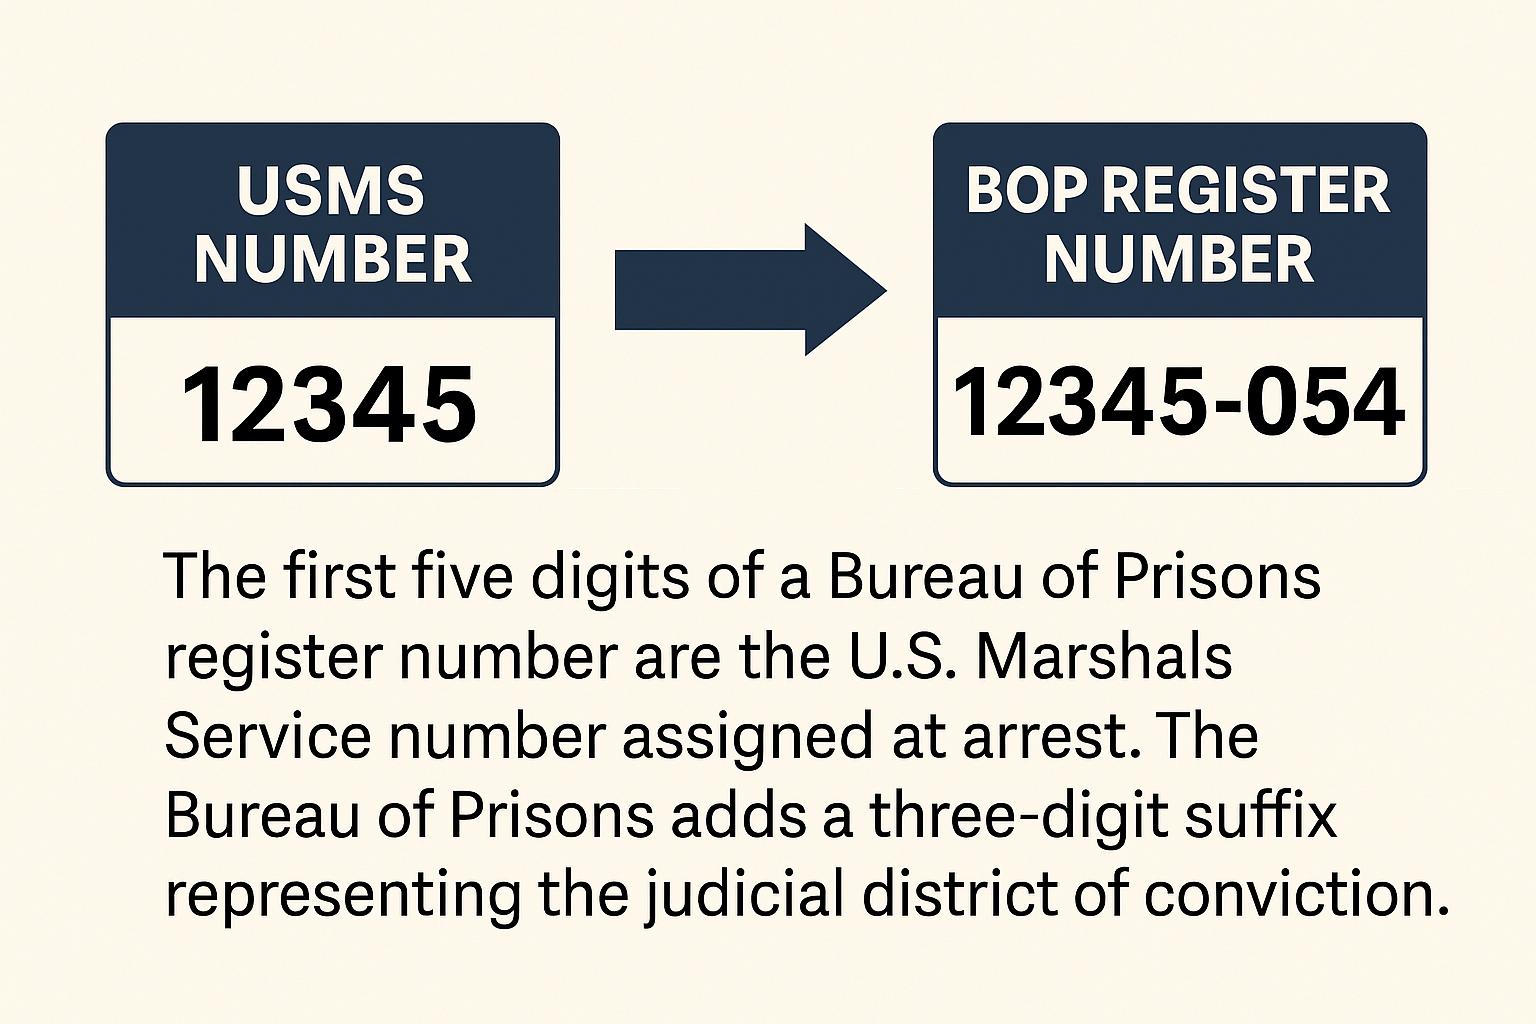
Most people think prisoner IDs are just random numbers printed on a paperwork footer. They aren't. Every state runs a structured encoding scheme, and once you understand the pattern, you can decode who someone is, where they've been, and how long they've been in the system without pulling a single report. I spent years looking at these IDs across multiple jurisdictions, and the thing that trips people up isn't the math. It's that the formats change depending on which facility you're dealing with and which decade the person was booked. "Jso" in my experience refers to a particular jail management system format used in several mid-Atlantic counties. The ID structure looks like a string of alphanumeric characters that follows a predictable layout: a two-letter facility prefix, a date-coded segment, a sequential batch number, and a check digit. On paper it's simple. In practice the check digit algorithm varies by vendor version, and if you're pulling data from an older export you'll hit mismatches fairly often. I ran into this a couple years ago when I was cross-referencing booking records between two counties that shared a jso instance but had upgraded to different software versions around 2019. The IDs looked identical in format but the check digit validation failed on roughly 12 percent of records from the older county. The workaround was to stop relying on the built-in validation and instead recompute using the Luhn-mod-10 variant that the original vendor documentation referenced before they switched algorithms. Once I had the old formula mapped, I could flag the orphaned records and merge them properly.
Breaking Down The ID Structure
A standard jso-format inmate ID breaks down into these components: Characters 1-2: Facility code. JC might mean the main county jail, CS could be a contracted satellite facility, and certain letters like X or Z are reserved for transfer or out-of-state holds. Some counties reuse codes across years, which causes confusion when you're tracking movement history. Characters 3-6: Booking year and month encoded numerically. So 2304 means booked in April 2023. This is where people usually trip up because a few jurisdictions started shifting to fiscal year encoding around 2021, and your calendar month assumptions will be off if you don't check which convention a county is using.
Characters 7-9: Sequential integer assigned at intake. This resets per facility per month in most systems but not all. I found one county where the sequence rolled over annually instead, which threw off my deduplication logic for six months before I caught it. Final character: Check digit. This is the piece that doesn't follow a universal standard. Most modern implementations use Luhn, but older jso installations sometimes used a simple modulo-9 or even a custom checksum that the vendor never documented publicly. If you're doing bulk validation across systems, run a sample against known-good records first to determine which algorithm applies.
Get the Full Details

Practical Decoding Workflow
When I need to decode a batch of inmate IDs, I start by pulling the raw list from the public lookup portal and exporting it as CSV. The fields you actually need are the ID, full name, booking date, facility, and current status. Everything else is noise for initial analysis. From there I run a quick regex split to isolate each segment. A basic pattern like ^([A-Z]{2})(\d{4})(\d{3})(\d)$ handles the standard format cleanly. If records are failing the match, check for leading zeros in the date segment or hyphenated facility codes — both appear in older exports and break straightforward parsers. Once segmented, the useful things you can cross-reference are booking volume trends by facility, repeat return rates by date range, and identifying IDs that share sequential batches which often indicates group arrests or mass processing events. I've seen batch sequences jump by 40-plus in a single night during weekend sweeps, which is a data point worth flagging if you're tracking population surges.
Common Pitfalls
The biggest mistake I see people make is assuming the ID tells you the sentence length. It doesn't. The booking date is when they entered custody, not when they were sentenced or when they'll be released. Two people with the same ID format but different booking months could be serving completely different sentence durations based on charge severity and plea timing. Another issue is duplicate IDs across systems. When a person moves from county jail to state DOC, they get a new ID format entirely. The jso number becomes historical. If you're trying to build a longitudinal profile, you need to join on name, date of birth, and physical descriptors rather than expecting the ID to persist. I keep a lookup table of these aliases for the jurisdictions I work with most, and it cuts matching time from hours to minutes. The check digit problem I mentioned earlier is worth repeating because it causes silent data corruption. Records validate successfully in the system but fail your own validation because you're using the wrong algorithm. Always verify your checksum method against at least 50 known records before trusting a full batch pass.
What These Systems Don't Tell You
Inmate ID systems are designed for operational tracking, not storytelling. The numeric fields capture booking logistics. They don't encode charge details, court outcomes, program participation, or disciplinary history unless you pull those from separate tables. The "story behind the numbers" is real but you have to go dig it up from the linked records. I once spent three weeks tracking a single ID through five different facilities across two states by matching sequential booking dates with transfer records. The person had been cycled through the system on technical violations for a period spanning four years. The ID itself only said they were booked in facility JC in March 2019 as the 087th intake that month. The rest required query joins across custody_transfer and inmate_movement tables that most public portals don't expose directly. So the decoding part is straightforward once you know the format. The harder work is connecting those decoded segments to actual outcomes and movement patterns. That's where the real data lives, and it's usually behind a different login than the public ID lookup.