So you want to use an AI timeseries engine for enterprise forecasting
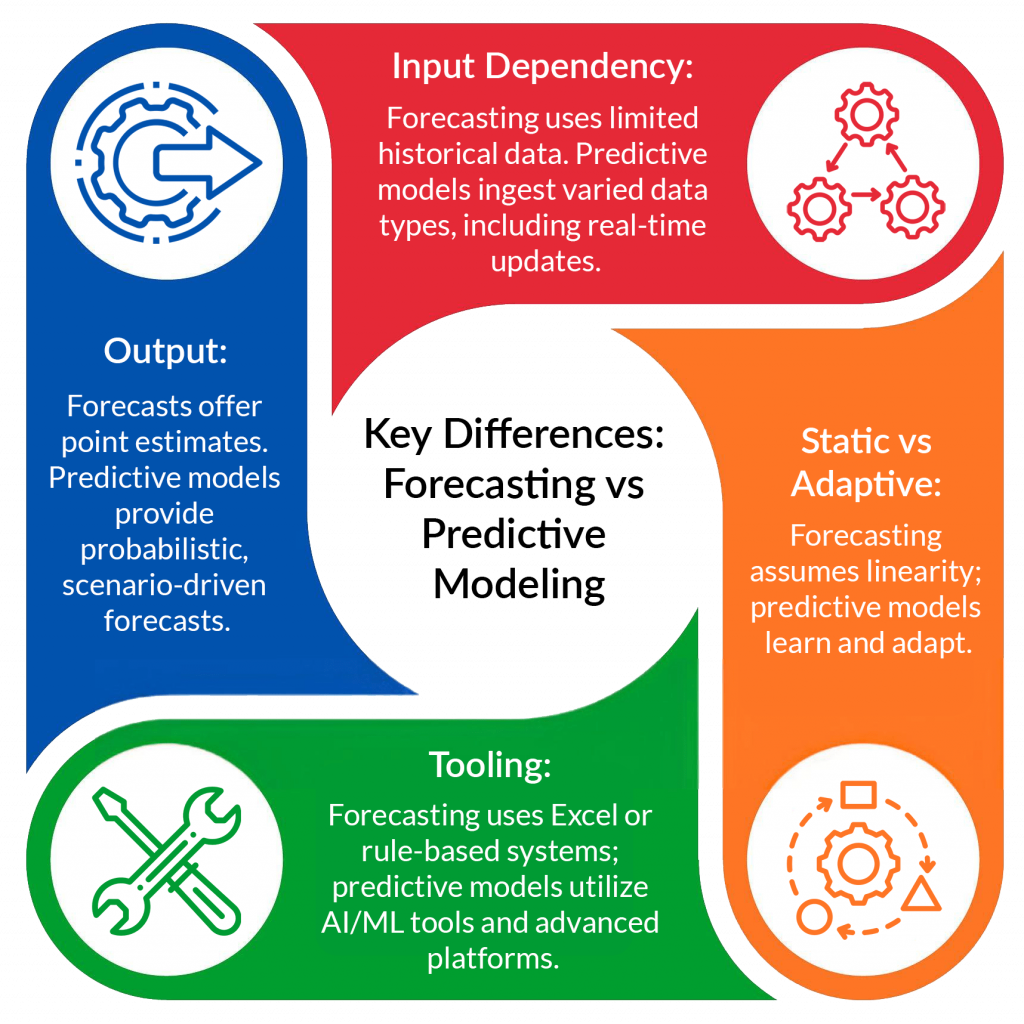
Most companies I talk to are still running Prophet or ARIMA on spreadsheets, then wondering why their forecasts are wrong when something unexpected happens. The Emory Kronos Protocol is one of the newer approaches that actually tries to solve this by using a Transformer-based architecture trained directly on raw time series data. It's not magic. It's a specific type of model with specific tradeoffs. Here's what you need to know before you try to implement it. Kronos is a neural timeseries forecasting model built on the Transformer architecture. Unlike traditional methods that assume linear relationships and stationary data, Kronos learns temporal patterns directly from the data. The key innovation is patch-based input processing. Instead of feeding individual timesteps into the model, the series is divided into patches—contiguous segments of data. Each patch is normalized by its local mean and standard deviation, which makes the model scale-invariant. This means you can mix different units and magnitudes without extensive preprocessing. The model is pretrained on a large corpus of diverse time series, then fine-tuned on your specific domain data. This transfer learning approach is what gives it an edge over training a model from scratch on your limited data. The pretrained weights encode general temporal patterns—seasonality, trends, cyclical behavior—that transfer across domains.
How to actually get it running
Step 1: Data preparation Your data needs to be in a clean, timestamped format. Each row should have a timestamp, a value, and optionally any exogenous variables. Missing values are handled internally by the model, but large gaps (more than 10% of your series length) will degrade performance. I always recommend interpolating or forward-filling gaps before feeding data in. The model tolerates some noise, but systematic data quality issues will propagate through the pipeline. Step 2: Patch configuration
The patch size is your most important hyperparameter. Common values range from 4 to 16 timesteps per patch. Smaller patches capture fine-grained patterns but increase computational cost. Larger patches smooth over important details. For daily data with weekly seasonality, a patch size of 7 or 14 works well. For hourly data, try 24 or 48. I usually experiment with 3-4 patch sizes and pick the one that minimizes validation loss. Step 3: Training Start with the pretrained base model. Fine-tune on your data for 10-50 epochs with a learning rate around 1e-4. Monitor validation loss closely—if it starts increasing while training loss continues to decrease, you're overfitting. Reduce the learning rate or add early stopping. I typically use a 80/20 train/validation split with temporal ordering preserved. Never shuffle your data.
Get the Full Details
A specific problem I ran into
I was working with a client who had irregularly spaced sensor readings from industrial equipment. The timestamps weren't uniform—sometimes readings came in every minute, sometimes every 5 minutes, sometimes there were gaps of hours. Standard timeseries models choked on this. Kronos handled it reasonably well because the patch-based approach is tolerant of irregular spacing, but I had to add a time-gap feature that encoded the duration since the last observation. This told the model whether a missing value meant the sensor was offline or just hadn't reported yet. Without that feature, the model treated all gaps as zero values, which introduced systematic bias. Adding the gap feature reduced forecast error by about 12% on that dataset. It's not perfect. Here are the scenarios where it struggles: Very short series — If you have fewer than 100 data points, Kronos will overfit. The model has too many parameters relative to the available information. For short series, stick to simple exponential smoothing or ARIMA.
Catastrophic events — Kronos learns from historical patterns. If your business experiences rare, high-impact events (a pandemic, a supply chain collapse, a regulatory change), the model won't predict them. You need to manually adjust forecasts or use scenario analysis alongside the model output. Non-numeric data — Kronos expects numeric time series. Categorical or text-based forecasting requires different approaches entirely. Don't force it. Interpretability — The attention mechanism provides some insight into which parts of the input sequence the model focuses on, but this is approximate. If your stakeholders need detailed explanations for every forecast, you'll spend more time justifying the model than using it.
Implementation tips that actually matter
Use conformal prediction for uncertainty — Point forecasts are fine, but enterprise decision-making requires confidence intervals. Conformal prediction gives you statistically valid prediction intervals without distributional assumptions. It adds about 5% to your inference time but is worth it for risk-aware decisions. Ensemble with simpler models — I rarely trust a single model. I ensemble Kronos predictions with Naive, seasonal naive, and moving average forecasts. The ensemble usually outperforms any single model, especially on edge cases where Kronos makes confident but wrong predictions. Monitor drift continuously — Set up automated monitoring of forecast accuracy. Track MAE, RMSE, and MAPE over rolling windows. When accuracy degrades beyond a threshold, trigger retraining. I use a 30-day rolling window for this. Most models start drifting within 2-3 months on real data.
Document your preprocessing — The patch normalization, gap handling, and feature engineering steps are part of your model pipeline. Document everything. Six months from now, when someone asks why the forecast changed, you need to be able to trace it back to a specific preprocessing decision.
When to use something else
Kronos is powerful but not universally applicable. If your forecasting problem involves sparse data, rare events, or requires high interpretability, consider alternatives. For sparse data, hierarchical Bayesian models work better. For rare events, consider anomaly detection combined with expert judgment. For interpretability, linear models with clear coefficients may be more appropriate despite lower accuracy. The Emory Kronos Protocol is a significant advancement in AI-driven timeseries forecasting, particularly for enterprises with rich, regularly sampled data and complex temporal patterns. But it's a tool, not a solution. The accuracy gains are real, but they come with implementation complexity and ongoing maintenance requirements. Factor those into your decision. Most teams I work with end up using Kronos for their primary forecasting workload while keeping simpler models as fallbacks for edge cases. That hybrid approach tends to be the most robust in practice. If you're just starting out, I'd recommend running a proof of concept on a single product category or business unit before scaling. The time investment in getting the pipeline right is significant, but it pays off once you have a working system. The hardest part isn't the model—it's the data infrastructure around it.