What You Actually Need To Know Before You Touch Your Data
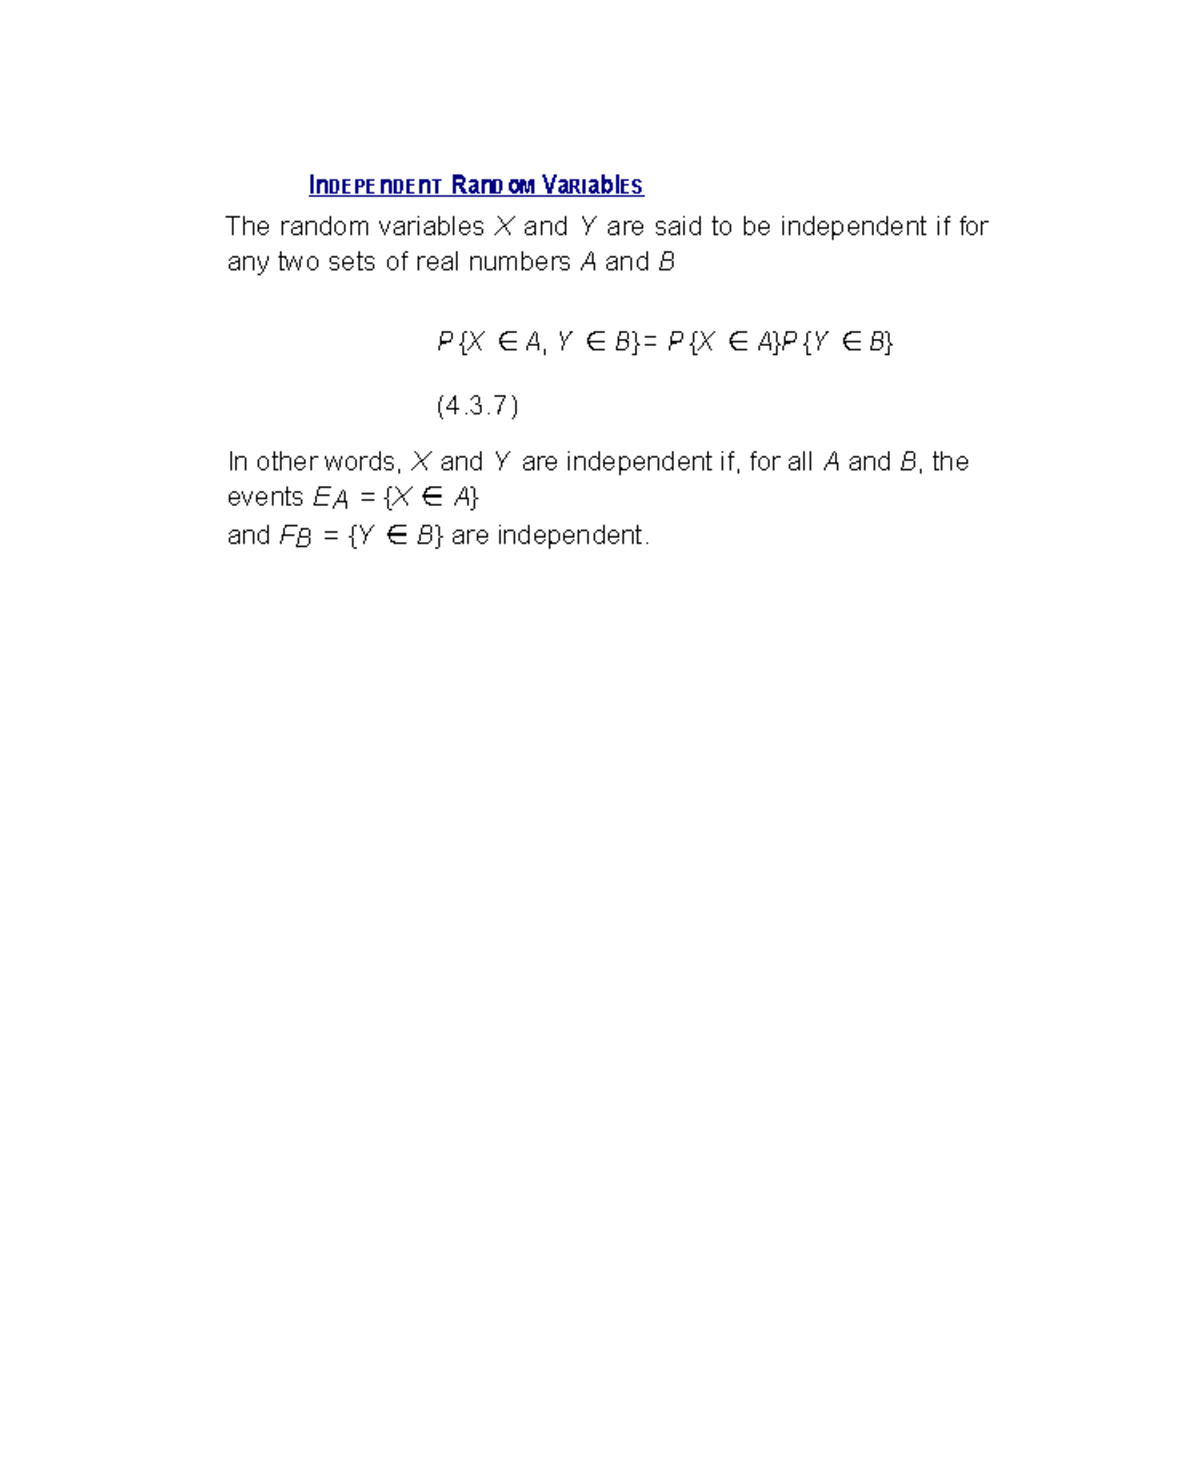
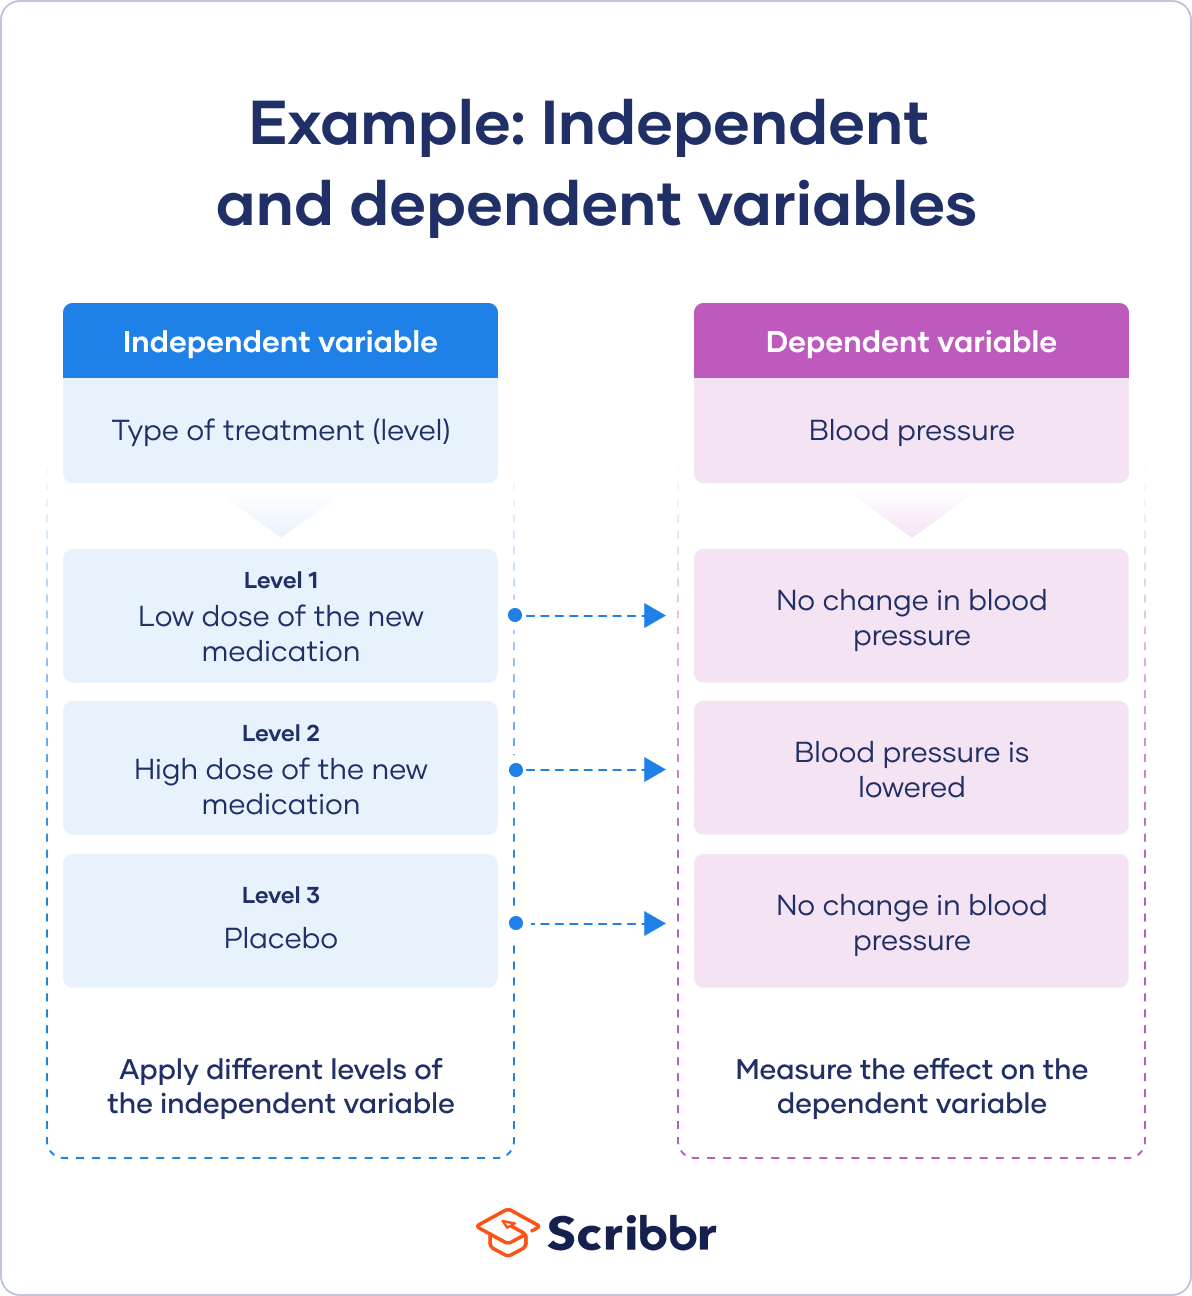
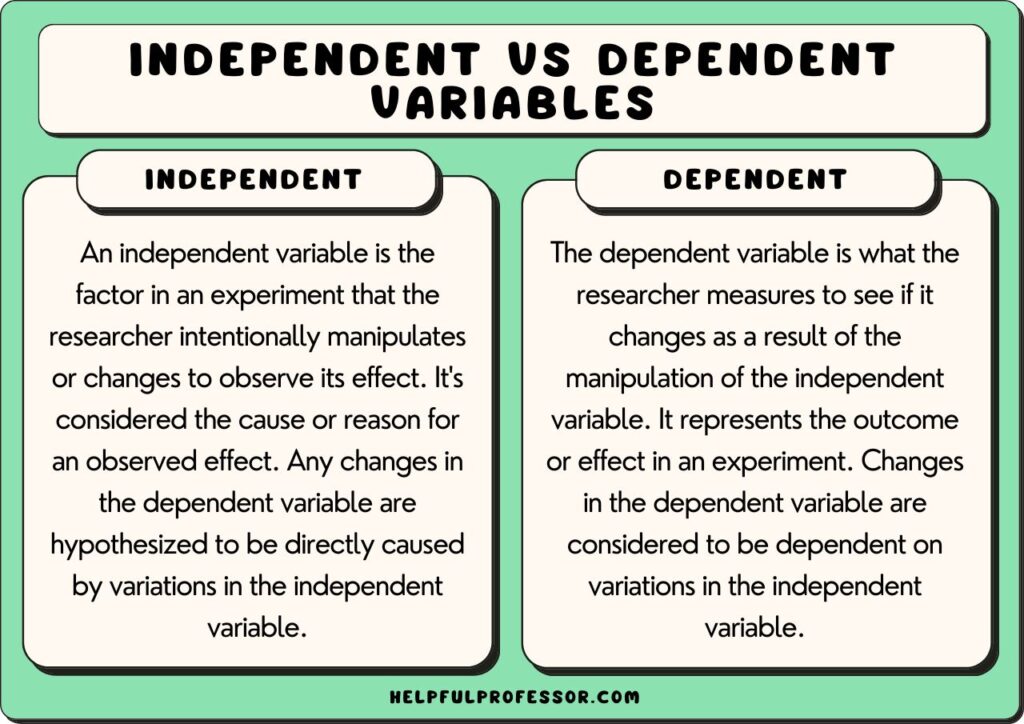
Independent variables are the inputs you deliberately change or measure in an experiment, and almost everyone gets them wrong at least once before they figure it out. I spent three weeks last year debugging a regression model that kept producing nonsense coefficients, and the root cause was that I had accidentally treated a derived variable as independent when it was actually a collider between two other factors. That mistake cost me about forty hours of work and a very tense conversation with my project lead. The basic idea is simple enough. You have a dependent variable that you want to explain, and one or more independent variables that you think might explain it. You hold everything else constant, vary the independent variable, and watch what happens to the dependent one. That is the ideal. Reality involves confounders, measurement error, and the occasional variable that looks independent but is actually determined by the outcome itself.
The Elusive X Unraveling The Mystery Of Independent Variables
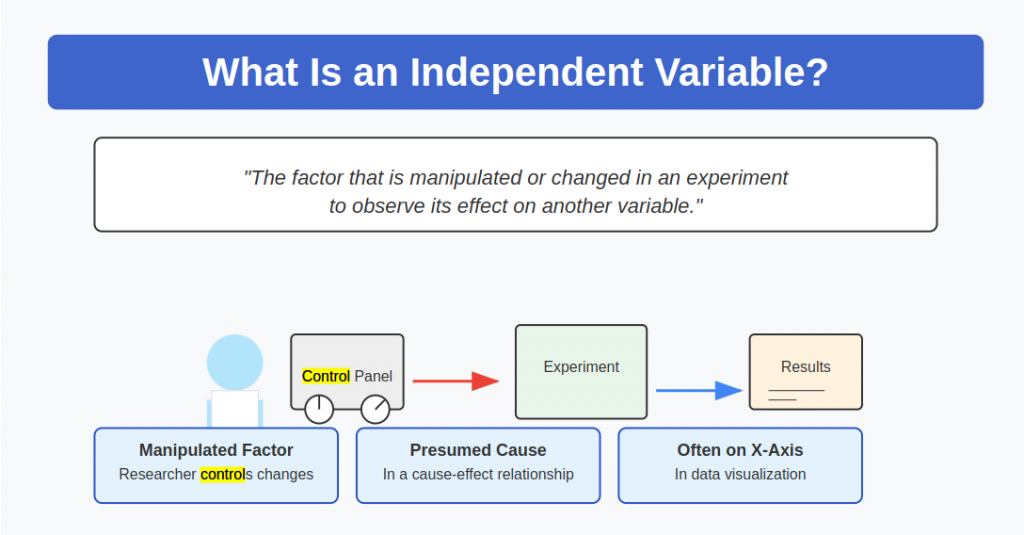
Here is how I approach identifying and setting up independent variables in practice, step by step, without the textbook nonsense. Step one: write down your causal question before you look at any data. This sounds obvious and nobody does it. If your question is whether advertising spend drives revenue, then ad spend is your independent variable and revenue is your dependent variable. If your question is whether revenue drives ad spend because your marketing team adjusts budgets based on quarterly earnings, you just reversed your causal direction and everything downstream is now wrong. Write the question on a piece of paper. Keep it there until the analysis is done. Step two: distinguish between manipulated and assigned independent variables. A manipulated independent variable is one you control directly, like setting temperature in a chemistry experiment. An assigned independent variable is one you observe rather than control, like a person's age or income level in a survey. Both count as independent variables, but the analysis methods and the strength of inference you can draw from them are completely different. With manipulated variables you can claim causation. With assigned variables you can usually only claim association unless you do something like instrumental variable analysis or difference-in-differences, which brings its own set of assumptions you need to justify.
Step three: check for hidden dependencies before you run any model. This is where I learned my collider mistake. A collider is a variable that is causally affected by two other variables. If you control for a collider in your analysis, you create a spurious association between its causes. In my case, I had included a middleman variable in my model that was being influenced by both the independent and dependent variables. The fix was to remove it and run a sensitivity analysis to confirm the coefficient estimates didn't shift dramatically. I used a DAG, or directed acyclic graph, to map out the relationships before and after. If you are not already drawing causal diagrams, you should be. It takes about ten minutes and saves you from making expensive mistakes. Step four: handle continuous and categorical variables appropriately. A continuous independent variable like hours studied can go straight into most regression models. A categorical one like treatment group needs dummy coding or effect coding depending on what question you are asking. If you have more than two categories, you need k-minus-one dummy variables. Forgetting that will either crash your model or silently give you the wrong reference group, and you will not notice until someone asks you a question you cannot answer. Step five: test for multicollinearity if you have multiple independent variables. When two or more independent variables are highly correlated with each other, your model struggles to separate their individual effects. The variance inflation factor, or VIF, is the standard diagnostic. A VIF above 5 is worth investigating. A VIF above 10 usually means your coefficient estimates are unreliable. The workaround is typically to drop one of the correlated variables, combine them into an index, or use regularization methods like ridge regression. Each option has tradeoffs in interpretability and predictive performance.
Get the Full Details

There are real limitations to treating independent variables as straightforward inputs. The biggest one is that observational data never fully resolves the question of which variable is actually driving what. You can control for observable confounders, but unobservable ones remain a threat to validity. Selection bias, reverse causality, and omitted variable bias will all bite you if you are not careful. No amount of p-hacking or model selection tricks will fix a fundamentally flawed causal identification strategy. Another practical issue is that independent variables measured with error will attenuate your coefficient estimates toward zero. This is called attenuation bias and it is especially problematic with self-reported data like income or survey-based health measures. If your independent variable has substantial measurement error, your estimated effect will be systematically smaller than the true effect. There are correction methods like instrumental variables and regression calibration, but they require strong assumptions that are often harder to defend than the original model. For anyone who wants to work through this themselves, R has the `lm` and `glm` functions for basic regression, the `car` package for VIF calculations, and the `dagitty` package for drawing and analyzing causal diagrams. Python users can use `statsmodels` for regression and `causalgraphicalmodels` for DAG work. Both ecosystems are well-documented and the learning curve is manageable if you start with simple cases before moving to anything involving interaction terms or hierarchical models.
The takeaway is not complicated. Define your causal question first. Draw your DAG. Check your variable types and dependencies. Run diagnostics. Acknowledge what your data cannot tell you. Independent variables are not mysterious, but treating them carelessly will produce results that look convincing and mean nothing.