Understanding How Both Strands of DNA Function in Real Molecular Work
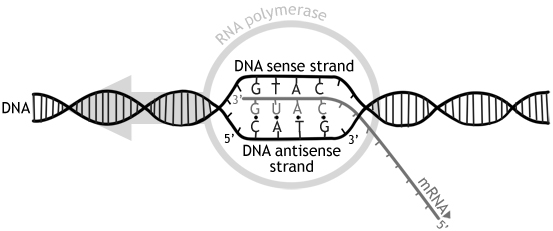
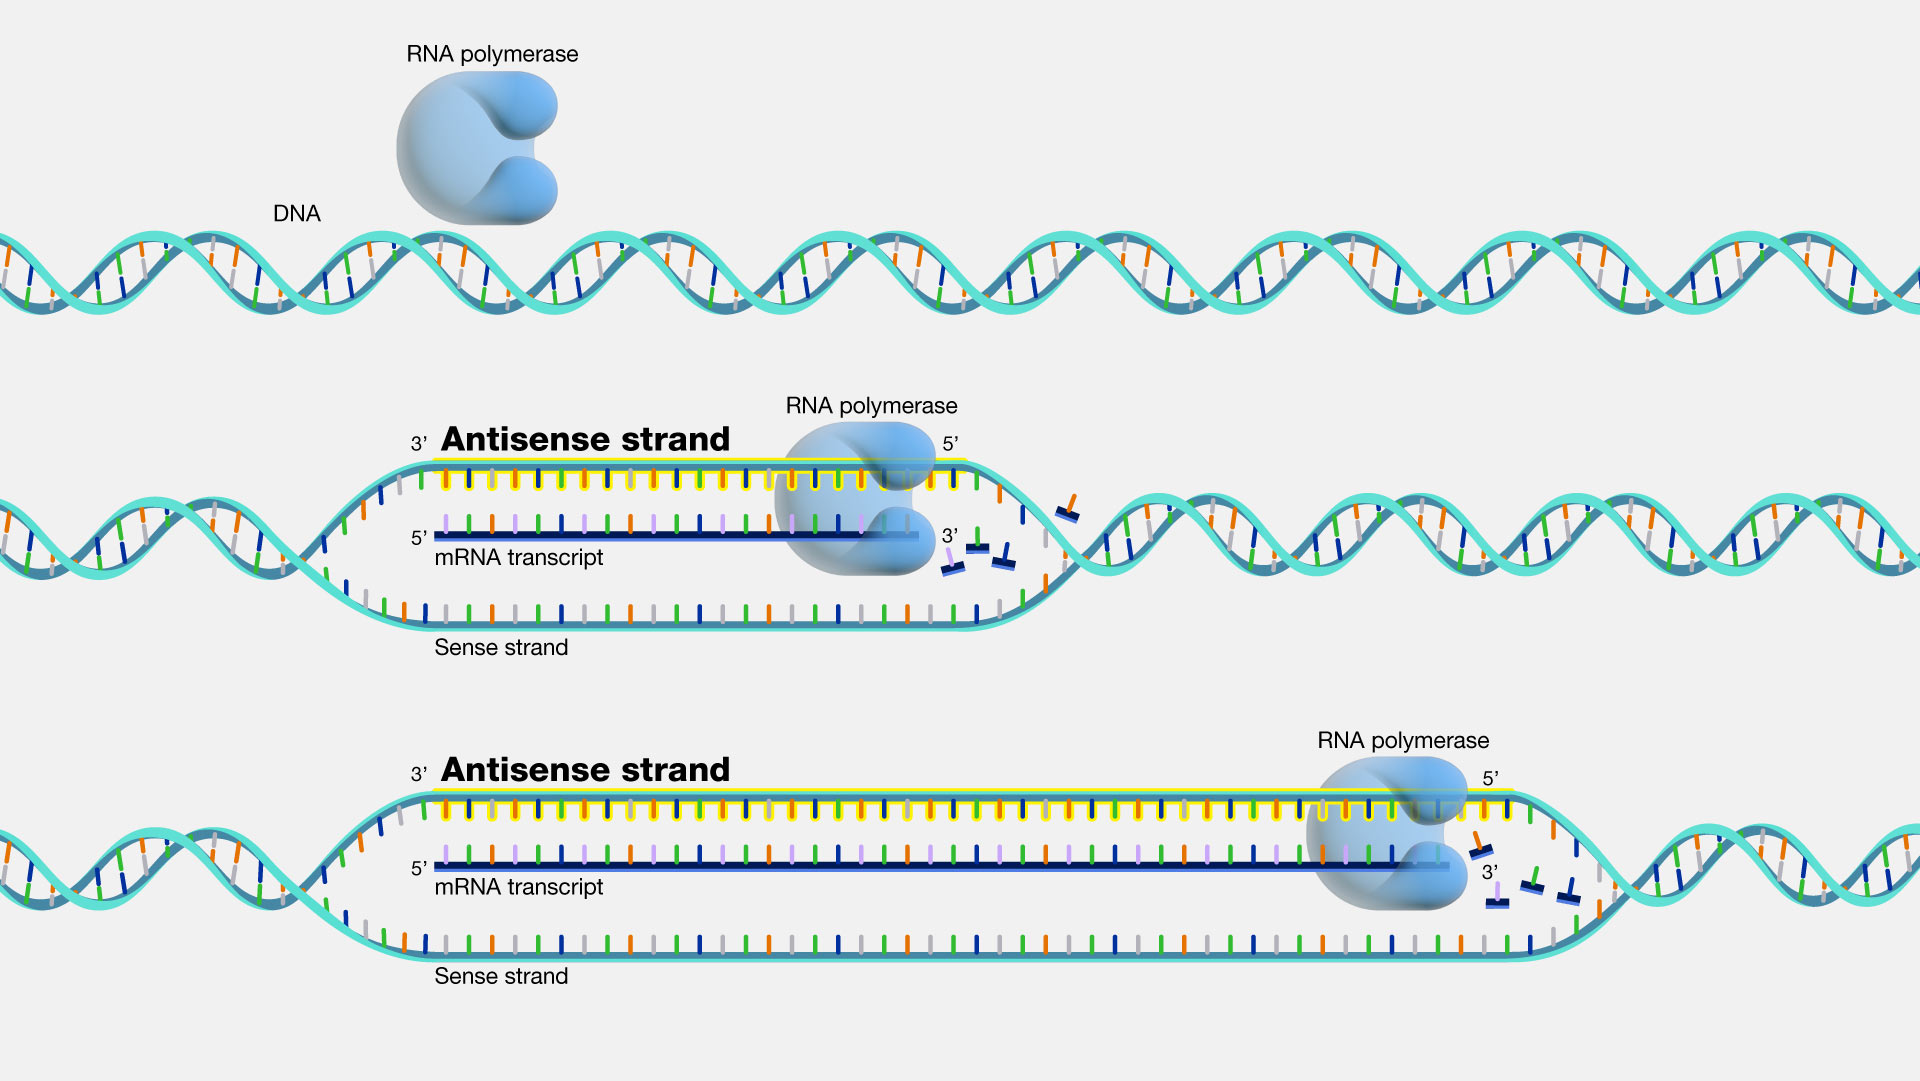
Most people learn that DNA is a double helix and that one strand codes for protein while the other doesn't. That's a simplified version of what happens in textbooks. The actual biology is messier, and if you've ever done RT-PCR or cloning, you know the sense and antisense distinction matters more than you might expect when you're designing primers or interpreting sequencing results. Let me get one thing straight about terminology first, because this is where a lot of people trip up. The "sense" strand of a gene is the one that has the same sequence as the resulting mRNA, except thymine replaces uracil. The "antisense" strand is the one that RNA polymerase actually reads during transcription. This isn't arbitrary — it's directional. DNA is read 3' to 5' on the template strand, and the new RNA grows 5' to 3'. So when we say sense or antisense, we're talking about which way the gene is oriented on the chromosome, not which one is more important. Here's a practical scenario I ran into last year that almost cost me two weeks of wasted bench time. I was working on a custom siRNA design for knocking down a specific human gene in a cell line. The gene in question was located on the negative strand of the genome, meaning the antisense strand was the template that RNA polymerase used. My initial primer design software labeled the coding sequence using the positive strand coordinates, and I ended up synthesizing the wrong siRNA duplex. It didn't work, obviously, because I was targeting the non-transcribed version of the sequence. I caught it when I ran a gel and the knockdown was completely absent. The fix was to flip my reference sequence and redesign using the actual transcribed strand as my guide. I learned to always verify strand orientation against Ensembl or NCBI's gene model before ordering anything.
The deeper insight most people miss is that both strands can be transcribed simultaneously in many regions of the genome. This isn't a rare exception. Large-scale transcriptome studies have shown that antisense transcription is widespread across the human genome, and in some cases it's functionally relevant. There are natural antisense transcripts that regulate their sense counterparts through various mechanisms — things like transcriptional interference, RNA masking, or recruitment of chromatin modifiers to the locus. This means the concept of a single gene having one sense and one antisense strand is more of a convenient model than a complete description of reality. When you're working in a lab setting, here's how the practical workflow looks. You clone a gene into an expression vector, and you need to make sure the insert is oriented correctly. If you put the sense strand in backwards, you'll either get no protein or you'll get the antisense RNA, which might be transcribed if your promoter is bidirectional or if there's read-through from adjacent elements. The standard check is a colony PCR using a forward primer that matches the 5' end of your insert and a reverse primer in the vector backbone. Then you run it on a gel. The band should match the expected size. If you're feeling unsure, sequence the clone. It takes about a day and saves you from wondering why your Western blot is coming back blank for three weeks. Another thing that trips people up is the terminology around "antisense oligonucleotides." These are synthetic single-stranded DNA or RNA molecules designed to bind to a target mRNA. They're called antisense because they're complementary to the sense mRNA strand. The mechanism involves RNase H cleavage when the oligo binds, which degrades the mRNA and prevents translation. This is a legitimate therapeutic approach used in drugs like nusinersen for spinal muscular atrophy. The challenge with these molecules isn't just design, it's delivery. Naked antisense oligos get degraded quickly in serum, so you need chemical modifications like phosphorothioate backbones or 2'-O-methyl sugars to stabilize them. That adds cost and complexity to the synthesis.
I should be blunt about the limitations here. The sense-antisense model works beautifully for protein-coding genes in bacteria and simple eukaryotic systems. It breaks down when you look at complex eukaryotic genomes with extensive non-coding transcription, overlapping genes, and strand-specific regulatory networks. If you're doing RNA-seq analysis, you absolutely must use a stranded library preparation protocol. Non-stranded RNA-seq will give you ambiguous read assignments in regions where both strands are transcribed, and you'll misquantify expression levels for overlapping genes. Stranded protocols add maybe 20 percent to the library prep time but they're essential for accurate data. The cost difference is roughly $50 to $100 per sample depending on your platform. For those who need to access reference sequences, the primary databases are freely available. NCBI's GenBank provides complete genomic sequences with feature tables that explicitly annotate which strand each gene occupies. You can download FASTA files for any sense or antisense region using the NCBI FTP site. The Entrez Direct command-line tools let you pull sequences by gene ID in a script. For example, querying a gene record gives you the strand information directly in the FEATURE table, so you know immediately whether the coding sequence is on the plus or minus strand. Ensembl similarly provides GTF files that encode strand orientation for every annotated transcript. There's also a practical consideration when you're dealing with viral sequences. Some viruses use ambisense strategies where parts of the genome are encoded on one strand and parts on the other. Influenza viruses have segmented genomes with negative-sense RNA, meaning their genomic RNA is equivalent to antisense and must be converted to sense mRNA by the viral polymerase before any protein can be made. This is completely different from the host cell's transcription machinery, and it's a frequent source of confusion when people first work with viral vectors or do virology experiments. You need to design your cloning strategy around the viral polymerase's directionality, not the cellular one.
Get the Full Details

If you're starting out and want to get comfortable with this, I'd recommend downloading a known gene from NCBI, looking at its genomic coordinates and strand orientation, then aligning the mRNA sequence to the genomic DNA to see how the introns are spliced. Do this for a gene on the positive strand and one on the negative strand. The patterns are identical in terms of splicing but opposite in terms of sequence orientation. After you've done it three or four times, the concept stops being abstract and starts being a normal part of how you read genetic data. It usually takes about an hour to complete the exercise properly, and you'll retain it longer than any textbook explanation will give you.