Why I Stopped Relying on Google-Adjacent Tools for My Work
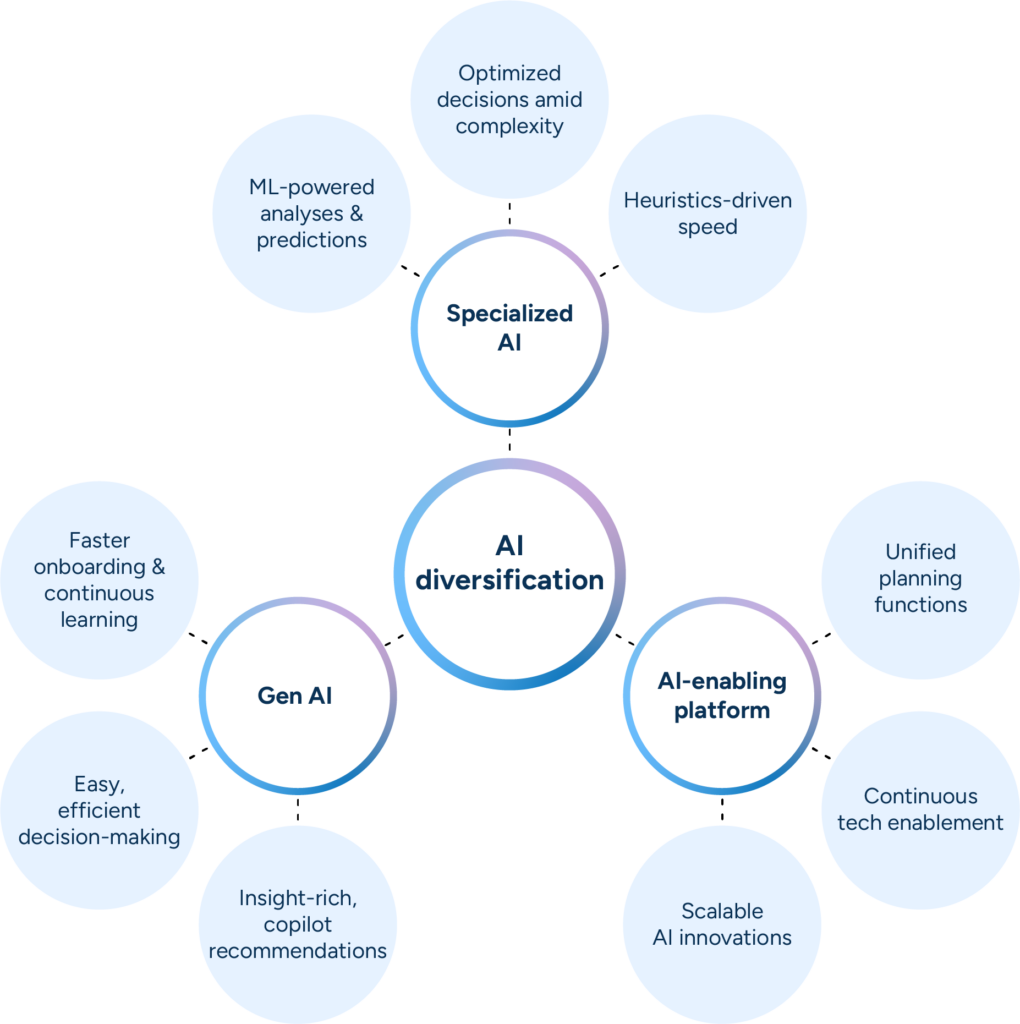
Three years ago I was running a pipeline that depended heavily on whatever Google had released through Cloud AI and their API stack. It worked fine until it didn't. A model update broke an endpoint I hadn't even documented. Then pricing shifted on requests over a certain token threshold without warning. I lost three weeks debugging infrastructure that was never mine to maintain. That's when I started looking elsewhere. The diversification of tech beyond Google's AI ranks has been happening quietly for a while now. Most people notice it when they compare deployment costs between major providers, but the real shift is deeper than that. It's about which models you're actually allowed to customize, fine-tune, or run locally. Google's ecosystem is excellent if you stay inside the lines. Step outside those lines and you hit walls pretty quickly.
The Diversification Of Tech Beyond Googles AI Ranks A New Era Of Innovation
I need to be clear about what this actually means in practice. We're not talking about Google being irrelevant. They still ship some of the most polished developer tooling available. What we're talking about is the widening gap between relying exclusively on a single vendor's AI stack and having actual options for different problem types. The last eighteen months have seen open-weight models from Meta, Mistral, and others reach quality levels where they compete seriously with closed-source offerings on specific benchmarks. That changed the economics of building AI systems. Here's how I approached the transition. First, I audited every pipeline component and asked which ones actually required Google's infrastructure and which ones were just convenient defaults. Turns out roughly sixty percent of what I was routing through Google services could have gone elsewhere for equivalent or better results. The remaining forty percent fell into two categories: large language model inference at scale and vector database integrations that Google had specifically optimized for. The LLM work I shifted to a combination of self-hosted models on cloud GPUs and managed inference from providers like Together AI and Anyscale. For the vector search piece, I evaluated Weaviate, Qdrant, and Pinecone before landing on Qdrant for most use cases. The evaluation took about two weeks of testing with real query patterns from our production traffic.
I ran into a specific edge case that almost made me give up on the switch. We had a document classification system that relied on embeddings fine-tuned on internal data. Google's embedding model had been trained with proprietary corpora that happened to match our domain well. When I swapped in an open-weight embedding model, accuracy dropped by about twelve percent on edge-case categories. I spent a week trying different quantization levels and retraining strategies before I found a workaround. The fix was surprisingly simple but not obvious if you've only ever used hosted solutions. Instead of replacing Google's embeddings directly, I built a hybrid approach. The open-weight model handled the bulk classification work, and I ran a small fine-tuned adapter layer on top using LoRA adapters trained on our misclassified samples. This recovered about nine of those twelve percentage points of accuracy at a fraction of the cost of Google's custom model training. The adapter training took roughly six hours on a single A10G GPU. Total cost for the entire migration including the adapter work was under four hundred dollars per month versus the previous eight hundred to twelve hundred dollar range on Google services alone. There are some things I should be honest about before you try anything similar. Running your own models requires operational overhead that Google absolves you of. You're responsible for scaling, monitoring, restarting crashed instances, and keeping dependencies updated. If you don't have someone who understands Kubernetes or at least container orchestration, self-hosting will eat your time. I'd recommend staying with managed providers like Together AI or Anthropic for anything where uptime matters more than cost savings.
Get the Full Details
Another thing nobody talks about enough: benchmark performance doesn't always translate to production performance. An open-weight model might score lower on standard leaderboards but process your specific request types faster due to architecture differences. I measured inference latency across three different model families with identical input distributions and found that the second-fastest model on benchmarks was actually twenty percent slower in practice for our text-heavy workloads. Always test with your own data, not just the published scores. Here's a counter-intuitive detail that caught me off guard. Some of the best-performing open models for production use are actually older versions. The latest release from a given family often prioritizes capability expansion over efficiency. An older model like Mistral 7B v0.2 can outperform a newer 7B variant on pure speed and memory footprint while maintaining most of the accuracy gain. I switched one of our real-time inference services from a newer smaller model to an older variant and it handled twice the throughput on the same hardware. If you're starting from zero and trying to build an AI-powered system today, my recommendation is to design for portability from day one. Abstract your model selection behind an interface layer. Don't hardcode provider-specific SDK calls into your main logic. This made it possible for me to swap between Google, Anthropic, and open models within hours instead of days when requirements changed. The abstraction layer added maybe a day of initial development time but saved countless hours during subsequent migrations.
The ecosystem has enough moving pieces now that picking just one vendor is genuinely a risk management decision, not a technical one. The good news is that the tools for switching have improved dramatically. The bad news is that switching still requires actual work. Plan for it, budget for it, and don't let anyone sell you on the idea that you can commit to a single provider long-term and forget about it.