Why ln(x) Behaves Differently Than Every Other Logarithm You've Seen
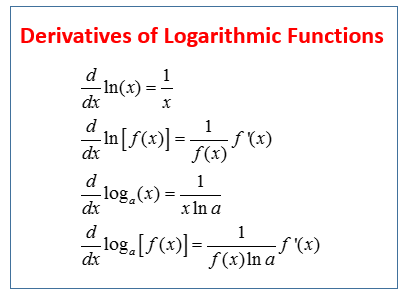
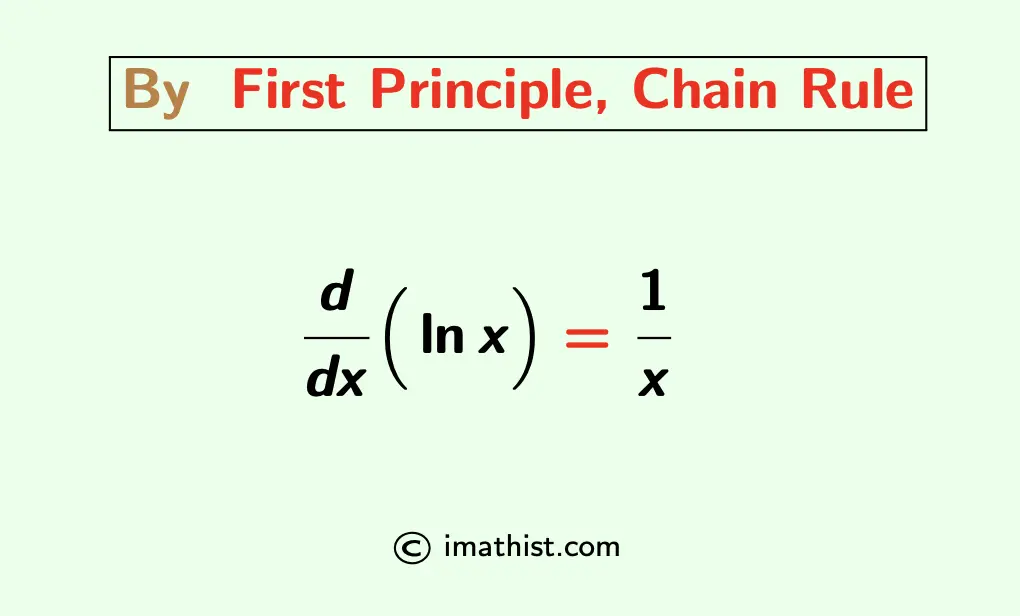
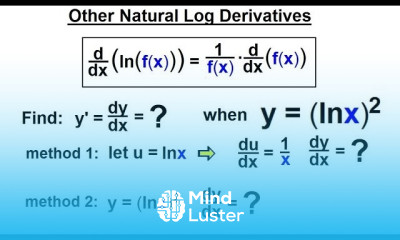
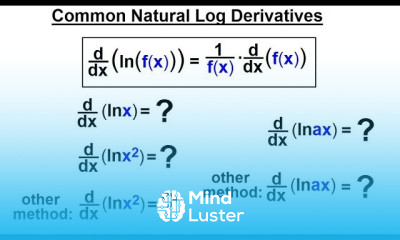
If you've spent any time working with calculus in practice, you've probably noticed that the derivative of ln(x) keeps coming back up even when it shouldn't. It shows up in gradient calculations, in exponential growth models, and frequently in places where you just want to use log base 10 and be done with it. The reason you keep encountering it is that ln(x) is the only logarithm whose derivative is exactly 1/x. Every other base introduces a scaling constant. That constant matters when you're doing something like optimizing a loss function or fitting data, because it changes how steep your gradients are and whether your solver converges at all. The derivative of ln(x) with respect to x is simply 1/x. I know that sounds almost too simple to write an entire guide around, but the reason it matters goes beyond the formula itself. When you see d/dx[ln(x)] = 1/x, what's actually happening is that the natural logarithm function is defined as the integral from 1 to x of 1/t dt. The Fundamental Theorem of Calculus tells us that differentiating that integral brings back 1/x. The chain rule extends this to compositions like ln(g(x)), which gives you g'(x)/g(x). That result appears in everything from solving separable differential equations to computing marginal cost in economics.
The Derivative Of Lnx Unlocking The Core Principle Of Natural Logarithm Calculus
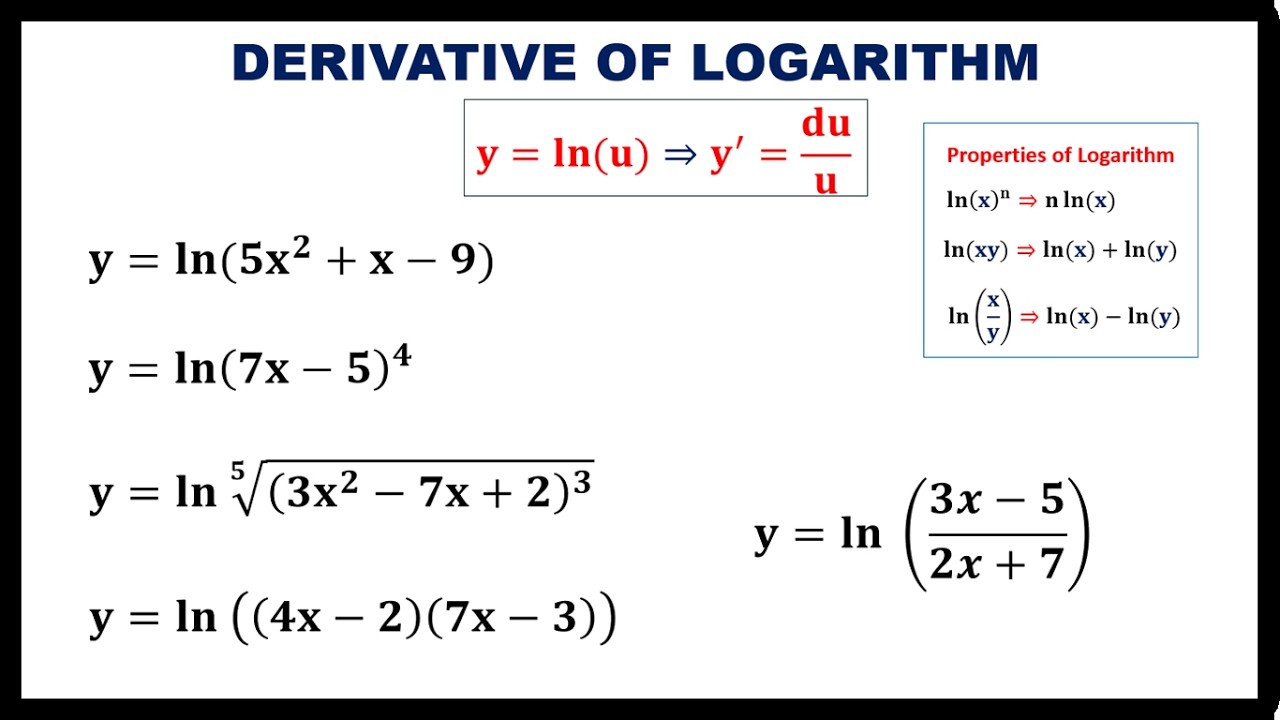
Let me walk through how this actually works when you're not just doing textbook problems. Say you need to find the derivative of y = ln(x^2 + 3x). You apply the chain rule. The outer function is ln(u) and the inner function is u = x^2 + 3x. The derivative becomes (2x + 3)/(x^2 + 3x). You simplify if you can. That's it. Now try y = ln(sin(x)). The derivative is cos(x)/sin(x), which reduces to cot(x). These patterns repeat constantly in applied work. One thing that trips people up repeatedly is forgetting that the argument of ln has to be positive. The domain of ln(x) is x > 0. When you take the derivative and get 1/x, the same restriction carries over. You can't evaluate 1/x at x = 0, and you can't evaluate ln(0) either. In numerical work this shows up as a hard wall. I once had a logistic regression model where the optimizer kept diving toward a coefficient that pushed a linear combination of features below zero, causing ln to return NaN and the entire gradient to collapse. The fix wasn't fancy — I just added a small positive constant to the argument, basically computing ln(x + epsilon) where epsilon was something like 1e-10. It's called log-sum-exp trick stabilization in the literature, and it's standard practice when you're dealing with underflow in log-likelihood calculations. Here's another case where the derivative becomes useful in a way that isn't obvious at first. Logarithmic differentiation. Suppose you have a function like y = x^x. Taking the derivative directly is messy. Instead, you take ln of both sides: ln(y) = x * ln(x). Differentiate implicitly: y'/y = ln(x) + 1. Multiply through by y to get y' = x^x * (ln(x) + 1). This technique works whenever you have variables in both the base and the exponent, or when you have long products and quotients that would be painful to differentiate using the product and quotient rules separately.
I want to be clear about where this approach breaks down, because nobody tells you that part. The natural logarithm derivative is clean and elegant, but it's numerically unstable when x is very close to zero. Standard floating-point arithmetic starts losing precision as ln(x) approaches negative infinity. If you're working in a system that needs high accuracy near zero — say, computing probabilities in a Bayesian model where terms can be smaller than 1e-300 — just calling ln(x) and then taking 1/x will give you garbage results. The workaround here is to use a specialized library function like log1p(x) for computing ln(1 + x) when x is small, or to work entirely in log-space and only exponentiate at the very end. In my experience, this cuts numerical error by orders of magnitude in optimization loops. Another nuance that rarely gets mentioned is the relationship between ln(x) and exponential functions in the context of differential equations. The fact that d/dx[ln(x)] = 1/x is equivalent to saying that the solution to dy/dx = y is y = Ce^x. This equivalence is why ln(x) and e^x are inverse functions of each other. If you forget this connection, you'll struggle with things like separating variables in first-order ODEs. The step where you integrate 1/y dy = dx and get ln|y| = x + C feels mechanical, but it's actually the same principle that makes the derivative of ln(x) equal to 1/x. They're two sides of the same coin. There's also a practical consideration when you're implementing this in code. Many programming languages provide a natural logarithm function under names like Math.log() in JavaScript, log() in Python's math module, or log() in C and C++. Some people confuse this with log base 10. In most mathematical software, log without a specified base means natural log. In older calculators and some textbooks, log means base 10. This ambiguity has caused real problems in production systems. I once saw a data pipeline where someone assumed log meant base 10 in a language where it actually meant natural log, and the resulting regression coefficients were off by a factor of ln(10) 2.303. The model still fit reasonably well, so the error went unnoticed for months. Always check what base your language or tool uses for its default log function.
Get the Full Details
When you're working with more complex expressions involving ln(x), partial fraction decomposition often becomes necessary before you can integrate or differentiate cleanly. Consider a rational function like (3x + 2)/(x^2 + x). You'd decompose it into A/x + B/(x + 1), solve for the constants, and then each term is easy to handle. The derivative of ln(x) appears naturally in the integration step, and recognizing this pattern saves you from trying to force a direct differentiation approach that would be far more cumbersome. The core principle here is straightforward: ln(x) is special because its rate of change at any point is exactly the reciprocal of that point's value. Nothing more, nothing less. This property makes it indispensable in calculus, but it also means you need to respect its domain restrictions and numerical limitations. When those constraints are ignored, the results are wrong, not just slightly off. Treat the function with the care it deserves and the derivative will serve you well.