Working With Genetic Variation Is Messier Than Textbooks Make It Look
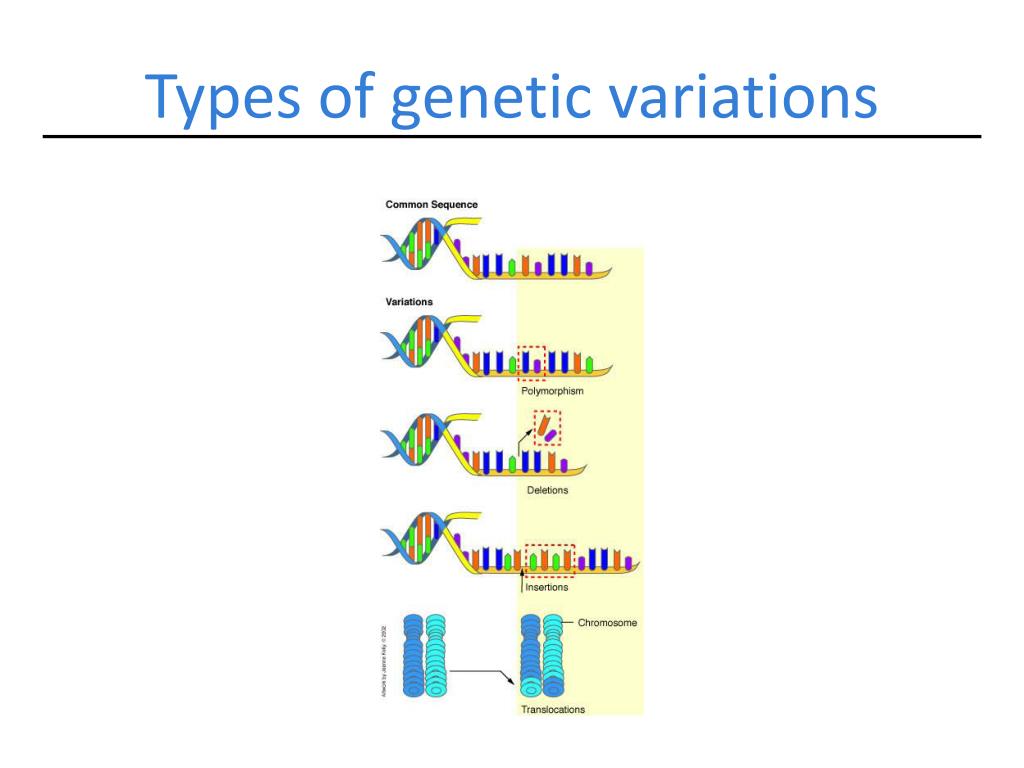
Genetic variation refers to any difference in the DNA sequence between individuals within a population or species. This includes single nucleotide changes, insertions, deletions, copy number variations, and structural rearrangements. That variation is what makes two people with similar ancestry look different, respond differently to the same drug, or carry different risks for disease. Most of it does nothing at all. That is important to keep in mind because people new to this area tend to overinterpret every variant they find. When you actually sit down to work with variation data, the first thing you notice is how uneven the coverage is across the genome. Some regions are sequenced cleanly. Others are so repetitive that even the best platforms struggle to place reads accurately. I spent three months on a project trying to call variants in a MHC region, and every pipeline I tried produced slightly different results. The workaround was running two callers independently — DeepVariant and GATK HaplotypeCaller — then taking the intersection of high-confidence calls. Anything only one caller found got flagged for manual review in IGV. That added about two days of work but saved us from publishing false positives. The second thing you learn is that the standard definition of what counts as a variant depends entirely on your question. In a clinical setting, you might care about missense and nonsense mutations in known disease genes. In an evolutionary biology context, neutral SNPs in intergenic regions are the useful data. Mixing those frameworks casually is a common beginner mistake. You end up comparing apples to orange and wondering why your results look wrong.
Here is something most introductory resources leave out: variation frequency cutoffs matter more than people realize. The 1 percent minor allele frequency threshold used in many studies is arbitrary. Some rare variants with real phenotypic effects sit just below that line. Conversely, some common variants are tagged by linkage disequilibrium with the causal mutation and are not causal themselves. When I was filtering a GWAS dataset last year, I pulled every variant above 0.5 percent allele frequency and cross-referenced it with expression quantitative trait locus data from GTEx. That alone narrowed the candidate list significantly without throwing away potentially relevant signals. Structural variation is another area where the standard toolkit falls short. Short-read sequencing misses a lot of large insertions, inversions, and translocations. If your study includes health-related traits, those gaps matter. Long-read technologies like PacBio HiFi and Oxford Nanopore have improved this considerably, but they are still expensive and require more DNA input. For many labs, the practical solution is a hybrid approach: use short reads for SNP calling and structural variant calling with a tool like Sniffles or cuteSV on long-read data from a subset of samples. Population stratification is the silent killer of association studies. If your case and control groups come from different ancestral backgrounds, you will find spurious associations simply because certain alleles are more common in one group than another. The fix is principal component analysis to identify and adjust for ancestry, followed by mixed-model approaches like BOLT-LMM that account for relatedness. I saw a published study once where the top hit was a variant near a pigmentation gene. The "disease association" was entirely driven by population structure. The authors had run a basic PCA but did not include enough PCs to fully correct for the stratification.
Functionally, most identified variants do not have a clear mechanism. annotation databases like ANNOVAR and VEP help, but they often report the same generic "missense variant of unknown significance" label for dozens of candidates. The real work comes after the variant calling pipeline finishes. You need to look at conservation scores, protein domain mappings, and splicing predictions. Combine CADD, REVEL, and SpliceAI scores and you get a much better picture than any single tool provides. Another hard truth: variant calling is not a one-size-fits-all process. The parameters that work for whole-exome sequencing in human samples will not work for RAD-seq data in non-model organisms. I once tried applying a human exome variant calling pipeline to a fish population study and got garbage results. The ploidy settings, reference genome quality, and coverage depth were completely wrong for the dataset. Retuning the pipeline with species-specific parameters brought the accuracy back to a reasonable level, but it took a day of trial and error to figure out which settings needed changing. Interpreting non-coding variation is probably the hardest part of this work. Regulatory regions, enhancers, and promoters are scattered throughout the genome and not well annotated in many species. Chromatin accessibility data and ATAC-seq can help pinpoint functional non-coding regions, but not every lab has the budget for that. As a rough workaround, I sometimes use RegulomeDB scores or ENCODE chromatin state annotations as a filter before diving deeper into candidate variants.
Get the Full Details
The biggest bottleneck in the field right now is probably the gap between variant discovery and biological meaning. We can find variants cheaply and quickly. Understanding what they do is still slow and expensive. Single-cell approaches and CRISPR screening are closing that gap, but they add cost and complexity. Until those methods become routine, the practical workflow remains: call variants, filter aggressively, prioritize by functional annotation, validate with an orthogonal method, and interpret with caution.