Getting Absolute Value Right
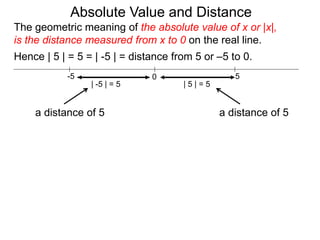
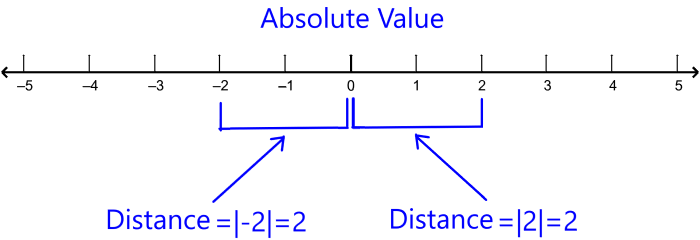
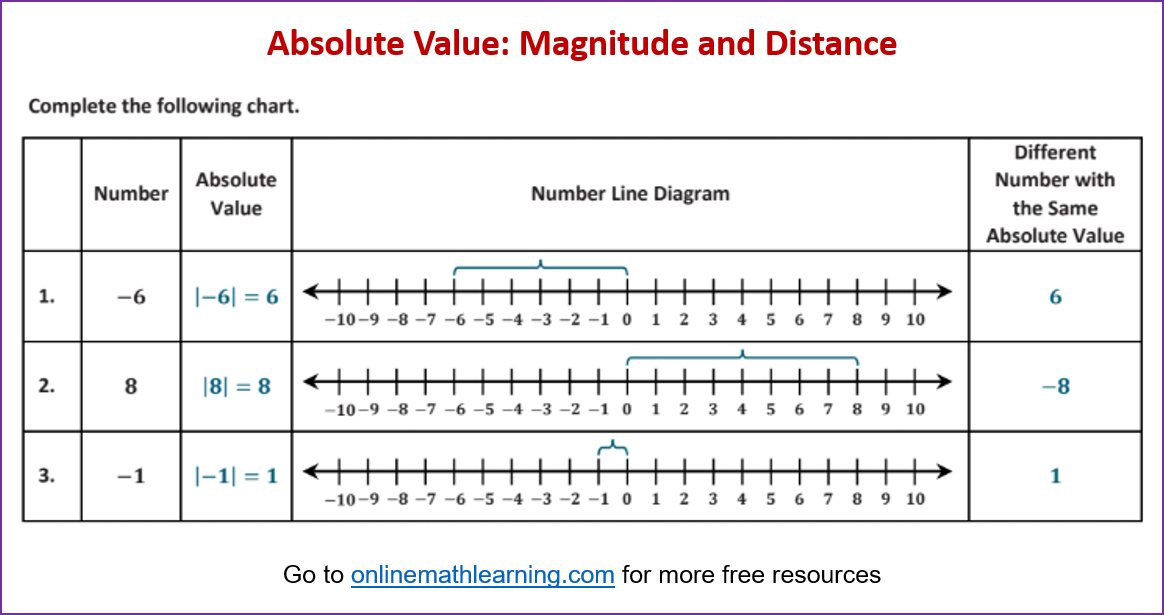
The definition of absolute value is straightforward until you actually need to apply it in contexts that matter. Most people learn it as "make negatives positive," which works fine for basic arithmetic. Then they hit problems involving equations, inequalities, or actual geometric distances, and suddenly the simple definition falls apart. The core idea is that absolute value measures distance from zero on the number line. It strips away direction and leaves only magnitude. That distinction between scalar size and signed value shows up everywhere, from physics to data processing to statistics. I remember working through a numerical integration project back when I was early in my career. The algorithm was throwing errors because the error bound calculations involved nested absolute values inside iterative loops. Someone had written the code assuming |a + b| = |a| + |b|, which is almost never true. Watch out for that one. The triangle inequality only gives you |a + b| |a| + |b|, so any algorithm relying on that simplified version will accumulate systematic errors that compound quickly. I rewrote the bounds checking to use separate cases and got the integration to converge in under thirty seconds instead of drifting into infinity over minutes.
The Definition Of Absolute Value Unlocking The True Meaning Of Distance And Magnitude
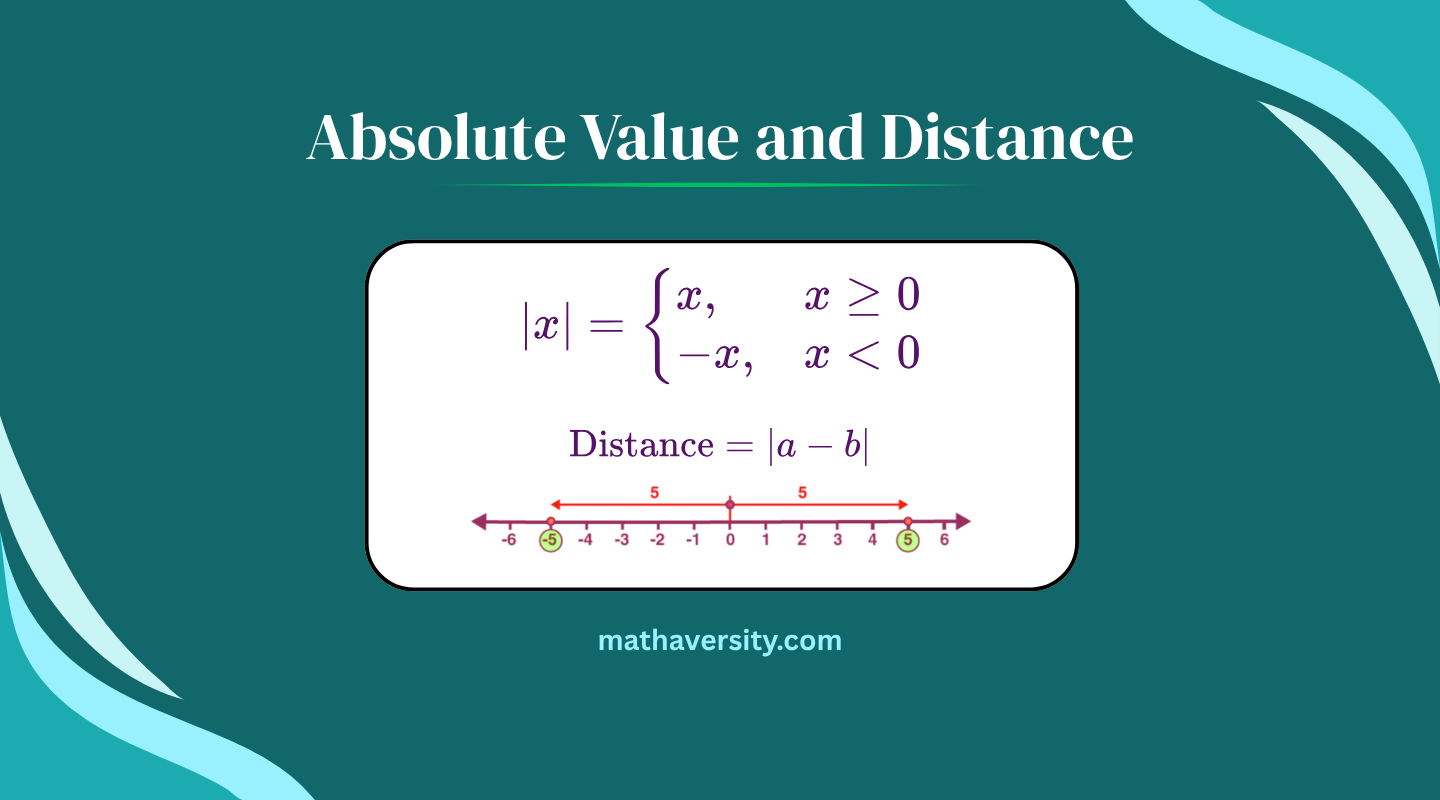
Formally, the absolute value of a real number x is defined as x if x 0, and -x if x
0. That definition looks simple enough, but it hides the fact that absolute value is really just a piecewise function with a kink at zero. When you're working with it in calculus or analysis, you need to remember that derivative behavior changes at that point. The function isn't differentiable at zero, and any optimization or approximation routine that assumes smoothness there will fail. I learned that the hard way when fitting a least-squares model and trying to take derivatives of an L1 norm term. Switching to an L2 regularization approach fixed the convergence issue, though it introduced a small bias in the coefficients. Distance interpretation matters more than most textbooks emphasize. The absolute value of a difference, |a - b|, is the distance between two points on the real line. That's not just a handy visualization. It's the actual definition of the metric for one-dimensional Euclidean space. When you extend this to higher dimensions, you get the Manhattan distance if you sum absolute differences across coordinates, and the Euclidean distance if you sum squared differences and take the square root. Each metric behaves differently under optimization. Manhattan distance favors sparse solutions and is more robust to outliers, while Euclidean distance penalizes large deviations more heavily. Choosing between them depends on your data distribution and what you're actually trying to minimize. There's a common misconception that absolute value and magnitude are interchangeable terms. They're related but not identical. Magnitude can apply to vectors, complex numbers, and other structures that don't have a strict ordering. The absolute value of a complex number z = a + bi is sqrt(a² + b²), which extends the real-line distance concept into the plane. For vectors, we usually say norm instead of absolute value, though the conceptual link is the same. The L1 norm of a vector is the sum of absolute values of its components. The L2 norm is the square root of the sum of squared components. These aren't just naming preferences. They produce genuinely different results in practice.
One edge case that catches people off guard involves absolute values inside limit calculations. If you're evaluating lim(x0) |x|/x, the left-hand limit gives -1 and the right-hand limit gives 1, so the limit doesn't exist. Some students try to cancel the x and get 1, which is wrong. The absolute value function creates a discontinuity in the derivative, and any limit analysis needs to check both sides separately. I see this mistake repeatedly in undergraduate work, and it compounds when students move into real analysis or measure theory. When solving equations with absolute values, splitting into cases is the standard approach. For |f(x)| = c where c > 0, you solve f(x) = c and f(x) = -c. For |f(x)| < c, you get -c < f(x) < c. For |f(x)| > c, you get f(x) > c or f(x) < -c. The trickier case is when c is a variable expression, like |x - 3|
2x + 1. You need to consider the sign of both sides, and sometimes the domain restrictions change the solution set in non-obvious ways. I've seen people lose valid solutions by assuming the right side is always positive without checking. For practical applications, computational libraries handle absolute value efficiently, but there are subtle issues with floating point arithmetic. The abs() function in most languages returns a float or integer depending on input type, but near-zero values can behave unexpectedly with denormalized numbers. In high-performance computing, branching on sign can stall pipelines. Using bitwise operations or conditional moves instead of abs() can sometimes speed things up, though modern compilers usually optimize abs() well enough for most use cases. The real bottleneck tends to be elsewhere in the pipeline anyway.
Get the Full Details

Abs( ) isn't universally applicable. It doesn't work for quaternion or octonion magnitudes in the same way. It doesn't provide a complete metric in all normed vector spaces. And it's not suitable for measuring distance in modular arithmetic systems where the concept of positive and negative breaks down entirely. If you're working in those domains, you need a different framework altogether. Stick to real and complex numbers, or use the appropriate generalization of magnitude for your structure.