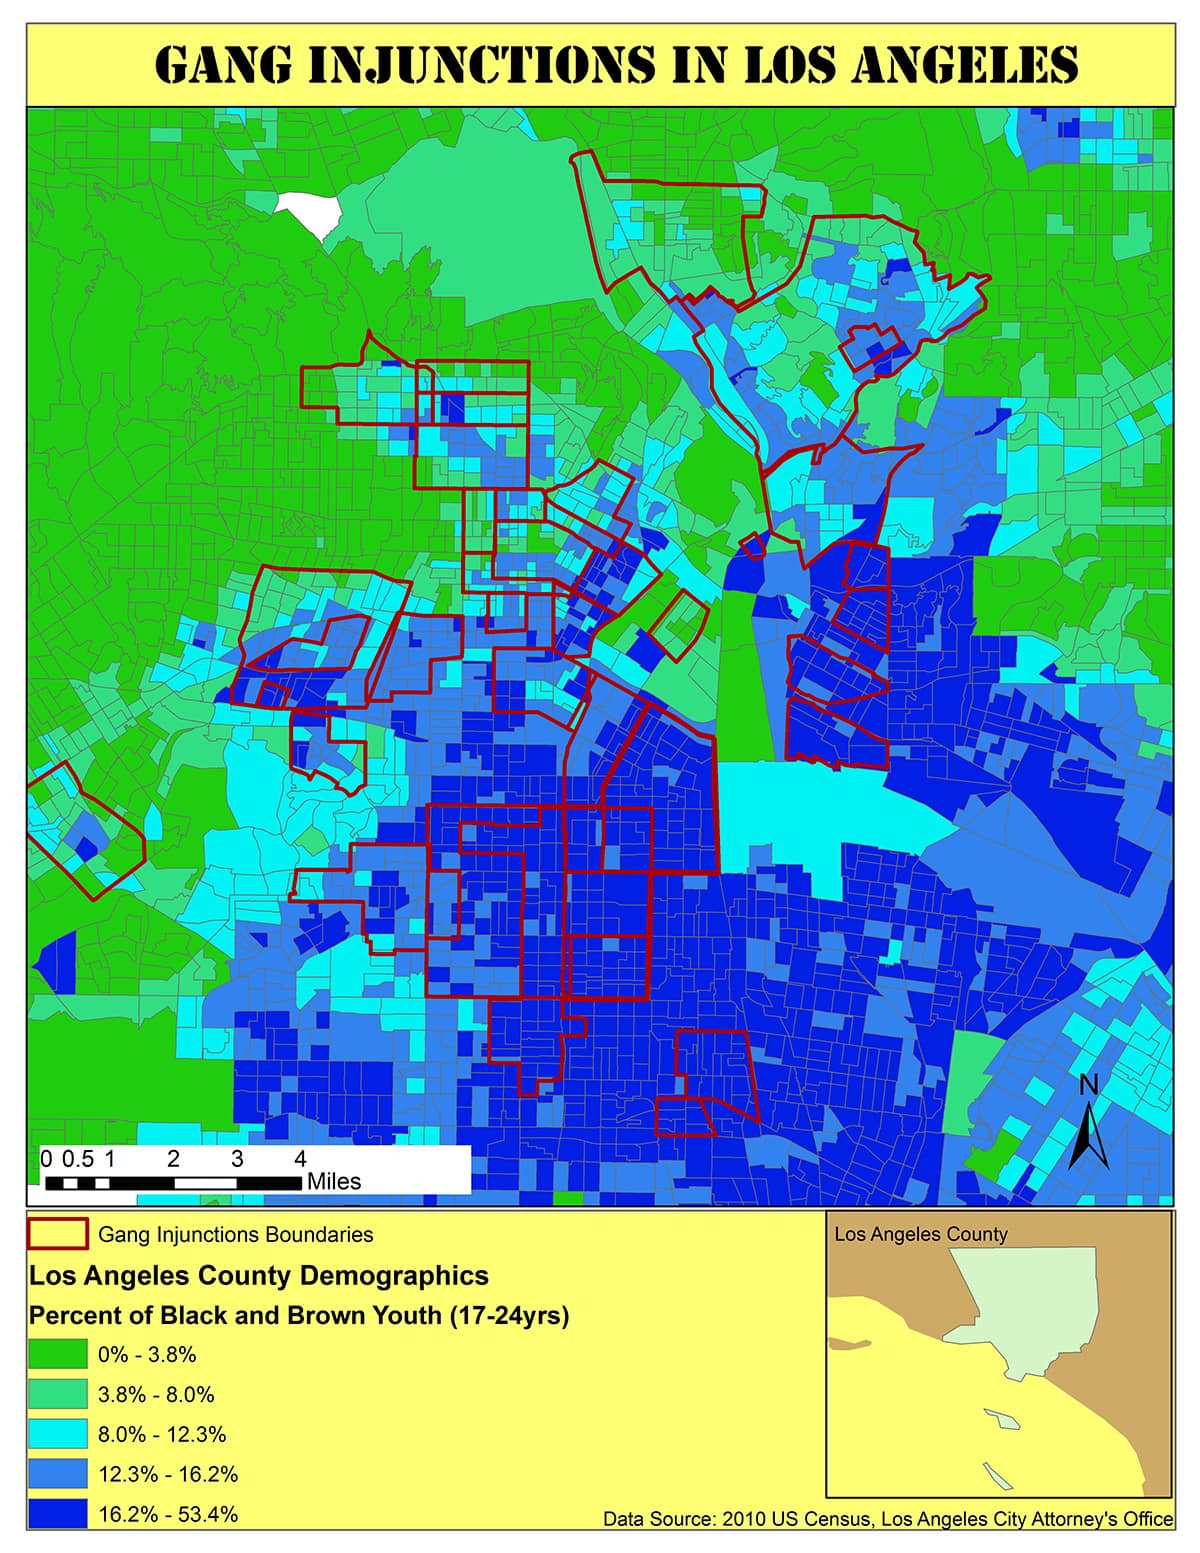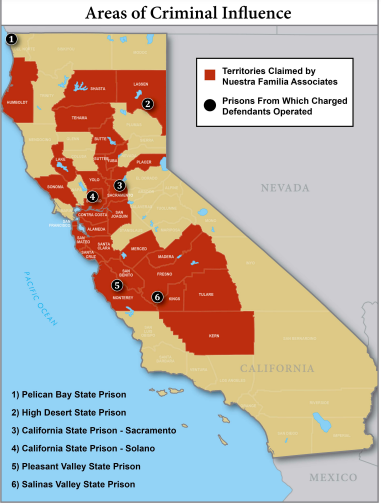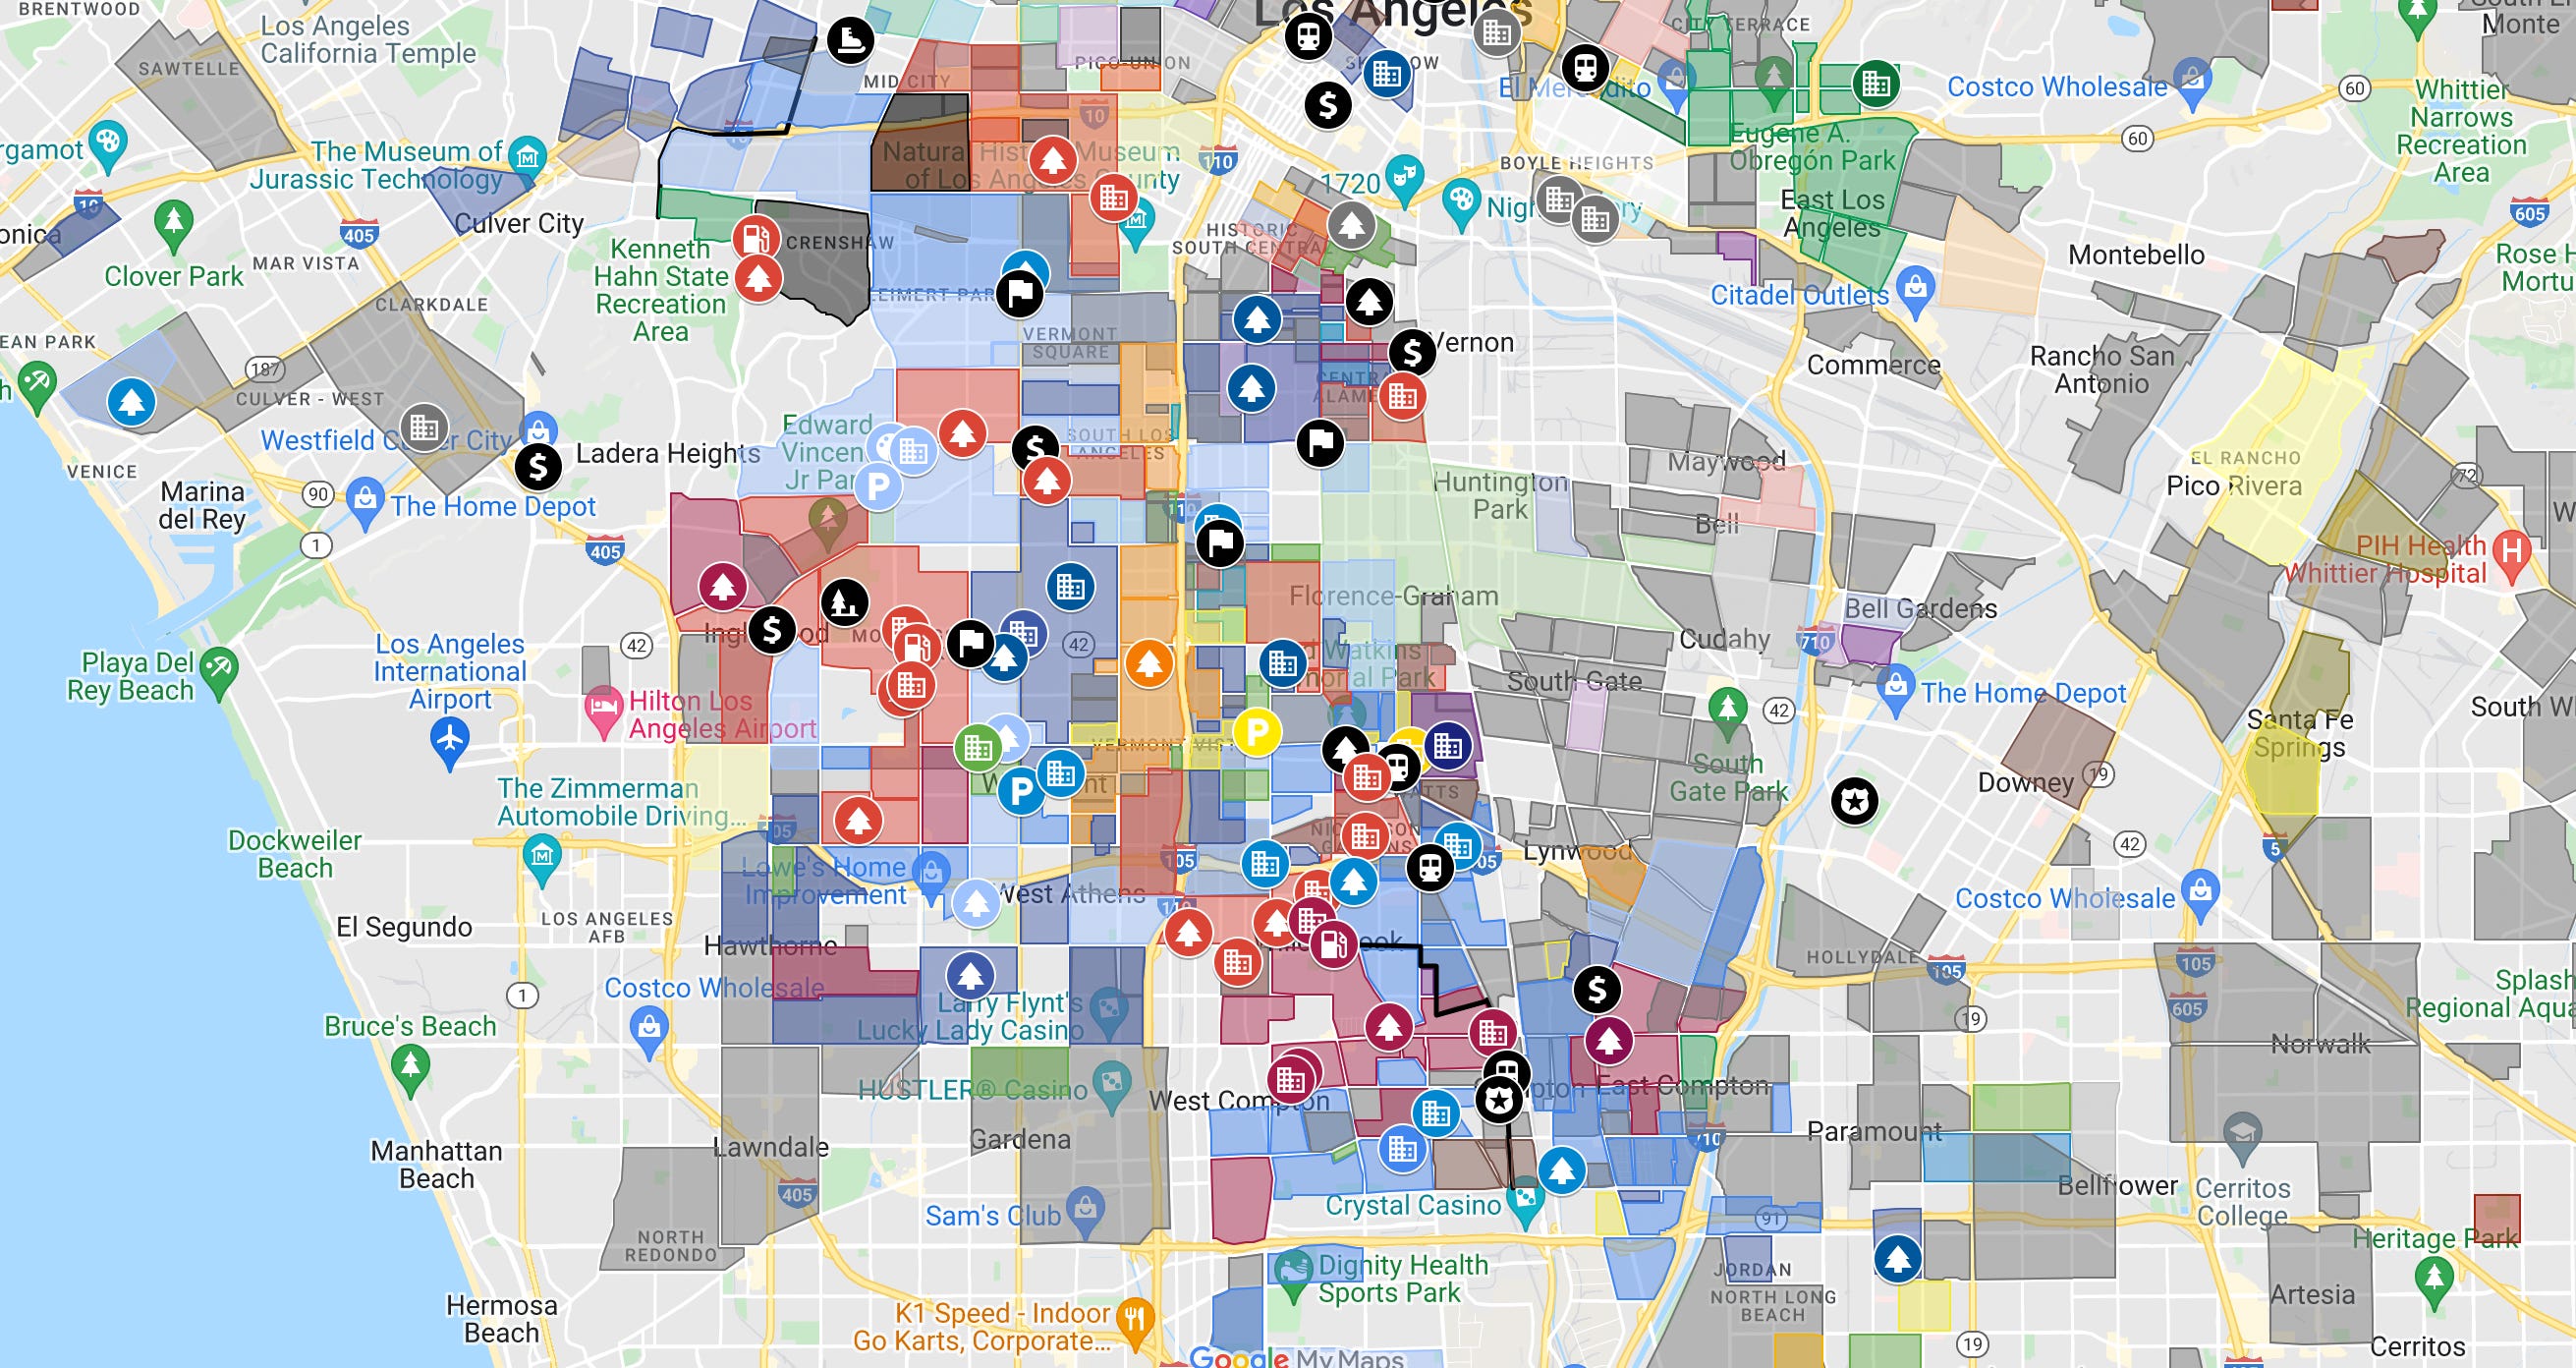
What You Are Actually Looking At
A gang map of California is not a single dataset. It is a patchwork of sheriff departments, CHP incident logs, CDC homicide data, and private databases that rarely talk to each other. When someone links to a visualization project called The Deadly Reality Of Californias Gang Map Exploring The States Most Violent Gangs, they are usually pointing at a community-driven aggregation of publicly available records with some estimates layered on top. I spent three years building territory models for law enforcement consult work and municipal planning. The first thing I learned is that most gang maps online are visually impressive and factually shallow. The second thing I learned is that when you actually need to know which streets matter, the public data is fragmented enough that you have to bring your own filters or you will spend more time cleaning than analyzing.
The Deadly Reality Of Californias Gang Map Exploring The States Most Violent Gangs
That phrase tends to come up when people want a quick mental picture of where things are concentrated. The short answer is that the highest-violence corridors run from South Central Los Angeles through the Inland Empire, down the Central Valley toward the Bay Area corridor, and into specific pockets of San Diego and Orange County. But those are loose generalizations. The real detail lives in precinct-level crime logs and CAD calls that most maps ignore because they are hard to get. If you want to understand the structure behind a project like this, start with the sources. The California Department of Justice maintains the Criminal Information Services Division database, which includes a gang and tattoo registry that gets updated quarterly. Then there are county-level open data portals. Los Angeles County, Orange County, San Bernardino County, and Riverside County all publish datasets with different schemas, different date ranges, and different column names for the same fields. That alone eats half a day every time you pull fresh data. Core data sources you will need
- California DOJ CalGang Registry — provides identified gang members and set affiliation, but it is not a territory map and it has significant reporting lag.
- County sheriff open data portals — crime incidents, CAD calls, arrest records, often with partial address normalization.
- FBI UCR and CDC WISQARS homicide data — useful for trend analysis but low spatial resolution at the city or precinct level.
- Local news archives and court docket records — tedious but essential for validating territory boundaries that public data misses.
When I was building a territory overlay model for a mid-sized California county, I ran into a specific problem that any amateur analyst hits eventually. The DOJ registry lists a member's primary home address, but that address is often their parents' house or a temporary stay. The actual turf activity is three miles away near a transit corridor or a commercial strip. If you plot registry addresses directly on a heat map, your core territory looks wrong and your density spikes in residential neighborhoods that are not actually central to the group's operations. My workaround was to cross-reference arrest records with CAD call-for-service data. I took the coordinates from arrest incidents over a rolling twelve-month window and applied a kernel density estimate with a bandwidth of roughly 0.4 miles. Then I compared that output against the registry addresses. The divergence was consistently significant. In one case, the apparent home-base density was off by about 60 percent from the actual high-activity zones. I ended up treating registry addresses as priors and letting incident-based density do the heavy lifting. That shift alone made the model usable for field verification instead of being a decorative dashboard.
Get the Full Details
How to Build a Workable Map From Scratch
Before you write a single line of code, decide what question the map needs to answer. Is it trend monitoring? Resource allocation? Research? The answer changes the entire pipeline. A trend map needs clean time series. A resource map needs current incident density. A research map can tolerate older data with better documentation. I have seen projects fail because someone tried to make one visualization serve all three purposes at once. Here is the practical pipeline I use when I have access to raw records. Step one: ingest and normalize
Pull data from each source into a staging area. Convert all dates to UTC. Standardize address formats. Use a geocoder that handles California-specific quirks — USPS CASS certification matters here because many county addresses include subdivision names or tribal land references that break naive geocoders. I route this through a dedicated geocoding service with a fallback to manual matching for anything that fails on the first pass. Roughly 8 to 12 percent of records in California datasets need manual correction on the first try. That number jumps if you include smaller rural counties. Step two: deduplicate and deconflict Multiple agencies report the same incident with slightly different timestamps and address variations. Run a clustering pass using incident type, location radius, and time window. A simple spatial hash with a 100-meter grid and a 30-minute window catches most duplicates without false merges. Then apply a rule-based filter to keep the most complete record from each cluster. This step usually removes 5 to 15 percent of records depending on source overlap.
Step three: assign context labels Gang-related incidents are labeled inconsistently across jurisdictions. Some use a flag field. Some use narrative text. Some use neither and rely on investigator notes stored in a separate system. I parse the narrative fields with a lightweight regex pass for known gang terminology, then layer in the formal flags from each agency. The result is a scored label, not a binary one. A score lets you show uncertainty on the map instead of pretending every label is solid. Step four: generate density surfaces

Apply kernel density estimation with bandwidth tuned to the urban scale you are working in. For a city like Los Angeles, a 0.3 to 0.5 mile bandwidth works. For a rural county, bump it to 1.5 or 2 miles or the surface becomes noise. Output the density as a raster, then convert to contours at meaningful percentiles. I usually render the 75th, 85th, and 95th percentiles as separate layers so the audience can see where intensity crosses from elevated to extreme. Step five: validate against ground truth This is the step most hobby projects skip. Take the top percentiles and compare them against known territory boundaries from court documents, sworn declarations, and local intelligence reports. Where the map agrees, flag it. Where it disagrees, investigate. In my experience, about 60 to 70 percent of high-intensity pixels in urban California map to historically recognized corridors. The rest is usually transit-adjacent activity or areas where incident reporting volume skews the density upward. The discrepancy itself is informative. It tells you where reporting is thick and where it is thin.
What Most People Get Wrong
The biggest mistake is treating a density map as a territory map. Density shows where incidents concentrate. Territory shows where a group exercises control. They overlap, but they are not identical. A street with high incident density might be a contested corridor rather than a home base. Conversely, a home base can have low visible incident density because activity is structured and dispersed. I had a client once who built a deployment plan around the highest-density pixels. It failed in the field because the actual primary locations were lower-density residential blocks two miles inland. The map looked right. The reality did not. Another common failure is ignoring reporting bias. Some neighborhoods have higher clearance rates and more proactive patrol, which inflates incident counts relative to actual activity. Others have underreporting due to fear or mistrust. A raw heatmap without a reporting-adjustment layer will mislead anyone who treats it as a pure activity measure. I usually normalize incident counts by a proxy for reporting intensity, such as call volume per capita adjusted for known patrol ratios. It is not perfect, but it prevents the map from reinforcing existing blind spots. A third error is static snapshots. Gang activity shifts. Territory changes after an arrest wave, a lockdown, or a leadership transition. A map that does not show recency is a history lesson, not an operational tool. I timestamp every layer and keep a rolling archive. Even a simple monthly refresh prevents the map from becoming stale.
Tools and Practical Setup
For small projects, QGIS with the Processing Toolbox handles most of the pipeline without licensing costs. Load your cleaned CSVs, run the geocoding batch, export to GeoJSON, then use the KDE plugin for density surfaces. The built-in graduated color ramp with percentile classification keeps the visualization honest. For larger projects, I move to PostgreSQL with PostGIS. The spatial functions for clustering, hashing, and density are far faster, and the schema lets me store metadata alongside geometries without breaking the workflow. For visualization, Leaflet or Mapbox GL JS gives you interactive maps that load quickly. Keep the basemap neutral. A dark basemap makes red dots look dramatic. A light basemap makes them look clinical. Pick one and stick with it. The aesthetic choice is not trivial because it shapes how the data is perceived. If you want a starting point for aggregation, look at existing open repositories on GitHub that pull from county portals. Projects that scrape multiple source URLs and normalize them into a common schema save weeks of work. Just verify their methodology before trusting their output. I have seen repos that merge data incorrectly because they assumed identical column names across counties. Column names are never identical across California counties.

Limitations You Should Accept Upfront
No public map will capture the full picture. Active gang intelligence is protected for operational reasons. Many relevant incidents are never recorded in open datasets because they resolve through diversion programs or internal discipline. Youth affiliations are handled differently than adult cases and often appear in separate juvenile systems that are not publicly accessible. The map you build will always be a partial view. The CalGang registry has a known false-positive rate. Membership designation can be based on association rather than confirmed activity. Some jurisdictions over-report to meet performance metrics. I treat registry entries as hypotheses, not facts, and weight them accordingly in any model. If you present registry data as ground truth, you will produce a map that overrepresents certain groups and underrepresents others. Another bottleneck is temporal lag. County portals often publish with a 60 to 90 day delay. Homicide data may lag further due to coroner and court timelines. If you publish a map without clear date stamps, users will assume it is current. It is usually not. Add a visible data-cutoff banner and a refresh schedule. Five minutes of labeling prevents hours of correction requests.
When the public data is too thin for your needs, the alternative is to restrict the map to confirmed aggregate trends and avoid fine-grained territory claims. That approach sacrifices local precision but gains credibility. I have found that a conservative map used by serious analysts is more valuable than an aggressive map used by everyone and trusted by no one.
What to Do Next
Start small. Pick one county. Pull one year of open incident data. Run the geocode-deduplicate-label-KDE validation loop. See where the model agrees with what you already know and where it diverges. The divergence points are where the real work begins. Then expand the county count and add registry overlays as a secondary signal rather than the primary signal. Document every assumption. Column mappings, geocoder choices, bandwidth selections, percentile thresholds. A map without a methodology note is just a pretty image. With a methodology note, it is a reproducible artifact that others can audit and improve. That is the difference between a project and a resource.