What Happens When You Try to Process Every Event in Real Time
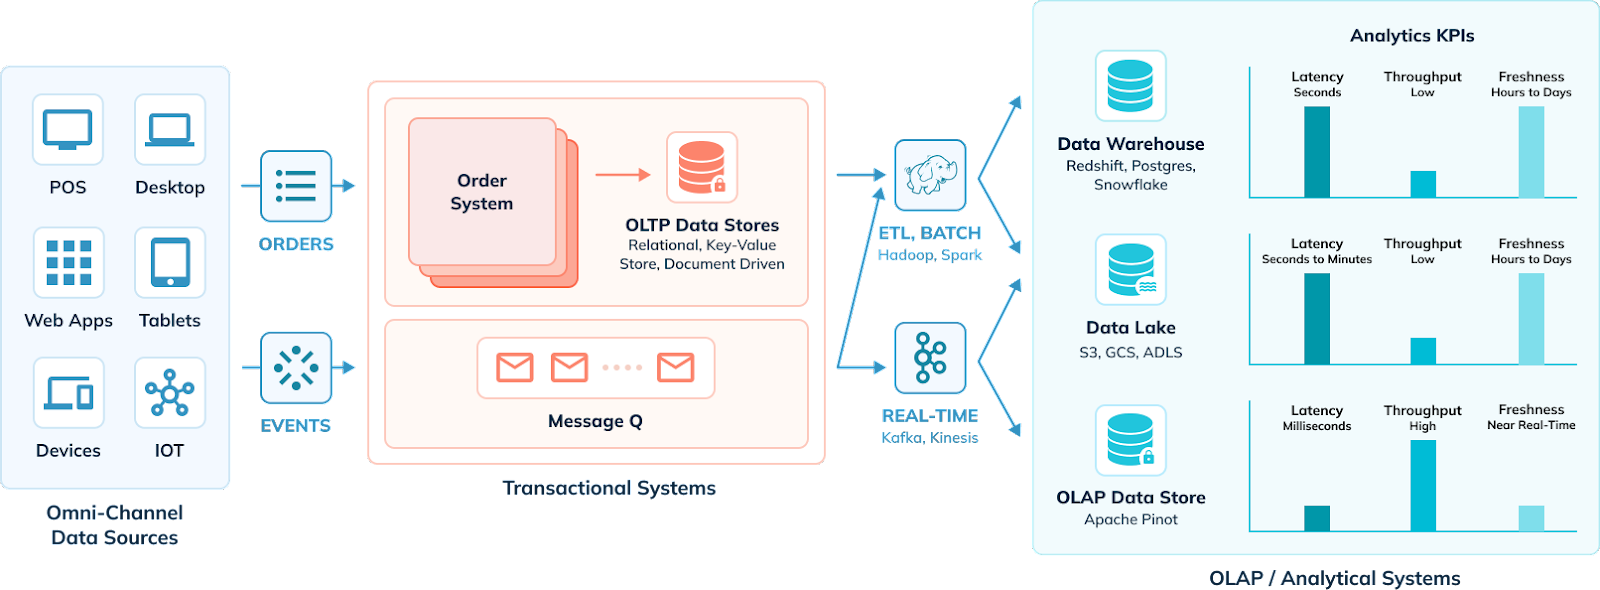
I spent most of 2023 and into 2024 working on analytics architectures for mid-market and enterprise orgs trying to move off batch pipelines. The basic pitch everyone makes is straightforward enough: ingest everything as it happens, store it in something fast, and serve it back to dashboards without waiting for nightly jobs. The reality is considerably more complicated than the slide decks suggest. Most teams I talk to are running into the same three bottlenecks. They underestimate the cost of schema evolution across streaming sources. They build systems that handle normal traffic fine but collapse under backpressure during spikes. And they rarely account for the operational overhead of maintaining the pipeline itself once it goes live. The organizations that actually pull this off tend to share a similar set of design choices, even though their tooling varies. The core architecture pattern I see working consistently is event sourcing layered over a durable streaming platform with a separation between the ingestion path and the consumption path. Kafka or Redpanda at the base layer, usually with schema registration through something like Confluent or Abris. Upstream connectors pull data from whatever databases, APIs, or message queues the business depends on. Downstream, you have a stream processing layer that handles transformations, windowing, and aggregation before materialized views serve the actual queries.
Here is the part people get wrong. The streaming layer is not where you do heavy joins or expensive aggregations. I've seen teams run SQL-style aggregations directly on Kafka streams and then wonder why their cluster costs tripled during a promotional period. The right move is to keep the streaming layer lean and push compute downstream to something like RisingWave, Materialize, or a dedicated OLAP engine fed by change data capture. This decoupling means your ingestion rate stays predictable regardless of how many dashboards are querying at any given moment. I ran into a specific problem last spring with a client who was ingesting around 400,000 events per second from a mobile app's interaction logs. Their schema registry had no enforcement on nested field additions, so a client push added a completely new optional object to the event payload. It wasn't in their test environment. It hit production through an A/B test, broke three downstream consumers, and caused a cascade of schema validation failures that took about six hours to fully untangle. The workaround was implementing strict schema evolution policies with a deprecation window, plus a canary ingestion pattern that routes a small percentage of traffic through a shadow consumer before allowing the new schema version to go wide. That shadow approach also caught another issue: one of their upstream data producers was sending timestamps in two different formats without telling anyone. The canary pipeline flagged it before it corrupted any stored aggregates. When you are actually building this for 2024, the stack tends to look something like this. You need a CDC layer for database changes. Debezium is the standard choice here, though some teams have moved to Strimzi for managed Kafka deployment. On the processing side, Flink remains the workhorse for complex event processing and stateful aggregations, while Spark Structured Streaming still has a place for batch-stream hybrid workloads. For serving, Apache Pinot and ClickHouse have been the most common choices depending on whether you need true real-time query results or near-real-time with acceptable latency trade-offs.
One counter-intuitive thing about realtime analytics that beginners consistently miss is that higher ingestion throughput does not necessarily give you better query performance. In fact, the opposite is often true. When you push ingest rates beyond what your compaction and retention strategy can handle, you get fragmented partition data that slows down every query because the engine has to merge too many small segments. I've seen teams hit a wall at around 150,000 events per second per partition on a standard three-broker cluster before query latency started climbing unpredictably. The fix was partition rebalancing and switching to a tiered storage model where hot data lives on local SSD and cold data gets pushed to S3. That single change dropped p99 query latency from roughly 8 seconds to about 900 milliseconds for their most common dashboard queries. Another thing nobody likes to admit is that real-time analytics introduces new failure modes that batch systems simply do not have. With batch, if a job fails, you rerun it. With streaming, the concept of rerunning doesn't apply the same way. You either replay from the beginning of the partition log, which can take hours or days depending on retention settings, or you accept the gap. I worked with a team that lost about fourteen minutes of financial transaction data because their consumer group offset was incorrectly committed during a rolling deployment. They didn't even know it was gone until the reconciliation report ran a week later. The lesson here is that you need idempotent consumers and strict at-least-once semantics with deduplication keys, not best-effort exactly-once processing that sometimes quietly fails. If you are architecting this for an organization, I would recommend starting with a clear distinction between your latency requirements. Not every analytics use case actually needs sub-second freshness. Some dashboards would be fine with five-minute windowing, which dramatically reduces infrastructure costs and complexity. Only the use cases that genuinely require low latency, like fraud detection or real-time personalization, deserve the full streaming pipeline with all the operational overhead that comes with it. Most teams I encounter allocate realtime infrastructure to everything, which is a fast track to budget problems.
Get the Full Details
On the cost side, expect to spend roughly 30 to 40 percent of your pipeline budget on infrastructure that is purely about reliability and recovery, not raw computation. Storage for Kafka logs, schema registry redundancy, operator tooling for monitoring consumer lag and partition health, backup and replay capabilities. If your architecture does not explicitly budget for this overhead, it will get cut first when things get tight, and then your system will break the first time anything goes wrong. For teams evaluating tools, there is no universal winner. RisingWave is simpler to operate than Flink if your workloads are mostly aggregate-based and you do not need complex event processing with CEP operators. Materialize is excellent for SQL-friendly teams but lacks the rich API ecosystem that Flink provides for custom processing logic. If you are already deep in the Confluent ecosystem, their new ksqlDB offerings have improved significantly but still carry the vendor lock-in tax. For open-source purists, the Redpanda plus Trino plus Presto path gives you decent performance with fewer moving parts, though you lose some of the mature tooling that Kafka ecosystems provide. The operational reality is that these systems require someone who understands both distributed systems fundamentals and your specific domain data. A data engineer who only knows SQL will struggle with backpressure management and partition awareness. A platform engineer who only knows infrastructure will miss the subtle data quality issues that show up only after weeks of production traffic. The teams that succeed tend to staff these projects with mixed backgrounds and invest heavily in observability from day one, not after something breaks.
There are also scenarios where real-time analytics is the wrong answer entirely. If your data sources are fundamentally batch-oriented, like legacy ERP systems that only expose data through end-of-day exports, no amount of streaming infrastructure will make that data truly real-time. You would be better served by optimizing your batch pipeline with incremental loads and faster staging. Similarly, if your query patterns are highly variable and ad-hoc, a columnar store with materialized views may outperform a streaming database because you avoid the overhead of maintaining continuous computation for data that is rarely queried. I worked with a healthcare analytics team that spent eight months building a full streaming pipeline only to discover their actual query patterns were dominated by monthly cohort analyses that could have been handled by a well-indexed PostgreSQL setup with scheduled refresh jobs. The fundamental takeaway is that realtime analytics architecture in 2024 is less about picking the fastest tool and more about making deliberate trade-offs between latency, cost, operational complexity, and data quality. The organizations that get this right are the ones that treat their streaming infrastructure as a product with users, not just a technical component. They invest in documentation, monitoring, and the kind of gradual rollout practices that prevent schema disasters from becoming production incidents. Everything else is just configuration.