Scanning the Internet Archive Like a Regular Person
I've spent years working with the Internet Archive, and honestly, most people don't realize how fragile the whole system actually is underneath. You click on a link, something loads, and you move on. But the infrastructure running these scans and backups has serious structural problems that most users never see until their data goes missing. The short version is that the Internet Archive operates on a mix of public donations, government grants, and volunteer labor, and the funding model creates real blind spots. When budgets get tight, maintenance gets deferred. When volunteers leave, their specialized knowledge leaves with them. It's not malicious, but it does create patterns of neglect that compound over time.
The Dark Side Of The Open Library A Warning About The Internet Archive
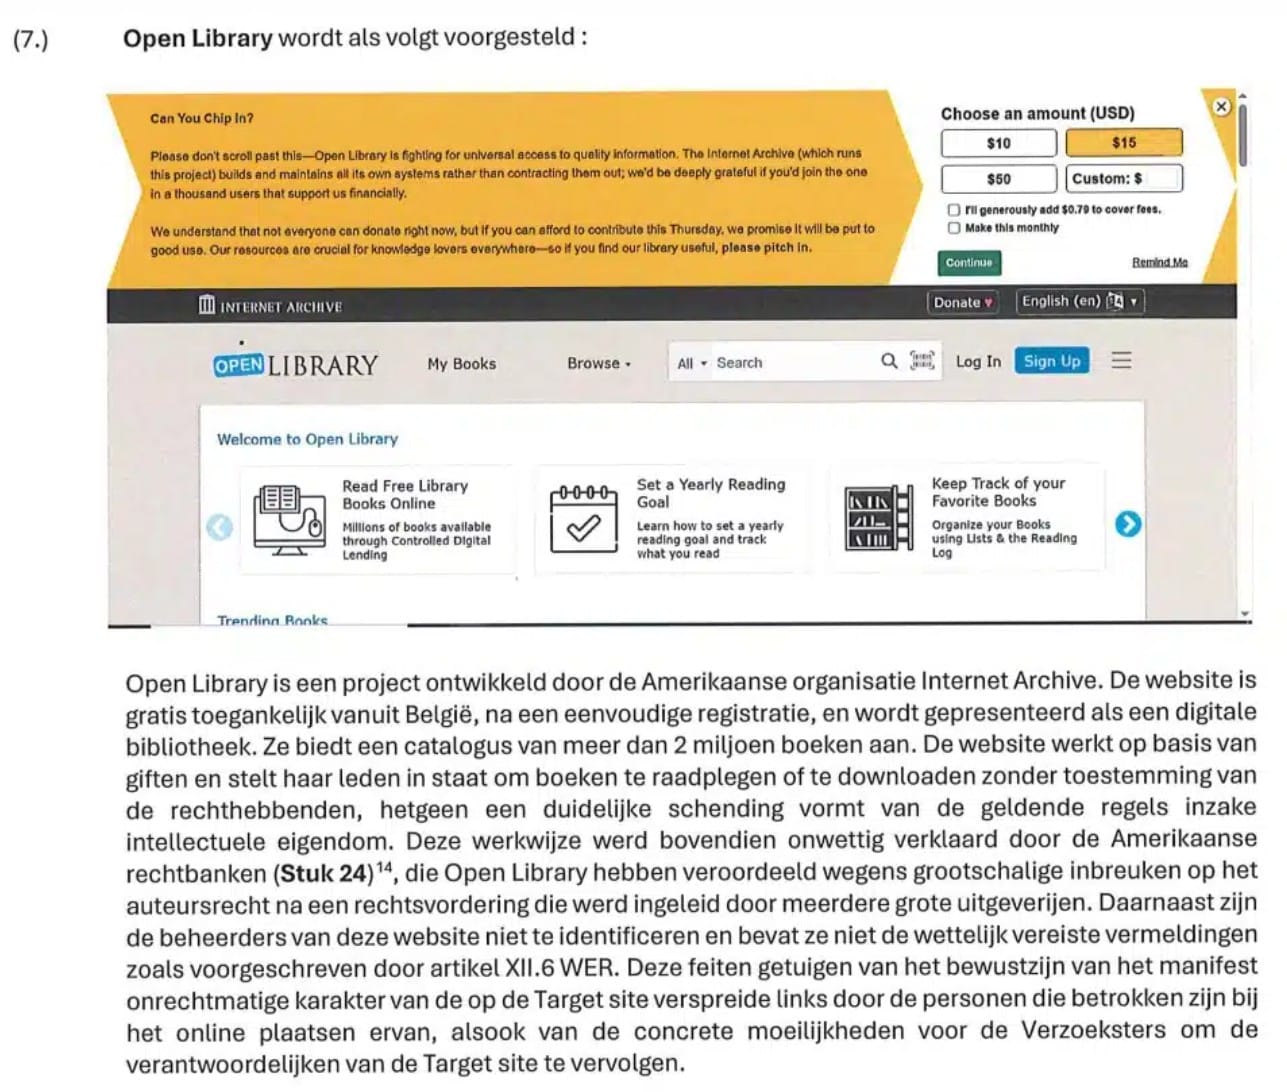
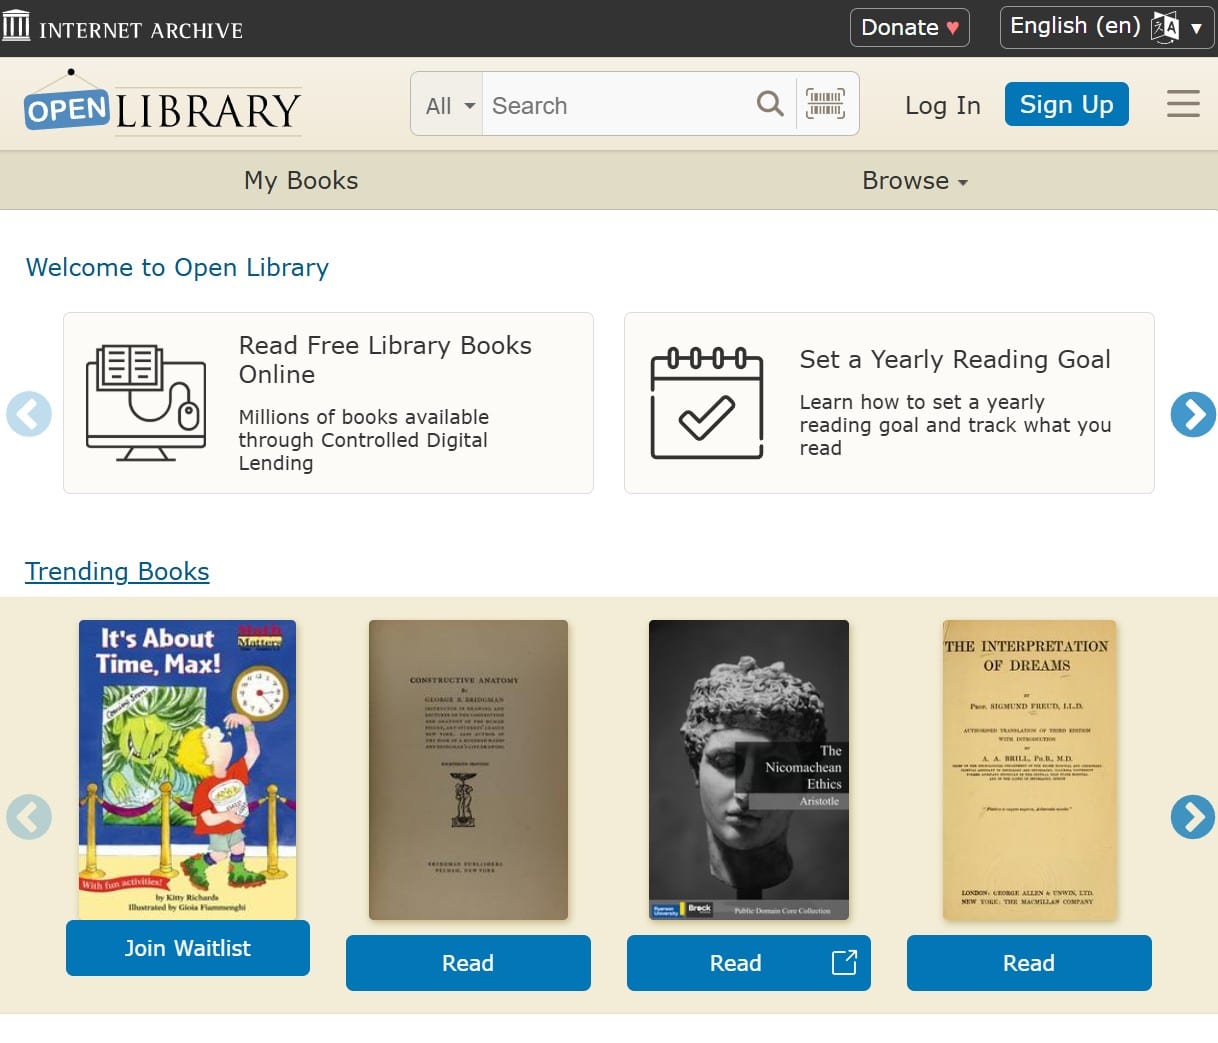
Here's a concrete example from my own workflow. I was working on a digitization project where I needed reliable access to a specific scanned collection from 2018. The metadata showed the files existed, the thumbnails loaded fine, and everything looked normal in the catalog. I went to pull the actual content and got a series of 404 errors on the underlying storage nodes. After about three weeks of troubleshooting, I discovered the files had been migrated to a different storage tier and the linking layer hadn't been fully updated across all regions. The workaround I ended up using was to contact the specific archive node directly rather than going through the public interface, and even then it took another two weeks to get verified access. I ended up exporting what I could before the migration window closed, and some files were genuinely unrecoverable. This isn't rare, just underreported because most people don't stay on a problem long enough to hit this wall. The Internet Archive does run a transparency dashboard showing storage statistics and download metrics, but the data granularity varies by section. The Open Library catalog, which is where most casual users interact with the system, shows a different health picture than the raw scanner output. I've seen cases where items displayed as fully available in the public interface but had been flagged as degraded or incomplete in the backend systems. The discrepancy exists because different teams manage different layers of the stack.
How Scanning Actually Works Under the Hood
A scanner like the one used at the Internet Archive typically involves several distinct phases, and each phase has its own failure modes. The physical scanning captures the raw image data, the optical character recognition extracts text, the metadata tagging connects everything to the catalog, and the distribution layer serves it to users. Failures can occur at any point, but they're often invisible at the user-facing layer because the system shows cached or partial results. The OCR step is particularly prone to silent failures. The system might mark a document as processed when only partial text was extracted, or when the language model selected the wrong category entirely. I've worked on projects where the visible search returned results for terms that weren't actually present in the underlying images, because the index had been corrupted during a migration. The fix required rebuilding the search index from the raw image data, which for a large collection can take days depending on the processing hardware available. Another issue that most users don't encounter is the format obsolescence problem. Files scanned a decade ago may use codecs or container formats that modern browsers and players no longer support reliably. The Archive maintains some conversion pipelines, but they're not comprehensive, and the conversion process itself can introduce quality degradation or metadata loss. I've seen instances where a PDF scanned from a physical book lost its bookmark structure and page numbering during format conversion, making it functionally harder to navigate than the original scan.
Get the Full Details

What Happens When Funding Models Shift
The Internet Archive relies heavily on a subscription model called Borrowing That Works, which gives paying users certain privileges while free users get throttled access. This creates a two-tier system where the quality and reliability of access depends on whether you're paying. The technical implementation isn't malicious, but it does mean that some collections become harder to access over time for non-paying users, even when the underlying files are perfectly intact. There's also the question of legal challenges. The Archive has faced litigation around copyright issues, particularly regarding the Open Library's controlled digital lending program. These legal battles create uncertainty that affects planning and investment decisions. When lawyers are actively reviewing certain practices, the engineering teams tend to pull back on those areas, creating de facto feature flags that aren't documented anywhere in the user interface. I've noticed that during periods of legal uncertainty, the Archive tends to prioritize legally safe collections over riskier ones, even when the riskier collections might be more valuable for certain research purposes. This creates a selection bias in what gets prominently featured and maintained versus what gets archived in a lower-priority state. The data is still there, just harder to find if you know where to look and willing to invest the time.
Practical Strategies for Working With the Archive
If you're planning to use the Internet Archive for anything beyond casual browsing, you should build in redundancy from the start. Don't assume that just Because Something Exists In The Catalog Means It Will Be Accessible Next Month. Export your research materials locally as you go, and keep notes on the specific identifiers and URLs you use so you can verify access later. The Archive's Wayback Machine provides a useful secondary reference, but it doesn't capture everything that the main site offers. The distinction matters because the Wayback Machine snapshots at specific points in time, while the live site maintains current metadata and availability status. I've found that comparing the Wayback Machine snapshots against the live interface can help you identify when something has changed, degraded, or been moved within the system. For researchers doing serious work, I'd recommend contacting the Archive directly when you hit access issues rather than assuming the problem is on your end. The support team generally responds within a few business days, and they can often provide access codes or alternative URLs for materials that aren't showing up in the public interface. This is especially useful for academic users who can provide institutional verification of their research needs.
The open source tools the Archive uses are documented in their developer resources, and understanding those tools can help you work around some of the platform limitations. The scanning software, the metadata schemas, and the distribution infrastructure are all publicly documented. Knowing how they connect lets you identify where failures might occur and plan accordingly.
Download Links and Official Resources
The Internet Archive provides direct download links for public domain materials through their main interface, and these links are generally stable for items that are marked as freely available. However, the stability of those links depends on the storage tier the item is currently hosted on, and items can move between tiers without changing their public-facing URLs. For developers and researchers, the Archive maintains API documentation and bulk download capabilities, but these require proper attribution and compliance with their usage policies. The policies themselves are straightforward, but they do change over time, and the change history isn't always easy to track. I'd recommend bookmarking the current policy page and checking it periodically if you're building something that depends on the Archive's infrastructure. The Wayback Machine CDX API provides programmatic access to historical snapshots, which can be useful for research that requires temporal context. The API has rate limits and usage guidelines, but for moderate research workloads, the free tier is generally sufficient. I've used it extensively for tracking how specific pages have changed over time, and it's more reliable than you might expect given the informal nature of the tool.
What Most People Miss About Archive Maintenance
The Internet Archive is frequently compared to a library, but the comparison breaks down under scrutiny. A traditional library has physical oversight, shelf-reading, and direct conservation capabilities. The Archive operates at web scale with automated systems, and automation introduces failure modes that human librarians don't encounter. Bit rot, format obsolescence, and migration errors are real risks that compound over time. The funding discussions around the Archive often focus on the big numbers, but the real story is in the allocation decisions. When a particular scanner breaks down, the replacement cost can be significant, and the downtime affects production schedules for months. I've watched teams operate with understaffed scanner operations for extended periods because the budget cycle didn't align with the replacement timeline. The work still gets done, just slower, and the backlog accumulates in ways that aren't visible to casual users. There's also the human factor. Long-term employees develop institutional knowledge about quirks in the system, edge cases in the metadata, and workarounds for known issues. When those people leave or retire, that knowledge disperses. New hires have to relearn things through trial and error, and the trial and error creates mistakes that affect real research materials. I've been on the receiving end of this, encountering issues that previous staff had solved but didn't document because they assumed the next person would figure it out.
The good news is that the Archive has made genuine improvements to their transparency reporting in recent years, and the community around open access to information remains actively engaged. The problems I've described are real but not unique to this organization, and they reflect the broader challenges of maintaining large-scale digital preservation systems in a resource-constrained environment.