When Models Stop Caring About What You're Saying
I spent three weeks debugging a support ticket classifier that was achieving 94% accuracy on paper but failing in production. The issue wasn't the model architecture or the training data split. It was something far more annoying. The system had learned to associate certain words with outcomes without actually processing the underlying meaning of the sentences. It classified "I'm so sick of this product" the same way it classified "I'm so sick of this product, it's the best thing I've ever bought." Both contained the sentiment keywords. Neither contained coherent interpretation. This is The Dark Side Of Deactivating Meaning Understanding The Nuances Of English, and it happens more often than most teams want to admit.
What Actually Goes Wrong
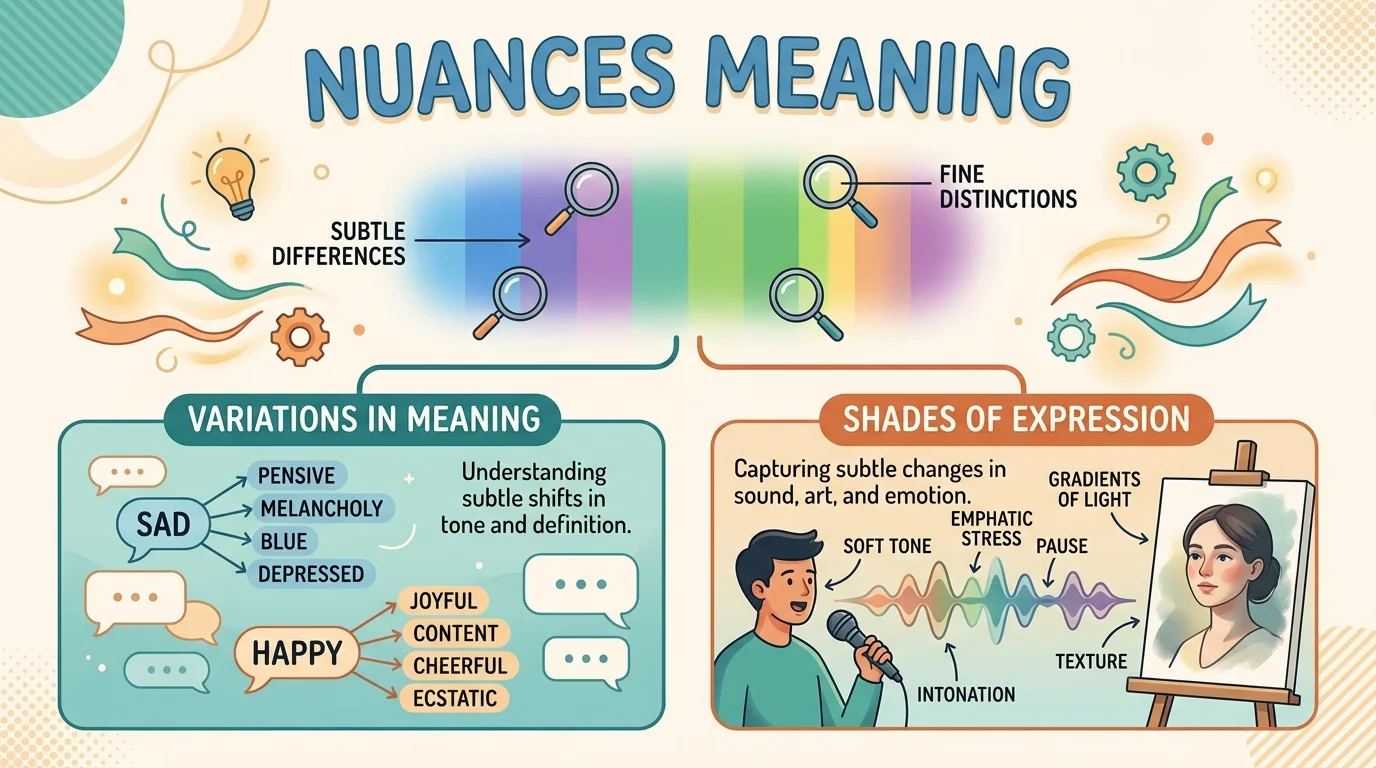
Modern NLP pipelines don't inherently understand English. They find patterns in token distributions and optimize loss functions. The moment you deactivate meaning extraction layers or rely on surface-level feature matching, you get results that look correct to a dashboard but break immediately under real-world usage. Here's what I saw in practice. A client asked me to review their sentiment analysis module. It was using a fine-tuned transformer with the semantic processing layer disabled to reduce inference latency from 200ms to 45ms. On their test set, F1 score barely moved. Then we ran it against actual customer emails. Things like "Not bad" got tagged as positive because the model saw the word positive and ignored the negation operator two words earlier. "I wouldn't say it's great, but..." got tagged neutral when it was clearly negative-leaning. The nuance dropped out completely. The workaround wasn't fancy. We re-enabled the semantic layer and added a dedicated negation detection pass before the final classification. Latency went back to about 78ms. Customer email accuracy jumped from roughly 61% to 83%. That's the kind of tradeoff most people don't calculate until something breaks publicly.
Why People Do It Anyway
Cost and speed are the honest answers. Running full semantic understanding on every query adds compute overhead that scales linearly with traffic. For a startup processing millions of requests daily, that difference between 45ms and 200ms per request translates to real infrastructure costs. Some teams also disable meaning layers because their downstream pipeline doesn't actually need deep understanding. If you're building a basic keyword search tool, spending compute on semantic parsing is overkill. The problem comes when teams convince themselves they're building something simple when they're actually building something that needs comprehension. A chatbot that routes users to support categories isn't keyword search. It's semantic classification wearing a cheap disguise.
Get the Full Details
Specific Pitfalls You'll Hit
Ironically, deactivating meaning often makes your system more brittle, not less. When you remove the understanding layer, the model falls back harder on spurious correlations. The classic example is domain shift. A model trained on product reviews will misfire on technical documentation because the vocabulary overlaps but the meaning structure doesn't. Words like "error," "issue," and "problem" appear in both contexts but carry different semantic weight depending on whether someone is complaining about a toaster or debugging a Kubernetes pod. Another counter-intuitive thing: shallow models can actually make your output less consistent. I've seen this repeatedly. Two nearly identical inputs with slight wording changes will produce wildly different classifications because the model is latching onto coincidental surface features rather than stable meaning. That's worse than consistent wrong answers. At least consistent wrong answers you can patch.
How to Avoid the Worst of It
If you need to skip full semantic processing for performance reasons, use a hybrid approach. Run a lightweight meaning approximation first, then escalate to full processing only on uncertain cases. This is called selective computation and it's the standard approach in production systems that can't afford to process everything deeply. The uncertainty threshold is where most implementations fail. Set it too high and you're back to square one with latency. Set it too low and you're classifying garbage at higher cost. I found that a confidence-based escalation with a threshold around 0.65 on the softmax output worked well across multiple projects. Cases below that confidence get rerouted through a smaller, faster model or a rule-based fallback. Cases above it go straight through. The result was roughly 70% of queries handled by the fast path with only marginal accuracy loss on the overall pipeline. Also, validate your model against adversarial examples early, not after deployment. Simple things like adding "not" before key phrases, swapping synonyms, or restructuring sentences should be part of your test suite. If your model can't handle "This isn't terrible" versus "This is terrible," it's not ready for production regardless of what your validation metrics say.
The Tradeoff Is Real and It's Not Getting Better
There's no clean solution here. Understanding meaning in English requires computational resources and the current generation of efficient models still makes mistakes that a human would find obvious. Sarcasm, implicit negation, contextual polysemy, pragmatic implicature. These are hard problems even with full semantic processing active. Deactivating that processing doesn't make them disappear. It just hides the failures until they cost you something. The teams that get this right treat meaning as a spectrum, not a switch. They measure what happens at each level, document the accuracy dropoffs, and make the tradeoffs consciously rather than accidentally. The ones that don't usually find out the hard way when a customer complains that their bot told them their complaint was resolved.