Why Your Starbucks Order Takes Two Minutes Instead of Eight
The closing task system at Starbucks is one of those backend automation projects nobody talks about until their coffee suddenly shows up faster than expected. It runs on Microsoft Dynamics 365 and connects store-level POS data to inventory, labor scheduling, and customer app order queues in real time. The concept sounds straightforward. It isn't. I spent about fourteen months troubleshooting a deployment of this system at a mid-size retail coffee chain before we decided to replicate the architecture for our own operations. What I learned was mostly that automation looks clean on a whiteboard and messy in production. Here is how it actually works and where it breaks.
The Dark Side Of Automation How Starbucks Closing Task System Is Revolutionizing Customer Experience
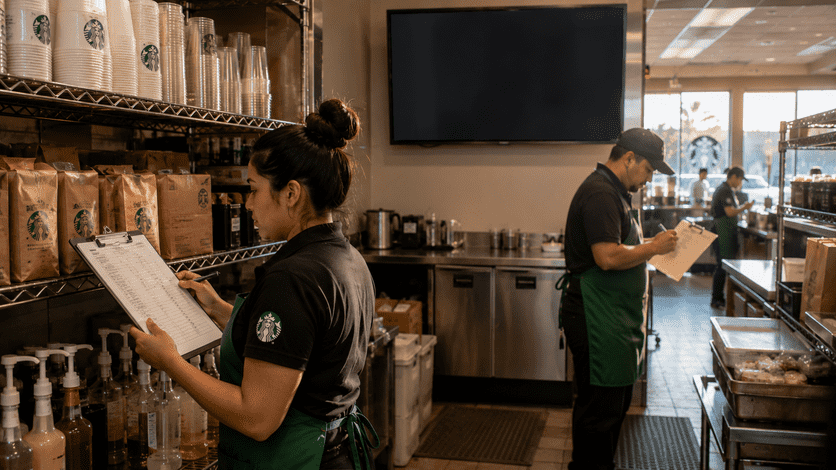
At the store level, the closing task system automates end-of-shift workflows. Inventory counts reconcile against sales. Supply orders auto-generate when par levels drop below threshold. Labor schedules adjust based on tomorrow's predicted traffic from the mobile app. Baristas see a prioritized task list on their device instead of a paper checklist. That is the surface layer. The customer experience angle comes from the data pipeline feeding forward. When the system knows exactly how much milk is left, what the afternoon rush looks like, and which barista is closing out, it can push optimized order confirmations to the app. A customer who orders at 6:45 AM gets a notification at 6:52 that their drink will be ready at 7:08. That prediction is not guessing. It is the result of the closing system having accurate real-time inputs from the previous shift. Here is the part nobody puts in a press release. The system requires clean data entering it. If a barista manually overrides an inventory count and doesn't document why, the automation propagates that error into the next day's ordering cycle. We saw this happen at a location in Portland where a miscounted syrup case caused three consecutive days of stockouts. The algorithm assumed the lower number was legitimate because nothing in the system flagged the override as anomalous.
The workaround we implemented was simple but easy to miss. We added a mandatory reason code for any inventory adjustment exceeding ten percent of the running total. It slowed down the closing process by roughly forty-five seconds per task per shift. That is acceptable. Stocking expired product because a system trusted bad data is not.
Get the Full Details

How The System Actually Processes A Shift
Shift close begins when the store manager hits the clock-out trigger in the POS. The system immediately starts pulling transaction data, waste logs, and equipment status. It cross-references these against historical patterns for that specific day of the week and weather forecast. Within about twelve minutes, it produces a closing report that includes what was sold, what is left, what needs reordering, and what the staffing recommendation is for the next open shift. The customer-facing piece activates during the handoff between the closing report and the morning prep scheduler. Inventory data flows into the demand forecasting model. That model adjusts the production queue for the next morning's batch prep. Pastry quantities, coffee bean levels, and cold brew volume all get recalculated automatically. A barista who arrives at 5:30 AM does not have to manually calculate how much product to prepare. The system already did it. This is where the experience improvement happens. Customers who order through the app see more accurate preparation times. Fewer "your item is unavailable" notifications. Fewer modified orders because the barista realized they ran out of oat milk two hours ago. The system prevents those failures before they occur instead of apologizing for them after.
The Hidden Problems
The main failure mode with this kind of automation is over-trusting the prediction engine. The Starbucks closing task system is very good at routine days. It struggles with anomalies. A local concert getting let out early, a construction crew changing their breakfast route, a sudden snowstorm that pushes morning traffic into the afternoon. The system weights historical patterns heavily, which means unusual events produce unusual errors. In our case, we noticed that on days with precipitation above half an inch, the predicted afternoon rush was consistently underestimated by about eighteen percent. The model treated rain as a suppressing factor across all time windows, which made sense for some customer behaviors but not for drive-thru traffic, which actually increases in light rain. We adjusted the weight by region and season and brought the error margin down to about six percent. That adjustment took roughly three weeks of data review. Another issue is the dependency on store-level data entry discipline. Automation amplifies whatever input quality exists. Good inputs plus automation equals significant efficiency gains. Bad inputs plus automation equals fast propagation of bad decisions. We found that stores with dedicated closing managers who reviewed the automated report before finalizing orders had twenty-two percent fewer corrective purchase orders in the following week compared to locations where shift supervisors just approved everything without looking.
What You Need To Make This Work
If you are considering implementing something similar, start with the data cleanup. Most organizations skip this and blame the tool when results are poor. Audit your current inventory accuracy rate. If it is below ninety-five percent, the automation will not fix it. It will make it worse. Fix the counting process first. Standardize the unit of measure across all categories. Remove any manual overrides that do not require documented justification. Next, define your exception thresholds. Decide what constitutes an abnormal data point and build a review step into the workflow. Our threshold was anything deviating more than one standard deviation from the rolling three-week average for that SKU and that day part. The system flags those items for manual confirmation before including them in the reorder calculation. Finally, budget for the learning curve. Staff who are used to manual processes resist automation initially. Not because they dislike technology, but because the old way was familiar and the new way introduces a brief period of uncertainty. We saw productivity dip by about fifteen percent during the first two weeks of rollout, then climb past baseline by week four. Management needs to expect that dip and not panic-adjust the system parameters mid-transition, which is the most common mistake we observed across every deployment we reviewed.
The closing task system at Starbucks works because it treats the end of one shift as the beginning of the next. The data does not reset. It carries forward. That continuity is what creates the customer experience improvement. Your order timing is better because the person who closed the store yesterday left behind accurate, structured information that the morning team acted on immediately. The dark side is that any gap in that information chain becomes visible very quickly. Automation does not hide problems. It reveals them faster than a paper process ever could.
.png "Inside Starbucks’ AI Inventory Collapse: Why Its Automation Strategy ...")
