
Why I Started Digging Into LA County Coroner Files
I first ran into this when a friend was researching mortality rates among people experiencing homelessness in Los Angeles. You can find a lot of surface-level reporting on the crisis, but the actual numbers tend to come from a few different sources that don't always agree with each other. The coroner's office sits somewhere in between, and it has its own problems. The coroner doesn't just record causes of death. They also log housing status, which is usually coded as a field rather than something you can search intuitively. Most people don't know how to pull that data out without spending weeks on email threads with public records liaisons.
The Dark Reality Of Homelessness In La A Closer Look At Los Angeles County Coroner Records
Here is how the actual process works, and where it breaks down. LA County Coroner cases are technically public under the California Public Records Act, but they are not freely downloadable in bulk. You can file a records request through the county website, and you will get a response. Usually within 10 business days if your request is narrow enough. The problem is that housing status isn't always captured consistently. I found that somewhere around a third of unhoused decedent files have incomplete or missing housing documentation, even in cases where the person was clearly living on the street. One workaround I learned the hard way is to pair coroner data with DMV address records and shelter intake logs. The coroner files alone will underestimate the unhoused population because they rely on whoever is reporting the deceased person's status at the time of intake. If someone is picked up by a police officer or a paramedic who marks their address as "unknown," that gets recorded as unknown, not as homeless.
Here is the practical method I use now:
Get the Full Details

- File a specific PRA request for coroner cases with housing status coded as unsheltered, sheltered, or unknown between two dates.
- Ask for the raw fields, not a summary report. Summaries are edited. Raw data has the inconsistencies you need to see.
- Cross-reference known shelter locations and encampment reports from the city's interim housing authority.
- Filter for cases where the coroner's "place of residence" field conflicts with other public records.
I spent about three months getting this workflow down. It usually takes me around 4 to 6 hours per quarter of data once I know what I am looking for. The first time through it took me roughly 30 hours because I did not know which fields actually contained housing status versus medical history notes. There is a common mistake people make here. They assume coroner data gives you a count of deaths among homeless people. It does not. It gives you a count of deaths among people the coroner identified as homeless, which is a narrower set. LA County has a large population of unsheltered individuals who die in places that are not logged as homelessness-related by the responding agency. ER visits, jail intakes, and psychiatric holds often end up in different databases entirely. Another thing that catches people off guard is that the coroner's office does not release case details the same way across all types of deaths. Natural causes, overdoses, and undetermined cases tend to have more complete housing fields. Suicides and homicides sometimes have less context because the investigative narrative takes priority over demographic documentation. I found this while working on a project tracking overdose deaths in the Skid Row area, and it made the numbers look artificially better than they actually were for that particular cause.
If you want the raw request form, the LA County Coroner's public records page is accessible through the main county website. Search for "LA County Coroner PRA request" and you will find the current form. It is not always easy to locate because the coroner's office updated their web structure recently, and the link moved from what used to be a prominent page to somewhere buried under the administrative section. The response you get back is typically a PDF with rows of data. You will want to open it in something like LibreOffice Calc or Google Sheets so you can filter and sort. Excel works too but tends to choke on the larger datasets if you pull multiple years at once. I should mention one limitation that matters a lot. The coroner's office does not track outcomes for people who were unhoused at the time of death but later got housing. If someone was placed in a transitional housing program and then died while enrolled, the record may not reflect their prior homelessness. This means the data skews toward the most vulnerable subset of the unhoused population, which is the people who never exited street homelessness. That is useful information, but it is not the full picture.
For people who want to go further, there is research from UCLA's Fielding School of Public Health that has published work on this. They have done some of the heavy lifting on methodology for connecting coroner records to broader homelessness datasets. Their approach involves matching names and dates across multiple county systems, which takes legal review and often a research partnership with the county. I do not recommend trying that alone unless you have institutional backing. The data integration work is technically straightforward but legally complicated. HIPAA restrictions apply to medical information in the files, and the coroner's office is careful about what they release outside of approved research channels. The numbers themselves are sobering even with the gaps. In recent years, the coroner has processed well over a thousand deaths among people experiencing homelessness annually in LA County. That is a significant portion of all coroner cases in the county. The causes vary widely, but cardiovascular disease, overdoses, and hypothermia are consistently among the top categories. What stands out is how many of these deaths could have been prevented with stable housing and basic medical care.
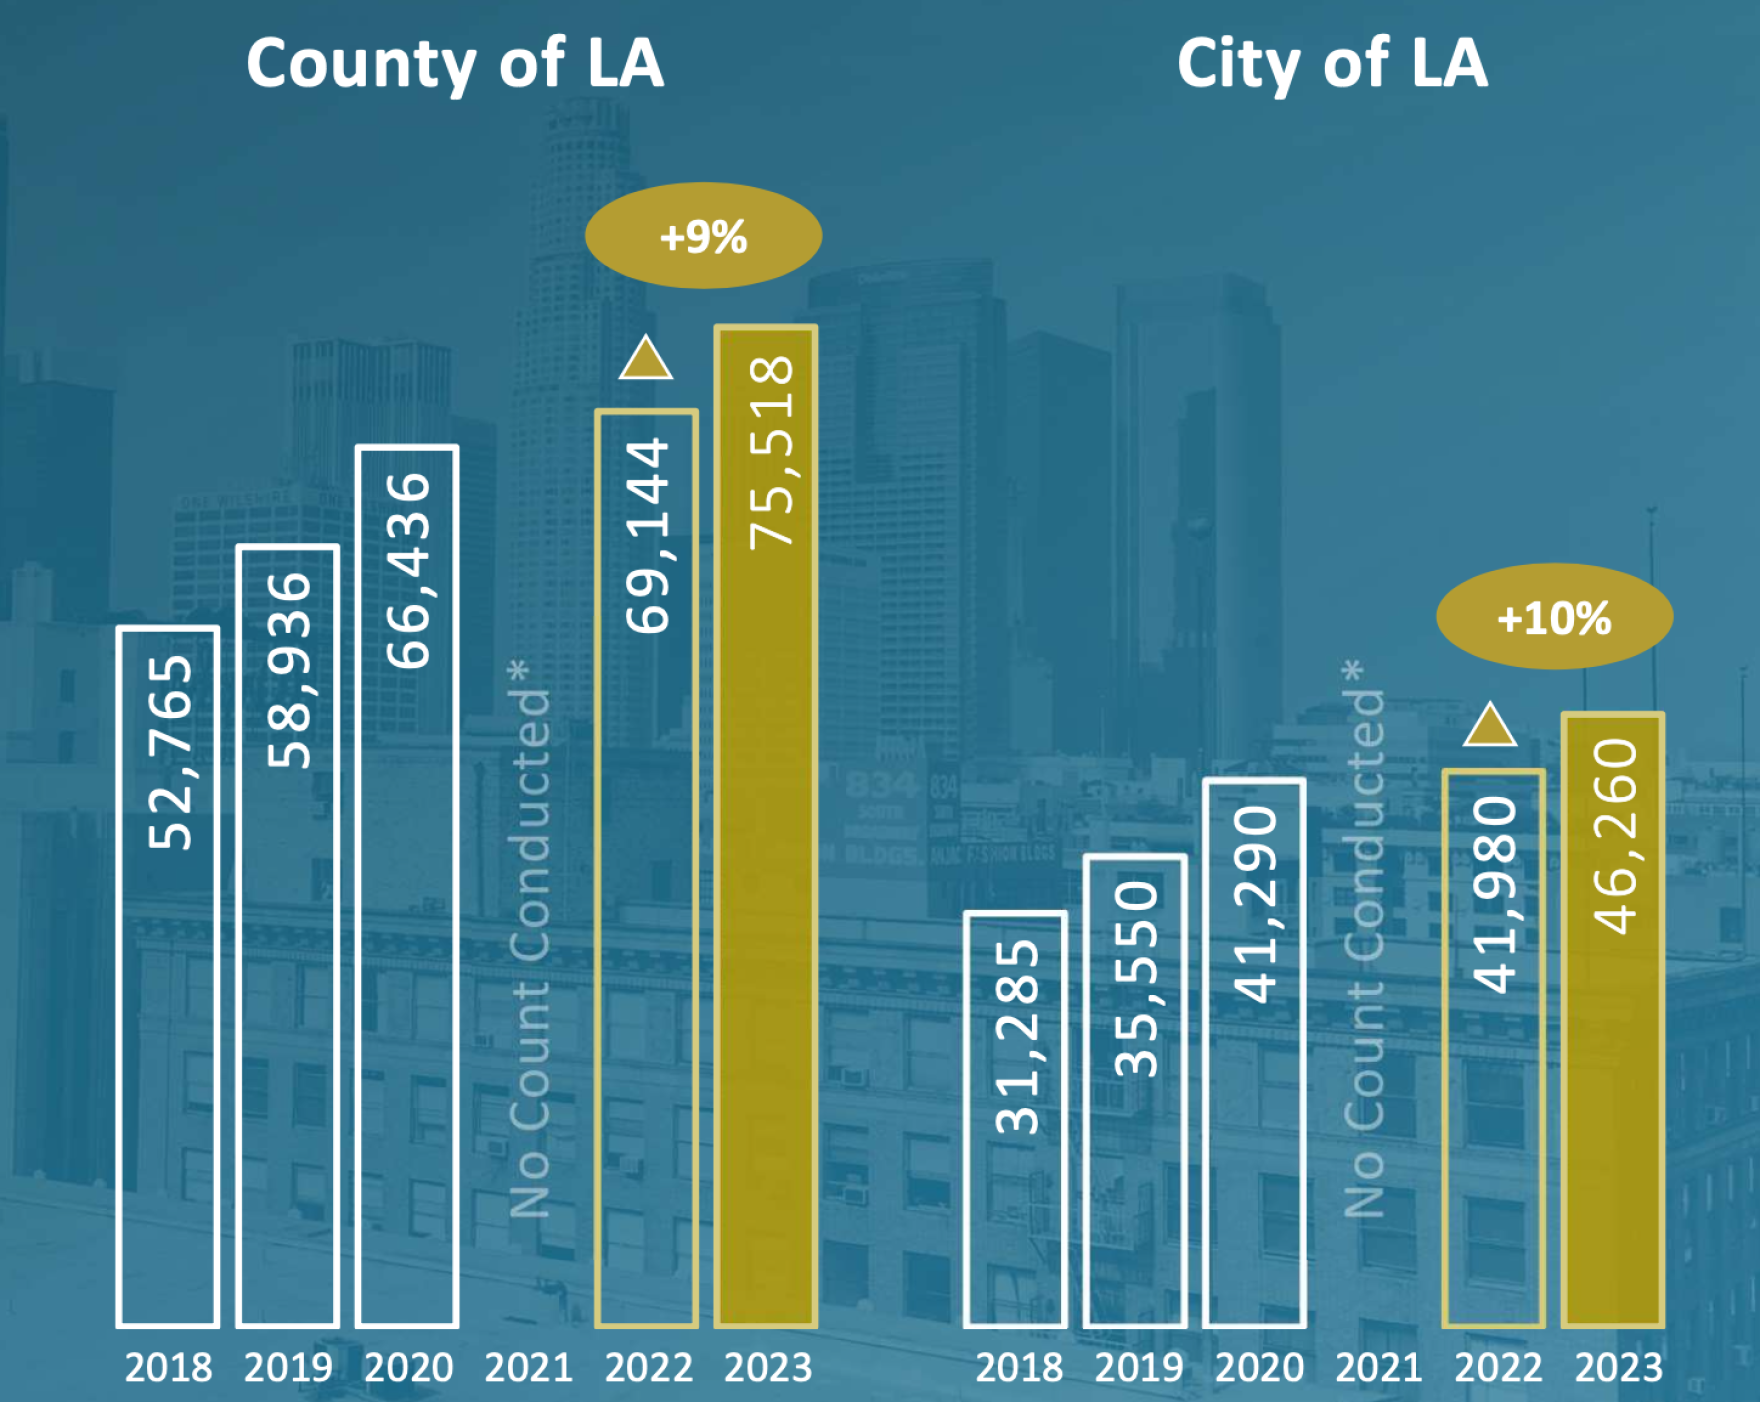
There is not a simple way to get all the data at once. The best approach is to file focused requests, be persistent about getting raw fields, and combine multiple sources to fill in the blind spots. If you spend the time doing it right, you can build a dataset that is actually useful for policy work or academic research. Most people stop after the first request because the data comes back messy and incomplete. The trick is to treat the mess as information. The gaps tell you something about how the system fails to document the most vulnerable deaths. That is not a weakness in the data. It is a finding in itself.


