Working with Dark Digital Art Styles on DeviantArt
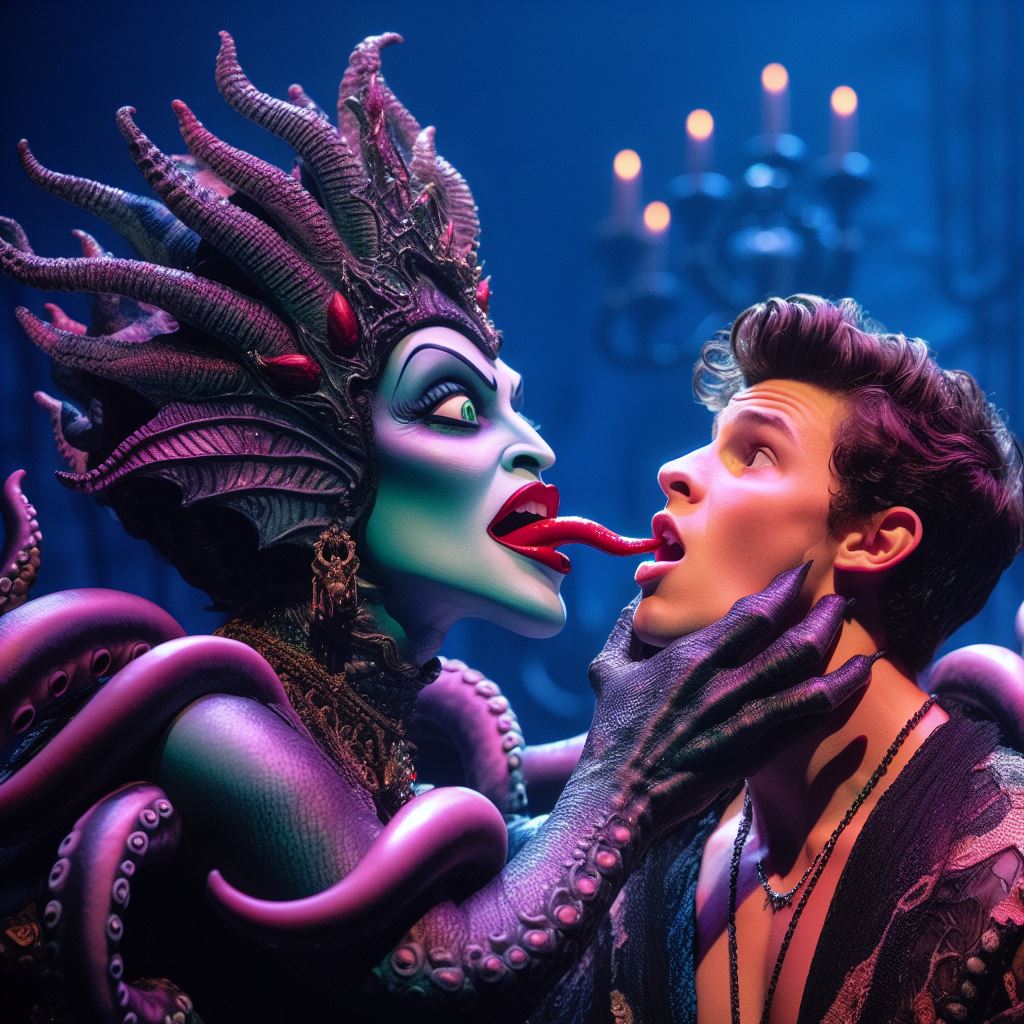
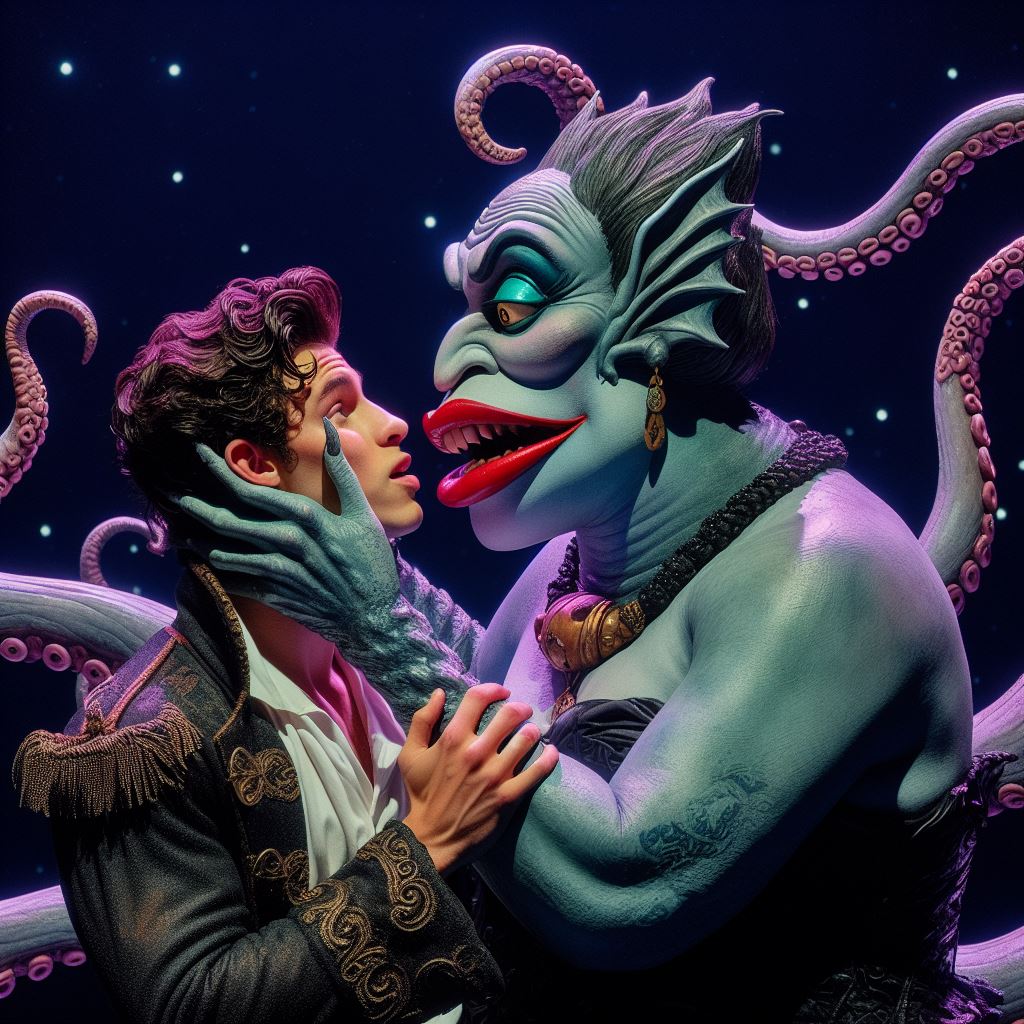
The DeviantArt community has always had a weird relationship with Ursula. You can't really avoid it if you've been on the site for more than a few years. She's one of those characters that keeps showing up, usually reimagined through darker, more elaborate lenses. The recent push for these kinds of pieces has gotten louder because of AI generation tools, which is why the scene feels different than it did ten years ago. People use a handful of different workflows when they create these pieces. Some are going full traditional digital painting, running through Photoshop or Clip Studio Paint. Others are using Stable Diffusion with custom LoRAs or training their own checkpoints on specific character aesthetics. The AI route is way more common now, honestly. It's faster and good enough for most people browsing DeviantArt. If you're looking at a piece like the one you referenced and want to make something similar, the first thing to decide is which pipeline you're using. For AI work, I'd recommend starting with a local installation of Stable Diffusion through Automatic1111 or ComfyUI. Both are free. The Automatic1111 interface is easier to pick up. ComfyUI is better if you want to build complex node-based workflows. Whichever you choose, you'll need a decent GPU. An NVIDIA card with at least 8GB of VRAM will get you there. I ran into issues on my older rig with 6GB of VRAM when trying to process anything larger than 1024x1024 without hitting out of memory errors. The workaround was using the --lowvram flag in the launch arguments, which slows things down but keeps the process from crashing entirely.
For the actual model, standard base models like SDXL 1.0 work fine as a starting point, but you'll want to pull in some finetunes from CivitAI that specialize in character art or dark fantasy aesthetics. Models trained on specific LoRA datasets for Ursula-like designs tend to give you better results than trying to force a generic model through positive and negative prompts alone. The tricky part with these kinds of pieces is getting the anatomy right. AI models have a tendency to mess up tentacle rendering and facial structure simultaneously. I spent weeks fighting with this before I figured out that using inpainting with a lower denoise strength (around 0.35 to 0.45) on the problem areas while keeping the rest of the composition intact made a noticeable difference. Without inpainting, any correction ruins the whole image. With it, you can fix specific problem zones without losing coherence.
Why These Images Pop Up on DeviantArt
There's a practical reason behind the volume of content. DeviantArt's search algorithm favors pieces with high engagement, and dark character reinterpretations tend to draw more comments and favorites than vanilla artwork. That drives the trend. People see what's getting traction and make similar work. It's not malicious. It's just how the platform's feedback loop works. What makes these pieces technically interesting is the lighting setup. Dark art relies heavily on rim lighting and subsurface scattering effects to make characters feel dimensional against shadowy backgrounds. If you're painting manually, you'll spend a lot of time on the light passes. If you're using AI, you can prompt for these effects but you'll still want to do post-processing in Photoshop or GIMP to sharpen the details and clean up artifacts. One thing beginners often miss is that prompt weighting matters a lot more than they expect. Using parentheses like (dark atmosphere:1.3) or square brackets like [Ursula design] changes how the model weights elements. The SDXL checkpoint handles this differently than SD 1.5, so you can't just copy-paste prompts between models and expect the same result. I learned that the hard way when I copied a prompt that worked perfectly on SD 1.5 and got completely different output on SDXL.
Get the Full Details

Where to Find and Download These Types of Images
DeviantArt itself is the primary source. Search terms like "dark Ursula," "Ursula reinterpretation," or "mermaid witch art" will pull up relevant work. You can filter by medium and date. CivitAI is another good resource for finding the specific models and LoRAs artists are using. Some creators post their generation settings openly on those pages. When downloading, check the artist's profile for download permissions. Some creators lock higher resolutions behind patron access. It's worth respecting that if you find a piece you actually like. The free versions are usually lower resolution watermarked files anyway. There's also a fair amount of this content on ArtStation and social media platforms, but DeviantArt remains the most concentrated hub for this particular niche. The community there has been building these kinds of pieces since long before AI tools became mainstream.
What Doesn't Work Well
Not every approach yields good results. Using Midjourney or DALL-E for this specific type of content tends to produce cleaner but less distinctive output. The AI tools tend to sanitize dark character designs into something more commercial. If you want that specific DeviantArt dark art aesthetic, local Stable Diffusion gives you far more control. You're also limited by your hardware. Running SDXL at high resolutions with detailed inpainting steps on a laptop GPU can take hours for a single image. A desktop setup with an RTX 3090 or 4090 cuts that down to minutes. Another issue is over-reliance on pre-made LoRAs. They often lock your output into a specific art style that looks identical across every image you generate. Training your own LoRA on a reference dataset takes more time but gives you much more unique results. I trained one on a collection of my own sketches and ended up with outputs that didn't look like everyone else's generated art. The legal side is worth noting too. Generating copyrighted character designs and posting them commercially can get complicated. Most people on DeviantArt post these as fan art and don't monetize them, which falls under a gray area. If you plan to sell prints or use the work commercially, you should look into the specific licensing terms for the models and LoRAs you're using. Some require attribution or prohibit commercial use entirely.
There's also the problem of consistency across series. If you're making multiple images in a cohesive set, keeping the character consistent between generations is genuinely difficult. The model will vary details slightly each time. You can mitigate this with reference images and IP-Adapter nodes in ComfyUI, but it still requires patience and trial and error to get the results you want.