Why your transaction data is useless even though you have all of it
Most teams I talk to have transaction data. Lots of it. They just don't know what to do with it because it's locked inside system-specific formats that change every time an update rolls out. The real problem isn't collecting data. It's making that data actually traceable across systems without spending three weeks building a pipeline for each new merchant or payment provider. I spent years dealing with this at a fintech company where we were pulling transaction records from eight different payment processors. Each one had its own schema, its own timestamp format, and its own idea of what a "successful" transaction looked like. Stripe calls it status. Square calls it transaction_status. A legacy bank API calls it resp_code. None of them align. Building a manual mapping for each was costing us about forty hours per integration. That number dropped to roughly six hours once we stopped treating customization as a manual process and started building it as a configuration layer.
The Complete Guide To Customizable Transaction Data Unlocking New Insights And Opportunities
Here's what that actually means in practice. You build a field-mapping configuration that sits between your raw transaction source and wherever you're storing or analyzing the data. The configuration does three things: it renames fields to a standard schema, it transforms values into consistent formats, and it enriches records with business logic you define. That's it. Nothing magical. But the way you structure the configuration determines whether this becomes a maintenance burden or something that scales. The first thing to decide is your standard schema. Pick a set of fields every transaction record must have regardless of source. Minimum viable set is transaction_id, amount, currency, timestamp, merchant_id, status, and payment_method. Everything else is optional. I learned this the hard way when we tried to preserve 47 fields from every source. Half of them were never queried. The other half conflicted across systems. We cut it down to twelve and the dashboard load time improved noticeably because there was less data moving through the pipeline. Field mapping is straightforward until you hit edge cases. Like when a single transaction produces multiple records across systems. A refund creates a negative amount in one processor and a separate reversal record in another. If you're just renaming fields, your analytics will double-count refunds. The workaround is to add a transaction_group_id during the mapping phase. You can derive this from the original authorization reference. Most processors include it. Bank transfers sometimes don't. For those, you match on amount, timestamp within a tolerance window, and merchant.
Timestamp normalization is where most projects fail quietly. Different sources use UTC, local time, or server time with unknown offsets. I've seen reports where transaction volumes appeared to spike at 3 AM because one processor was logging in EST and another in PST. The fix is to store everything in UTC at ingestion and keep the original timestamp in a separate field. Never trust the first timestamp you see. Always verify it against the processing timestamp if both exist. They should be within seconds of each other. If they're more than a minute apart, something is wrong with the source. Enrichment is where the actual insights come from. Raw transaction data tells you what happened. Enrichment tells you why it matters. Add customer_segment from your CRM. Add product_category from your catalog. Add risk_score from your fraud system. The key is doing this at ingestion time, not later in the analytics layer. When you query enriched data retrospectively, you're often missing context that's no longer available in the source systems. One counter-intuitive thing about this: storing more raw data than you need upfront actually slows everything down. I know that sounds wrong. But every extra field increases storage costs, query times, and the chance of schema drift breaking your pipelines. Only store what your queries actually use. If someone asks for a field you didn't store, you can go back and re-ingest from your raw log. The log should be cheap to keep. The processed schema should be lean.
Get the Full Details
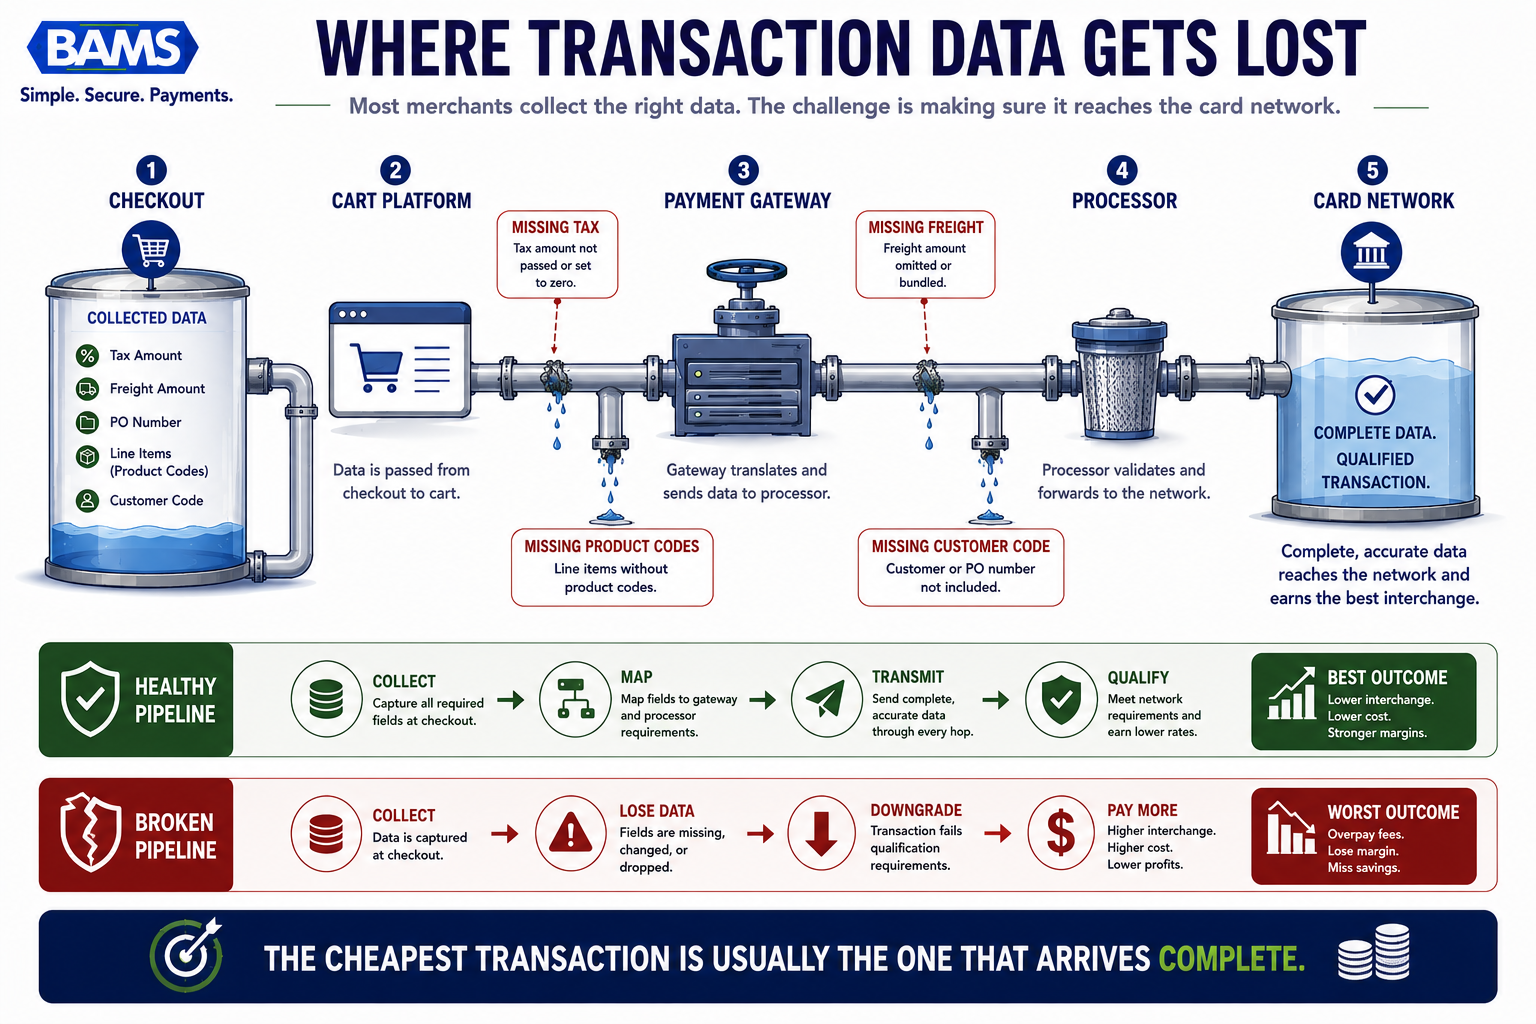
Configuration management matters more than people realize. When your mappings live in code, every change requires a deploy. When they live in a database or a configuration file that the pipeline reads at runtime, you can update mappings without touching the codebase. We switched to a JSON-based configuration stored alongside our application config. Mapping changes went from taking a half-day including testing and deployment to about fifteen minutes including review. That sounds minor until you're doing it weekly. Validation is the step everyone skips and then regrets. Before you trust any output from your pipeline, you need automated checks that compare aggregated totals between the source and your normalized data. Run these daily. If the variance exceeds one percent, something broke. It's usually a new field format from a processor update, not a code bug. The notification from these checks saved us from publishing incorrect revenue numbers for an entire quarter once. We caught it on day two instead of day ninety. There are tradeoffs. Customizable transaction data pipelines are not simple to set up. The initial configuration takes time. The validation layer adds complexity. If you're handling fewer than a thousand transactions per day across one or two sources, a manual export-import workflow might actually be faster than building this infrastructure. Don't build automation for problems that don't exist yet. But if you're at the scale where manual processes are breaking, the investment pays for itself within a few months.
The biggest pitfall I see is treating this as a one-time project. Transaction processors update their APIs regularly. New fields appear. Old ones get deprecated. Your mappings will break. Budget time for ongoing maintenance. We allocate about ten percent of our engineering capacity to keeping the pipeline current. That's not excessive. It's just what it costs to keep the data accurate. If you're looking for a starting point, there are open-source tools like Apache NiFi and custom transformation scripts in Python that handle the core logic. The configuration patterns are portable across tools. The specific implementation details change, but the field-mapping, timestamp-normalization, enrichment, and validation approach stays the same. Pick the tool that fits your stack. The methodology is what matters.